
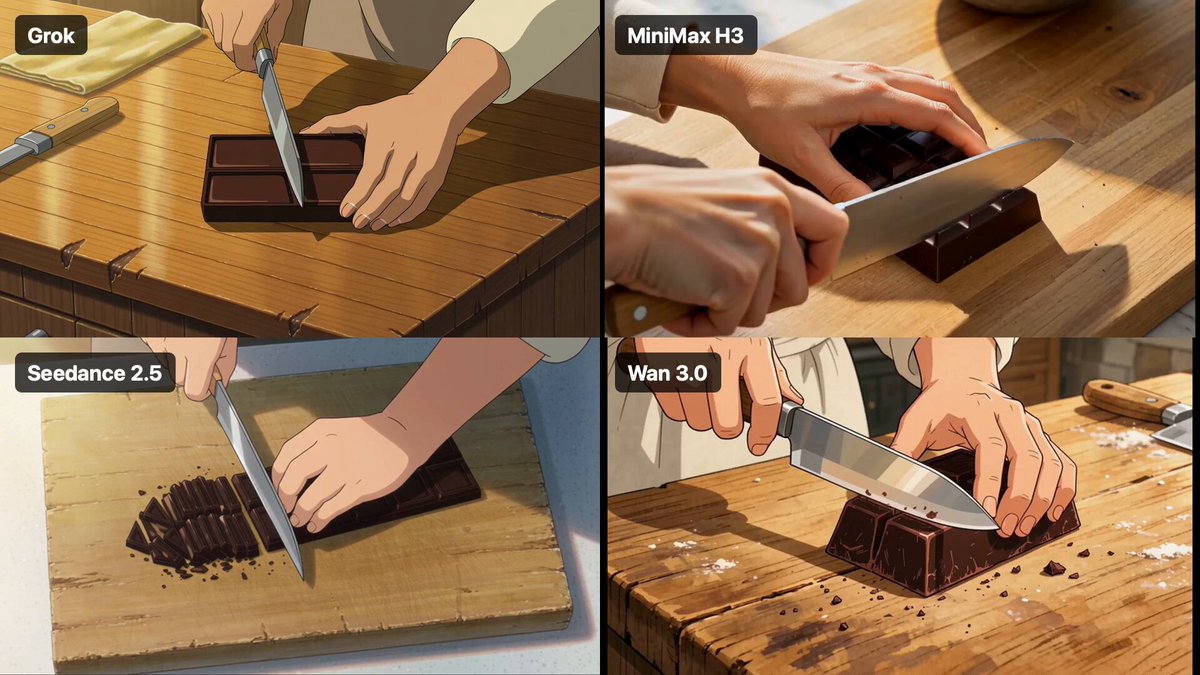
Why a Still Image and a Sentence Are Enough to Start
A few years ago, making a video meant cameras, lighting, actors, and a schedule. Today, a large share of the footage you see in ads, explainers, and social clips begins as nothing more than a photograph and a written instruction. That shift is not a gimmick. It changes who can produce video, how fast a concept can be tested, and how many visual ideas one person can explore in an afternoon.
The core idea is simple: generative models learn how pixels move. They have watched millions of hours of footage and absorbed patterns about how smoke drifts, how fabric folds, how water ripples, how a person turns their head. When you hand one a still image and describe what should happen next, it does not cut or animate frames the way a traditional editor would. It predicts a plausible, continuous motion path and renders it.
The text part matters just as much. A prompt is not a caption. It is a set of directorial instructions: subject, action, camera behavior, lighting, pacing, mood. When a prompt is vague, the model improvises, and improvisation is where most disappointing results come from. When a prompt is precise, the output becomes predictable enough to build a sequence around.
This guide walks through a repeatable workflow: choosing between text-to-video and image-to-video, selecting the right model for each shot, writing prompts that hold up under motion, planning a shot list, keeping characters consistent, fixing common failures, and finishing in an editor so the result feels like a real video rather than a demo reel.
Text-to-Video Versus Image-to-Video: Choosing the Right Entry Point
These are not competing formats. They solve different problems, and most strong projects use both.
When text-to-video is the better choice
Use pure text prompts when you need to invent something that does not exist yet: a sweeping establishing shot of an imaginary city, an abstract transition, a stylized montage, or a concept you want to explore in several variations before committing. Text-to-video is also faster when visual continuity across shots is not critical, because you are not managing reference assets.
The tradeoff is control. You describe a scene and get one interpretation. If the framing, wardrobe, or color palette matters, you will do a lot of re-rolling.
When image-to-video earns its place
Image-to-video shines whenever a specific look must be preserved. Common cases:
- Product shots. You have a hero photograph and need a slow push-in with a subtle rotation.
- Character continuity. A generated or photographed actor must appear identical across six clips.
- Brand assets. Backgrounds, packaging, and typography already exist and cannot drift.
- Archival or documentary work. A historical photograph becomes a gentle parallax move instead of a hard cut.
- Storyboards. A sketch or render becomes an animatic you can show to a client.
A practical rule: if you would be upset that the model invented a detail, start from an image. If you genuinely do not care how the scene looks and only care that it feels right, start from text.
The hybrid pattern most teams settle into
Generate a still first, then animate it. Use text-to-video or a still-image generator to produce a keyframe, review it, adjust it in an image editor if needed, and only then run image-to-video. This two-step approach costs one extra round of generation but eliminates most surprises. It also gives you a reviewable artifact at each stage, which matters when someone else has to approve the work.
Matching the Model to the Shot
There is no single best video model. Different architectures excel at different things, and treating them as interchangeable is one of the fastest ways to waste time.
Decision criteria that actually matter
| Criterion | What to check | Why it changes your choice |
|---|---|---|
| Motion complexity | How far and how fast things move | Simple drift favors fast, cheap models; complex action needs stronger temporal reasoning |
| Clip length | Native duration per generation | Long clips reduce stitching work but often cost more per second |
| Reference adherence | How tightly output follows your input image | Critical for products, faces, and branded assets |
| Stylization range | Realistic versus animated or painterly | Some models default to a filmic look you then have to fight |
| Resolution and aspect ratio | Native output size | Vertical-first models save cropping headaches for social formats |
| Iteration speed | Time per attempt | Fast drafts early, high-fidelity runs late |
| Controllability | Camera motion, motion strength, seed locking | Determines whether you can fine-tune or only re-roll |
A practical tiering system
Instead of hunting for one perfect model, tier your work:
- Draft tier. Fast, low-resolution runs to test composition and motion direction. Expect to throw most of these away.
- Approval tier. Medium quality with the strongest reference adherence. This is what you show a client or stakeholder.
- Final tier. Highest fidelity, longest duration, best motion coherence. Run this only on shots that already passed the previous two tiers.
This tiering keeps your expensive generations concentrated on shots that actually survive review. Teams that skip it usually end up rerunning final-quality renders because a basic framing decision was wrong.
Model strengths by shot type
- Talking-head and portrait shots: prioritize identity preservation and micro-expression stability. Push-in and slight head-turn moves work best.
- Product and tabletop: prioritize reference adherence and controlled lighting. Avoid models that add dramatic camera moves by default.
- Landscape and establishing shots: prioritize motion realism in clouds, water, and foliage. Long, slow moves hide artifacts.
- Action and sports: prioritize temporal coherence. Expect shorter usable clips and plan for more attempts.
- Abstract and graphic transitions: almost any model works; prioritize speed and color consistency.
Writing Prompts That Survive Motion
A prompt that produces a beautiful still may produce a chaotic clip, because motion adds a second layer of failure. The model must keep the subject recognizable while changing it frame by frame.
The five-part prompt formula
Write every prompt with these elements in order:
- Subject and scene. "A ceramic coffee cup on a weathered oak table, morning light from the left."
- Action. "Steam rises slowly and drifts to the right."
- Camera. "Slow push-in, eye level, shallow depth of field, no shake."
- Light and atmosphere. "Warm backlight, soft haze, no lens flare."
- Style and pace. "Documentary realism, calm pacing, natural color."
That structure does two things: it removes ambiguity, and it gives you a diagnostic tool. If the output fails, you can identify which element was ignored instead of rewriting everything.
Motion verbs are your camera crew
Words like "drifts," "settles," "unfolds," "sweeps," and "glides" produce very different results from "moves" or "animates." Vague verbs invite the model to invent dramatic motion you did not ask for. Specific verbs constrain it.
Equally important is a negative instruction set. Phrases such as "no camera shake, no morphing faces, no extra limbs, no text overlays, no sudden cuts" prevent a surprisingly large share of common artifacts. Keep the negative list short and targeted; a long list of prohibitions can flatten the image.
Control motion strength
Most tools expose a motion intensity or camera-motion control. Treat it as a dial, not a switch:
- Low: subtle parallax, breathing, hair movement, steam. Ideal for portraits and products.
- Medium: walking, turning, moderate camera travel. The default for narrative shots.
- High: running, fast pans, complex interactions. The highest artifact risk.
When a shot fails at high intensity, drop to medium and extend the shot later with an edit rather than regenerating at the same setting.
Build the Shot List Before You Generate Anything
Generation is the expensive part. Thinking is cheap. Write the shot list first.
A usable shot list has one row per clip with these columns: shot number, duration, subject, action, camera move, input asset, target model tier, and notes. Filling this in takes twenty minutes and typically saves hours of scattered generation.
The side benefit is editorial. Once the list exists, you can see whether your sequence has variety. Five consecutive slow push-ins will feel monotonous no matter how good each clip is. Adding a wide shot, a detail insert, or a lateral move gives the edit rhythm.
A common structure for a 45-second piece:
- Wide establishing shot, 4 seconds, slow forward drift
- Medium subject shot, 4 seconds, gentle push-in
- Detail insert, 2 seconds, static with subtle motion
- Action beat, 3 seconds, medium camera travel
- Reaction shot, 3 seconds, slight handheld feel
- Closing wide, 5 seconds, slow pull-back
Notice that durations are short. AI-generated clips rarely hold up for ten seconds without visible drift. Short clips edited together read as more professional than long ones with artifacts.
The End-to-End Workflow, Step by Step
Step 1: Define the deliverable
Decide the aspect ratio, total runtime, frame rate, and where the video will be seen. A vertical social clip and a horizontal website hero have different framing priorities, and re-framing after generation usually crops away the composition you worked for.
Step 2: Collect or create your source stills
For each shot, decide whether you need a photograph, a rendered still, a generated keyframe, or nothing at all. Check that stills are sharp, well-exposed, and free of compression blocking. Low-quality inputs produce low-quality motion because the model has to invent detail that is not there.
Step 3: Prepare the stills
- Crop to the target aspect ratio before generating, not after.
- Clean up distracting elements that would otherwise animate.
- Keep resolutions consistent across a sequence so grain and sharpness match.
- For faces, use a clear, front-facing or three-quarter reference.
Step 4: Generate drafts at low cost
Run fast drafts of every shot in the list before polishing any single one. This surfaces structural problems early: a shot that does not work, a sequence that needs a different angle, a transition that needs an extra beat.
Step 5: Review with a checklist, not a feeling
Score each draft on subject fidelity, motion naturalness, camera stability, lighting consistency, and artifact count. Anything that fails two categories gets regenerated rather than salvaged.
Step 6: Upscale and interpolate the winners
Only final-tier shots deserve enhancement. Upscaling a flawed clip just produces a sharper flaw. When you do upscale, keep the source frame rate and target frame rate in mind; frame interpolation can smooth motion but also introduces warping around fast movement.
Step 7: Assemble, sound-design, and color
See the post-production section below.
Consistency Across Shots: Characters, Style, and Color
Consistency is the hardest problem in AI video, and it is almost entirely a planning problem.
Lock a reference set
For any recurring character, keep a small reference pack: one front view, one three-quarter view, one profile, plus a full-body shot. Reuse the same pack across every shot. Do not let the model guess between clips.
Freeze your descriptive language
If shot one says "short dark hair, olive jacket, overcast light," shot seven must say exactly the same thing. Paraphrasing changes the output. Keep a text file with the canonical description of each character, location, and prop, and paste from it.
Control color across the sequence
Generated clips often drift in white balance. Two fixes work well: apply a unified color grade in your editor, and generate with a fixed style phrase in every prompt, such as "neutral daylight, natural color, no color grading." The second makes the first much easier.
Use first-frame and last-frame controls when available
Many image-to-video tools accept a starting frame and sometimes an ending frame. Setting both turns the model into an interpolation engine between two approved images, which is the single most reliable way to keep a sequence coherent.
Common Mistakes and How to Fix Them
The morphing face. Caused by high motion strength, low-resolution input, or a face that is small in frame. Fix by cropping closer, lowering motion intensity, and generating at a higher input resolution.
Unwanted camera movement. Usually from vague prompts. Always include an explicit camera instruction, including "static camera" when you mean it.
Flickering textures. Fine patterns such as fabric weave, brick, or mesh are hard to hold steady. Reduce texture frequency in the source still or soften it slightly before generating.
Rubber-limb artifacts. Common in full-body motion and hands. Frame shots to avoid complex hand actions, or use a mid-shot and let the edit imply the action.
Clips that look like a slideshow. Usually a sign of low motion strength combined with a static subject. Add a secondary motion element such as drifting smoke, moving light, or a subtle camera move.
Sequence drift. Fix with locked reference images, identical descriptive phrasing, and a single color grade applied after assembly.
Over-reliance on one model. Different shots benefit from different engines. Keep two or three options and match them to the shot list.
Post-Production: Where Clips Become a Video
Raw generations are ingredients. The final piece is built in an editor.
- Assemble on a rhythm. Cut on motion peaks rather than at fixed intervals. Short clips cut fast feel energetic; slow clips need longer holds.
- Add transitions deliberately. Match cuts and hard cuts usually beat cross-dissolves in AI footage, because dissolves draw attention to small inconsistencies between clips.
- Stabilize selectively. Apply stabilization only where camera shake is unintentional, and use a low strength so you do not get a warping, jelly-like effect.
- Grade as one piece. A single adjustment layer over the whole timeline unifies color far better than per-clip corrections.
- Design sound early. Ambient beds, footsteps, room tone, and music cover a surprising number of visual imperfections. Sound is not a finishing touch; it is structural.
- Add texture. Subtle grain, a slight vignette, and a light bloom make generated footage sit better alongside camera footage.
- Export for the platform. Match resolution, bitrate, and audio loudness targets rather than exporting one master and hoping it survives compression.
A Short FAQ
How long should each AI clip be?
Two to five seconds is the sweet spot. Generate slightly longer than you need and trim the edges, where drift usually appears first.
Do I need an expensive GPU?
Not for most workflows. Hosted generation handles the compute. Local rendering only becomes worthwhile if you generate at high volume.
Can I use generated video commercially?
It depends on the terms of the specific tool and the training data involved. Check the usage terms of each service you use, keep records of your prompts and source assets, and be cautious with recognizable faces, logos, and copyrighted characters.
Why does my output ignore part of the prompt?
Prompts compete for attention. Put the most important instruction first, keep the total length moderate, and split complex scenes into multiple shots rather than describing everything at once.
Is it better to generate a still first?
For anything with brand, character, or product requirements, yes. It adds one step and removes several rounds of failed attempts.
How many attempts should a good shot take?
Draft tier: expect three to eight attempts. Final tier: two to four, run on a shot that already passed review. If a shot needs twenty attempts, the prompt or the input image is the problem, not the model.
Can I mix AI clips with real footage?
Yes, and it usually looks better than either alone. Use real footage for hands, complex interactions, and anything requiring precise timing, and use generated clips for establishing shots, inserts, and transitions.
Making the Workflow Repeatable
The difference between a lucky one-off result and a reliable production pipeline is documentation. Keep a project file that records the prompt template, the model and settings used per shot, the reference images, and the review scores. After three or four projects, you will notice patterns: which model handles your product shots best, which motion strength your audience responds to, and where your sequences typically lose energy.
Start small. Pick one still image, write one five-part prompt, generate five drafts, and edit the best two together with music. That single exercise teaches more than reading about the process, and it takes about an hour. From there, scale by adding shots to the list rather than by increasing the complexity of each prompt. Text and stills are enough to begin; discipline is what turns them into video people actually want to watch.
