
Why text-and-image video generation changed the production math
For most of the last decade, the expensive part of video production was not the idea. It was translation: crews, locations, lighting, coverage, and the long tail of reshoots. Generative video compresses that translation step into something closer to sketching. A creator can describe a shot, watch a version of it appear in minutes, reject it, and try again before lunch. That changes the shape of the creative process, not just its price tag. Ideas that would once have been dismissed as too expensive to test become twenty-minute experiments.
The bottleneck has moved. It is no longer “can we shoot this?” but “can we describe this precisely enough, and can we hold it consistent across ninety seconds of screen time?” Most disappointment with AI video does not come from the renderer failing. It comes from the maker arriving at the renderer without a shot list, without reference frames, and without a plan for what the clip has to do in the edit.
Three capabilities drove the shift. First, diffusion-based video models learned to produce coherent motion over several seconds instead of melting into abstraction. Second, image conditioning matured: you can hand a model a still frame and ask it to continue from there, which gives you a hard anchor for composition and identity. Third, the tooling around generation — keyframes, motion controls, upscaling, lip sync — became a pipeline rather than a collection of disconnected demos.
The result is a workflow that looks less like animation and more like directing. You scout with prompts. You lock a look with reference images. You shoot individual beats, then assemble them in an editor. The craft lives in the decisions between generations, and that is what this guide covers.
Text-to-video vs image-to-video: picking your input path
When text alone is enough
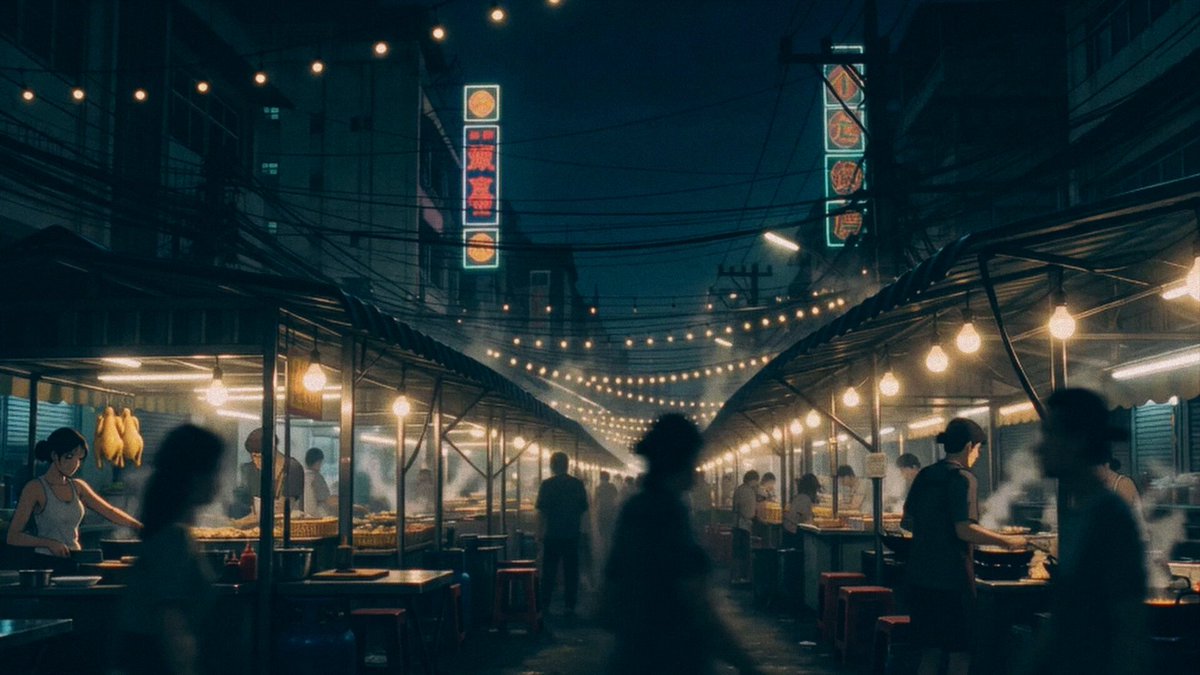
Text-only generation is the fastest way to explore. Use it when you are still deciding what a scene should feel like, when the subject is generic (a foggy street, a wave breaking, a slow push through a market), or when you need footage that will sit at low opacity under a voiceover. Prompt-led generation is also the right choice for abstract and motion-graphics-flavored material, where narrative continuity does not matter.
The trade-off is control. A text prompt describes a distribution of possible shots, not one shot. If you need the actor facing left, holding a specific prop, and wearing the jacket from the previous scene, text alone will drift.
When a still frame carries the shot
Image-to-video inverts the priority. You invest effort in a single frame — generated or photographed — and then ask the model to animate it. This is the more reliable path for anything that must match: product shots, character close-ups, recurring establishing shots, and any scene where the composition itself is part of the storytelling. Because the first frame is fixed, you spend less time fighting the model over layout and more time shaping motion.
A practical rule: if a viewer would notice that the shot is wrong rather than merely different, start from an image.
Hybrid: text for exploration, images for delivery
Most professional workflows are hybrid. You generate a wide set of candidates from text prompts to find the look, then freeze the best frames and re-run them through image conditioning to produce the clips you will actually cut. The exploration pass is cheap and disposable; the delivery pass is deliberate and repeatable.
Choosing a model for each shot: decision criteria
Motion realism versus stylization
Some engines are strong at physically plausible motion — cloth, water, crowds, camera parallax — and weak at stylized aesthetics such as clay render, cel shading, or painterly grain. Others are the reverse. Rather than committing to a single model, match the engine to the shot: use the physically strong one for live-action-feeling beats and the stylized one for title sequences, dream logic, and animation-flavored inserts.
Clip length and resolution
Long single takes are seductive and usually a mistake. A model that produces a beautiful four-second clip may fall apart at twelve. Build coverage instead: several short clips of the same moment that you can cut between. Short clips also survive the edit better, because you can trim around the inevitable micro-artifacts.
Iteration speed and budget fit
An underrated criterion is how quickly an engine returns a draft. If a render takes twenty minutes, you will generate three versions and accept the fourth. If it takes ninety seconds, you will generate twenty and find the one that sings. Choose the fast path for exploration and the slow, high-quality path for final frames.
Licensing and commercial use
Before you build a client deliverable, confirm the terms that apply to the model you used, the reference images you supplied, and any voice or likeness involved. Rules differ by provider and by region, and they change. Treat this as a pre-production checklist item, not an afterthought.
Anatomy of a prompt that survives the render
Subject, action, environment
Every prompt needs a subject (who or what), an action (what changes between the first and last frame), and an environment (where and when). Vague prompts produce vague results: “a man walking” gives the model almost nothing to anchor to. “A lanky man in a mustard raincoat walks away from camera through a neon-lit alley, puddles reflecting signage” gives it a subject, an action with direction, and a place with light logic.
Lens, light, and grade
Cinematographic vocabulary transfers surprisingly well: focal length, depth of field, key direction, time of day, film stock, contrast. Naming a lens — 35mm, shallow depth of field — often does more for the look than fifteen adjectives about quality. Add a grade only when you mean it, because high-contrast teal and orange and flat overcast pull in opposite directions.
Motion and duration cues
Describe how the camera behaves separately from how the subject behaves. A slow dolly in with a mostly still subject is a different request from a handheld follow with a briskly walking subject. If the tool exposes duration or motion-strength settings, use them; if not, encode pace in the prompt with words like slow, drifting, hurried, sudden.
What to leave out
Long lists of negatives and stacked contradictions confuse conditioning. Prefer one clear idea per clip. If you need two ideas, that is two clips and an edit point, not one overloaded prompt.
From script to shot list: planning the sequence
Beat sheet to shot list
Start with beats, not shots. A thirty-second piece usually has three to six beats: setup, escalation, turn, resolution. Under each beat, list the shots that could carry it and mark whether each shot is text-led or image-led. This simple table prevents the classic failure of generating beautiful clips that have nowhere to sit.
Writing prompts as production notes
Keep prompts in a spreadsheet with columns for shot number, beat, prompt, input image, model, duration, and status. When a client asks for a variation six weeks later, you regenerate rather than guess. Production notes also make collaboration possible: a second editor can pick up the project without reverse-engineering your thinking.
Batching for review
Generate in batches of eight to twelve variants per shot, review them in one sitting, and mark each as keep, maybe, or reject. Reviewing in batches keeps your judgment consistent; reviewing one clip at a time makes you fall in love with whatever you just watched.
Consistency across clips: characters, props, locations
Reference sheets and character bibles
If a character appears in five shots, build a reference sheet: front, three-quarter, profile, plus a wardrobe detail. Use the same sheet for every generation of that character. Consistency is largely a documentation problem before it is a modeling problem.
First-frame locking
Where continuity matters, lock the first frame and extend the shot rather than re-prompting it from scratch. Continuation is nearly always more stable than re-description, because it inherits the exact pixels you already approved.
Style anchors
Pick one clip and treat it as the visual anchor for the whole piece. Judge every subsequent clip against it for contrast, saturation, grain, and lens character. In post, a shared grade can rescue clips that are close but not identical — but it cannot rescue clips that were designed to look different.
Keyframes, motion, and camera direction
Start and end frames
If your tool supports both a first and a last frame, you gain real shot design control. Create or generate the end frame, then let the model interpolate between them. This is how you get a car to arrive at a specific mark or a door to close exactly on cue.
Camera moves
Name the move and the speed. A slow crane up reads differently from a quick tilt down. Avoid stacking two moves in one clip unless the tool has explicit keyframe regions, because the model will average them into mush.
Motion strength
Higher motion settings produce more dynamic clips and more artifacts. When in doubt, generate one version at low motion and one at high, then choose in the edit. A restrained move that holds up at full screen beats a dramatic one you have to hide behind a cut.
Sound, pacing, and finishing in post
Dialogue and lip sync
If a shot depends on a line, record or generate the dialogue first. Timing visuals to audio is far easier than the reverse, and lip-sync tools work best when the line is already locked.
Ambience and music
Layer ambience under every clip, even quiet ones — silence reads as an error to most viewers. Music carries rhythm across cuts that the visuals alone cannot.
Editing for rhythm
Cut on motion. If a clip is four seconds long and only the middle two are clean, that is a two-second clip. Do not stretch a shot to fit a music bar; trim the bar instead.
The finishing pass
A typical final pass looks like this: stabilize shaky generations, upscale to delivery resolution, apply a consistent grade, add a light grain layer to unify different sources, and check loudness. This pass is what separates work that looks generated from work that looks directed.
Common mistakes that waste render time
- Prompts that describe everything and choose nothing. Pick a subject, a move, and a light direction before you add flavor.
- Re-prompting instead of continuing. Reuse approved first frames to hold identity across shots.
- Generating finals during exploration. Draft at low quality, commit late, and only then spend time on the hero version.
- Ignoring the edit. A clip that appears for 1.2 seconds does not need twelve seconds of clean motion.
- Leaving sound decisions until the end. Audio choices change shot length more often than visuals do.
- Skipping reference documentation. Without a character bible, drift across clips is inevitable.
- Fighting an unsuitable model. If three attempts fail, switch engines rather than rewriting the same prompt a fourth time.
- Overloading a single clip with story. One clip, one idea; the story lives in the sequence.
FAQ: quick answers to recurring questions
How long should an AI-generated clip be?
For narrative work, two to five seconds per shot is a healthy default, arranged into runs of coverage. Longer clips are useful for establishing shots and slow reveals where the audience expects to sit still. The safest approach is to generate slightly longer than you need and trim in the edit.
Do I need to know cinematography to get good results?
You do not need a film degree, but you do need three pieces of vocabulary: shot size, camera move, and light quality. Being able to say “medium close-up, slow push in, soft window light” will improve your output more than any prompt-hacking trick.
Can I mix AI footage with real footage?
Yes, and it is one of the most practical uses of these tools. Shoot your anchor footage, then generate inserts, backgrounds, and impossible shots around it. Match grain, contrast, and lens character in the grade so the seams disappear.
How many variations should I generate per shot?
Eight is a reasonable starting point for exploration and three for a locked look. The point of a batch is comparison: reviewing variants side by side keeps you from accepting the first acceptable result.
What about text, logos, and signage on screen?
Readable text remains one of the weakest areas of generative video. Generate the shot without text and add typography in post, where you control font, timing, and legibility.
What is the fastest way to improve?
Rebuild one thirty-second sequence every week from the same script, changing only your shot list and prompts. Comparing your own versions over time teaches more than any list of settings, because it shows you which decisions actually moved the result.
The makers who get the most from text-and-image generation are not the ones with secret prompts. They are the ones who plan like directors, document like producers, and edit like editors — treating each render as one step in a pipeline rather than a finished outcome.
