
AI video generation has moved from novelty to a genuine production tool. What started as short, unstable clips with melted faces and drifting backgrounds now covers storyboarded sequences, camera movement, character consistency, and audio-aware editing. For anyone who makes creative content, the interesting question is no longer whether these tools work, but how to fit them into a workflow that produces something worth watching.
This guide walks through the practical side: what different categories of generators actually do well, how to write prompts that hold up over multiple shots, how to direct a sequence instead of a single clip, where the pipeline breaks, and how to vet output before it reaches an audience.
The Main Categories of Video Generation Tools
Generators cluster into a few families, and each family suits different jobs.
The conditioning mix matters enormously. Some models accept only text. Others accept text plus a reference image, a depth map, a motion skeleton, or an existing clip for style transfer. The more channels a model accepts, the more control you have, but also the more setup work each shot needs. Video is also not a stack of independent images: a model has to keep a face, a jacket, a lighting direction, and a background consistent across dozens or hundreds of frames, and architectures differ sharply in how well they do that. You notice the difference the moment a subject turns their head or a camera pans across a detailed environment. Rendering budget is the third lever, because resolution, frame rate, clip length, and generation passes all trade against each other. A generator that produces gorgeous eight-second clips at high resolution may be useless for a 40-second continuous shot.
Text-to-video models. You describe the scene and the model invents everything. This is the most flexible category and the least controllable. It excels at establishing shots, abstract sequences, environments, weather, and mood pieces where nobody needs to recognize a specific object. It struggles with precise choreography, specific text, and anything requiring a real person's likeness.
Image-to-video animators. You supply a still frame, and the model animates it. This is the workhorse of most real production workflows because it solves the composition problem before generation begins. You can art-direct the frame in a still image tool, a 3D render, a photo, or a hand-drawn illustration, then let the model handle motion, parallax, and atmosphere. Because the starting frame is fixed, subject identity is far more stable.
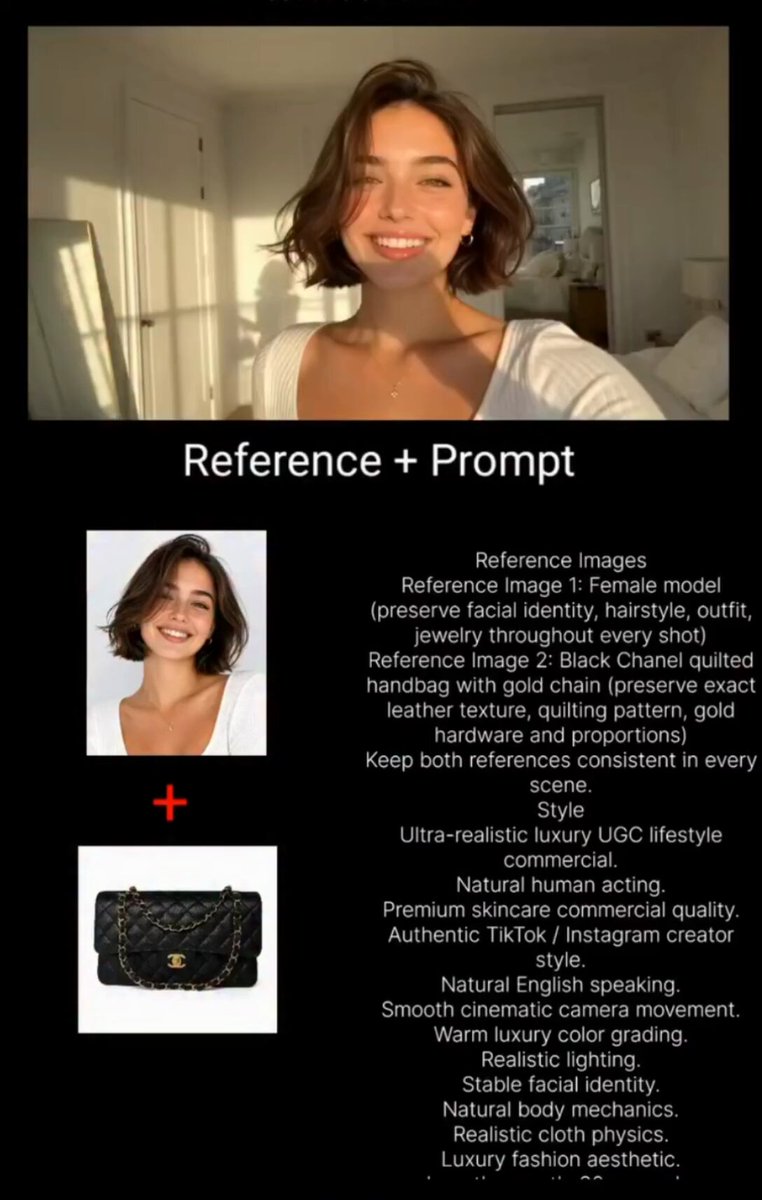
Reference and character-conditioned models. These accept a subject reference and aim to preserve it across shots. They are the right choice for recurring characters, product shots, brand mascots, and any sequence where the viewer must believe they are watching the same person or object repeatedly. Results depend heavily on the quality and neutrality of the reference image: a flat, evenly lit reference works far better than a dramatic three-quarter shot with strong shadows.
Motion and camera-control models. These expose explicit controls for camera movement, subject motion, and timing. Instead of hoping the prompt yields a push-in, you specify it. This category is essential when a sequence needs to cut together smoothly, because matched camera behavior is what makes separate clips feel like one scene.
Editing and assembly layers. Generation is only part of the job. You still need to cut clips, sync audio, add titles, stabilize motion, and export for the target platform. Some toolchains integrate assembly directly; others expect you to hand clips to a conventional editor. Neither approach is wrong, but the choice affects how much time you spend moving files around.
A realistic studio setup usually combines three or four of these families rather than betting everything on one model. A single text-to-video model is great for B-roll and terrible for continuity.
How to Choose a Model for a Specific Shot
Model selection is where most quality is won or lost, and it is almost never a matter of picking the best overall tool. Match the model to the shot. Ask these questions in order.
Does the shot contain a recognizable subject? If yes, use an image-to-video or reference-conditioned model. If no, a text-to-video model will be faster and more imaginative.
Does the shot need precise camera movement? If the movement carries meaning, use a model with camera controls. If the camera is essentially locked off, any decent animator will do.
How long is the shot? Choose a model whose comfortable clip length matches your need, then plan cuts around that limit instead of fighting it. Three well-matched four-second clips usually beat one strained twelve-second clip.
How much of the frame moves? Complex full-frame motion, like a crowd or a waterfall, is where temporal consistency fails first. Reduce the amount of simultaneous motion, or accept a shorter clip.
What happens on the next cut? If the sequence returns to the same location, generate both shots from closely related reference frames so lighting and color match.
What is the tolerance for a retry? Some shots are cheap to regenerate thirty times; others are expensive or slow. Budget retries deliberately, and reserve high-cost models for the shots that genuinely need them.
A simple decision rule: reference-conditioned model for anything with a face or a product, camera-control model for anything with motivated movement, text-to-video for atmosphere and inserts.
Writing Prompts That Survive Multiple Shots
The most common mistake in AI video work is writing each prompt as an isolated poem. A sequence needs prompts that share a grammar.
Establish a locked vocabulary for each project and reuse it verbatim. If shot one says "soft overcast daylight, cool gray tones, 35mm lens feel," shot seven should say the same, not "overcast light, muted palette, telephoto look." Models do not know those are synonyms, and near-miss wording produces near-miss visuals that will not cut together.
A reusable shot prompt combines subject, action, camera, lighting and palette, environment, lens and grade, and a short negative note about what must not appear. The subject should carry one or two identifying details that stay identical across shots. The action should be one clear motion, described as a single continuous event, because two simultaneous complex actions usually produce mush. Camera should state framing, angle, and movement explicitly rather than leaving the model to guess.
A worked example. For a short brand film about a ceramicist, the locked vocabulary might be: "warm tungsten lamp light, deep shadows, muted terracotta and slate palette, 50mm lens, shallow depth of field, quiet workshop at night." Every prompt in the sequence carries that block unchanged, and only the subject, action, and camera lines vary.
Additional habits that pay off. Keep prompts in a spreadsheet or structured document with one column per attribute, because continuity errors are almost always bookkeeping errors, not model errors. Generate short: four to six seconds is a sweet spot for most models, and you should extend with cuts rather than with prompt begging. Describe motion as physical behavior rather than emotion, so "she exhales and her shoulders drop" instead of "she feels relieved" renders far more reliably. Specify one primary motion per shot; a camera move plus a subject move is fine, but a camera move plus two subject moves plus weather is usually not. Version your prompts, because when a shot works you want to know exactly which wording produced it.
Directing a Sequence Instead of Isolated Clips
Generating a clip is a craft. Generating a sequence is a directing job, and it needs a different layer of thinking.
Start with a shot list before you touch any model. Write the sequence in plain language first, as a paragraph of prose or a simple list of beats. Then break it into shots and mark each one as a setup, a development, or a payoff. This takes twenty minutes and saves hours of drifting generation.
Then decide the visual rhythm. Are shots long and observational, or quick and percussive? Rhythm determines clip length and camera behavior, and it should be consistent within a section of the film. A common failure is a sequence where half the shots feel like slow documentary observation and half feel like a trailer, purely because each shot was generated in isolation.
Make a continuity binder, even a lightweight one, and track location, time of day, and lighting state per shot; wardrobe and props per shot; screen direction of movement, so a character walking left to right keeps walking left to right across the cut; the reference frame used for each shot; and the exact prompt, seed, and settings used for each accepted clip. That last item matters more than people expect, because reproducibility is what separates a workflow from a lucky afternoon.
Finally, plan for the joins. Generate a few frames of overlap or a matching final frame for each shot so the editor has material to work with. Some models let you condition the last frame of one clip as the first frame of the next, which is the single most effective continuity technique available. Where that is not supported, keep the camera movement and subject position similar enough at the cut point that the audience does not notice the seam.
Turning Story Structure into Shot Instructions
An AI sequence still needs a narrative spine, and the spine dictates the shotlist.
For a thirty-second product film, a reliable structure is one establishing shot of the environment, one detail shot of the product in use, one human reaction shot, one wide shot with the product in context, and one closing frame. Five shots, each three to five seconds, is enough for a complete piece.
For a two-minute explainer, structure as an introduction, three to four concept beats, and a conclusion. Each concept beat can be a small sequence of two or three shots: a wide to establish, a medium for the action, and a close-up for the detail that proves the point.
For a narrative short, keep the number of distinct locations small. Every new location is a new continuity problem, and AI tools are at their weakest when a scene must look like the same place from radically different angles. When you translate beats into shots, write each shot as a single dramatic function. If a shot is trying to establish location, show character, and deliver information at once, split it. Single-function shots generate better and cut better.
Working Across Model Families and Fixing Failures
No single generator wins everything, and the strongest pipelines mix deliberately. A typical hybrid approach uses a text-to-video model for establishing shots and abstract transitions where invention matters more than control, an image-to-video model with a carefully prepared still for anything involving a character or product, a camera-control model for the hero shot that anchors the piece, and a fast, cheap model for rough animatics so you can test the edit before committing to expensive generations.
The animatic step deserves emphasis. Rough out the entire sequence at low quality, cut it together, and watch it. Most structural problems, such as a beat that drags or a transition that confuses, are visible even in placeholder renders. Fixing them before the final pass is dramatically cheaper in both time and generation budget. Beyond that, treat your model library as a portfolio and keep notes on which model handled which shot type best for your project's style. A model tuned for photoreal landscape work may be a poor fit for stop-motion aesthetics, and vice versa.
Failure modes follow predictable patterns. Identity drift across shots means the face or object changes gradually; fix it by moving to a reference-conditioned model, using a neutral reference image, and keeping lighting consistent between reference and target. Flicker and texture boil happens when the model re-decides surface details each frame; reduce fine high-frequency detail, lower simultaneous motion, and avoid extreme sharpening in post. Warping limbs and hands are the classic failure, fixed by reframing so hands are partly occluded or in motion blur, and by keeping them away from the frame edge where distortion concentrates. Melted or unreadable text should never be generated at all; generate a clean plate and add typography in the editor. Camera moves that fight the subject cause motion discomfort, so pick one dominant direction per shot. And shots that refuse to cut together usually have a palette or lens mismatch, best resolved by regenerating from a neighboring shot's frame or applying a unifying grade across the sequence.
If you are spending more time configuring than creating, you probably have too many models in play. Narrow to two for a given project: one for controlled shots, one for atmosphere.
Quality Control and a Repeatable Production Workflow
Before a sequence ships, run the same checklist every time. It takes ten minutes and prevents almost all embarrassing output. Watch at full speed once with sound off, because continuity errors are obvious when audio cannot carry you. Watch frame by frame at every cut and look for flash frames, resolution changes, or sudden grade shifts. Check every face and hand at full resolution rather than at timeline scale. Verify grade consistency with a scopes check, since eyes adapt to drift. Read all on-screen text out loud to confirm spelling and confirm nothing generated itself into the background. Confirm no unintended artifacts or logos appear in reflections or on product surfaces. Check audio sync on any lip movement, and honestly assess whether lip-sync should be avoided entirely by cutting away instead. Then export and test on a phone, because most audiences watch vertical, small, and in bright environments.
Keep a rejection log. When a shot fails a check, note which check and what caused it. Over a few projects, that log becomes the most useful document in your pipeline, because it tells you exactly which shot types to stop attempting with which models.
Once you have a few finished pieces, formalize the process into six stages. In stage one you write the piece in plain prose, with no model touching anything, to produce a script and a beat list. In stage two you convert beats into single-function shots marked as establishing, action, detail, reaction, or transition. In stage three you produce and approve a still for every shot containing a subject, because approving images is fast and approving video is slow. In stage four you generate low-cost, low-resolution versions of every shot and cut them together into a rough animatic that proves the edit works. In stage five you regenerate approved shots at full quality and assemble a locked picture. In stage six you finish music, ambience, voice, titles, grade, and delivery formats. Every approval then happens at the cheapest possible point, and you never spend heavy generation effort on a shot whose framing you have not already accepted.
A Worked Example: Sixty Seconds from Brief to Export
To make the workflow concrete, here is a compact walkthrough for a one-minute piece about a watchmaker's studio.
The brief is a quiet, observational film. The viewer should feel the slowness of the craft, with no voiceover. The beat list runs: an empty studio at dawn; hands on a bench with tools moving; a mechanism turning in close-up; the maker's face in concentration; a finished watch on the wrist in daylight; and a wide shot of the studio in use.
The shot list becomes nine shots: two establishing, four action or detail, one reaction, one product, one closing wide. The locked vocabulary is "early morning window light, dust in the air, warm oak and brass palette, 50mm lens, shallow depth of field, no music." Reference frames are generated and approved for the maker's face, the bench tools, the mechanism, and the final watch, all approved as images before any animation begins.
All nine shots are then generated at low resolution and cut to a temp track as an animatic. One structural fix emerges here: the reaction shot lands too early, so it moves after the mechanism close-up. For final generation, the controlled shots are regenerated with the reference-conditioned model, the two establishing shots are done with text-to-video for atmosphere, and the closing wide is regenerated from a frame of the first establishing shot so the dawn light matches. The finish is ambient room tone, subtle tool sounds, a minimal grade, and titles added in the editor rather than generated.
The whole piece uses two model families and one editing pass, which is representative of real production: modest tooling, disciplined continuity, and most of the value coming from shot planning rather than from any single generation technique.
Frequently Asked Questions
Do I need to be a video editor to use these tools? Not to generate, but the final twenty percent of quality comes from editing. Knowing how to cut on motion, match color, and control pacing is what makes a sequence feel intentional. If you only learn one editing skill, learn rhythm.
How do I keep a character consistent across many shots? Use a reference-conditioned model, start with a neutral, evenly lit reference image, lock your lighting vocabulary, and regenerate problem shots from a neighboring shot's frame rather than from the original reference. Consistency is usually a continuity bookkeeping task, not a prompt-writing one.
Which is better, text-to-video or image-to-video? Image-to-video for anything with a subject, product, or specific composition. Text-to-video for atmosphere, environments, and abstract inserts. Most finished pieces use both.
Why do my clips look great alone but wrong together? Palette, lens, and motion direction do not match. Fix it with a shared vocabulary block, matched camera behavior, and a unifying grade across the sequence.
Should I generate text inside the video? Almost never. Add typography in the editor. It is sharper, editable, and cannot misspell itself.
How long should each clip be? Four to six seconds is a comfortable default for most models. Plan the edit around that limit rather than trying to force longer continuous takes.
Can I use these tools for client work? Usually yes, but confirm the licensing terms of both the model and any reference images you supply, and keep documentation of your sources. Model terms differ meaningfully, and clients increasingly ask.
What is the fastest way to improve output quality? Stop generating single clips. Build a shot list, approve reference frames as stills, and test the whole sequence as a low-resolution animatic before committing to final generation.
Where This Is Heading
The direction of travel is clear on three fronts. Control is increasing, with more explicit camera, motion, and subject conditioning replacing prompt roulette. Consistency is improving, making recurring characters and multi-shot sequences practical rather than experimental. And integration is deepening, so generation sits inside the edit rather than beside it. Planning also matters more, not less: as raw model quality converges, the differentiator shifts to how well you direct, sequence, and finish.
For creative people, the practical implication is that the skill worth developing is not prompt memorization. It is directing: knowing what a shot needs to accomplish, how it joins the next one, and what to reject. The tools will keep changing. A disciplined shot list, a continuity binder, a locked visual vocabulary, and a staged approval workflow will keep working regardless of which model you open next month.
Start small. Pick one thirty-second piece, run it through all six stages, and keep the rejection log. That single exercise will teach you more than a month of scrolling through other people's generated clips.
