
Why AI Video Stopped Being a Novelty
A few years ago, generating a convincing video clip from a text prompt felt like a magic trick. You typed a sentence, waited, and got something that looked almost real — if you squinted, ignored the melting hands, and accepted that the camera would drift for no reason. That era is over. Generative video has become a production discipline with its own craft, its own vocabulary, and its own set of failure modes.
The practical consequence is simple: the interesting question is no longer "can AI make a video?" It is "how do I build a workflow that produces a watchable video reliably, on a deadline, without burning a week on retries?"
That question has three parts. First, model selection — matching the strengths of different generative engines to the specific shots you need. Second, control — using prompts, reference images, and motion instructions to get predictable results instead of lottery tickets. Third, assembly — treating generated clips as raw footage that still needs editing, sound, grading, and quality control.
Most creators who struggle with AI video are strong in one of these areas and weak in the others. They write beautiful prompts but have no shot list. They have a shot list but pick the wrong model for a close-up of a human face. They generate gorgeous clips and then paste them together with no sound design, so the result feels like a demo reel rather than a film.
This guide is a practical workflow for closing those gaps. It is tool-agnostic on purpose: the specific model names change quickly, but the underlying craft of planning, prompting, and finishing does not.
Pick the Right Model for the Shot, Not for the Project
The most common inefficiency in AI video work is choosing one model for an entire project because you learned it first. In practice, different engines are genuinely better at different jobs, and mixing them inside a single edit is normal professional behavior.
Think in terms of shot classes, not projects.
Photoreal humans, faces, and product beauty shots
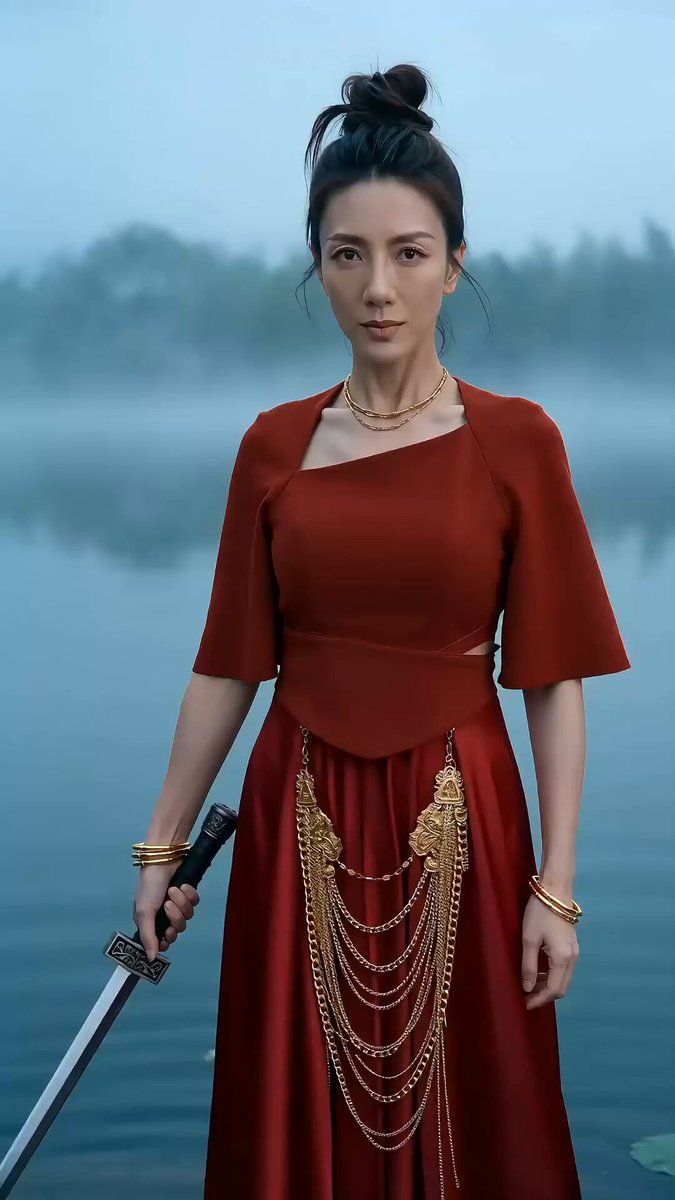
When a shot depends on a believable human face, skin texture, or a product lit like a commercial, prioritize models with strong photoreal rendering and stable facial geometry. These engines tend to produce clean detail on eyes, hair, and fabric, and they handle slow, subtle movement better than fast action.
For these shots, plan short durations — three to five seconds — and let editing create the sense of length. A four-second shot of someone turning their head can carry more emotional weight than a twelve-second shot where the model runs out of coherent motion and starts improvising.
For still imagery that will later be animated, image models with strong photographic realism are useful as a first step: generate a perfect frame, then use it as the starting image for a video model. This hybrid approach is often the single biggest quality upgrade available to a creator.
Motion, lens behavior, and camera control
Some engines are built for movement: sweeping drone shots, whip pans, push-ins, rack focus, and complex camera paths. When your shot list includes camera language — "slow dolly left as she turns," "low-angle tracking shot through a corridor" — lean on models that respond well to explicit camera direction.
The test is simple. Generate the same prompt twice with two different engines. If one gives you a stable camera path and the other gives you a drifting, unstable frame, that is your camera model for the project, even if the other engine produces prettier stills.
Stylized and region-specific aesthetics
Different training datasets produce different visual dialects. Some models render anime, manga, and stylized illustration with far more coherence than others. Others excel at specific regional aesthetics — the lighting, color palettes, and framing conventions common in East Asian commercial and cinematic work.
If your brand or story lives in a particular visual world, test a few engines on a single reference prompt and compare. You will often find one model that simply "understands" your intended look, and using it consistently gives your project a coherent identity across every shot.
Draft engines and final engines
Not every generation needs to be final quality. A useful workflow splits into two passes:
- Draft pass: fast, inexpensive generation to test composition, blocking, and pacing. You are not judging detail; you are judging whether the shot works.
- Final pass: slower, higher-quality generation of only the shots you have confirmed. Usually with more careful prompting, a reference image, or both.
This single habit is the difference between a smooth project and a week of grinding. Generating twenty variations of a shot at final quality is wasteful. Generating twenty quick blockouts, choosing two, and then producing those two properly is efficient and produces better work.
Pre-Production: The Part Most Creators Skip
Pre-production in AI video is not paperwork. It is the mechanism that prevents you from prompting in circles.
Shot lists built for generation
Write your shot list before you open any tool. For each shot, capture:
- Duration — usually 3–8 seconds for a generated clip.
- Subject and action — what is on screen and what changes during the shot.
- Camera — angle, movement, and lens feel.
- Light and mood — time of day, key light direction, color temperature.
- Continuity anchors — which character, wardrobe, prop, or location this shot must match.
A shot list turns an open-ended creative task into a checklist. It also reveals problems early. If your list contains a shot of two characters shaking hands in close-up, you already know that is a high-risk generation: hands, contact, and two faces in one frame. You can redesign it as two separate shots before you waste an afternoon.
Lookbooks and reference stills
Collect ten to twenty reference images for each project: color palettes, lighting examples, wardrobe, locations, and framing. These do two jobs. First, they clarify your own intent so your prompts become more specific. Second, they can often be used directly as image inputs to guide generation.
A reference image is worth several paragraphs of prompt text. When a model can see the color grade and composition you want, it stops guessing.
Continuity documents
Write one short block of text describing each recurring element — character, costume, location, prop. Keep the wording identical every time you use it. Consistency in AI video is partly a technical problem and partly a discipline problem: if you describe the same jacket differently in three prompts, you will get three jackets.
A simple continuity sheet might include:
- Character A: age range, build, hair, distinguishing features, wardrobe.
- Location B: architecture, time of day, dominant colors, weather.
- Prop C: material, size, condition, position relative to the subject.
Paste these blocks into prompts verbatim. It feels mechanical. It works.
Prompting for Cinematic Control
Prompts are not wishes. They are shot descriptions, and they work best when written like a director's note rather than a poem.
A reliable structure for a video prompt has five layers:
- Subject — who or what, with continuity text.
- Action — one clear motion, not three.
- Camera — angle, movement, lens.
- Lighting and mood — time, source, tone.
- Style and texture — genre, grade, film stock feel.
Camera language that actually lands
Use specific, conventional terms. "Slow dolly in," "handheld follow," "static wide," "low angle," "over-the-shoulder," "shallow depth of field," "24mm wide," "85mm portrait." These map to real cinematography concepts that most models have seen labeled in training data.
Avoid vague intensity words like "epic," "cinematic," or "stunning" as your only camera instruction. They add mood but no geometry, and geometry is what makes a shot readable.
Lighting and grade
Specify direction and quality, not just time of day. "Golden hour, soft rim light from the left, warm highlights, cool shadows" gives a model far more to work with than "sunset."
If your project has a defined look, repeat the grade description in every prompt: "desaturated teal shadows, warm skin tones, gentle halation." Repetition across shots is what makes a sequence feel like one film.
Motion verbs and tempo
One primary motion per shot. If you want a turn, a step, and a hand gesture, that is three shots, not one prompt. Models handle compound action by blending it into mush.
Tempo words help: "slow," "deliberate," "gradual," "steady." Fast, chaotic motion is the hardest thing for generative video to keep coherent, so if you need energy, get it from editing and sound rather than from a single overloaded clip.
What to leave out
Do not cram your entire creative vision into one prompt. Long prompts with contradictory instructions — "static camera" plus "sweeping dynamic movement" — produce unpredictable results. Keep prompts focused, and use multiple generations to build complexity rather than describing all of it at once.
Keeping Characters and Scenes Consistent
Continuity is the hardest problem in AI video and the one that most often breaks immersion. There are four practical levers.
Reference images. The most reliable method. Generate or photograph a clean, well-lit reference of your character or location, then use it as an image input on every shot. Keep the angle and lighting of the reference neutral so it does not fight the shot you are making.
Locked descriptive text. Copy the same continuity paragraph into every prompt without paraphrasing. Small synonym changes cause visible drift.
Shot design that avoids stress. If a face must stay identical, avoid extreme close-ups where any deviation is obvious, and avoid fast head turns. Medium shots, profile angles, and slight motion are far more forgiving.
Editing as continuity. Cutaways, inserts, reaction shots, and sound can hide a great deal. If a character looks slightly different in two shots, inserting a two-second cutaway of hands, a prop, or the environment makes the transition feel intentional rather than broken.
A rule of thumb: plan for one or two hero shots where consistency must be perfect, and design the rest of the sequence so it does not depend on scrutiny. You cannot fix every shot, but you can control which shots the audience examines closely.
From Clips to a Finished Sequence
Raw generated clips are not a video. They are footage. The edit is where the piece becomes watchable.
Order and pacing
Start with the strongest clip as your anchor, then build backward and forward from it. Cut on motion — a turn, a step, a hand entering frame — because motion hides cuts better than a static transition.
Keep shots shorter than you want to. A three-second shot that feels complete beats a six-second shot where the model starts drifting at second four. If a clip "falls apart" in the final third, cut it.
Sound
Sound is the single highest-leverage upgrade for AI video. Ambience, footsteps, fabric rustle, room tone, and a light music bed make generated footage feel grounded. Without sound, even beautifully rendered clips read as artificial.
Layer three elements:
- Ambience — continuous background that establishes place.
- Spot effects — sounds tied to visible actions.
- Music — pacing and emotional framing.
If dialogue is needed, generate or record voice separately and cut to it, rather than trying to sync performance to a clip. Write dialogue for rhythm, not for perfect lip sync, and avoid long close-up speaking shots unless you have the tools and time to handle them properly.
Upscaling, grain, and finishing
Apply upscaling before final grading, not after. Then add a consistent finish across all clips: film grain, slight color grade, subtle vignette, and matched contrast. A shared finishing pass is what makes clips from different models look like they belong to one project.
Export at your delivery resolution and codec, and keep a high-bitrate master. You will thank yourself when the same footage needs a vertical cut for social.
A Quality-Control Checklist Before You Export
Run the same checks on every project. It takes minutes and catches most embarrassments.
- Faces: eyes symmetrical, teeth sane, no identity drift between shots.
- Hands: finger count, wrist angle, contact with objects.
- Motion: no reversed limbs, no sliding feet, no warping edges.
- Physics: liquid behaves like liquid, cloth falls downward, shadows match light direction.
- Text: any signage or logo is either correct or removed — generated text is rarely right.
- Continuity: wardrobe, props, hair, time of day, and weather stay consistent.
- Audio: no clipping, no jarring ambience jumps at cuts, consistent loudness.
- Pacing: does the piece hold attention at 1x speed with sound on, on a phone screen?
Watch the whole thing once with sound and once muted. Problems that hide in the audio mix often appear in silence, and vice versa.
Common Mistakes and Fixes
Overloading prompts. Fix: one action, one camera move, one lighting idea per generation.
Generating final quality too early. Fix: blockout with fast drafts, then promote only the winners.
Ignoring aspect ratio until the end. Fix: decide delivery format first. Vertical, square, and widescreen need different compositions, and reframing after the fact always loses something.
No reference images. Fix: build a small lookbook and use image inputs whenever the tool supports them.
Treating each clip as independent. Fix: write a continuity sheet and reuse the exact wording.
Neglecting sound. Fix: budget as much time for audio as for generation. It is not decoration; it is half the experience.
Chasing perfection on one shot. Fix: set a retry limit. Ten attempts, then redesign the shot into something simpler or split it into two.
Copying trends instead of building a look. Fix: define a visual signature — palette, lens choice, pacing — and repeat it. Recognition comes from consistency, not novelty.
Building a Repeatable Practice
The creators who get good at this are the ones who run deliberate practice loops rather than one-off experiments.
A simple weekly routine:
- Day 1 — Study. Pick one short film, ad, or music video. Break it into shots. Count the durations. Note the camera moves.
- Day 2 — Imitate. Rebuild three shots from that reference using your tools. Do not aim for a full sequence; aim for matchable single shots.
- Day 3 — Push a weakness. Whatever failed last week — hands, motion, consistency — becomes today's only subject.
- Day 4 — Build a sequence. Take five to eight clips and cut them into a thirty-second piece with sound.
- Day 5 — Review and document. Write down what worked, what the model struggled with, and the exact prompts that produced your best results. Keep a personal prompt library.
Over a couple of months, this produces something more valuable than any single project: a personal knowledge base of what your tools can and cannot do, with evidence.
FAQ
How long should a generated clip be?
Three to eight seconds is the practical sweet spot. Longer clips tend to lose coherence, drift in identity, or develop unstable motion. Build length through editing rather than a single long generation.
Do I need to use only one model for a project?
No. Use the strongest engine per shot class, then unify the result with a shared grade, grain, and sound design. The finishing pass creates cohesion that the generation stage cannot.
Why do my characters change between shots?
Usually because the descriptive text changed slightly, no reference image was used, or the shots are framed so tightly that small differences become obvious. Lock your wording, use image inputs, and favor medium shots for recurring characters.
What is the fastest way to improve quality?
Add reference images and add sound. Those two changes tend to lift perceived quality more than switching to a different model.
Should I start with a script or with images?
Start with a shot list. A script tells you what happens; a shot list tells you what to generate. For AI video, the shot list is the actionable document.
How do I handle dialogue?
Generate or record it separately, then cut the visuals to the audio. Avoid depending on perfect lip sync unless it is central to the piece.
How many attempts should a shot get?
Set a limit of eight to ten generations for a hero shot. If it still is not working, the prompt or the concept is the problem, not the model. Simplify, reframe, or split the shot.
What makes AI video look obviously artificial?
Unstable hands, drifting faces, physics that ignores weight, abrupt motion, silent footage, and inconsistent color between shots. Almost all of these are fixable through better shot design, a finishing pass, and audio.
Do I still need editing skills?
More than ever. Generation gives you footage. Editing gives you a film. Learning basic cutting, pacing, sound layering, and grading will improve your output more than any prompt trick.
Where the Craft Is Heading
The tools will keep changing. Model names will rotate, quality will rise, and controls that require careful prompting today will become defaults tomorrow. What will not change is the underlying discipline: plan the shot, control the frame, keep the world consistent, and finish the piece with sound and grade.
Treat generative video as a production pipeline rather than a slot machine. Draft cheaply, commit deliberately, design shots around each engine's strengths, protect continuity with references and locked text, and always leave room in your schedule for the edit. Do that, and the technology stops being a novelty you show people and starts being a craft you actually use.
