
Why AI video storytelling changed the production pipeline
For most of film history, the gap between an idea and a finished shot was measured in money and logistics. A rooftop chase required permits, a stunt team, insurance, and a shooting window. Today the same gap is measured in prompt iterations and render minutes. That shift does not remove craft from the process; it relocates it. Instead of solving logistics, the storyteller solves intent: what exactly should the audience feel in this second, and which generated take delivers it?
Generative video models have become good enough that the first draft of a scene is now nearly free to attempt. That changes the economics of creative risk. You can test three visual interpretations of the same beat before lunch and keep the one that lands. The bottleneck moves from production capacity to decision-making: knowing which take is right and how to keep a coherent world across dozens of clips.
This article is a working method, not a tour of features. It covers the full path from a written idea to an exported, publishable video, with the parts that usually break: shot planning, prompt structure, visual consistency, quality control, and sound design.
The five stages of an AI video workflow
Treat AI video like a production pipeline with five stages. Skipping a stage rarely saves time; it just moves the rework later.
Stage one: story and script
Write the script as if a camera had to shoot it. Every line should imply an image. "She realized she had been wrong" is unshootable; "she stops mid-sentence, looks down at the unopened letter, and sets her cup down" is a shot.
Keep a one-page beat sheet with a single sentence per beat: setup, turn, escalation, resolution. Six to eight beats is plenty for most short-form videos and keeps the generation work bounded.
Stage two: shot list and visual language
Convert beats into shots, and give each shot a job. Label them by function rather than beauty: establishing, character introduction, tension, product detail, emotional close, transition.
Decide the visual language before generating anything. Pick a palette, a lens feel (wide and cool versus tight and warm), a movement rule (locked-off, slow push, handheld drift), and a texture rule (clean, filmic grain, archival). Write these into a style block that you paste into every prompt. Consistency in AI video comes from repeated constraints, not from a model remembering your earlier clips.
Stage three: generation and iteration
Generate in passes. Pass one is silhouette and composition: cheap, fast settings, low resolution, just to confirm the framing. Pass two is performance: the expression, the timing, the motion. Pass three is finishing: the highest quality setting on the clips you actually intend to use.
Most beginners do this backwards, burning their best settings on shots they later cut.
Stage four: assembly and edit
Bring clips into an editor and cut for rhythm before you fix anything else. A slightly soft shot that lands on the beat beats a pristine shot that drags. Then layer in titles, transitions, and any live-action inserts.
Stage five: sound, captions, and delivery
Sound is where AI video gains credibility. Foley, room tone, a music bed with a real dynamic arc, and a mix that dips under dialogue do more for perceived production value than another round of generation.
Captions should be burned in or uploaded as a separate file depending on the platform, and the aspect ratio should be decided at the script stage, not after export.
Choosing the right generation approach for each shot
Not every shot needs the same technique. Matching the approach to the shot is the single biggest efficiency gain in an AI video workflow.
Text-to-video, image-to-video, and video-to-video
Text-to-video is best for establishing shots, abstract montages, and anything where the exact geometry does not matter. It is fast and surprising, and it is the wrong tool for a recurring character.
Image-to-video takes a still you have composed and animates it. This is the workhorse for character shots, product shots, and any frame where composition must be exact. You design the frame in a still image tool, then animate it with a controlled camera move.
Video-to-video restyles existing footage, which is ideal when you have real performances and want a stylized look. It also works well for turning a rough 3D previsualization into something photoreal.
Motion presets, camera moves, and loops
Explicit camera language beats vague adjectives. "Slow dolly in" and "locked-off wide" produce more predictable results than "cinematic". If your tool offers motion strength controls, keep them low for dialogue and medium for landscapes; high values tend to warp faces and hands.
Loops are underrated. A six-second seamless loop of steam, rain, or traffic can be reused across a project as connective tissue, saving generation time and money.
Prompt craft that actually controls the frame
A prompt is a shot brief compressed into one paragraph. If your prompt reads like a mood board, you will get mood board results.
The five-slot prompt structure
Use five slots in order:
- Subject and wardrobe. Who or what, with specific, non-generic detail.
- Action and beat. What changes during the shot.
- Camera. Framing, angle, movement, and speed.
- Light and time of day. Source, direction, and quality of light.
- Texture and style. Grain, lens character, palette, reference era.
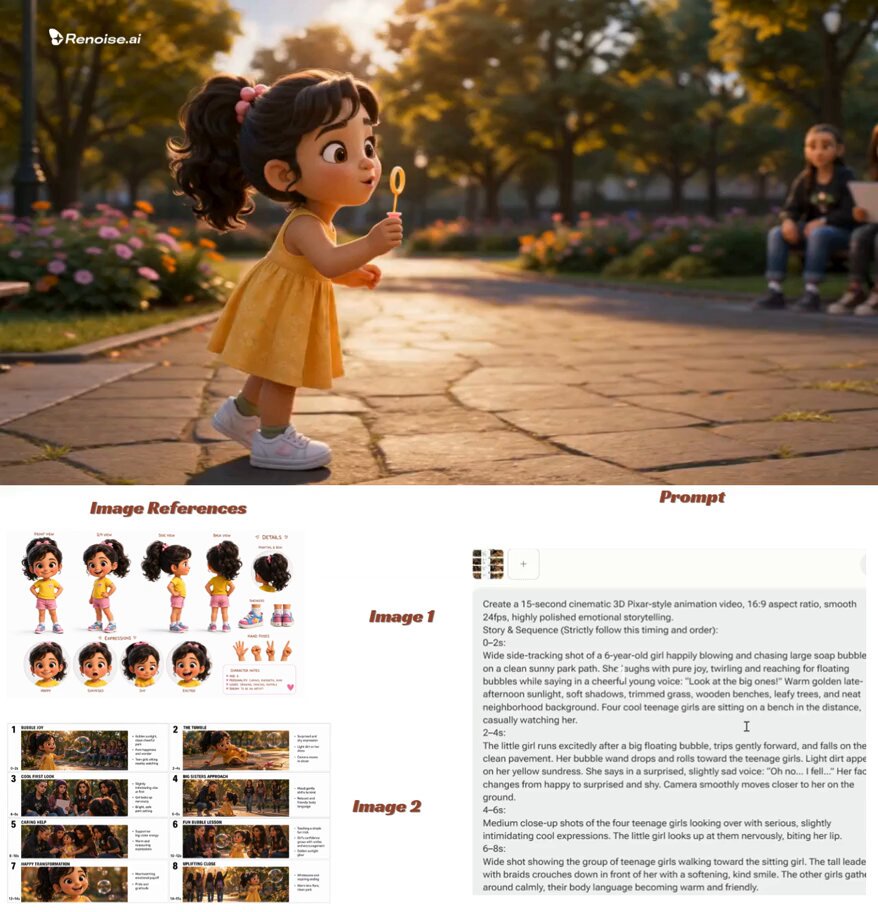
A concrete example: "A middle-aged fisherman in a faded yellow raincoat, hands cracked from salt; he pulls a rope hand over hand, shoulders rising with effort; medium shot, low angle, slow dolly in; overcast dawn light, soft and blue, single warm lamp behind him; 35mm film grain, muted teal and amber palette."
That prompt gives the model five independent decisions instead of one vague vibe.
Negative prompts, continuity anchors, and seeds
Negative prompts remove recurring failures: extra fingers, text overlays, watermarks, jittery motion, duplicated limbs, sudden cutaways. Keep the list short and specific; long negative lists create their own artifacts.
Continuity anchors are details repeated in every prompt for a scene: the raincoat color, the lens, the time of day, the camera height. They are your continuity department.
Seeds matter more than most people admit. Reusing a seed across a shot keeps noise patterns stable, which reduces visible flicker when you cut between takes.
Building a consistent look across scenes
Character and world consistency is the hardest part of AI video, and it is solved with constraints, not luck.
Start with a character sheet: three reference stills in different lighting, plus a text block describing face shape, hair, wardrobe, and distinguishing marks. Reuse that block verbatim. Small wording changes produce different faces.
For environments, define an anchor frame for each location and derive all shots in that location from it, either by animating the anchor or by using it as a style reference. This keeps walls, windows, and furniture in the same places.
Color is a continuity tool too. Applying one grade across all clips in post hides small inconsistencies in white balance and contrast. A simple LUT applied at the end of the edit makes ten generated clips feel like one film.
Finally, accept that some scenes should not be AI-generated. Live-action inserts, screen recordings, and simple graphics anchor an AI world and make the generated shots read as intentional rather than synthetic.
Managing time, cost, and renders without a studio budget
AI video projects fail on planning, not on tooling. A few habits keep them on schedule.
Tier your resolution. Preview at the lowest resolution that lets you judge motion and composition. Only the final selects get the expensive pass.
Batch by location and lighting. Generating all the dawn exterior shots in one session keeps your prompt context fresh and reduces drift between takes.
Keep a shot tracker. Columns for status (scripted, prompted, generated, selected, edited), take count, and notes on what failed. Without it, you will regenerate shots you already have.
Set a take budget per shot before you start. Three to five takes is normal for a clear prompt. If you are on take twelve, the prompt is the problem, not the model. Rewrite the shot or change the approach.
Store your winning prompts. A prompt library organized by shot type (establishing, dialogue, product, transition) turns each project into a faster one.
Quality control: catching artifacts before they reach the edit
Watch every clip at full speed and again frame by frame. Common failures cluster in predictable places.
Hands and fingers morph, merge, or multiply; keep hands out of frame or moving through occluded space when possible. Faces lose identity during fast turns; use slower motion for close-ups. Text of any kind will render as gibberish, so add real text in post. Backgrounds breathe and warp at the edges; a slight crop solves most of it. Physics breaks in reflections, liquid, and cloth; cut before the break or cover it with a transition. Lip sync drifts after four or five seconds, so keep talking-head shots short and cut on movement.
Build a fix list as you review, and only regenerate shots that fail on story or identity. Everything else is usually cheaper to hide with editing, sound, or a different take.
A worked example: a sixty-second brand story from brief to export
Here is the whole pipeline on a realistic project.
Write the beat sheet: a craftsperson opens a workshop at dawn, chooses a tool, makes a mistake, corrects it, and holds up the finished object. Six beats, sixty seconds.
Build the shot list: wide establishing of the workshop, close-up of hands on a drawer handle, medium of the tool selection, insert of the mistake, medium of the correction with a small smile, and a final product shot against a window.
Define the style block: warm morning light, 40mm lens feel, gentle handheld drift, fine grain, palette of amber, walnut, and pale blue.
Create a character sheet from three reference stills and lock the wardrobe description.
Generate pass one at low resolution for framing across all six shots. Cut them together silently to check pacing. Two shots do not work: the workshop wide feels empty, and the mistake insert is unreadable. Rewrite both prompts with more specific foreground detail and a clearer action.
Generate pass two at preview quality for the four surviving shots plus the two rewrites. Select takes, note any hand or face problems, and regenerate only those.
Animate the final selects at full quality. Import into the editor, cut to a temporary music track, then replace it with a licensed track that has a build and a resolution on the final beat.
Add sound design: room tone, tool clinks, a drawer slide, footsteps on wood, and a soft breath before the final hold. Add captions in the platform's aspect ratio, export a vertical version and a landscape version, and check both on a phone before publishing.
Total generation time is a few hours spread across a day, and most of it is spent on the two shots that were rewritten, not on the one that worked immediately.
Common mistakes and how to avoid them
Chasing realism before structure. A believable texture on a badly paced scene is still a bad video. Cut first, polish second.
Writing one prompt per scene. Long scenes need multiple shots. If a prompt describes two actions, split it.
Ignoring aspect ratio. Vertical first drafts cannot be reframed into cinematic wides without losing the composition. Decide the frame at the script stage.
Generating without a style block. Inconsistent color and lens language reads as amateur faster than any artifact.
Overloading negative prompts. Twenty exclusions can produce stranger output than none. Use five or six that address your actual recurring failures.
Skipping sound. Silent AI video feels unfinished; foley and music are the cheapest quality upgrade available.
Never reviewing at full speed. Frame-by-frame inspection misses rhythm; full-speed viewing misses artifacts. Do both.
Refusing to shoot live. A ten-second phone clip of a real hand or a real location can rescue an entire sequence.
FAQ
How long should an AI-generated shot be?
Four to eight seconds is the practical sweet spot. Longer clips drift, and you will cut them down anyway.
Do I need a powerful computer to work this way?
Not necessarily. Generation can happen in a browser; the heavier requirements are for editing, grading, and export. A mid-range laptop with a stable connection handles most workflows.
How do I keep the same character across scenes?
Use a written character block plus reference stills, reuse the same seed where possible, keep lighting and lens language consistent, and grade everything together at the end.
Should I write prompts in English?
Most models are trained heavily on English descriptions, so English prompts tend to be more predictable, but you can write in your own language if the tool supports it well. Test both on the same shot and compare.
What is the fastest way to improve?
Rebuild one thirty-second video three times with different style blocks, and compare. Iterating on a small complete piece teaches more than generating hundreds of disconnected clips.
When should I stop using AI for a shot?
When the shot depends on precise human performance, readable text, or a specific real location. Use live footage and reserve generation for what it does best: worlds, weather, scale, and texture.
