
Why AI Video Synthesis Changed the Production Pipeline
Not long ago, generating a usable moving image from a text prompt meant accepting a trade: you got novelty, but you paid for it with melted faces, drifting backgrounds, and motion that looked like an early-web GIF. That trade has mostly collapsed. Modern synthesis systems can hold a character's face steady through a pan, keep a skyline consistent across a nine-second push-in, and respond to camera language like "slow dolly left, 35mm, shallow focus" with something that looks intentional rather than accidental.
The practical consequence is that video production now has a second front end. The first front end is still the traditional one: script, storyboard, location, crew, edit. The second front end is generative: prompt, reference frames, iteration, upscale, edit. Most teams end up running both in parallel, and the interesting craft question is no longer "can AI make video?" but "which shots belong in which pipeline?"
A talking-head testimonial with a real person? Traditional. A surreal dream sequence where a city folds in on itself? Generative, almost certainly faster and cheaper. A product close-up that has to match an existing brand asset pixel for pixel? Generative, but with a reference image driving the shot rather than text alone.
This guide walks through how current text-to-video systems work, how to choose between them, how to write prompts that survive motion, how to keep characters consistent across shots, and how to finish a sequence so it reads as a film rather than a demo reel.
How Modern Text-to-Video Systems Work
Almost every serious system today is a hybrid. Understanding the two underlying families helps you predict where a model will fail.
Diffusion-first pipelines
Latent diffusion was built for still images, then extended across time. The model denoises a compressed representation of a video clip, and an extra temporal layer keeps adjacent frames from disagreeing with each other. Diffusion-first systems tend to be excellent at texture, lighting, and photoreal faces, and they are often steerable with reference images, depth maps, or masks.
The weakness is temporal reasoning. Ask a diffusion-first model to depict a cause-and-effect action — a glass tipping, spilling, and shattering in order — and it may render three beautiful moments that don't quite connect.
Transformer-based sequence models
Transformer systems treat video as a sequence of patches, much like a language model treats words. They learn longer-range dependencies, which is why they handle multi-shot continuity, camera moves, and physics-adjacent behavior more gracefully. When you ask for a camera to orbit a subject and the background reveals correctly, you are usually watching a sequence model at work.
The trade-off is often speed and controllability. Long-context sequence generation is expensive, and the interfaces tend to be more conversational and less knob-heavy.
Where the two converge
In practice, the strongest results come from a chain, not a single model. A common pattern:
- Generate a still keyframe with an image model or a reference photo.
- Animate it with a video model in image-to-video mode.
- Extend or interpolate to reach the target duration.
- Upscale and stabilize in a finishing pass.
Treat each model as a specialist, and the pipeline stops being a magic box and starts being a bench of tools.
Choosing a Model: A Practical Decision Framework
Model choice is not about which one is "best." It is about which failure mode you can tolerate on this specific shot. Score candidates against five criteria.
1. Prompt adherence versus realism
Some systems prioritize doing exactly what you said, even if the result is stylized. Others prioritize looking photographic and quietly ignore half your instructions. If your script depends on a specific action — "a hand lifts the lid and steam escapes" — adherence matters more than sheen. If you need a moody establishing shot, realism wins.
2. Duration and shot length
Short generations (four to six seconds) are cheap to iterate and easy to cut. Longer generations save effort but cost more per attempt and often degrade in the final second. A good rule: generate short, cut on motion, and let the edit create the illusion of length.
3. Reference and keyframe support
If you have brand assets, character designs, or a storyboard, keyframe support is non-negotiable. Image-to-video with a strong first frame gives you more control than any paragraph of text.
4. Aspect ratio and resolution
Horizontal for narrative and YouTube, vertical for social, square for certain ad placements. Check whether the model supports your ratio natively or crops, because cropping changes composition in ways that break framing.
5. Cost per usable second
The only metric that matters economically is not cost per generation — it is cost per usable second after you have thrown away the rejects. A cheaper model that needs eight attempts is more expensive than a pricier model that lands in three.
Open ecosystems and flexibility
Beyond the headline models, there is a growing ecosystem of open-weight and library-hosted video models. These matter when you need on-premise processing, custom fine-tuning, unusual aspect ratios, or protection for sensitive footage. They also let you swap engines when a new release changes the quality bar, without rewriting your entire pipeline.
Writing Prompts That Survive Motion
A prompt that produces a gorgeous still often produces a chaotic clip, because motion introduces everything a still frame hides: weight, direction, timing, and interaction.
The six-slot prompt structure
Build every prompt from these slots, in order:
- Shot type — wide establishing, medium two-shot, tight close-up, over-the-shoulder.
- Subject — who or what, with age, wardrobe, and one identifying detail.
- Action — a single, physical, present-tense verb phrase.
- Camera — lens, height, and movement ("35mm, eye level, slow dolly in").
- Light — time of day, source, color temperature, contrast.
- Texture — film grain, lens flare, atmospheric haze, stock reference.
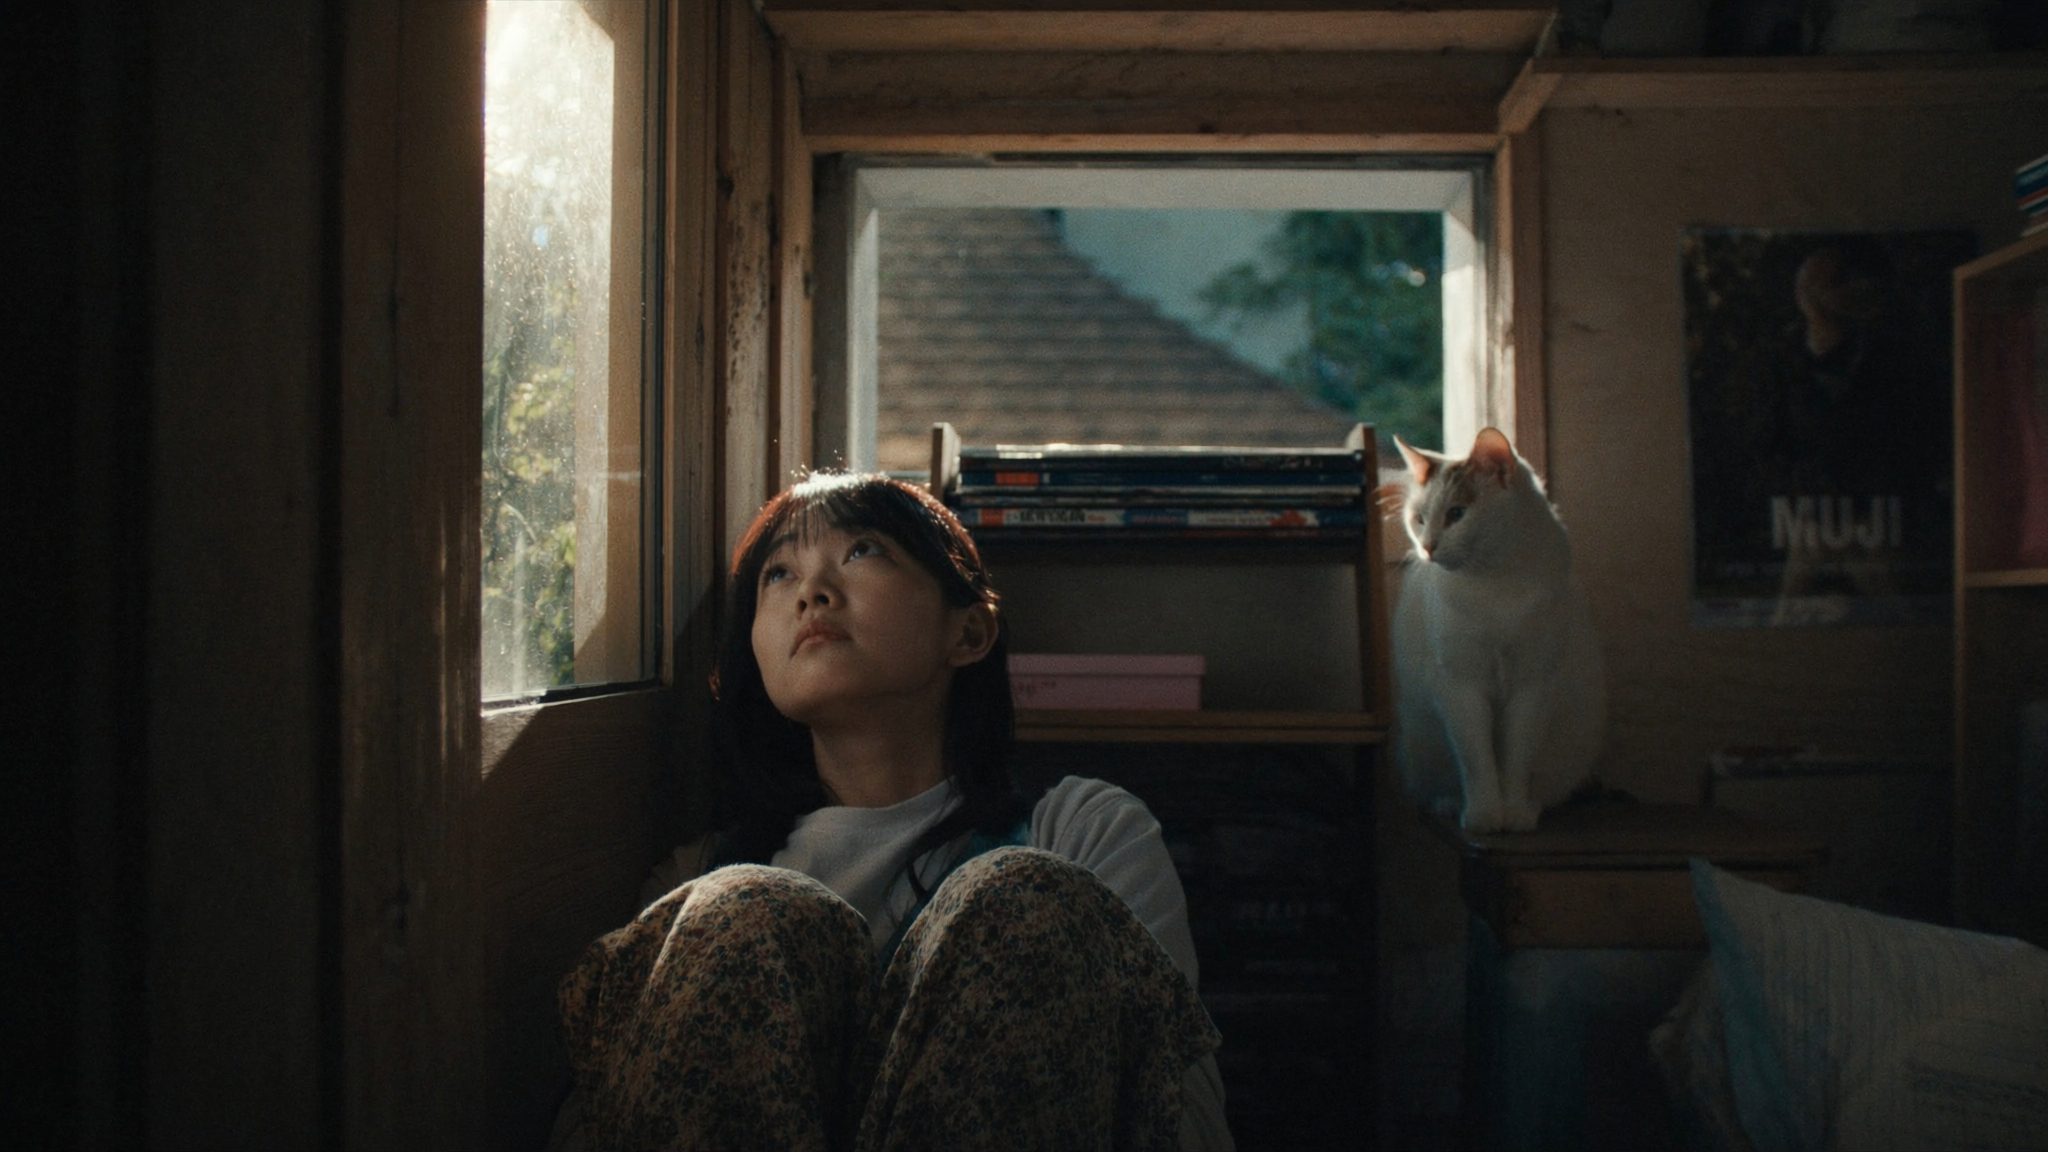
Example: Medium close-up of a woman in a rain-soaked wool coat, lifting a lantern toward a doorway, 50mm, eye level, slow push in, dusk with warm practical light from the left, fine grain and light haze.
That is one action, one camera move, one light source. When you stack three actions, the model averages them into mush.
Negative prompts and failure vocabulary
Most interfaces accept negative prompts. Useful entries: warped hands, extra limbs, flickering background, morphing face, text artifacts, jitter, rubbery motion, oversaturated.
Add a negative term every time you reject a generation for the same reason. Your personal negative list becomes more valuable than a generic one.
Camera language beats adjectives
Words like cinematic and epic do very little. Concrete camera instructions do a lot. Compare:
- Weak: "epic cinematic shot of a hero."
- Strong: "Low-angle medium shot, 24mm, slow crane up, backlit by a setting sun, dust in the air."
The second prompt tells the model where to put the camera and what the light is doing. That is most of what "cinematic" means.
Iterate one variable at a time
When a generation fails, change exactly one thing: the action, the light, or the camera. Changing all three teaches you nothing about which one mattered.
Keeping Characters and Scenes Consistent Across Shots
Consistency is the difference between a clip and a scene. Three techniques carry most of the weight.
Keyframes and first/last-frame control
If the model accepts a first and last frame, you can choreograph a shot precisely: give it the starting composition and the ending composition, and let it interpolate. This is the closest thing to animation direction that text-to-video offers, and it is dramatically more reliable than describing the motion in words.
Character reference and multi-image fusion
Feed two to five reference images of the same person from different angles, and the model learns the face as a concept rather than a single pose. Best practices:
- Use references with even, frontal lighting.
- Avoid heavy makeup or extreme angles that the model will overfit to.
- Keep wardrobe consistent between references and prompt.
- Reuse the same reference set for every shot in the sequence.
Scene locking with a style guide
For environments, write a reusable "scene block" — three sentences describing architecture, palette, weather, and lens — and paste it verbatim into every prompt in that scene. Small wording changes produce large visual changes, so resist improvising.
A quick test for consistency: generate three shots, place them side by side, and squint. If the palette and the light direction match, your scene is locked. If not, fix the scene block before generating anything else.
Cinematic Control: Lenses, Movement, and Pacing
Synthesis models respond surprisingly well to real cinematography vocabulary. A short glossary worth memorizing:
| Term | What it does in a prompt |
|---|---|
| 24mm / 35mm / 85mm | Widens or compresses perspective |
| Dolly in / truck left | Changes the camera's physical position |
| Pan / tilt | Rotates in place, cheaper-looking if overused |
| Rack focus | Shifts attention between planes |
| Handheld | Adds subtle instability and realism |
| Crane up | Reveals scale |
Two rules keep camera work from feeling cheap. First, one move per shot — a dolly and a pan in the same clip reads as a glitch. Second, cut on the move. Ending a shot mid-motion and starting the next one mid-motion creates energy that static framing cannot.
Pacing is a separate skill. Generate longer than you need, then trim in the edit. A four-second clip that starts on a settled frame wastes half a second on nothing; cutting into motion immediately makes generated footage feel twice as expensive.
Sound, Assembly, and the Finishing Pass
Silent generated footage is not finished footage. The audio pass is where most AI video stops looking like AI video.
Sound design. Layer three tracks: ambience (room tone, wind, city hum), foley (footsteps, cloth, clicks), and music. Ambience alone covers 80% of the uncanny feeling that silence creates.
Dialogue. If characters speak, record or synthesize the voice separately, then animate mouth movement or frame the shot so the mouth is obscured. Trying to force a model to lip-sync reliably is still the fastest way to burn a day.
Upscaling and stabilization. Run a dedicated upscaler, then a light stabilization pass. Heavy stabilization warps faces, so keep it subtle and apply it before color grading, not after.
Color and grain. A single film-emulation LUT and matched grain across every shot does more for visual coherence than any model upgrade. Grade all shots in one timeline so the palette stays unified.
Frame rate. Mixing 24fps and 30fps clips produces judder. Convert everything to a single timeline frame rate before you start cutting.
A Repeatable Workflow From Brief to Delivery
Here is a sequence that holds up on real projects.
- Write the shot list first. Ten to twenty shots, each one sentence. This is your script, your budget, and your progress tracker.
- Build reference boards. Gather stills for character, wardrobe, environment, and palette. These become your prompts' visual anchors.
- Generate one hero frame per shot. Still image only. Approve the composition before spending compute on motion.
- Animate them at short duration. Four to six seconds each, image-to-video, one camera move per clip.
- Select ruthlessly. Keep the best take, delete the rest immediately, and note why each reject failed.
- Assemble a rough cut with temp music. Judge rhythm before you judge image quality.
- Regenerate only the shots that fail the rough cut. A shot can look great in isolation and destroy the scene's pacing.
- Finish: upscale, stabilize, grade, grain, sound. Apply in that order.
- Export masters at the highest resolution you own, then create platform-specific crops from the master rather than re-generating for each ratio.
Two notes on this workflow. Step three is the one people skip, and skipping it is the most common cause of wasted effort. Step five is the one people resist, because deleting work feels wasteful — but an uncurated folder of 200 clips is not a film.
Common Mistakes and How to Fix Them
Morphing faces. Usually caused by over-specifying the action or asking for a large head turn. Fix: shorter clips, gentler motion, stronger character references.
Drifting backgrounds. Caused by camera moves the model cannot track. Fix: lock the background with a scene block, use first/last-frame control, or reduce the move to a push-in.
Rubbery motion. Often a duration problem — the model is stretching two seconds of movement across six. Fix: shorten the clip or generate more motion for the model to interpolate.
Inconsistent color across shots. Fix: one LUT for the entire sequence, not per-shot grading.
Ignoring sound until the end. Fix: cut a temp audio bed as soon as you have a rough sequence. It changes which shots you keep.
Chasing a single perfect prompt. Fix: accept that iteration is the method. Twenty cheap attempts beat three expensive ones.
Planning Compute and Time Realistically
Generative video is an iterative medium, and your schedule should reflect that. A useful planning heuristic: assume three to five generations per approved shot, and budget your time in editing hours rather than generation hours.
Also plan the handoff points. Generation, sound, and grading are different skills, and on small teams they are often different people. A clear folder structure — one directory per shot, containing the prompt, references, takes, and the approved clip — saves more time than any model upgrade.
Finally, keep a prompt journal. Every project, write down which prompts worked, which negative terms you needed, and which model handled which shot type. After three projects you will have a personal playbook that is more accurate than any published tutorial.
FAQ
Do I still need a storyboard if the model generates everything?
Yes, more than ever. The model gives you infinite options, and a storyboard is what tells you which options are wrong.
How long should a generated clip be?
Four to six seconds for most shots. Longer clips cost more and tend to degrade in the final second, and cutting into motion hides the seams.
Why does my character look different in every shot?
You are probably relying on text descriptions alone. Add three to five consistent reference images and reuse the same reference set across the whole sequence.
Is text-to-video better than image-to-video?
Image-to-video is more controllable almost every time. Use text-to-video for exploration and mood, and image-to-video for anything that has to match a look.
Can I mix models in one project?
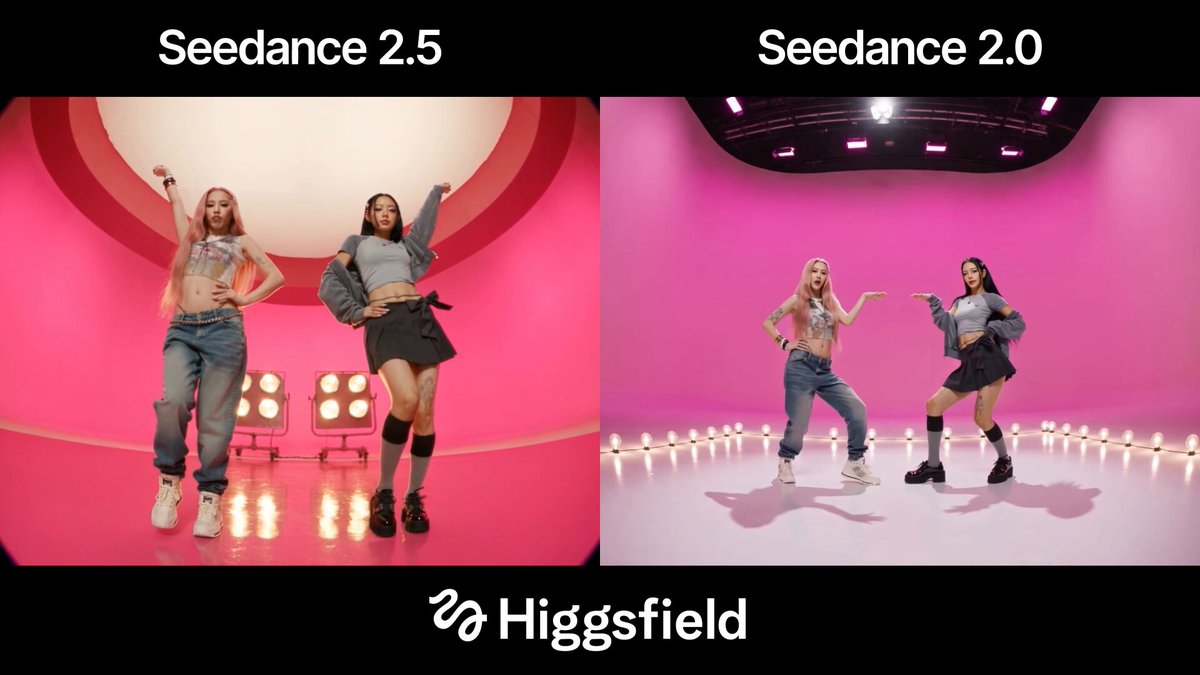
Yes, and you usually should. Generate establishing shots on whichever model handles scale well, and character shots on whichever handles faces. Match them in the grade.
How do I stop footage from looking like AI?
Three things, in order of impact: add ambience sound, apply consistent grain and grade, and cut faster. Most "AI looking" footage is just slow, silent, and slightly too clean.
What about lip-sync?
Treat it as a separate discipline. Record the audio first, then either animate to it or compose the shot so the mouth is off-axis or obscured.
Do I need a GPU?
Only if you want local generation, custom fine-tuning, or private footage handling. Otherwise hosted tools are faster to start and cheaper at low volume.
Where to Go Next
Pick one shot type — a medium close-up with a slow push-in — and generate twenty variations. Curate, delete, and note what changed each time. That single exercise teaches more about AI video synthesis than any overview, because synthesis is not a tool you configure once. It is a loop of write, generate, judge, and refine, and the people who get good results are simply the ones who have run that loop the most times with the most discipline.
