
Why a Structured Workflow Beats Prompt Roulette
Most people meet generative video the same way: they type a sentence into a box, wait, and hope. Sometimes the result is stunning. Usually it is close but wrong in ways that are hard to name — a face that drifts, a camera that lurches, hands that melt, a background that changes between two shots that were supposed to happen in the same room.
The fix is not a better single prompt. It is a workflow. Video generation tools have matured enough that the limiting factor is rarely raw model quality anymore. The limiting factor is whether the person driving them has a repeatable process for planning shots, choosing the right model for each one, holding visual continuity, capturing usable audio, and assembling everything into something that reads as a finished piece.
This guide lays out that process end to end. It is written for independent creators, small studios, and marketers who need consistent output rather than lucky one-offs. You will find decision criteria instead of hype, concrete examples instead of vague advice, and a troubleshooting section that covers the failures you will actually hit.
Choosing the Right Model for Each Shot Type
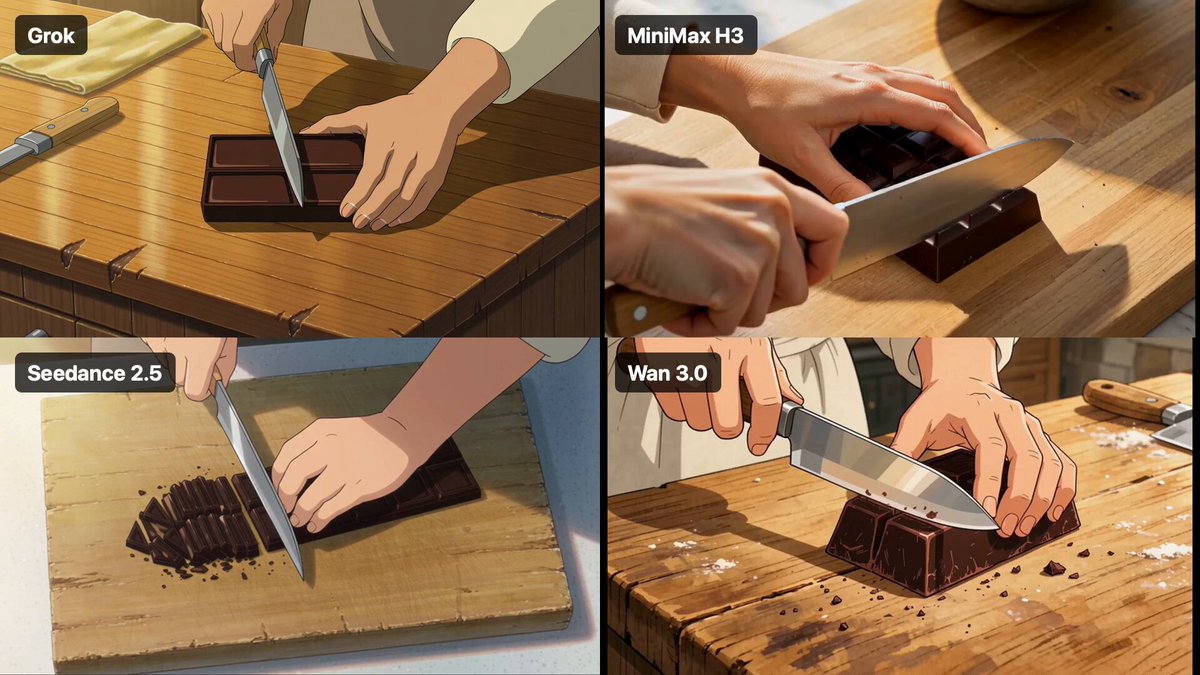
There is no single best video model. There are models that excel at different jobs, and a strong pipeline routes each shot to the tool that fits it.
Realism-led text-to-video
Some models are built to produce photoreal footage from a text description alone: natural light, believable skin, cinematic depth of field. These are your choice for establishing shots, product hero shots, crowd scenes, and any moment where the viewer should forget they are watching generated footage. They tend to be slower and less controllable, so treat their output as raw material to be trimmed rather than a precise instrument.
Image-to-video animators
When the exact composition matters — a specific logo placement, a specific face, a specific framing — generate or select a still first, then animate it. Image-to-video tools preserve composition much more faithfully than text-to-video because they already have the frame. This is the workhorse of most professional pipelines: storyboard frame in, motion out.
Fast iteration models
Certain tools trade fidelity for speed. Their real value is not the final render; it is exploring. Run ten variations of a movement, a camera angle, or a lighting setup in the time a premium model takes to produce two. Once you know what you want, regenerate the winner on a higher-fidelity model.
Open-weight and fine-tunable models
The open ecosystem — including families like Hunyuan, Wan, and Stable Video Diffusion derivatives — matters when you need control that hosted tools do not offer: custom styles trained on your own footage, unusual aspect ratios, local processing, or integration into an existing render farm. The trade-off is setup cost and maintenance. It is worth it if you produce at volume or need a proprietary look.
A simple routing rule
Ask one question per shot: does the viewer need to believe this is real, or do they need to see something specific? Realism pushes you toward premium text-to-video. Specificity pushes you toward image-to-video. Uncertainty pushes you toward a fast model first. Everything else is a variation on those three.
Pre-Production: Turning an Idea Into a Shot List
Generative tools reward planning more than any other medium, because every shot is an independent generation. If you improvise, you will spend your budget on shots you never use.
Start with a written beat sheet: five to twelve beats that describe what changes in the story. Not camera angles yet — just narrative movement. Then convert each beat into shots. A useful shot entry contains five fields:
- Duration — target length in seconds. Most models handle five to ten seconds comfortably; anything longer should be assembled.
- Subject action — one clear verb. "She turns toward the window," not "she reflects on her life."
- Camera — static, push in, pull out, orbit, handheld, crane. One movement per shot.
- Lighting and palette — golden hour, overcast, neon night, high-key studio.
- Continuity anchors — wardrobe, props, location details that must persist across shots.
Keep a storyboard frame for every shot, even a rough one. A frame you can see is worth more than a paragraph you can only imagine, and it doubles as the first-frame input for image-to-video generation.
Budget your attempts, not your seconds
In practice, most usable shots take three to five generations. Plan for that from the start. If a shot is critical and unpredictable, simplify it — reduce camera movement, reduce the number of people, reduce the number of simultaneous actions — so it converges faster. Difficulty compounds: two characters plus a camera move plus dialogue is roughly ten times harder than any one of those alone.
Keeping Characters and Style Consistent
Continuity is the single biggest weakness of AI video, and the single biggest reason amateur output looks amateur. A face that shifts subtly between shots breaks the illusion faster than a slightly soft render.
Establish a character sheet
Before generating anything, lock down a reference: one clean front-facing image, one three-quarter view, and one from behind. Add detail notes for hair, eye color, age range, signature clothing, and any distinctive props. When you write prompts, reuse the same descriptive phrasing every single time. Varying your wording changes the output.
Use reference-guided generation
Many image-to-video and image-generation tools accept a reference image alongside a prompt. Feed the character sheet into every shot that features that character. Combined with identical descriptive text, this dramatically reduces drift. When a tool supports multi-image conditioning, supply both the character reference and the scene reference so both stay stable.
Anchor the world, not just the person
Locations drift too. Build a location sheet with the same discipline: one wide reference of the space, plus a note on key visual features — the window on the left, the red chair, the tiled floor. Use those references for every shot in that location.
Style consistency across a project
Decide your palette and grain up front and describe it in every prompt. If you want a warm filmic look, say so consistently rather than occasionally. Alternatively, generate everything and apply a single color grade in post — that is often faster and more reliable than trying to enforce a look at generation time. A unified grade hides a surprising amount of shot-to-shot inconsistency.
Camera Language and Motion Prompts
AI models do not read cinematography theory. They respond to movement described plainly and specifically.
Useful motion vocabulary that translates well:
- Static / locked-off — safest, most stable, best for dialogue and inserts.
- Slow push in — adds tension; keep the speed descriptor modest.
- Dolly out — reveals; works best when the subject is centered.
- Orbit / arc — good for product and character reveals, but risky with busy backgrounds.
- Handheld — adds energy; small amounts go far.
- Crane up / drone rise — strong for establishing shots.
Avoid stacking movements. "Slow push in while orbiting and tilting up" usually produces mush. One movement per generation, then cut.
Prompt structure that holds up
A reliable order is: subject, action, environment, lighting, camera, style. For example: "A woman in a grey wool coat walks toward a rain-streaked window, interior café, overcast afternoon light, slow push in, muted filmic color, subtle grain." Everything after the comma is a constraint; keep constraints to what genuinely matters. Long prompts with contradictory instructions — "minimalist" plus "intricate detail" plus "clean background" — produce inconsistent frames.
Resolution, aspect ratio, and frame rate
Decide your delivery format before you generate. Vertical social edits, widescreen narrative, and square product spots have different framing logic. Generating widescreen and cropping to vertical later loses composition. If you need multiple formats, generate the primary format and plan a second pass for the others.
Sound: Voice, Music, and Effects
Video without considered audio feels like a demo. Audio is where most AI-driven projects are weakest, and it is also the easiest place to gain an advantage.
Dialogue and voice
If you need spoken lines, generate them separately with a voice tool rather than trying to get lip-synced dialogue out of a video model. Write short lines — eight to fourteen words per breath — and generate multiple takes with different pacing. For lip sync, match the audio to a shot where the face is large enough to read clearly; wide shots hide sync errors, but close-ups amplify them.
Consistency matters as much as quality. Keep one voice per character across the entire piece, and save the voice settings you used so you can regenerate matching lines later.
Music
Choose music before you finish the edit. Tempo dictates cut rhythm, and trying to fit music to a locked edit wastes time. Generate or license a track, then mark its beats and place your cuts on or near them.
Sound design
The three layers that make generated footage feel real are room tone, movement sound, and impact. Room tone — a low ambience bed — glues mismatched shots together. Footsteps, cloth movement, and object handling sell physical presence. Impacts, whooshes, and low-end hits punctuate transitions. Even a minimal pass with these three layers will noticeably raise perceived production value.
Assembly: Turning Clips Into a Coherent Film
A folder of impressive clips is not a video. Assembly is where you decide what the piece actually is.
Cut for rhythm
Sequence your strongest shots early, then build momentum. Generated footage often has a slightly unnatural cadence, and cutting faster than feels comfortable usually fixes it. If a shot is beautiful but does not advance the piece, cut it.
Use cutaways and inserts
AI generation struggles with complex continuous action. Cutaways — hands, objects, environment details — are cheap, easy to generate, and hide transitions. A three-shot sequence of a face, a hand, and a wide shot reads as a complete scene even if no single shot shows the full action.
Stabilize, then color
Apply stabilization where needed, then a single color grade across the whole timeline. A unified look does more for coherence than any individual shot. Add subtle grain or texture to unify footage from different models — mixing outputs from several tools is one of the fastest ways to make a project look inconsistent.
Titles, captions, and graphic layers
Typography is the fastest way to make generated footage look intentional. A clean title card, consistent lower thirds, and restrained on-screen text signal craft. Keep motion graphics simple and consistent in weight, color, and animation timing.
Quality Control and Common Failure Modes
Watch every clip at full size before it enters the timeline. The following problems cover most of what you will encounter.
- Face drift — the subject's features shift mid-shot. Fix with reference images and shorter shots; if it persists, split the shot.
- Morphing limbs and hands — usually caused by too much action in one generation. Reduce movement, reframe, or crop.
- Warping backgrounds — often from aggressive camera moves. Switch to a static or slow push.
- Flicker and texture boil — frequent in lower-fidelity models. Reduce motion, increase resolution, or add a subtle grade and grain pass.
- Unrequested text — models love inventing signage. Specify "no text, no lettering" or crop the area.
- Object permanence errors — a prop disappears or changes between shots. Keep props simple and repeat them in every prompt.
- Sync drift — audio and mouth movement diverge over a long take. Break dialogue into shorter clips.
A practical review checklist
Before approving a clip, check five things: does the face hold, do the hands read, does the camera move as intended, is the lighting consistent with neighboring shots, and is there any distracting artifact in the background? If two or more fail, regenerate rather than trying to fix in post.
Building a Repeatable Pipeline
Once you have made a handful of videos, systematize what worked.
Create templates. A shot list template, a prompt template with fixed field order, a project folder structure. Templates remove decisions that should be automatic.
Name everything predictably. Scene, shot, take, and version — for example s02_sh04_t03_v02. When you have two hundred clips, this is the difference between a smooth edit and an afternoon of scrolling.
Keep a prompt library. Every prompt that produced a keeper goes in the library, tagged by shot type: dialogue, product, establishing, action, insert. Over time this becomes your most valuable asset — more valuable than any individual model.
Standardize your export settings. Same resolution, codec, and frame rate across every generation. Mixed exports cause stutter and sync issues during editing.
Log what failed. A short note on why a shot was abandoned prevents you from repeating the same mistake next month.
Batch similar work. Generate all dialogue shots in one session, all establishing shots in another. Context switching is expensive; consistency improves when related shots are produced close together.
Finally, treat model choice as a moving target. New tools appear constantly and capability shifts fast, so build your pipeline around your process — planning, references, cutting, grading — rather than around any one generator. Processes survive tool changes. Tool-specific tricks rarely do.
Frequently Asked Questions
How long should an AI-generated shot be?
Aim for three to eight seconds. Beyond that, artifacts accumulate and continuity becomes fragile. If a scene needs twenty seconds, build it from three cuts rather than one long generation.
Do I need to train a custom model to get a consistent look?
Usually not. Reference images, reused prompt phrasing, and a unified color grade solve most consistency problems. Custom training becomes worthwhile when you need a signature style at high volume or need to match existing brand footage closely.
Which is better, text-to-video or image-to-video?
For control, image-to-video wins nearly every time, because you resolve composition before spending generation time on motion. Use text-to-video for exploration, atmosphere, and shots where you genuinely do not care about exact framing.
How do I handle dialogue scenes?
Generate the audio first, then build the visual around it. Keep individual lines short, favor medium or close framing for lip sync, and cut away to reaction shots and inserts frequently. This is how conventional film handles the same problem, and it works just as well with generated footage.
Why does my footage look artificial even when the image quality is high?
The problem is usually one of three things: motion that is too smooth and continuous, missing sound design layers, or an absent color grade. Add camera imperfection, room tone, and a unified look — the perceived realism jumps immediately.
How many generations should I expect per usable shot?
Three to five is typical once your prompts are dialed in. For complex shots with multiple characters or elaborate camera moves, plan for more, or simplify the shot until it converges.
Can I mix outputs from different tools in one project?
Yes, but only with deliberate unifying steps: consistent resolution, one color grade, matched grain, and a single audio mix. Without those, mixed sources look exactly like what they are. With them, audiences rarely notice — and you gain the freedom to route each shot to whichever model handles it best.
What is the most common beginner mistake?
Starting to generate before the shot list exists. Planning feels slow, but it removes the single largest source of wasted effort: producing beautiful clips that do not fit together into a story.
