
Why AI Video Generation Became Part of the Normal Toolkit
A few years ago, generating usable footage from a text prompt was a party trick. Clips lasted three seconds, faces melted during camera moves, and anything resembling a coherent scene required more luck than craft. That gap has closed fast. Modern generative video models can hold a character's likeness across multiple shots, follow a described camera move, match a color palette, and produce footage that survives a 4K export without obvious tells.
The result is a shift in how video gets made. Generative tools are no longer a novelty reserved for experimental shorts. They are used for product explainers, social ad variants, previsualization on larger productions, documentary B-roll, music videos, and internal training material. Marketing teams that once booked a two-day shoot for a single 30-second spot now generate twelve versions in an afternoon and reserve the camera crew for the hero spot.
But access to powerful models is not the same as the ability to produce a good video. The bottleneck moved. It used to be generation quality. Now it is workflow design: how you move an idea from a rough concept to a locked edit without losing narrative coherence, visual consistency, or your own sanity.
This guide walks through that workflow end to end. It covers how to plan shots, choose the right model for each task, write prompts that behave like direction, keep characters and locations stable, handle sound, and catch artifacts before an audience does.
The End-to-End AI Video Workflow, Stage by Stage
Most creators fail not because a model underperforms, but because they treat generation as the whole job. Generation is one stage out of seven. Skipping the others is what produces the familiar result: a folder of beautiful clips that refuse to become a film.
Stage 1: Concept and Script
Start with a written script, even a rough one. A script forces you to commit to a point of view, a runtime, and a beat structure. For a 45-second product video, that might be five beats: problem, agitation, product introduction, proof, call to action. Each beat becomes one to three shots.
Write for the medium. Generative models handle simple, visually legible actions far better than complex choreography. "A woman opens a laptop on a kitchen counter at sunrise" is directable. "A woman realizes her life has changed" is not.
Stage 2: Shot List and Storyboard
Convert the script into a numbered shot list with four columns: shot number, description, duration, and technical note. The technical note is where you decide whether the shot is text-to-video, image-to-video, or a still that you will animate later.
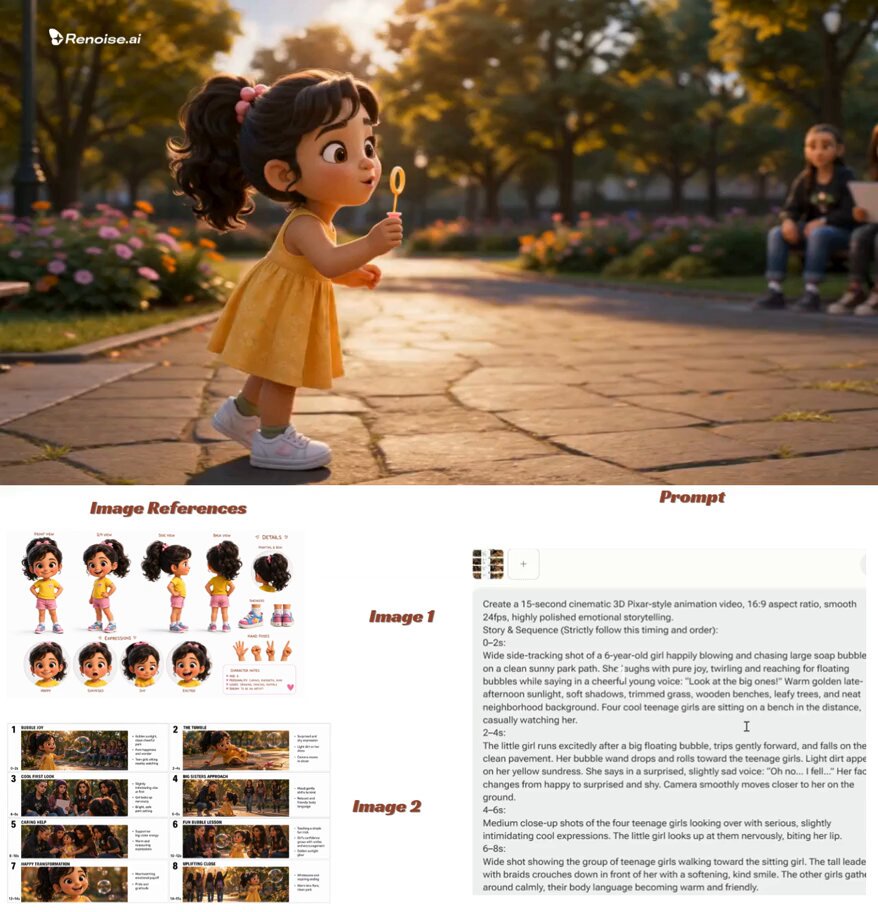
Storyboards do not need to be drawings. A grid of reference images pulled from a mood board, each labeled with the intended camera angle, gives you a shot plan you can actually follow. This also becomes your continuity checklist later.
Stage 3: Asset Preparation
Gather character references, location references, logo files, and brand colors in one folder before generating anything. Image-to-video models generally produce far more consistent results than pure text prompts, because the first frame carries the composition, lighting, and subject identity.
Stage 4: Generation
Generate in batches, not one at a time. For each shot, produce four to eight variations with slight prompt differences. Label files immediately using a convention like s03_v2_take4.mp4. Unlabeled output becomes unusable within a day.
Stage 5: Selection and Assembly
Pull the best takes into your editor and cut a rough assembly with no music or effects. Watch it twice. If the story does not hold with placeholder sound, no amount of polish will save it.
Stage 6: Sound, Voice, and Music
Add voiceover, ambient beds, effects, and music after picture lock. Sound design is where AI-generated footage stops feeling artificial, because real ambience masks the small motion inconsistencies that give generated video away.
Stage 7: Finishing and Delivery
Color correction, grain, subtle sharpening, and export presets tuned to each platform. A clip that looks great in a desktop timeline can fall apart after aggressive platform compression, so always export and check on a phone.
Choosing the Right Model for Each Shot
There is no single best video model. There are models that are excellent at specific jobs, and the practical skill is matching the job to the tool.
Text-to-Video Versus Image-to-Video
Text-to-video is best for exploration: mood pieces, abstract transitions, establishing shots, and anything where you are still discovering what the scene looks like. Image-to-video is best for control: character shots, product shots, and any frame where composition matters. If you already know exactly what the first frame should look like, generate a still first and animate it.
Motion, Physics, and Camera Language
Some models excel at subtle human motion and facial expression. Others are stronger at vehicles, water, smoke, and physical simulations. Others still are built around camera moves, honoring descriptions like slow dolly in, handheld follow, or crane up.
Test each model with the same three-shot benchmark: a person talking, an object in motion, and a camera move through space. Keep notes. A model comparison chart built from your own footage is worth more than any published leaderboard.
Resolution, Duration, and Cost per Second
Longer clips are not automatically better. Most shots in a finished edit run two to four seconds. Generating ten-second clips and cutting them down wastes time and money. Set your target duration per shot during the storyboard stage and generate to that length.
Cost per second varies enormously between models, so build a simple estimate before a big project. Multiply shots by takes by average clip length, and you have a rough total.
Local Versus Hosted Options
Open-weight models that run on your own hardware give you unlimited iteration and full privacy, at the cost of setup time and a serious GPU. Hosted platforms give you speed and the newest models, at the cost of per-generation spend and less control over the pipeline. Many studios run a hybrid: hosted models for exploration, local models for iteration on shots that need fifty takes.
Prompt Craft: Writing Instructions a Model Can Actually Follow
A prompt is not a wish. It is a shot description written for a very literal collaborator. The most reliable prompts follow a consistent internal order.
A Repeatable Prompt Structure
Subject and action first. Then setting, then lighting, then camera, then style, then technical constraints.
Example: A ceramicist shapes a bowl on a spinning wheel, hands wet with clay, in a sunlit studio with dust in the air, warm morning light from a large window, medium close-up, slow push in, shallow depth of field, documentary realism, 24fps, natural color.
Every element maps to a decision. Change one element at a time when iterating, or you will never know what caused the improvement.
Negative Descriptions and What to Avoid
If a model keeps adding an unwanted element, describe the scene more completely rather than piling on prohibitions. Models respond better to positive specification than to negation. Instead of "no crowd," write "an empty street at dawn."
The Iteration Loop
Work in cycles of three: generate four takes, identify the single biggest flaw, adjust one prompt element, generate four more. Creators who rewrite the entire prompt each time rarely converge, because they cannot tell which change helped.
Directing With Agents: Where Automation Actually Helps
Agent-style assistants that plan shot sequences, suggest camera coverage, and maintain continuity notes can genuinely improve output, but only if you understand what they are doing.
Use an assistant for the parts of the job that are structural rather than creative: breaking a script into a shot list, suggesting coverage for a scene, flagging continuity problems between shots, and generating prompt variations from a base description. Keep the creative decisions yourself: what the scene means, which take is honest, where the cut lands.
The failure mode is handing over the entire project and accepting whatever comes back. That produces generic work, because the assistant optimizes for plausibility, not for intention. Treat it as a first assistant director, not as the director.
A useful practice is to ask for three alternative approaches to the same scene, then choose one and develop it. This keeps you in the decision seat while still benefiting from the speed of machine planning.
Quality Control: Catching Artifacts Before Your Audience Does
The artifacts that matter are the ones that break the illusion of continuity. Watch for these categories.
Face and hand instability. Fingers multiply, jewelry shifts, ears change shape between frames. Fix by shortening the shot, reframing to a wider angle, or animating from a locked still.
Object persistence errors. A cup disappears, a chair changes color, a logo warps. Fix by reducing motion in the shot or by compositing a real asset over the generated plate.
Motion stalls. The subject moves, then freezes while the background continues. Fix by trimming before the stall and covering the cut with a reaction shot or an insert.
Texture shimmer. Repeated patterns like brick, fabric weave, or hair flicker. Fix with slight grain, a mild blur on the affected area, or by regenerating at a different resolution and downscaling.
Build a checklist and run every shot through it at full size, then at thumbnail size. Small screens hide artifacts but also reveal composition problems that a full-size monitor masks.
Sound, Voice, and Music Without a Studio
Sound is the most underrated part of the AI video workflow, and the fastest way to raise perceived quality.
Start with voice. Synthetic narration is now good enough for explainers and internal content, but realism comes from performance direction, not voice quality. Vary pace, add small pauses, and avoid flat delivery. If the video depends on emotional connection, cast a human for the voice and use AI for the rest.
Next, ambience. Every real location has a room tone. A generated interior with no room tone sounds like a vacuum and feels immediately fake. Add a low-level atmospheric bed under every scene, even quiet ones.
Then effects. Footsteps, cloth movement, keyboard clicks, and door closes anchor motion to sound. Because generated motion is approximate, a well-placed foley effect tells the audience what just happened, and their brain fills the rest.
Finally, music. Choose a track with a tempo that matches your cut rhythm. If your average shot length is 2.5 seconds, a track at 96 BPM gives you roughly one cut per two beats, which feels natural without conscious effort.
Editing and Finishing: Where Output Becomes a Film
The edit is where generated clips stop being clips. A few principles carry most of the weight.
Cut on motion. Begin a cut while the subject is still moving. Cutting on a static frame draws attention to the cut itself.
Vary shot length. Uniform shot lengths read as a slideshow. Alternate longer establishing shots with quick inserts.
Match color across shots. Generated shots rarely share a color profile. Apply a unified grade, or a simple LUT, so the whole piece feels like one camera shot it.
Add texture. A light film grain layer hides small inconsistencies and unifies different models' output. Keep it subtle; heavy grain reads as a filter.
Sound bridge everything. Carry audio across picture cuts to smooth transitions that would otherwise feel abrupt.
Budget, Time, and Team Decisions
The economics of generative video are different from traditional production, and planning accordingly matters more than any individual tool choice.
For a solo creator, the trade is time for money. Generating many takes is cheap in spend but expensive in attention, so batch your work: write all prompts first, generate all shots in one session, then select in one session. Context switching is the real cost.
For small teams, define roles clearly. One person owns the script and shot list. Another owns prompts and generation. Another owns editing and sound. When one person tries to do all three in parallel, continuity collapses.
For agencies, standardize a pipeline and a naming convention early. The ability to hand a project to a colleague mid-production is worth more than any single model's quality advantage. Document which model was used for each shot, because regenerating a shot six months later with a different model will not match.
Also budget for revision. Clients rarely approve the first cut, and regenerating a shot is not free even when it is fast. Assume two rounds of notes on any client deliverable.
Common Mistakes and How to Avoid Them
The same errors show up across almost every project.
Generating before planning. If you cannot describe the finished video in three sentences, you are not ready to generate.
Chasing perfection on individual shots. A shot that is 85 percent right, cut well, beats a perfect shot that does not fit the rhythm.
Too many models in one project. Mixing five models produces five visual languages. Pick two or three and stay consistent.
Ignoring dialogue and text. Models still struggle with legible on-screen text and lip-synced speech. Plan around this by using real overlays in the edit and recording voice separately.
No backup plan for characters. If your lead character must stay identical, generate a locked reference image set first and animate from those stills. Text-only character consistency is still fragile.
Skipping the phone check. Always watch the final export on a phone before delivery. Half your audience will see it there first.
FAQ
How long should an AI-generated video be? For social, 15 to 45 seconds. For explainers, 60 to 120 seconds. Longer pieces are possible but require stronger script discipline, because generative footage has less narrative elasticity than filmed material.
Do I need to disclose that a video is AI-generated? Disclosure requirements vary by platform and jurisdiction. A short on-screen note or a description line is a low-cost habit that builds trust regardless of local rules.
Can I keep a character consistent across many shots? Yes, with a reference-first approach: create a set of approved still images of the character, then animate each shot from one of those stills. Pure text prompts drift over long sequences.
What resolution should I generate at? Generate at the highest resolution your budget allows, then deliver at platform target. Downscaling hides artifacts; upscaling exposes them.
How many takes should I generate per shot? Four to eight for exploration, two to three once your prompt structure is dialed in. If you need twenty takes for every shot, the problem is the prompt, not the model.
Is a local setup worth it? Only if you generate heavily and value privacy or unlimited iteration. For occasional projects, hosted models are faster and cheaper overall.
What is the single highest-leverage improvement? Sound design. Adding proper room tone, foley, and a well-tempoed music bed changes perceived quality more than switching models.
The tools will keep changing, and new models will keep arriving with better motion, longer durations, and tighter control. What stays constant is the workflow: plan, prepare, generate in batches, select ruthlessly, cut for rhythm, and finish with sound. Get that sequence right and any model becomes usable. Skip it and even the best model produces a folder of clips that never becomes a video.
