
Most teams that struggle with AI video do not fail because the models are weak. They fail because they treat generation as one step instead of a pipeline. A prompt goes in, a clip comes out, the clip is roughly right, and then someone spends three hours regenerating variations of the same shot instead of moving forward.
The better approach is to think like an editor with a toolbox. Different models solve different problems: one is good at expressive motion, another holds a face steady across eight seconds, another turns a single illustration into a believable loop. The skill is not memorizing model names. It is knowing which stage of the pipeline you are in and what that stage actually needs.
This guide lays out a neutral, tool-agnostic workflow for going from text or a still image to finished animation, along with the decision criteria, prompt patterns, and failure modes that matter most in practice.
Why a large model library can slow you down
Choice feels like freedom until you are three hours into comparison testing. When a platform offers dozens or hundreds of generative engines, the temptation is to sample them all on the same prompt and pick a winner. That process rarely produces good video, because the models were never meant to be compared on identical inputs.
Video generation models carry aesthetic biases. Some lean cinematic and desaturated. Some push stylized, high-contrast anime framing. Some are tuned for product shots with clean backgrounds, and others for handheld, documentary-style motion. Running the same prompt across all of them tells you which model likes your prompt, not which model is best.
A more useful mental model is routing. Think of every shot in your sequence as a job ticket with requirements attached: duration, motion type, subject count, reference material, target aspect ratio, and deadline. Then match the ticket to the engine most likely to satisfy it. The library stops being a menu and becomes an assignment board.
Two practical habits make routing work:
- Keep a personal benchmark reel. Three or four short prompts that cover your common needs — a talking head, a product rotation, a landscape pan, a stylized character action. Run new engines against those first.
- Log results in a spreadsheet, not in your head. Columns for engine, prompt, duration, motion quality, artifacts, and render time. After twenty entries you will have opinions you can actually defend.
Text-to-video, image-to-video, and everything in between
These are not competing techniques. They are different entry points into the same pipeline, and most polished sequences use both.
Text-to-video: fast exploration, weaker control
Text-to-video is best for mood, pacing studies, and establishing shots where the exact composition does not matter. It is fast, requires no asset preparation, and is excellent for storyboarding a sequence before you commit to precise frames.
Its weakness is control. If you need a specific character in a specific costume doing a specific action in a specific room, text prompts alone will fight you. You will get close, then spend dozens of attempts chasing the last ten percent.
Image-to-video: animating a still you already approved
Image-to-video flips the problem. You generate or illustrate a keyframe first, approve it, and then let a model add motion. Because the composition is locked, you get far more predictable results — and you can fix a bad frame in an image editor rather than re-rolling a whole clip.
This is the single most reliable technique in AI video production, and it is the reason so many professional workflows start with stills.
Hybrid pipelines: keyframe first, motion second
The strongest pattern combines both. Use text-to-video to explore and lock a visual direction. Then generate hero keyframes for each shot, animate them with an image-to-video engine, and only drop back to text-to-video for transitions and inserts where precision is not critical.
A simple rule of thumb: the more specific your shot, the more of the pipeline should run through images.
How to pick a model per shot: six decision criteria
Before you open a tool, write the shot's requirements down. Then evaluate engines against these six axes.
1. Motion complexity
Is the camera moving, or the subject, or both? Simple subject motion — a head turn, a blink, fabric moving — is handled well by almost everything. Complex choreography, running, fighting, or multi-limb interaction still separates engines sharply. Test the hardest motion in your sequence first; if an engine survives that, it will handle the easy shots.
2. Temporal consistency
Watch for flicker, texture crawl, and identity drift. Pause the clip at the one-second mark and the last frame. If the face, hair, or clothing has shifted meaningfully, the engine is not reliable for continuity-dependent shots.
3. Style fidelity
Every engine has a look. Some render skin with a soft, filmic falloff, others with crisp digital edges. Choose the engine whose default aesthetic is closest to your target, because it is much easier to nudge a model toward your look than to drag it there from the opposite direction.
4. Reference and control support
Does the engine accept a reference image, a style image, a depth pass, a pose skeleton, or a motion clip? Control inputs are what turn a lucky generator into a predictable production tool.
5. Iteration speed
Time-to-first-preview matters more than final render quality during development. An engine that produces a rough draft in a fraction of the time lets you test three compositions before lunch. Do the slow, high-quality pass only on shots you have already approved.
6. Duration and resolution limits
Know the native clip length. Many engines generate short segments that must be stitched, and stitching introduces its own continuity problems. If a shot needs to be continuous for a long time, plan the seam before you shoot.
A repeatable AI video workflow, step by step
This is the sequence that holds up across projects, from a fifteen-second social clip to a multi-minute explainer.
Step 1 — Lock the script and build a shot list
Do not start generating before the script is final. Every change later invalidates shots you have already produced. Convert the script into a shot list with columns for shot number, duration, description, camera movement, and required reference assets.
The shot list is your routing document. It also prevents the most expensive mistake in AI video: producing beautiful clips that do not cut together.
Step 2 — Generate and approve keyframes first
For each shot, generate a still image and get it approved before any motion is added. This is where art direction happens. Check composition, lighting direction, eyeline, and consistency with neighbouring shots.
Editing stills is cheap. Re-rolling video is not.
Step 3 — Run motion tests at low resolution
Animate each approved keyframe with short, low-resolution test passes. Evaluate motion quality, not detail. You are answering one question: does the movement read as intended?
Keep test passes short — two to three seconds is usually enough to judge whether a motion idea works.
Step 4 — Commit to final passes
Once motion is approved, re-run at full resolution and length. Change one variable at a time. If you alter both the prompt and the motion strength simultaneously, you will not know which change helped.
Step 5 — Assemble, sound, and review
Cut the clips together before you polish individual shots. Pacing problems are invisible in isolation. Then add sound design — room tone, foley, music — because audio does more for the perception of realism than another round of upscaling.
Finally, watch the whole sequence once with the sound off, and once with your eyes closed. Both passes catch different problems.
Keeping characters and sets consistent
Consistency is the hardest problem in AI video, and it is a system problem, not a prompt problem.
A few techniques that reliably help:
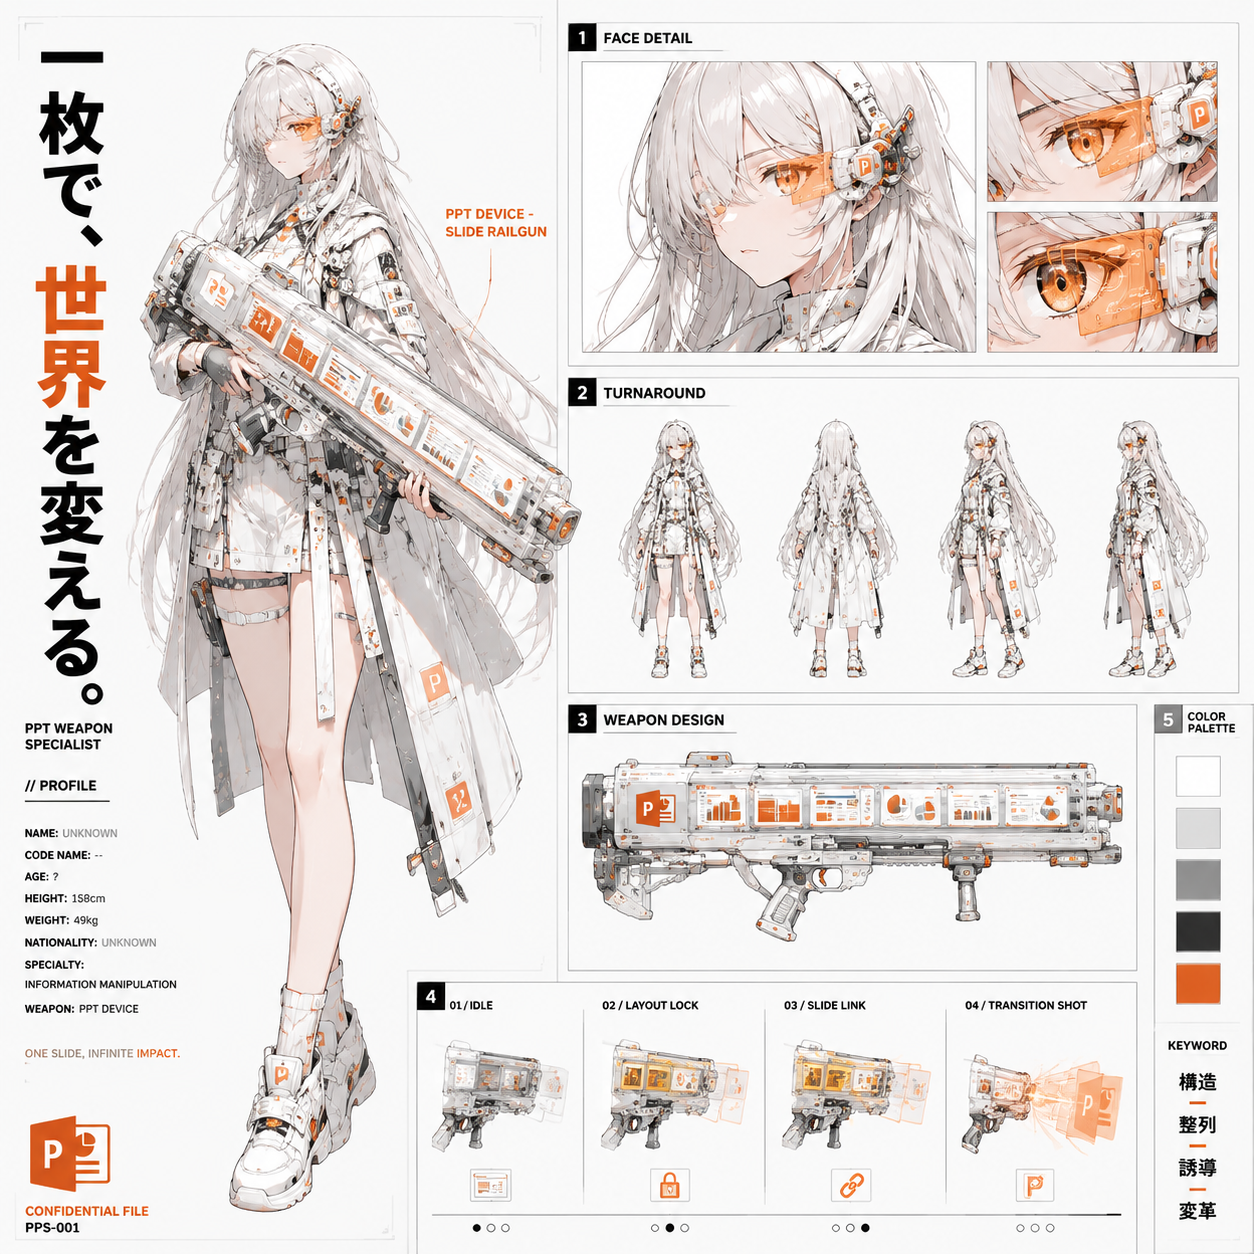
- Build a character sheet. Front, three-quarter, and profile views, plus a close-up. Use these as reference inputs rather than describing the character in text every time.
- Reuse successful keyframes as style anchors. If a frame nailed the lighting and palette, feed it into the next shot's generation.
- Stabilize wardrobe and palette. Limit the character to two or three colours. Fewer variables means fewer drift opportunities.
- Generate sets separately. Create background plates, then animate characters against them rather than describing both in one prompt.
- Accept controlled imperfection. Audiences forgive minor variation between cuts far more than a single shot that flickers internally.
Prompt patterns that travel between models
Prompts are not portable in their details, but their structure is. Write descriptions in this order and most engines will interpret them sensibly:
- Subject — who or what, with two or three defining attributes.
- Action — the single motion that must read clearly.
- Environment — location, time of day, weather.
- Camera — framing, lens feel, movement.
- Lighting — direction, quality, colour temperature.
- Style — film stock, illustration style, render aesthetic.
- Negative constraints — what must not appear.
Keep motion instructions singular. "She turns her head and stands up and the camera pulls back" is three shots pretending to be one. Split it, and each clip will be stronger.
Budgeting time and compute without guesswork
Generative video has a cost curve, whether you are paying in money, in queue time, or in machine hours. Plan for it explicitly.
- Spend the most on approved shots only. Roughly 70% of your budget should go to final passes on shots that already look right in test form.
- Batch your tests. Queue low-resolution variants together and review them in one sitting rather than one at a time.
- Cap retries per shot. Decide in advance that a shot gets three attempts before you change the approach instead of the prompt.
- Track time, not just money. The real constraint is usually your own attention. Long queues during peak hours can cost more than a higher per-generation price.
Mistakes that quietly ruin AI video projects
- Describing a whole scene in one prompt. Results look busy and unfocused.
- Skipping the keyframe step. You lose composition control and pay for it in retries.
- Judging clips individually. A shot that looks flat alone may be perfect in context.
- Ignoring the cut. Match eyelines, motion direction, and screen position across adjacent shots.
- Chasing photorealism when stylization would be faster. Stylized looks are more forgiving of small artifacts.
- Not archiving prompts. When a client asks for a variation weeks later, your notes are the only way back.
- Forgetting audio. Silence makes even strong footage feel unfinished.
Quick reference: matching the shot to the tool
| Shot type | Recommended approach |
|---|---|
| Establishing landscape | Text-to-video, wide framing, slow camera move |
| Character close-up | Keyframe image first, then image-to-video |
| Product rotation | Image-to-video with controlled reference |
| Stylized action | Engine with strongest motion handling, short clips |
| Dialogue cutaways | Keyframe plus subtle motion only |
| Transitions and inserts | Text-to-video for speed, or simple editing moves |
| Looping backgrounds | Short image-to-video loop, then duplicate in the timeline |
FAQ
Do I need to use many different models?
No. Two or three well-understood engines cover most work. Breadth helps only once you know what you are routing.
How long should each clip be?
Shorter than you think. Three to five seconds gives you editing flexibility and reduces the chance of drift appearing mid-shot.
Why does my character change between shots?
Usually because each shot was generated from a text description rather than a shared reference image. Build a character sheet and reuse it.
Is image-to-video always better than text-to-video?
For controlled shots, yes. For exploration and mood, text-to-video is faster and often more surprising.
What resolution should I generate at?
Test low, finish high. Only pay for full resolution once the motion is approved.
How do I stop flicker?
Shorten the clip, simplify the motion, and reduce the number of moving elements. Flicker usually comes from the model trying to do too much at once.
What to do next
Pick one short sequence — fifteen seconds, three or four shots — and run it through the full pipeline: script, shot list, keyframes, motion tests, final passes, assembly, sound. Do not skip stages because the project is small. The point is to build muscle memory for the order of operations.
Once that sequence works, add complexity one variable at a time: a second character, a camera move, a longer duration. The teams that produce reliable AI video are not the ones with access to the most engines. They are the ones with a repeatable process and a clear idea of which stage they are in.
