
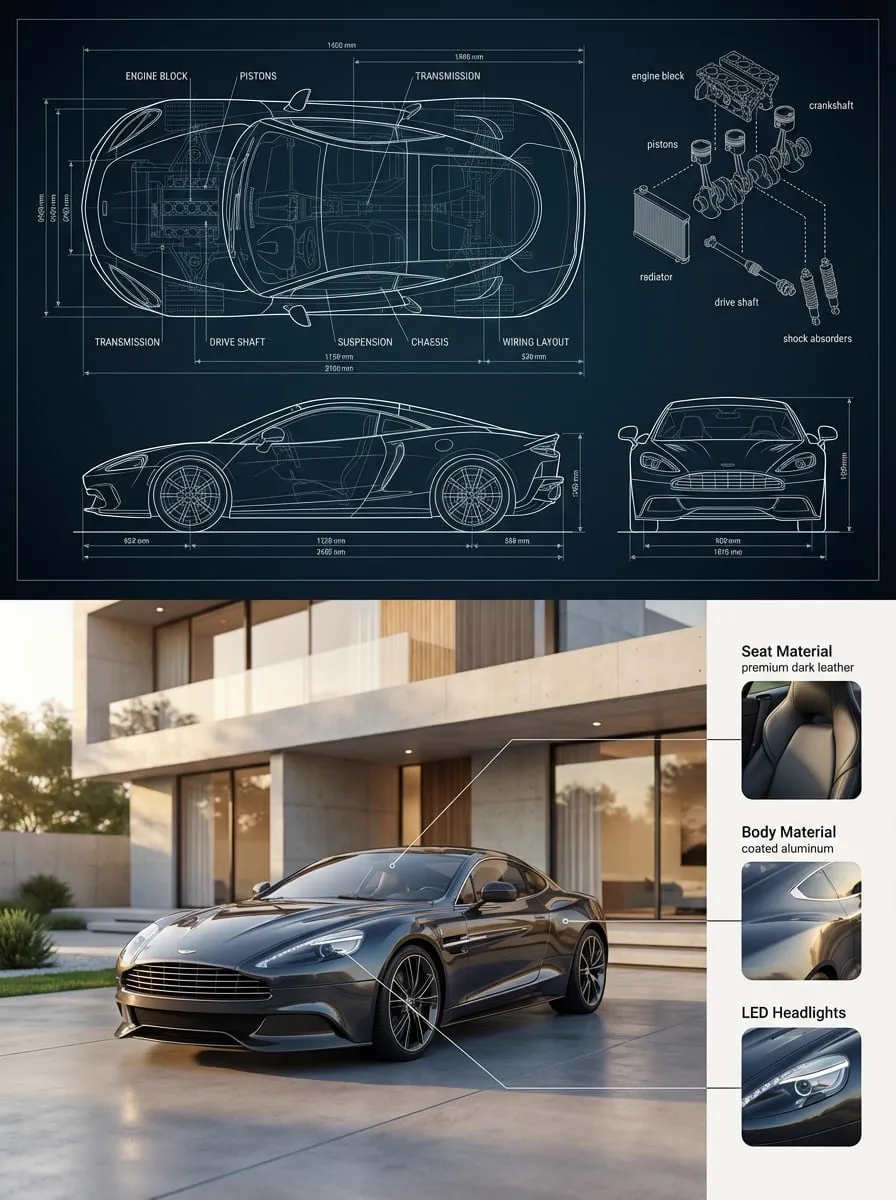
Live production used to be a fortress of specialist gear and manual labor: a switcher operator, a graphics team, a lighting crew, a hardware encoder, and a control room full of people watching a wall of monitors. Virtual production added another layer — LED volumes, camera tracking, and real-time engines. Today, AI is quietly dissolving the boundary between generated footage, live camera feeds, and interactive virtual environments. The result is a new kind of production pipeline where a small team can design a virtual set in the morning, drive it with a tracked camera in the afternoon, and stream it with live captions and translated audio by evening.
This guide walks through how to actually build that pipeline: what each layer does, where AI genuinely helps, where it still fails, and how to design a workflow that survives a live show without breaking.
Why AI Is Reshaping Live and Virtual Production
Three technical shifts explain most of the change.
First, generation became cheap. Producing a convincing background plate, a stylized animated insert, or a synthetic establishing shot now takes minutes rather than a shoot day. That changes what is possible in pre-production and in live filler content.
Second, control became programmable. Earlier generative tools returned a single output you either accepted or rejected. Modern tools accept structured input: reference images, timing instructions, camera parameters, and scene constraints. When a system exposes parameters, it can be scripted, and when it can be scripted, it can be integrated into a live control path.
Third, compositing became real-time. Keying, matting, relighting, and upscaling that once required a render farm now run at interactive rates on a single workstation GPU. That is what makes AI-assisted virtual sets practical rather than aspirational.
What AI does not fix is the fundamentals. Bad lighting on the talent still looks bad. Weak scripting still produces a weak show. No amount of generation rescues a production with no plan, no cue sheet, and no fallback path. The teams getting the most out of these tools are the ones who treat AI as an accelerant for a well-designed process, not a replacement for one.
The Four Layers of an AI Production Pipeline
Almost every modern AI-assisted production can be described as four layers stacked on top of each other. Naming them explicitly makes it much easier to debug problems, because failures usually live in one layer, not everywhere.
Layer 1: Generation
This is where raw imagery, motion, and audio come from. That includes text-to-video, image-to-video, motion transfer, background extension, upscaling, voice synthesis, and music or ambience generation. The key design question here is not "which model is best" but "which model is best for this specific shot type." A model that excels at cinematic landscapes may produce mush on human faces, and the reverse is also true. Maintain a short list of three to five specialized tools rather than chasing a single universal one.
Layer 2: Control and continuity
The control layer is what separates a demo from a production. It handles reference images, character anchors, style definitions, seed management, shot numbering, and version tracking. If your control layer lives in a spreadsheet and a folder of files named final_v3_actual_final, you will lose a week to re-rendering the wrong take.
Layer 3: Real-time compositing
This layer merges live camera feeds with generated or virtual elements. It includes camera tracking data, keying, depth estimation, relighting, and latency management. Anything in this layer must run faster than your show's tolerance for delay.
Layer 4: Delivery
Delivery covers encoding, captions, translation, chaptering, thumbnail generation, and distribution to each platform. This is the layer most teams under-plan, and it is the layer your audience notices most when it fails.
A minimum viable stack can run on one workstation and one cloud account. The important thing is that the layers are distinct, because when something goes wrong at minute twelve of a live show, you need to know instantly whether you are debugging a generation artifact, a tracking drift, or an encoder setting.
Pre-Production: Storyboards, Previs, and Shot Planning
AI's highest-leverage contribution is often before a single camera is switched on.
From script to shot list
Feed a script into a language model with a strict output format: scene number, shot number, framing, duration, talent, props, and whether the shot is live, generated, or hybrid. The structured output becomes your cue sheet and your asset checklist in one pass. Insist on a consistent schema — free-form summaries are nearly useless on set.
Previs renders
Once you have a shot list, generate quick previs frames for the shots that matter. Even rough previs changes conversations with clients and stakeholders dramatically, because people react to images far more precisely than to prose. Two hours of previs can eliminate a day of reshoots.
Build a reference bible
A reference bible is a single document containing approved looks: character references from multiple angles, palette swatches, lighting direction, lens character, and set references. Every generated asset should be traceable to an entry in that bible. When someone asks why a shot feels off, the bible usually answers the question in seconds.
Keeping Characters and Sets Consistent
Character consistency is the single most common failure point in AI-assisted production, and it is almost always a process problem rather than a model problem.
Reference sets, not single references
One portrait is not enough. Build a reference set: front, three-quarter, profile, two expressions, and a full-body shot. Multi-image conditioning across several references substantially improves identity retention when the character appears at different angles or in different lighting.
Wardrobe, prop, and lighting locks
Lock everything that is not supposed to change. If a character wears a green jacket in scene one, that jacket is a locked asset. Do not let the generator reinterpret it per shot. The same applies to hero props and to the direction of key light — a character lit from the left in one shot and from the right in the next reads as a continuity error even to viewers who cannot articulate why.
Run a consistency audit pass
Before you assemble, review all shots featuring the same character in a single grid at thumbnail size. Problems that are invisible when watching clips sequentially become obvious when you see ten frames side by side. Flag drift in face shape, hairline, skin tone, and wardrobe color, then re-render only the flagged shots.
Real-Time Compositing and Virtual Sets
This is the layer that makes a hybrid show feel live rather than assembled.
Camera tracking and calibration
Whether you use a physical tracked camera or a virtual one, calibration determines whether the composite holds. Track the lens, not just the camera body: focal length changes mid-shot will break a composite that assumed a fixed lens. If you are working with a physical camera on a jib or dolly, budget time for a tracking rehearsal before the show, not during it.
Latency budgets
Write down a latency budget and defend it. A reasonable target for interactive virtual sets is under three frames of added delay for tracking and compositing, with heavier generation steps pushed off the live path entirely. Anything that requires more than about 200 milliseconds of computation should probably be pre-rendered or triggered during a transition rather than during a host's sentence.
Matching light and grain
Synthetic elements betray themselves through light direction and texture. Sample the key light direction from the live plate and apply it to generated elements. Then apply a light film grain or sensor noise pass across the whole composite so the generated areas match the camera's texture. This one step does more for perceived realism than most resolution upgrades.
Audio, Captions, and Multilingual Delivery
Audio is where audiences forgive the least.
Live captions and translation
Speech recognition plus translation gives you live captions in multiple languages. The practical requirements are low latency, punctuation restoration, and a glossary of proper nouns. Build that glossary before the show: product names, guest names, and technical terms. Without it, the caption layer will confidently mistranslate your key message.
Voice consistency and dubbing
For recorded segments, voice synthesis can produce consistent narration across dozens of clips, and dubbing can open a show to new markets with a fraction of the usual cost. Always keep the original audio track and disclose synthetic dubbing where regulations or platform policies require it.
Accessibility as a design constraint
Captions, audio description, and high-contrast graphics are not finishing touches. Deciding early that every generated lower third must pass a contrast check costs almost nothing; retrofitting accessibility into a finished show costs a great deal.
Hardware, Latency, and Budget Trade-Offs
Cloud versus local
Local workstations win on latency, predictability, and per-hour cost for long sessions. Cloud wins on burst capacity and for models too large to run locally. A common hybrid: local for anything in the live path, cloud for batch generation before and after the show.
Resolution and frame rate decisions
Decide once whether you are delivering 1080p60, 4K30, or something else, and let that decision constrain every layer upstream. Upscaling generated assets is fine for backgrounds; upscaling faces and text rarely looks good. Match your generation resolution to the final delivery resolution for anything with a human face or on-screen type.
When to keep a human in the loop
Automate the repetitive and the measurable. Keep humans on judgment calls: pacing, tone, and anything involving a person's reputation. A useful heuristic is that AI should propose and humans should approve for anything that goes out live under your brand.
Quality Control, Common Mistakes, and Safety
A pre-flight checklist
Before going live: verify all tracking calibration, confirm every cue has a manual fallback, check caption glossary loading, confirm encoder bitrate and backup ingest, test the audio path end to end, and confirm that generated assets have cleared your review step.
Mistakes that break AI live workflows
- Generating at the wrong aspect ratio. A beautiful 16:9 plate cannot be cropped to vertical without destroying composition. Generate per destination.
- No fallback for live generation. If a live effect depends on a model call, you need a pre-rendered backup ready to cut to.
- Skipping the consistency grid. Drift is invisible clip by clip and glaring side by side.
- Letting captions run unglossed. Proper nouns will be mangled.
- Over-trusting a single model. Tool diversity is resilience.
- Forgetting disclosure. Synthetic presenters and dubbed audio may require labeling.
Rights, consent, and disclosure
Confirm you have rights to every reference image you feed into a generator. Get explicit consent before cloning a person's likeness or voice, and keep that consent documented for as long as the asset exists. Where synthetic media is used in news, advertising, or political content, disclosure is typically mandatory — design the on-screen label into the graphics package rather than bolting it on later.
Example Workflow: A 30-Minute Hybrid Live Show
Here is how the layers fit together in practice.
Two weeks out. Write the script. Generate a structured shot list with a language model. Produce previs frames for the eight most complex shots. Assemble the reference bible: host references, two guest references, set references, and the graphics palette.
One week out. Generate background plates and virtual set extensions. Render all insert videos and motion graphics as files, not live calls. Build the caption glossary. Run a consistency grid over everything featuring the host and re-render flagged shots.
Two days out. Set up camera tracking and run a full calibration. Test the compositing chain with the real talent in the real lighting. Record a five-minute dress rehearsal and watch it back at delivery resolution on a normal screen.
Show day. Local workstation handles tracking, keying, and compositing. Captions run with the glossary loaded. Every generated element has a pre-rendered backup queued in the switcher. One operator owns the fallback panel and nothing else.
Post-show. Publish the live stream as VOD with chapter markers generated from the cue sheet. Produce two vertical cutdowns from the same assets. Translate captions into your top three markets and publish localized versions within 48 hours while interest is still high.
FAQ
Do I need a virtual production LED volume to do this?
No. LED volumes give in-camera compositing and correct eyeline for talent, which is valuable for narrative work. For streaming, a green screen plus real-time keying and lighting match gets you most of the benefit at a fraction of the cost.
How much of a live show can realistically be AI-generated?
Environments, inserts, graphics, captions, and dubbing scale well. Live spontaneous human performance should stay human. Hybrid is almost always stronger than fully synthetic.
What is the biggest technical risk?
Latency drift. A compositing chain that runs 80 milliseconds behind in rehearsal can run 300 milliseconds behind under a real show's load. Test under load, not in isolation.
How do I keep character identity stable across many shots?
Use multi-image reference sets, lock wardrobe and props as fixed assets, keep the lighting direction consistent, and run a thumbnail grid audit before assembly.
Is it worth generating vertical and widescreen versions separately?
Yes. Reframing a widescreen composition rarely works. Generate or shoot per aspect ratio, or plan frames with a safe center region deliberately composed for vertical.
What should a small team automate first?
Captions, chapter markers, thumbnails, and cutdown assembly. These are high-volume, low-judgment tasks where automation saves hours and risks little.
How do I decide between cloud and local rendering?
Anything in the live path stays local. Batch generation and upscaling can go to cloud capacity. Re-evaluate quarterly as your show length and resolution change.
What is the most overlooked step?
The consistency audit. It takes twenty minutes and prevents the kind of continuity errors that make an entire production feel amateur.
Where This Is Heading
The direction of travel is clear: production tools are becoming programmable, generated assets are becoming interchangeable with captured ones, and the live/recorded distinction is eroding. The teams that thrive will not be the ones with the largest model collections. They will be the ones with the cleanest pipelines — a reference bible that stays current, a latency budget that is respected, a fallback path for every cue, and a habit of auditing consistency before the audience ever sees the result. Start with one layer, get it boringly reliable, then add the next.
