
Why model choice matters more than prompt tricks
Most people who struggle with text-to-video assume their prompts are the problem. They rewrite, they add adjectives, they paste in camera jargon. Sometimes that helps. But the single biggest lever on output quality is which model you send the prompt to, and how you sequence that model inside a larger production workflow.
Modern video generation is not one technology. It is a family of related but distinct approaches: diffusion-based clip generators, image-to-video animators, motion-transfer systems, long-form narrative models, and specialised tools for faces, products, or stylised animation. Each excels at a narrow band of shots and struggles outside it. A model that produces a stunning slow push-in on a landscape may collapse the moment two characters need to speak. A model tuned for anime aesthetics will fight you if you want photoreal skin texture.
The practical consequence is simple: keep a shortlist of models rather than a single favourite, and match each shot in your script to the model most likely to nail it. That is the entire discipline. Everything else — prompting, reference images, edit assembly — is downstream of that decision.
This guide lays out a decision framework, a layered production workflow, prompt structures that survive across different models, consistency tactics, and a quality-control checklist you can run before anything reaches an audience.
The four jobs a video model can actually do
Before comparing brands or versions, categorise models by the job they perform. Almost every tool on the market falls into one of four buckets, and the buckets behave very differently.
Clip generators
These turn a text prompt into a few seconds of motion. They are the workhorses of short-form content, B-roll, establishing shots, and abstract transitions. Strengths: speed, stylistic range, dramatic camera movement. Weaknesses: short duration, weak narrative continuity, unreliable anatomy at high complexity.
Image-to-video animators
You supply a still frame and the model adds motion. Because you control the first frame, composition and character identity are locked before generation begins. This is the single most reliable path to visual consistency across a project, and it is why professional pipelines increasingly start with still images rather than text alone.
Character and subject models
Some systems are trained or fine-tuned to preserve a specific face, product, or illustration style across many clips. They trade flexibility for identity stability. If your video series stars the same presenter or mascot in every episode, this category matters more than raw resolution numbers.
Narrative and long-form systems
A newer class attempts multi-shot sequences with consistent characters, dialogue, and continuity. They are improving fast but remain the least predictable category. Use them for previsualisation and storyboards, then rebuild hero shots with clip or image-to-video models for final quality.
Mapping your script to these four buckets instantly tells you how many tools you need. Most projects need two or three.
A decision framework for matching shots to models
When you have dozens of options, comparison shopping by specification is hopeless. Compare by shot instead.
Style fidelity versus motion realism
Ask what the audience will notice more. A stylised animated short can tolerate slightly mushy motion if the look is exactly right. A product demo cannot: the object must be geometrically believable even if the lighting is plain. Rank your shot list by which of these two matters more, then bias model selection accordingly.
Duration and shot complexity
A five-second single-action beat is easy. A twelve-second beat with a character walking, then turning, then interacting with an object is not. Many failures attributed to bad prompting are actually duration mismatches. Break complex action into two or three shorter generations and cut them together. You will get better results in less time than fighting a single long generation.
Character and subject consistency
Count how many shots share the same subject. One shot: use whatever looks best. Ten shots: prioritise a model or workflow that accepts reference images or trained identities, even if it is slower or stylistically narrower.
Cost, latency, and iteration budget
Every generation has a cost in money or compute time, and iteration is where quality comes from. Estimate how many attempts each shot will need — usually three to eight for hero shots, one or two for background filler — then pick models that let you iterate without anxiety. A slightly weaker model you can afford to run ten times beats a premium model you can only afford to run twice.
Text rendering and overlays
If your video includes legible on-screen text, signage, or labels, treat it as a separate problem. Generate clean plates and add typography in the edit rather than asking a video model to spell words correctly.
A layered production workflow that scales
The most reliable text-to-video projects follow the same broad sequence, regardless of which specific tools are involved.
Step 1: Write a shot list, not a script
Scripts describe dialogue and emotion. Shot lists describe what the camera sees, for how long, and with what motion. Write one line per shot: subject, action, camera behaviour, duration, and mood. Twenty to forty lines is typical for a two-minute piece. This document becomes your production plan and your prompt source.
Step 2: Lock the visual language
Choose a palette, a lens character, and a lighting direction before generating anything. Create two or three reference stills that define the look. Every subsequent generation — image or video — should be checked against those references. Skipping this step is the most common reason projects feel like a compilation of unrelated clips.
Step 3: Generate keyframes as stills
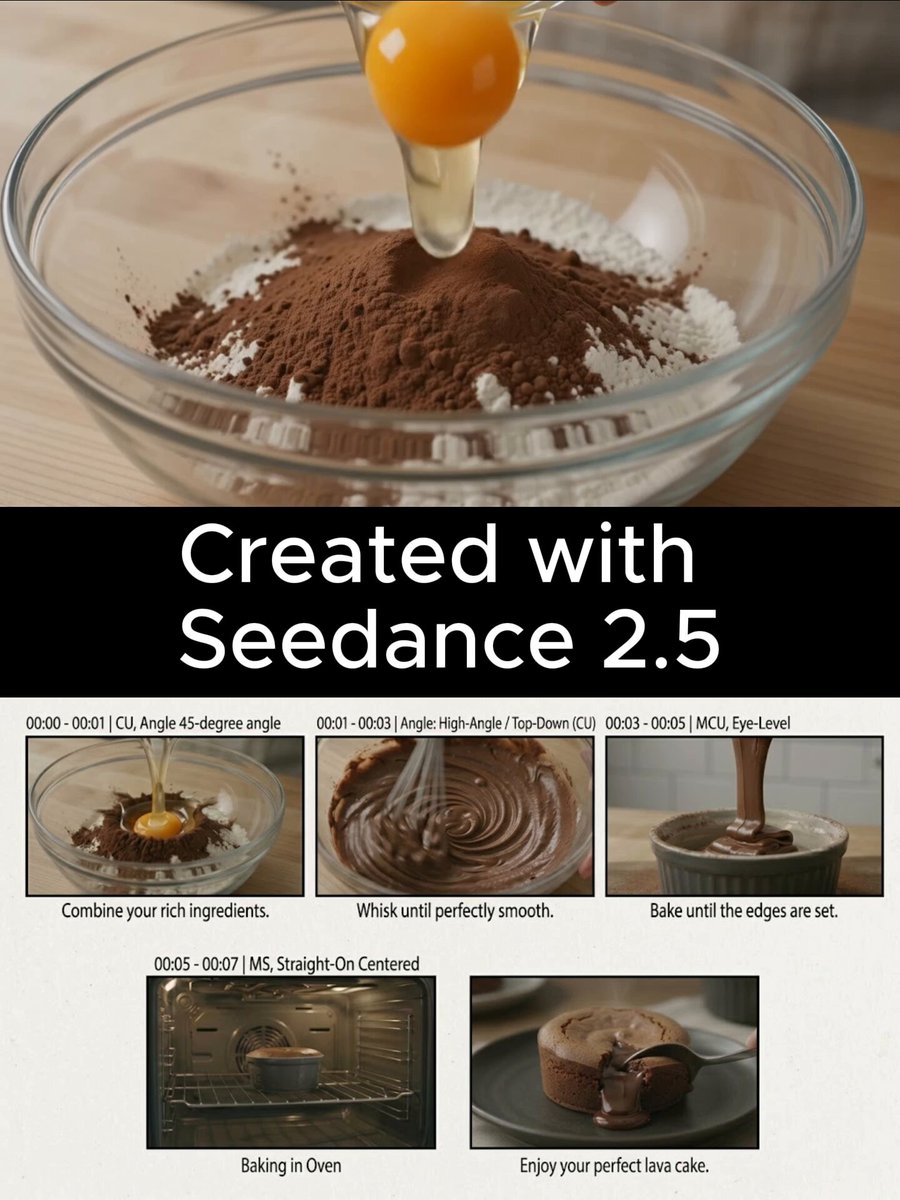
Produce a still image for the first frame of each shot. Iterate on the still until composition and style are right, because editing a still is fast and cheap compared with re-rolling video. This produces a storyboard that doubles as your video inputs.
Step 4: Animate from the keyframes
Send each approved still to an image-to-video model with a motion-focused prompt. Because the composition is already locked, the prompt only has to describe movement: camera path, subject action, environmental motion, pacing.
Step 5: Generate longer or riskier shots separately
For shots that need sustained action, use a clip generator and accept that you will discard several attempts. Keep the best take, and keep the rejected takes for a week in case the edit changes.
Step 6: Assemble, sound, and grade
Cut in an editor, add sound design and music, then apply a light grade across all clips to unify them. Colour grading is the cheapest consistency tool available. A shared curve and grain pass can make clips from different models feel like one shoot.
Step 7: Review at delivery size
Watch on a phone, a laptop, and a large screen. Artefacts invisible on a monitor often scream on a phone, and vice versa.
Prompt structures that survive across different models
Each model has quirks, but a well-organised prompt transfers surprisingly well. Use a consistent six-part order.
Subject, action, camera, lighting, style, constraints
A template looks like this: [subject and appearance] + [single primary action] + [camera behaviour] + [lighting] + [visual style and references] + [constraints such as aspect ratio, duration, what to avoid]. Keeping the order stable makes it easy to debug: if motion is wrong, change only the action clause.
One action per generation
Models handle one clear verb far better than three chained verbs. "She turns and smiles and picks up the cup" asks for a sequence. "She picks up the cup" asks for a moment. Write moments.
Concrete camera language
Useful phrases include slow push-in, static wide, handheld follow, slow orbit, crane down, and rack focus. Vague terms such as "cinematic" or "dynamic" carry little weight on their own; pair them with an explicit movement.
Lighting as a separate clause
Lighting is where amateur-looking output is won or lost. Naming the direction and quality — soft window light from frame left, hard rim light, overcast diffusion, practical neon — produces far more consistent results than naming a mood.
Negative prompts and guardrails
Most systems accept exclusions. Useful entries: warped hands, extra limbs, text, watermark, flicker, jitter, jump cuts, morphing faces. Add them once at the project level rather than rewriting them per shot.
Keep a prompt log
Record the prompt, model, seed, and a one-line verdict for every accepted shot. Within a week you will have a personal playbook far more valuable than any generic list of tips.
Handling character and style consistency across shots
Consistency is a production problem, not a prompting problem. Several tactics stack well.
Use reference images. Supply the same character sheet or product photo across every shot. Many models accept a reference alongside the prompt.
Change one variable at a time. If you alter lighting, framing, outfit, and location simultaneously, you cannot tell what caused the drift.
Keep wardrobe and props constant. Small identity markers — a jacket colour, a specific bag, a scar — anchor recognition even when faces drift slightly.
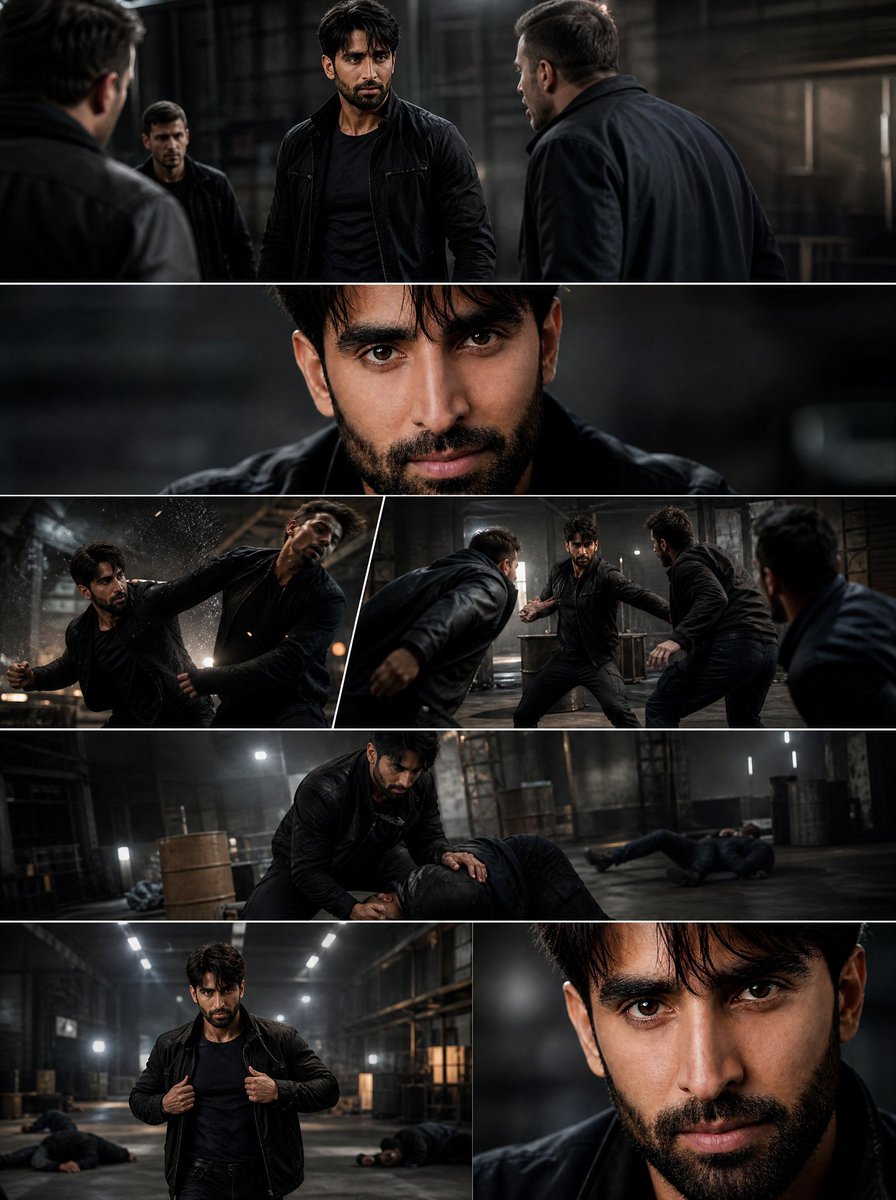
Shoot coverage intentionally. If a face is hard to keep stable, cut away to hands, over-shoulder angles, and environment inserts. Editors have solved this problem for a century.
Reserve your most consistent model for close-ups. Wide shots forgive identity drift; close-ups never do.
Train or fine-tune when the series is long. For recurring characters across many episodes, a small custom model or identity adapter pays for itself in saved re-rolls.
Quality control: a pre-publish checklist
Run every accepted clip through the same checks before it enters the timeline.
- Anatomy: hands, teeth, eyes, ears, and limbs at frame edges.
- Object permanence: does a prop change shape, colour, or count?
- Geometry: do straight lines stay straight as the camera moves?
- Flicker and texture crawl: common on flat surfaces and foliage.
- Motion continuity: does the clip start and end in a state you can cut from and to?
- Text: any accidental lettering or signage should be intentional and legible.
- Aspect ratio and frame rate: match your delivery spec exactly.
- Audio sync, if the model generates sound: verify against the visual beat.
Anything that fails two or more checks goes back to generation. Fixing in the edit rarely works for structural errors, and a single broken frame can undermine an otherwise strong sequence.
Common mistakes and how to avoid them
Chasing realism when stylisation would be faster. Stylised looks hide small imperfections. If the story does not demand photorealism, choose a stylised model and move faster.
Generating before designing. Producing clips without a locked palette or reference set guarantees rework.
Overloading prompts. Long prompts with competing instructions produce average results across all of them. Split the shot.
Ignoring sound. Audiences forgive visual imperfection far more readily than bad audio. Budget time for sound design.
Using one model for everything. Even a superb model has weak spots. Two or three tools used deliberately beat one tool used stubbornly.
Never deleting bad takes. Keep a rejected folder, but do not browse it. Decision fatigue is real and it slows projects more than any technical limitation.
Skipping the small-screen test. Most viewers watch on phones. Check there first.
Tool categories worth combining
Rather than a brand list, think in categories and assemble a stack that covers each.
- A fast clip generator for exploration and B-roll.
- A high-fidelity image-to-video animator for hero shots.
- An image model with strong prompt adherence for keyframes.
- An identity or character reference system for recurring subjects.
- An upscaler or detail enhancer for final delivery resolution.
- A traditional editor with good colour tools and audio mixing.
- A voice or music generator if you are producing narration without a studio.
A stack of five to seven tools covers the vast majority of short-form and commercial work. Add specialised tools only when a specific shot type keeps failing.
FAQ
How many models do I actually need to learn?
Two or three well-understood models beat ten half-learned ones. Add a new tool only when you can name the shot type it will fix.
Should I start from text or from an image?
Start from an image whenever consistency or composition matters. Text-only generation is best for abstract, atmospheric, or exploratory shots.
Why do my clips look great alone but wrong in sequence?
Almost always a missing visual language: inconsistent lighting direction, palette, or lens character. Fix it with a reference set and a unifying grade.
How long should a single generated clip be?
As short as the edit allows. Three to six seconds covers most beats; longer generations are less stable and harder to fix.
How do I handle dialogue?
Generate silent visuals and add dialogue in post, either as voice-over or lip-synced separately. Asking a video model to handle performance and speech simultaneously is still risky.
What about resolution and frame rate?
Match your delivery spec and upscale at the end. Generating at a higher resolution does not repair structural errors in motion.
Can I automate the pipeline?
Partly. Script parsing, keyframe generation, and batch submission can be scripted. Shot selection and grading still benefit from human judgement, and that is where the quality lives.
Building your own shortlist
A large model library is only useful if you convert it into a small, opinionated shortlist. Start by logging twenty shots you admire from your own projects, note which tool produced each, and mark whether the shot needed one attempt or eight. Patterns appear quickly: two models will account for most of your successes, one will handle your stylistic outliers, and the rest are noise.
From there, write a one-page internal standard: default model for establishing shots, default for character work, default for product, the reference set to use, the negative prompt to carry everywhere, and the checklist to run before a clip is accepted. Document it, share it, and update it as models change.
The technology will keep shifting. Models will get faster, longer, and more controllable, and the specific names on your shortlist will turn over. What stays constant is the method: plan shots before generating, lock your visual language early, match each shot to the model that handles it best, keep more attempts than you think you need, and never let a clip reach an audience without passing the checklist. Build that process once and every new model becomes an upgrade rather than a fresh learning curve.
