
What Cinematic Really Means in AI Video
Most people who try AI video generation for the first time produce something that technically moves but never feels like film. The difference rarely comes down to the model. It comes down to whether the person driving the model understands what makes footage read as cinematic in the first place.
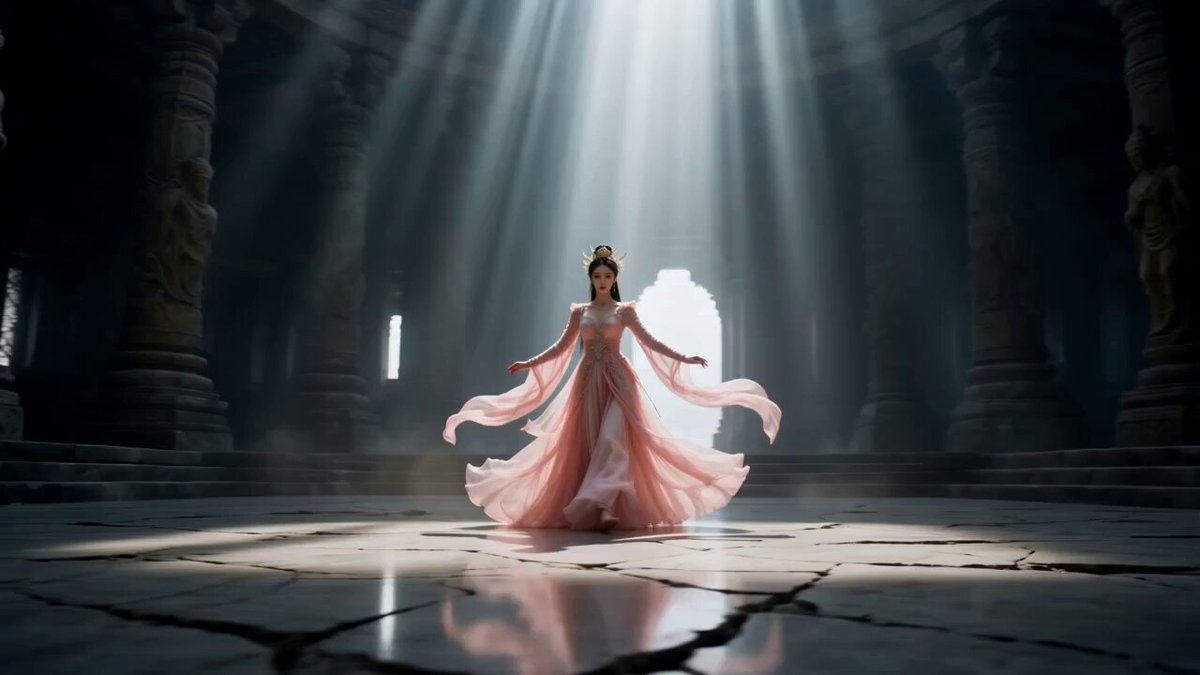
Cinematic footage is a set of deliberate constraints. A shallow depth of field isolates a subject from a busy background. A locked-off wide shot establishes geography before a cut pushes in. Color temperature shifts subtly between scenes to signal emotional change. Movement is motivated — the camera moves because the story needs it to move, not because the tool offers a camera move.
AI generation tools are excellent at producing attractive frames. They are considerably weaker at producing coherent sequences of attractive frames that feel like they belong together. That gap is where the craft lives, and it is where this guide focuses.
You will not find a list of settings to copy. Instead, you will find a workflow: how to plan a sequence, how to choose between different classes of models for different jobs, how to prompt for camera and lighting language, how to keep characters and environments consistent, and how to finish in an editor so the result holds up at full screen.
Model Selection: Matching the Tool to the Shot
The single biggest efficiency gain in AI video work is refusing to use one model for everything. Modern pipelines usually involve several specialized generators, and the skill is knowing which one to reach for.
Text-to-video versus image-to-video
Text-to-video is best for exploration. You describe a scene and let the model surprise you. It is fast, cheap in terms of iteration, and ideal for finding the visual language of a project in the first day or two.
Image-to-video is best for control. Once you have a frame you love — generated in an image model or photographed — you animate it. Because the first frame is locked, consistency improves dramatically and the output becomes predictable enough to plan a shot list around.
A practical rule: explore in text-to-video, then rebuild the winning look as a still and animate it with image-to-video for the final shots.
Specialized roles inside a pipeline
Beyond the two main categories, most serious workflows use at least four specialized functions:
- Style and still generation. Dedicated image models produce sharper, more art-directed frames than video models do on their first frame.
- Motion and camera control. Some models accept explicit camera parameters — pan, tilt, dolly, orbit — while others infer motion from the prompt. Use parameter-driven models for technical shots and prompt-driven models for organic movement.
- Upscaling and detail reconstruction. A dedicated upscaler or detail-enhancement pass will usually beat a single high-resolution generation attempt, both in quality and in time spent.
- Audio and lip synchronization. Dialogue, ambience, and synchronization are typically separate tasks that should be handled after the visual cut is locked.
A decision framework
| Shot need | Best tool class | Why |
|---|---|---|
| Establishing landscape | Wide-capable text-to-video or image-to-video | Detail density matters less than composition |
| Character close-up with dialogue | Image-to-video plus a lip-sync pass | Frame control plus facial stability |
| Complex action beat | Parameter-driven motion model | Explicit camera control avoids chaos |
| Product or object hero shot | Image-to-video from a clean still | Crisp edges and consistent geometry |
| Stylized montage | Style-tuned model or LoRA-style adaptation | Consistent aesthetic across many short clips |
The temptation is always to standardize on one model because it is familiar. Resist it. Ten minutes of routing logic saves hours of re-generation.
Building a Look Bible Before You Generate
A look bible is a one-page document, plus a folder of reference images, that defines the visual rules of your project. It exists so that every generation decision — from prompt wording to color grading — has something to be checked against.
Include the following:
- Aspect ratio and delivery format. Decide early. Vertical and widescreen compositions are not interchangeable, and models behave differently at each ratio.
- Palette. Two or three dominant colors plus one accent. Write them as hex values if you plan to grade later.
- Lens character. Wide (24mm) feels environmental and slightly distorted. Normal (50mm) feels neutral. Telephoto (85mm and up) compresses space and flatters faces.
- Lighting signature. Hard directional key with deep shadow reads as thriller. Soft wraparound with lifted blacks reads as prestige drama. Overcast diffusion reads as documentary.
- Texture and grain. Clean digital, subtle film grain, or a heavier analog look. State it explicitly, because models default to clean.
- Camera behavior. Locked off, handheld, gimbal-smooth, or whip-pan. Mixed camera personalities inside one scene is one of the most common reasons AI sequences feel amateur.
Keep the look bible short enough to reread before every generation session. A document nobody opens is not a look bible; it is a wish list.
Multi-image conditioning for asset consistency
Many modern pipelines let you supply several reference images at once: a character's face from three angles, a costume detail, a location plate. Conditioning on multiple references dramatically improves continuity across shots because the model has more than a single frame to anchor to.
Build a small reference library per project: one folder for characters, one for environments, one for props, one for style frames. Update it as the project evolves, and prune anything that no longer matches the direction.
The Step-by-Step Cinematic Workflow
Step 1 — Write a shot list with intent
Before any prompt, write the sequence in shot terms. Not "a woman walks through a market" but:
- Shot 1: Wide, market exterior, morning haze, slow dolly right.
- Shot 2: Medium, woman enters frame from left, camera holds.
- Shot 3: Close-up on hands selecting fruit, shallow focus.
- Shot 4: Over-the-shoulder, she glances back, slight handheld drift.
Each line carries a framing, a subject action, and a camera instruction. That is the minimum information a video model needs to produce something usable, and it is the minimum you need to judge whether the output is wrong.
Step 2 — Generate the reference frames first
Generate stills for each shot before animating anything. Stills are fast, cheap to iterate, and easy to compare side by side. Once you have eight or ten frames that look like they belong to the same film, your sequence is effectively designed.
Reject frames aggressively at this stage. A still that is merely acceptable will become a clip you resent.
Step 3 — Generate in passes, not in one attempt
A common beginner mistake is asking for a complex shot in a single pass: character, action, camera movement, lighting change, and background detail all at once. Models handle this poorly.
Instead, work in passes:
- Pass one: get the composition and subject right with minimal motion.
- Pass two: introduce the camera move.
- Pass three: add secondary motion — cloth, hair, background crowds, particles.
Each pass keeps the earlier result as input where possible, so quality compounds rather than resets.
Step 4 — Control motion with keyframes
Keyframe control lets you specify a start frame and an end frame and let the model interpolate. This is the most powerful technique available for complex shots, because it turns a vague motion prompt into a defined trajectory.
Practical uses: matching a cut so the actor's head lands in the same position across a transition, animating a reveal where an object must travel a specific path, or creating seamless loops for background plates.
Step 5 — Assemble and cut before you polish
Bring all clips into an editor early. Watch the sequence at speed with temp music. You will immediately spot pacing problems, redundant shots, and jarring continuity breaks that are invisible when clips are reviewed individually.
Cut ruthlessly. AI sequences almost always run 20 to 30 percent too long.
Step 6 — Grade, then treat
Color grading unifies clips generated by different models. A single look applied across the timeline does more for perceived production value than any individual generation upgrade. Follow grading with grain, halation, and a subtle vignette if the look calls for it.
Prompting for Cinematic Results
Prompts for cinematic footage are closer to a camera report than to a story description. Structure beats poetry.
Camera and lens vocabulary
Use specific terms: slow dolly in, static tripod shot, handheld follow, crane up, orbit around subject, rack focus from foreground to background. Include a focal length when it matters: 85mm portrait compression, 24mm wide angle. Mention the height: low angle, eye level, overhead.
Lighting vocabulary
Say what the light is doing: golden hour backlight with lens flare, single practical lamp, warm pool of light, overcast diffusion, no visible shadows, hard key from camera left, deep falloff. Also specify what happens to the backgrounds: crushed blacks, lifted shadows, blown highlights on windows.
Movement and pacing
Describe speed explicitly. Slow, deliberate and quick, energetic produce very different results. For action, name the beat structure: anticipation, strike, recoil. For quiet scenes, name what is still rather than what moves.
A reusable prompt template
[Shot type and focal length] of [subject] in [location], [lighting description], [color and palette notes], [camera movement and speed], [texture or film stock reference], [aspect ratio], [negative constraints]
Negative constraints matter. Listing what you do not want — no text overlays, no warped hands, no sudden zoom — reduces cleanup time considerably.
Solving Consistency Across Shots
Consistency is the hardest problem in AI video and the one that most determines whether a sequence feels professional.
Character consistency
Three techniques, in order of effort:
- Reference conditioning. Feed multiple angles of the same character into every shot. Cheapest and usually sufficient.
- Face restoration pass. Generate freely, then run a dedicated face or identity transfer step to unify the character across clips.
- Locked-first-frame method. Create a canonical portrait, then build every shot as image-to-video from a variation of that portrait. Most reliable, and the slowest.
Environment and prop continuity
Log what appears in each shot: which side of the room the window is on, what color the car is, which hand holds the cup. Keep this in a spreadsheet row per shot. When a detail flips between cuts, viewers feel something is wrong even if they cannot name it.
Fighting flicker and morphing
Flicker usually comes from a model being asked to hold too much detail at once. Reduce the amount of moving detail in the frame, shorten the clip to a few seconds, or generate a longer take in pieces and cut them together. Morphing — where facial features or object shapes drift — is best solved by shortening generation length and using image-to-video with a strong start frame.
A useful habit: generate each shot three times at slightly different seeds. Pick the cleanest, and keep the others as inserts so you can cut around any moment where detail breaks down.
Common Mistakes and How to Fix Them
| Mistake | Symptom | Fix |
|---|---|---|
| One model for every shot | Inconsistent look across cuts | Route each shot to the class of model that suits it |
| Prompts written as prose | Vague, unplanned motion | Use camera-report structure |
| Overloaded single-pass generations | Warping, garbled backgrounds | Split into composition, motion, and detail passes |
| No grading pass | Clips feel unrelated | Apply one unified look across the timeline |
| Too few generated takes | Settling for near-misses | Generate three variants per shot, keep the best |
| No sound design | Footage feels like a demo reel | Add ambience, foley, and music early |
| Sequences too long | Viewer attention drops | Cut 20 to 30 percent after the first assembly |
| Inconsistent camera personality | Scenes feel disjointed | Choose one camera behavior per scene in the look bible |
The pattern behind most of these is impatience: generating before planning, or polishing before cutting.
A 30-Second Trailer Walkthrough
Here is how the workflow looks end to end on a short piece.
Day one — direction. Write a twelve-shot list for a 30-second trailer. Define the look bible: widescreen, teal and amber palette, 35mm compression, mild grain, slow dolly movements only. Generate forty stills, select twelve.
Day two — generation. Convert each selected still into a clip, two to four seconds each, using image-to-video with conservative motion. Generate three takes per shot. Reject anything with visible morphing.
Day three — assembly. Cut to a temp track. The first assembly runs 46 seconds. Trim to 31 by removing two establishing shots and tightening four others. Note that three clips have a slightly different color cast.
Day four — finish. Apply a single grade across the timeline, then add grain and a subtle vignette. Add music, then ambience per scene, then three or four foley hits on cuts. Export.
Notice that actual generation occupied about a third of the schedule. The rest was planning and finishing, which is where the cinematic quality comes from.
Audio, Grading, and the Final 10 Percent
AI video is silent by default, and silence is the fastest way to make good visuals feel cheap.
Build sound in layers. A music bed establishes tone. Ambience — room tone, traffic, wind, crowd — makes generated spaces feel physically real. Foley on specific actions gives cuts impact. If there is dialogue, record or synthesize it in a separate pass and treat the lip-sync step as a distinct task rather than something the video model should handle.
On the visual side, three finishing moves do most of the work:
- Unified grade. Match black levels and white balance across every clip before anything else.
- Contrast shaping. Cinematic images generally have protected highlights and slightly crushed shadows. A simple curve applied to the whole timeline gets you most of the way.
- Grain and halation. Subtle texture hides minor inconsistencies between clips generated by different models.
Resist the urge to over-grade. The goal is not a heavy look; it is a consistent one.
FAQ and Final Checklist
How long should each AI-generated clip be?
Two to five seconds is the practical sweet spot for most current models. Longer clips tend to accumulate artifacts. Build longer sequences by cutting several short clips together.
Do I need image generation skills?
Not in a traditional sense, but you do need to be able to judge a frame — composition, light, focal length. That skill transfers directly from photography and illustration.
How many takes should I generate per shot?
Three is a good default. If all three are unusable, the prompt or the input frame is the problem, not luck.
What if my character changes between shots?
Switch to a locked-first-frame approach: create one canonical portrait and build every shot from variations of it. Then add an identity-unification pass in post.
Where should I start learning?
Start with a single ten-second scene: two shots, one character, one location. Complete it end to end — generate, cut, grade, sound — before attempting anything longer. The bottleneck is almost never generation quality; it is finishing discipline.
Final checklist before export
- Every clip passes the look bible on palette, lens, and grain.
- Character details match across every cut that includes them.
- No clip exceeds five seconds without a deliberate reason.
- The sequence has been cut at least twice, with at least 20 percent removed.
- A unified grade is applied to the full timeline.
- Ambience exists in every scene, and foley hits land on major cuts.
- The piece has been watched once at full size with sound, start to finish, without pausing.
That last item catches more problems than any technical check. A cinematic AI video is not a collection of impressive generations. It is a sequence that holds attention from the first frame to the last, and that only happens when planning, generation, and finishing are treated as three separate crafts.
