
Why cinematic short-form is the format AI handles best
Short cinematic video sits in a sweet spot that generative tools were practically built for. You need a limited number of shots, a tight runtime, and a strong visual idea — not a two-hour narrative with dozens of speaking roles. That means a solo creator with a laptop can now produce something that looks like it came out of a small commercial house.
The economics changed, but the craft did not. The bottleneck is no longer whether a tool can render a convincing 6-second clip. The bottleneck is whether you can make ten of those clips feel like they belong to the same film. That is a directing problem, not a rendering problem, and it is where most AI video projects fall apart.
This guide walks through a complete workflow: choosing the right model for each shot, locking character and style consistency, planning shots like a director, running efficient generate-review-refine loops, layering sound, and finishing the edit so it plays well on vertical feeds and widescreen players alike.
Choosing a generation model per shot, not per project
The biggest mistake new creators make is committing to one tool for an entire film. Different shots have different demands, and modern text-to-video, image-to-video, and video-to-video engines each excel at different things.
Text-to-video, image-to-video, and video-to-video
Text-to-video is best for establishing shots, abstract transitions, environments, and anything where the camera is the main character. It gives you the most surprise and the least control.
Image-to-video is the workhorse of narrative shorts. You generate or photograph a still that already has the composition, lighting, and character you want, then let the model add motion. Because the first frame is fixed, you get dramatically better consistency across a sequence.
Video-to-video (often called restyling or motion transfer) is useful for turning reference footage into a different look, extending a shot, or changing the pace of an existing clip. It is also the cleanest way to preserve a real actor's performance while shifting the visual style.
What to judge a model on
Ignore demo reels. Evaluate a model against your specific project with a short test:
- Motion plausibility — do hands, fabric, hair, and liquids behave? Watch a walking figure for five seconds.
- Prompt adherence — does it respect camera direction ("slow dolly in, 35mm, shallow depth of field") or ignore it?
- Identity retention — feed it the same character reference five times and compare faces.
- Temporal stability — does the background warp or flicker when nothing should be moving?
- Latency and cost per second — measured in your actual iteration loop, not in a spec sheet.
Speed versus fidelity
Some engines return a usable clip in under a minute; others take several minutes per attempt. A practical rule: use fast, cheap models for exploration and blocking, then switch to high-fidelity models for the final pass on shots that survive the edit. You will usually find that only 40–60% of your first-pass shots make it into the timeline, so paying premium rates on exploratory renders is wasted spend.
Shot consistency: the hardest problem in AI filmmaking
Consistency has three layers: the character, the world, and the camera. Solve them in that order.
Character references and multi-image fusion
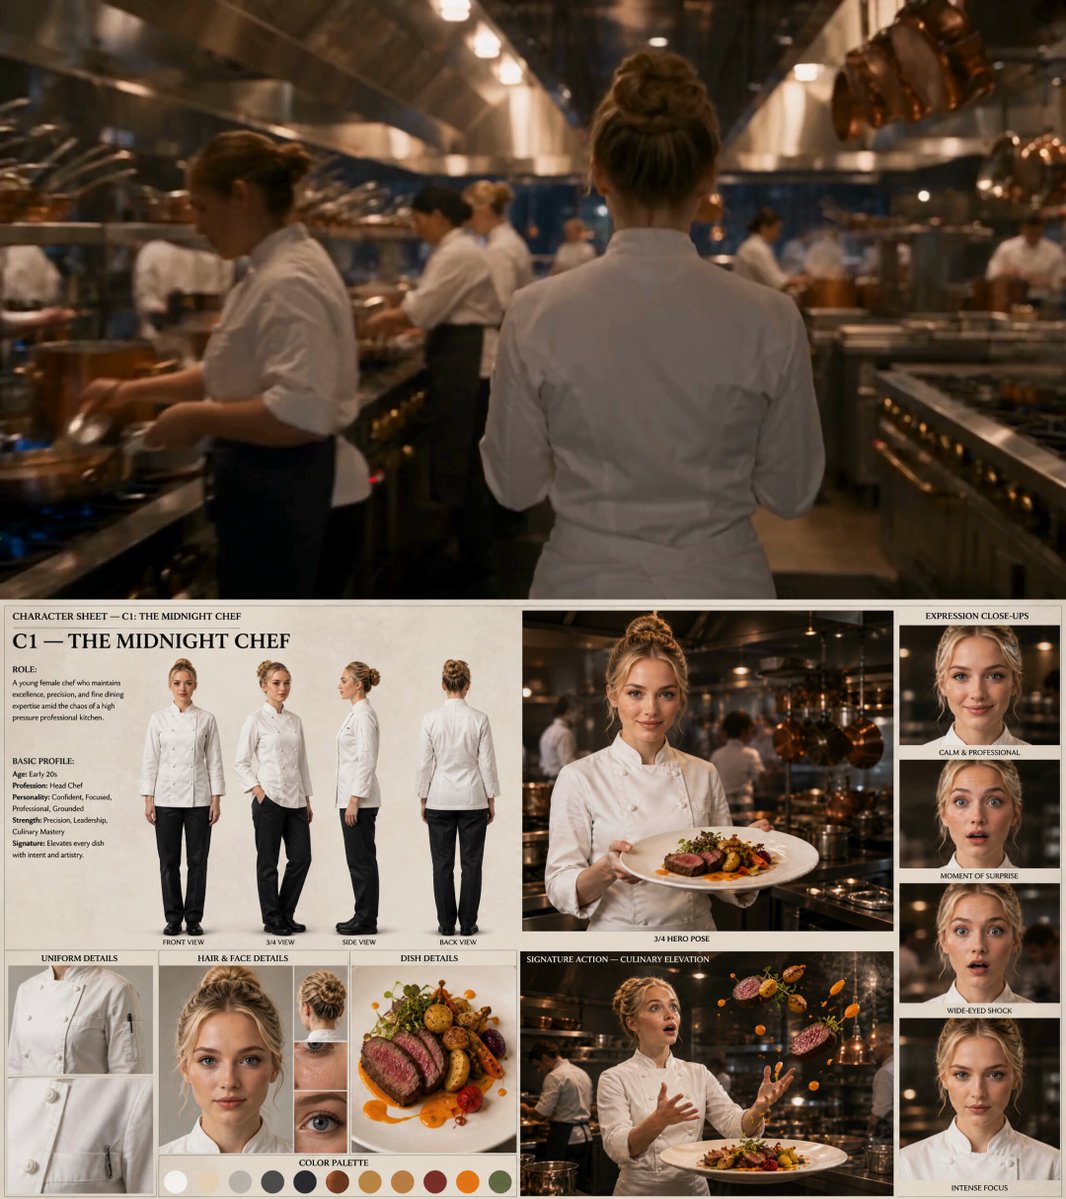
A single reference image is rarely enough. Build a small character sheet — ideally 4–8 images covering:
- Front, three-quarter, and profile views in neutral light
- A close-up for facial detail
- A full-body shot for proportion and wardrobe
- Two or three emotional states
Multi-image fusion lets you feed several of these simultaneously so the model blends identity across angles rather than guessing from one frame. If your tool supports weighted references, give the close-up more weight for dialogue shots and the full-body shot more weight for wide shots.
Wardrobe deserves special attention. Change a jacket color between shots and audiences read it as a different character, a different day, or a continuity error. Lock costume in the reference set and repeat the description verbatim in every prompt.
Keyframe control and start/end frames
Keyframe control is the single most powerful consistency technique available. Instead of describing motion and hoping, you define the first frame, sometimes the last frame, and let the model interpolate between them.
A practical pattern for a dialogue scene:
- Generate a still of the character mid-sentence with the intended framing.
- Use it as the start frame with a subtle motion prompt ("slight head turn, blink, shallow breathing, static camera").
- For the reverse angle, generate the matching still from the character sheet and repeat.
- Stitch the two shots in the edit so the eyelines match.
If your tool supports frame packing or multi-frame conditioning, you can supply a sequence of keyframes to control both the path of the camera and the timing of an action. This is how you get a hand reaching for a cup to land exactly on the beat you need. It takes more setup but eliminates the frustrating "almost right" render.
Style locks and color scripts
Write a one-paragraph style bible and paste it into every prompt. Include:
- Format and lens language (anamorphic, 2.39:1, 40mm equivalent)
- Lighting (single practical source, motivated soft key, dusk ambience)
- Palette (desaturated teal shadows, warm skin tones, amber highlights)
- Film characteristics (subtle halation, fine grain, no digital sharpening)
- References in plain language — era, genre, mood — rather than specific film titles
Then do a color script: list the dominant color of each shot in order. A gradual shift from cool to warm across 45 seconds does more for perceived production value than any single render upgrade.
Preproduction like a director, not a prompt typist
Write a shot list before you write a prompt
A shot list forces decisions that prompts cannot. For each shot, note:
| Field | Example |
|---|---|
| Shot number | 04 |
| Duration | 3.5s |
| Framing | Medium close-up |
| Camera | Slow push in, handheld |
| Action | She reads the message, looks up |
| Audio | Room tone, distant traffic |
| Purpose in story | Turning point |
If you cannot fill in the "purpose" column, cut the shot. AI makes it cheap to generate footage, which makes it easy to accumulate shots that do not serve the story.
Camera language that models understand
Models respond well to concrete cinematography vocabulary:
- Movement: dolly in/out, truck left, crane up, whip pan, orbit, static locked-off
- Lens: wide, normal, telephoto, macro, shallow depth of field, deep focus
- Angle: eye level, low angle, high angle, Dutch tilt, over-the-shoulder
- Speed: slow motion, real time, time-lapse, speed ramp
Keep camera instructions to one primary movement. "Slow dolly in while orbiting and racking focus" produces mush. If you need a complex move, split it into two shots and cut between them.
Anatomy of a prompt that works
A reliable structure has five parts:
- Subject — who or what, with locked descriptors.
- Action — one clear verb.
- Environment — location, time of day, weather.
- Camera — one movement, one lens, one framing.
- Style — your style-bible paragraph, trimmed to the essentials.
Example: "A woman in a charcoal wool coat stands on a rain-slicked platform, lifts her head as a train's lights approach. Night, mist, sodium street lamps. Medium shot, slow dolly in, 50mm, shallow depth of field. Anamorphic, desaturated teal shadows, warm skin tones, fine grain."
Notice there is one action, one camera move, and a consistent lighting statement. That is the entire secret.
The generate-review-refine loop
Work in passes
Pass 1 — blocking. Fast models, low resolution, many variations. You are hunting for composition and motion ideas. Do not polish anything.
Pass 2 — selection. Pull the best take per shot into a rough timeline with placeholder audio. Watch it start to finish. Roughly a third of your shots will be cut here. This is normal and healthy.
Pass 3 — fidelity. Re-render the surviving shots at higher quality, with refined prompts and locked keyframes.
Pass 4 — repair. Fix specific defects: a warped hand, a flickering background, a mouth that does not match the line.
Common failure modes and fixes
- Identity drift across shots. Add a second and third reference image; shorten the prompt so the model leans on the reference rather than inventing description.
- Melting hands and objects. Reduce motion complexity, shoot tighter, or occlude the problem area with framing, props, or a foreground element.
- Background morphing. Use a locked-off camera, or generate the plate as a still and animate only the subject.
- Jittery motion. Ask for slower action and add "smooth, fluid motion, cinematic motion blur" to the prompt.
- Wrong pacing. Extend or shorten in the edit rather than re-rendering; AI clips tolerate modest speed changes well.
- Prompt ignored entirely. Reorder so the camera instruction comes earlier, and remove contradictory descriptors.
When to switch models mid-project
Switch when a shot class consistently fails. If every dialogue close-up in one engine comes back with unstable eyes, move those shots to a different engine and keep the rest where it is. Model switching is a normal production technique, not a betrayal.
Sound design: the half of the film nobody renders
AI video gets all the attention, but audio is what makes a short feel expensive. Audiences forgive a slightly soft render; they do not forgive hollow sound.
Dialogue, foley, and ambience
Start by laying three beds under every scene:
- Ambience — continuous, quiet, scene-specific. Wind, room hum, distant city, forest.
- Foley — footsteps, fabric, cup placement, door latches. Small sounds sell physical presence.
- Dialogue — record it clean, or generate it, then treat it with a gentle EQ and de-esser.
Keep ambience at roughly -30 to -24 dB under dialogue, and foley peaking around -18 dB. If a shot feels weightless, the fix is almost always missing foley.
Music and the mix
Choose music after the rough cut, not before. Temp tracks are useful, but write or select the final cue against picture so hits land on cuts. A simple structure for a 45-second piece:
- 0–8s: single sustained element, minimal
- 8–25s: rhythmic pulse enters, build
- 25–35s: peak or drop on the story turn
- 35–45s: resolution, tail out
On the mix, duck music 3–6 dB under dialogue, and leave 1–2 dB of headroom. Export a stereo master and check it on phone speakers — that is where most short-form video is actually watched.
Editing, grade, and finishing
Cut on motion. If a character is turning their head in the last frames of shot A, start shot B on the same rotational direction. This single habit makes AI-generated sequences feel far more coherent.
Target an average shot length of 1.5–3 seconds for vertical social cuts and 3–5 seconds for widescreen narrative. Shorter is not always better; too many cuts read as insecurity.
For the grade:
- Normalize exposure across shots first, then apply a look
- Use one LUT for the whole piece, applied at 60–80% strength
- Add a subtle vignette and a touch of grain to unify renders from different engines
- Slightly crush blacks and desaturate shadows to hide compression artifacts
- Keep skin tones consistent even when the surrounding palette shifts
Finish with captions burned in or supplied as a sidecar file, and export at a high bitrate. Upload platforms re-compress aggressively, so give them something clean to work with.
A complete example: 45-second brand short
Concept: a courier delivers a package across a rain-soaked city at night.
Preproduction (1 hour). Shot list of 12 shots: two establishing city shots, four courier movement shots, three close-ups on hands and face, two destination shots, one product reveal. Write the style bible. Prepare a character sheet of six reference images and three location stills.
Generation (2–3 hours). Use a fast engine for all 12 shots at rough quality. Keep the best take of each. Re-render the eight survivors on a high-fidelity engine with keyframes: start frame from the location still, end frame from a separately generated still for the arrival. Expect 2–4 attempts per shot.
Assembly (1 hour). Drop into the timeline, cut on motion, adjust durations so the product reveal lands at 35 seconds.
Sound (1.5 hours). Rain and traffic ambience across the whole piece, foley on footsteps and the package handoff, one music cue with a build into the reveal, light dialogue only in the first shot.
Finish (45 minutes). Single LUT, exposure matching, grain, captions, two exports (9:16 and 16:9).
Total: roughly six hours of focused work for a piece that would previously have needed a crew, a permit, and a week.
Budget, time, and tooling decisions
Ask five questions before committing to a stack:
- How many finished shots do I need? Ten shots means 25–40 generations. Fifty shots means you need automation and a fast model.
- Is identity continuity critical? If yes, image-to-video with multi-image references is non-negotiable.
- Do I need audio baked in? Some engines produce synced dialogue; others require a separate pipeline. Decide early.
- What is my latency tolerance? Real-time ideation and overnight batch rendering are different workflows.
- What is the delivery format? Vertical-first changes framing, shot length, and caption placement.
Build a small internal kit: a style-bible document, a character sheet template, a shot-list spreadsheet, and a naming convention like project_scene_shot_take. That kit saves more time than any single tool upgrade.
Frequently asked questions
How long should an AI-generated cinematic short be?
45–90 seconds is the practical sweet spot. Long enough for a story turn, short enough to hold attention and keep consistency manageable.
Can I use one model for everything?
You can, but you will pay in quality. Most experienced creators use at least two: a fast one for exploration and a high-fidelity one for finals.
Why do my characters change faces between shots?
Almost always because references are too few or the prompt is too descriptive. Add reference images, shorten text, and repeat wardrobe and hair descriptors verbatim.
Do I need keyframe control for every shot?
No. Use it where the action must land precisely — object handoffs, reveals, dialogue beats. Free motion is fine for establishing shots and atmosphere.
How do I hide AI artifacts?
Frame them out, add foreground occlusion, cut faster in problem areas, and add grain and motion blur in the grade. Prevention through prompt simplification beats repair.
Is sound design really necessary?
Yes. It is the fastest way to move a project from "AI demo" to "film." Budget at least as much time for audio as for your final renders.
Final checklist before you export
- Every shot has a stated purpose in the story
- Character identity holds across all appearances
- Wardrobe, hair, and props are consistent
- Camera movement is motivated, not decorative
- Cuts land on motion or on musical beats
- Ambience, foley, and dialogue layers are all present
- Exposure and skin tones match shot to shot
- One unified look applied across all engines' output
- Captions are accurate and readable on a phone
- Exports exist in every aspect ratio you need
Cinematic short video with AI is not about finding the perfect model. It is about applying real filmmaking discipline to a toolset that finally keeps up with your ideas. Plan the shots, lock the references, layer the sound, and cut with intention — the technology will handle the rest.
