

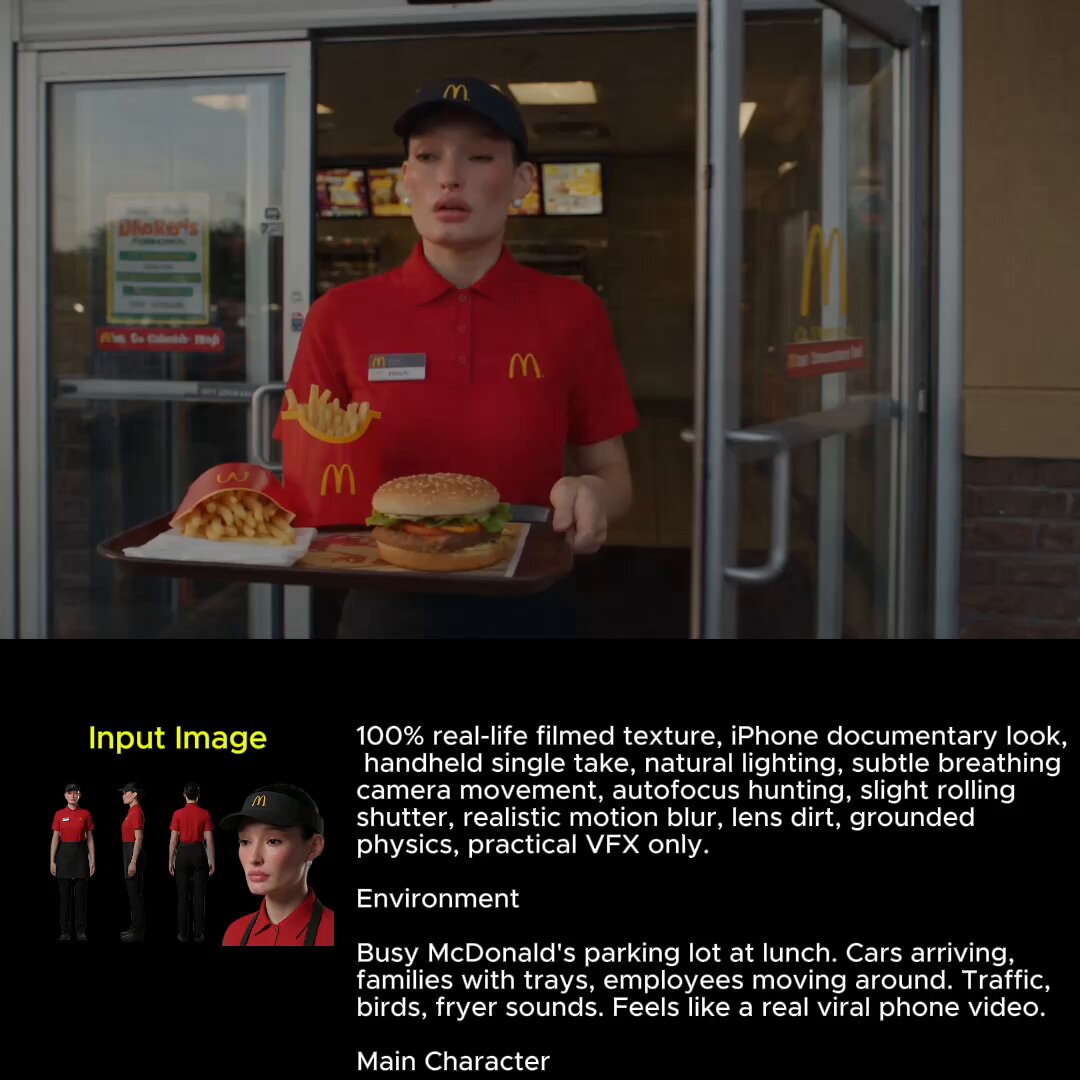
Text-to-video generators have quietly crossed a threshold. Instead of describing a scene once and hoping the model guesses right, you can now hand a system a small set of reference examples — a character sheet, four style frames, a short motion clip — and let it infer the rest. That shift, usually called few-shot video synthesis, is what turns AI video from a novelty machine into something usable for episodic series, product campaigns, and character-driven storytelling.
This guide walks through the practical side: how the underlying architecture shapes your results, how to build a repeatable production workflow, which prompting patterns hold up under pressure, how to pick between the leading generative models for a given shot, and where most creators lose consistency.
What Few-Shot Video Synthesis Actually Means
The term borrows from machine learning, where "few-shot" describes a model that generalizes from a handful of examples rather than thousands. In video generation, it means the model is conditioned on a small, curated bundle of inputs rather than a single sentence. That bundle might include:
- Two to eight still images of a character from different angles
- One or more style references (a color grade, a film stock, a lighting treatment)
- A short motion clip that demonstrates the camera move you want
- A written scene description with dialogue, blocking, or timing notes
- Optional depth, pose, or mask data to control composition
The important consequence is that the model is no longer inventing everything from scratch. It is interpolating inside a visual space you defined. That is why a well-built reference kit can produce a clip that looks like it belongs to the same production as the last ten clips, while a bare prompt usually cannot.
Few-shot versus zero-shot versus fine-tuning
| Approach | Inputs needed | Consistency | Setup effort | Best for |
|---|---|---|---|---|
| Zero-shot prompting | Text prompt only | Low to moderate | Minutes | Concept exploration, mood boards |
| Few-shot conditioning | 2–8 images plus prompt | Moderate to high | Hours | Series, branded content, recurring characters |
| Fine-tuning or adapter training | Hundreds of examples | Highest | Days to weeks | Long-running franchises, studio pipelines |
Few-shot sits in a useful middle ground. It is fast enough for daily production and strong enough to keep a face, a jacket, or a lighting setup recognizable across twenty clips. If you are producing anything with continuity — a mini-series, a tutorial with a recurring host, a product line with multiple variants — few-shot conditioning is the practical default.
Inside the Architecture Without the Hype
You do not need to read research papers to get good output, but understanding three layers helps you diagnose failures instead of re-rolling blindly.
Text and image encoders
Your prompt and your reference images are both converted into embeddings — numerical summaries of meaning and appearance. The text encoder captures intent ("slow dolly-in on a rain-slick street"), while the image encoder captures appearance (that specific face, that specific jacket texture). When the two signals disagree, the model usually follows the visual reference and treats the text as a softer suggestion. This is the single most common source of confusion for new users: if your reference images show a blonde character and your prompt says "dark-haired," you will get blonde.
The temporal backbone
The core generator produces frames, but a separate mechanism enforces relationships across time. Early systems handled this frame by frame and produced the infamous melting faces and flickering backgrounds. Modern architectures model motion as a latent trajectory, which is why camera moves, hair, and fabric now behave far more plausibly. When you see a clip that is beautiful for two seconds and then loses the plot, you are usually watching the temporal model run out of confident prediction — often because the action described exceeded what the reference set could support.
Why reference conditioning works
Attention mechanisms let the generator consult your reference images at every step of denoising. In practice, this means the model can ask, "what does this person's ear look like?" and retrieve an answer from your kit rather than hallucinating one. More references do not automatically mean better results: three sharp, well-lit, consistent images beat fifteen blurry ones every time, because noisy references create conflicting retrieval targets.
Building a Repeatable Few-Shot Workflow
The creative work is only half the job. The other half is a pipeline you can run again tomorrow without reinventing it.
Step 1: Lock the shot list before you write a prompt
Write the sequence on paper or in a document: shot number, duration, subject, action, camera, and the emotional beat. Ten to twenty shots is a comfortable first project. This step prevents the most expensive mistake in AI video — generating gorgeous clips that cannot be edited together because their framing, lens, or lighting do not match.
Step 2: Build the reference kit
For every recurring element, assemble a dedicated folder:
- Characters: front, three-quarter, and profile views; neutral expression plus one or two emotional states; consistent lighting across all of them.
- Environments: wide establishing frame, mid-shot detail, and one extreme close-up texture (concrete, fabric, foliage).
- Style: three to five frames that represent the grade you want, ideally from a project you already like.
Name files so you can find them mid-session. A folder called character_a_kit is worth more than a beautifully curated library you cannot navigate at speed.
Step 3: Write prompts with three distinct clauses
Separate subject, action, and camera into explicit clauses. A prompt like "a woman walks through a market, cinematic, 4k" gives the model almost nothing to anchor on. A production-ready prompt reads more like:
Subject: woman in her thirties, red canvas jacket, short dark hair, visible freckles. Action: she stops mid-step, turns her head left, expression shifts from neutral to wary. Camera: medium close-up, shallow depth of field, slow handheld drift right. Environment: covered market, warm tungsten practicals, light rain outside the awning. Continuity: same jacket, same hair length, same color grade as reference set.
Notice the continuity clause. It sounds redundant to a human, but it reliably nudges the model toward your reference set instead of its own prior.
Step 4: Generate in passes, not in one heroic run
Do not attempt a finished shot on the first generation. Instead:
- Composition pass — low resolution, focused only on framing and blocking.
- Motion pass — keep the winning composition, adjust only the action and camera timing.
- Detail pass — final render with the full reference kit attached.
- Repair pass — regenerate only the damaged segments and splice.
This staged approach saves considerable render time, because you are not paying for high-fidelity output while the composition is still wrong.
Step 5: Assemble, then finish
Export at a consistent frame rate and codec, cut in your editor, then add the layers that AI rarely nails: sound design, music, subtle grain, and color continuity. Audio is the fastest way to make generated footage feel intentional rather than synthetic. Footsteps, room tone, and a music bed do more work than another render attempt.
Prompt Patterns That Hold Up in Production
Certain structures survive contact with real projects.
The subject lock. Open every prompt with the same descriptive phrase for your character or product. Repetition is a feature, not a flaw — it stabilizes identity across clips.
Motion verbs over adjectives. "Walks," "turns," "lifts," "settles," and "glances" produce predictable motion. "Dynamic" and "cinematic energy" produce unpredictable motion. Choose verbs you could act out yourself.
One camera instruction per shot. Combining a dolly-in, a pan, and a rack focus in a five-second clip usually yields mush. Pick the move that serves the beat.
Explicit negatives. State what you do not want: no text overlays, no additional people in frame, no camera shake, no lens flare unless requested. Many tools accept a negative prompt field; use it.
Time markers. For clips longer than a few seconds, describe the shot in beats: "seconds one to three, she enters; seconds four to six, she notices the door." This gives the temporal model a structure to follow.
Choosing the Right Model for the Shot
Different generators have different personalities. Rather than crowning a winner, match the tool to the task.
| Shot type | What tends to work well | Why |
|---|---|---|
| Photoreal human close-ups | Runway Gen-4, Kling, Sora-class models | Strong facial detail retention and skin rendering |
| Stylized illustration or anime | Flux-based image pipelines feeding video models | Style references transfer cleanly through image conditioning |
| Long continuous takes | Models with strong temporal memory and clip extension | Fewer seams when you extend beyond the base length |
| Fast iteration and drafts | Luma Ray, Pika, MiniMax | Lower cost per attempt, quick turnaround for composition passes |
| Multimodal control (image plus motion plus audio cues) | Vidu Q1 and similar multimodal systems | Accept multiple conditioning signals in one request |
A practical pattern is to draft with a fast model and finish with a detailed one. Your composition pass rarely needs photoreal skin; your final pass rarely needs to explore five different framings.
Multimodal Control: Images, Depth, Motion, and Audio
Text alone is a blunt instrument. The most reliable clips come from stacking control signals.
Image references handle identity and appearance. Depth or pose maps handle composition and body position, which is invaluable when a character must interact with a specific object. Motion references — a short clip showing the camera move or the rhythm of an action — transfer timing in a way words struggle to describe. Audio cues, where supported, can drive lip movement and rhythm, and they make dialogue scenes far less robotic.
When stacking signals, introduce them one at a time. If you change the reference set and the motion input simultaneously and the result is wrong, you have no way to know which caused it. Change one variable per generation round; it feels slower and is dramatically faster overall.
Common Mistakes and How to Fix Them
Inconsistent references. If your character's jacket is red in two images and maroon in three, expect flicker. Curate ruthlessly.
Overstuffed prompts. Long prompts dilute attention. If a clause does not change the image or the motion, delete it.
Ignoring aspect ratio early. Deciding at the end that you need vertical delivery means re-framing every shot. Choose delivery format before the first render.
Chasing perfection in a single clip. Generated footage is assembled footage. Editors cut around flaws; perfectionists re-render for hours.
Neglecting continuity between shots. Eyeline direction, screen position, and light direction must match across cuts. Track them in a simple spreadsheet column next to each shot.
Skipping sound. Silent generated footage reads as a test. Sound turns it into a scene.
A Reusable Quality-Control Checklist
Run every clip through the same five checks before it enters the timeline:
- Identity: Does the subject match the reference kit across the full duration, including the final frames?
- Anatomy: Hands, teeth, eyes, and hair edges are the usual failure points — check them at full resolution.
- Motion logic: Does movement follow physical cause and effect, or does something drift without reason?
- Camera discipline: Is the move consistent, or does the virtual camera change its mind mid-shot?
- Editability: Is there enough head and tail room to cut cleanly, and does the color grade sit next to the neighboring shot?
Anything that fails two or more checks goes back for a repair pass rather than an apology in the edit.
Frequently Asked Questions
How many reference images do I actually need?
Three to five well-lit, consistent images per recurring subject is a strong starting point. Add more only when you notice a specific identity detail failing — an ear shape, a logo, a pattern.
Can I keep a character consistent across an entire series?
Yes, and the method is discipline rather than magic. Freeze the reference kit, freeze the descriptive subject line, and version your prompts so you can trace what changed when something drifts.
Why does my clip look great for two seconds and then degrade?
Usually the action you described outpaces what the reference set can support, or the clip runs longer than the model's confident prediction window. Shorten the action, strengthen the references, or split into two shots.
Is few-shot synthesis worth it for simple product videos?
Often, yes. Product consistency is easier than human consistency, and a locked kit of three angles per product variant pays for itself the moment you produce a second video in the same line.
Do I still need prompt engineering if I have good references?
References control appearance; prompts control behavior. You need both. A perfect reference kit with a vague prompt produces a beautiful clip of nothing happening.
How do I keep costs predictable?
Draft at low resolution with a fast model, reserve high-fidelity renders for approved compositions, and batch similar shots together so you reuse the same reference bundle and prompt scaffolding.
What about audio and dialogue?
Generate or record audio separately and treat it as the master track. Building picture around a finished audio bed produces tighter timing than trying to fit sound to generated motion.
Where to Take This Next
The real unlock in few-shot video synthesis is not a single model or a single prompt trick. It is treating generation as a production pipeline with inputs, passes, quality gates, and finishing steps. Assemble one reference kit, run one short sequence end to end, and document what worked. That document is worth more than any list of settings: it is the beginning of a house style that scales beyond a single project.
