
Why Stills Are the Best Starting Point for AI Video
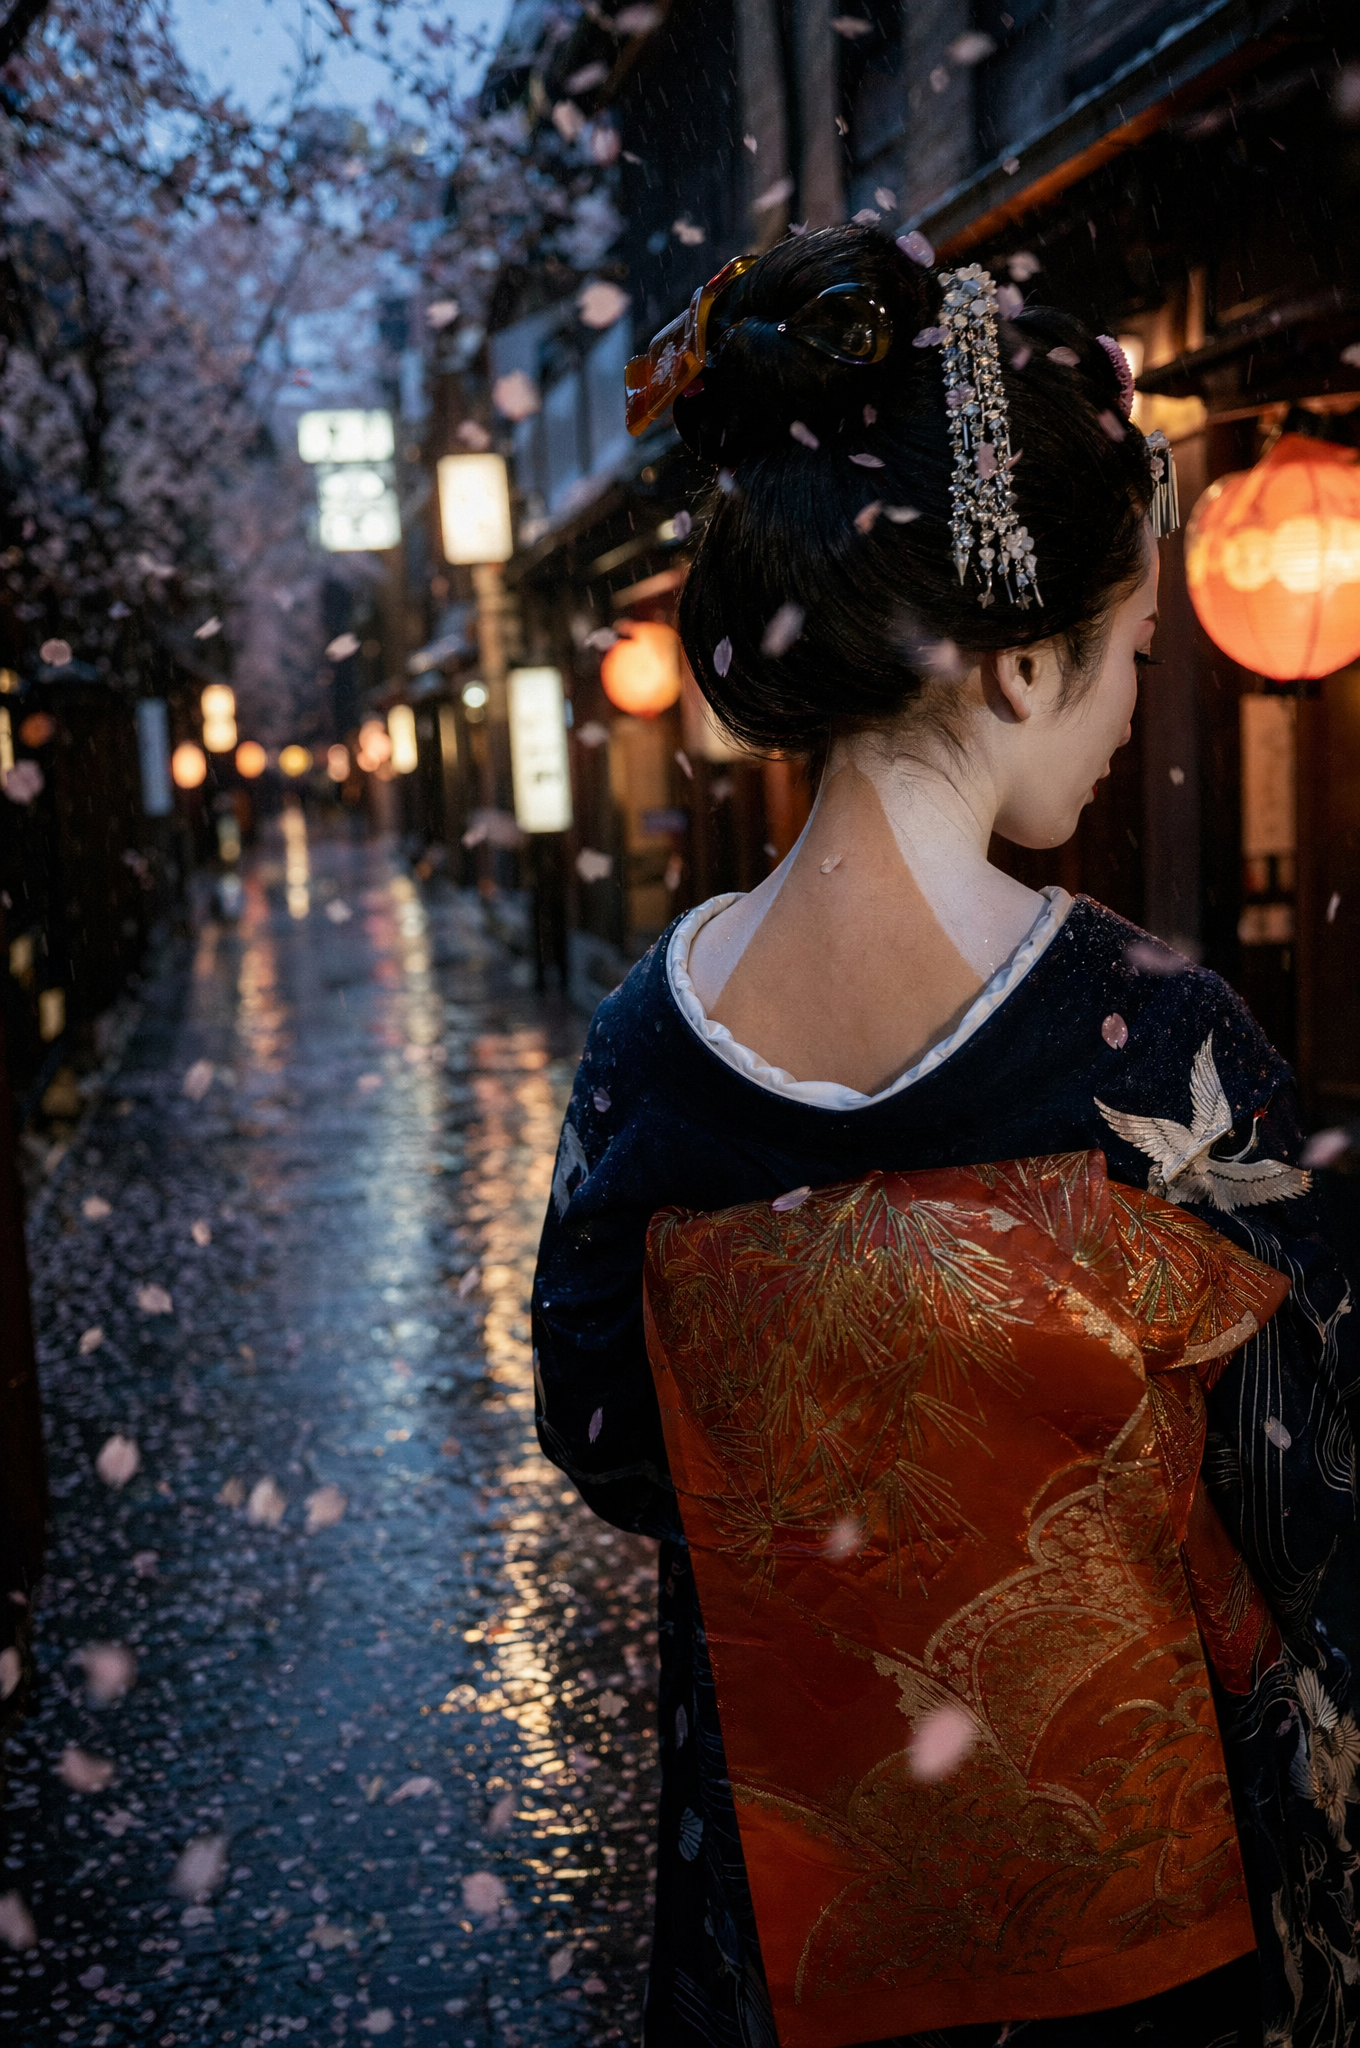
Most people approach AI video backwards. They type a text prompt, wait for something vaguely cinematic to appear, and then spend an hour trying to bend a random clip into the story they actually had in mind. Starting from a still image flips that equation. You know what the frame looks like before any motion exists, which means composition, wardrobe, lighting, and color are deliberate decisions rather than discoveries.
That control matters more than most beginners expect. Motion models are far better at animating a frame than at inventing one. When a still provides the visual anchor, the model spends its capacity on movement, parallax, and temporal consistency instead of guessing at faces, hands, and material texture. The output looks like the image you approved rather than a distant relative of it.
Stills are also cheap and fast to iterate on. A photograph, an illustration, a 3D render, or a frame pulled from stock footage can all serve as a seed. You can build a consistent cast by reusing the same character images across dozens of shots, which is the single most reliable trick for making AI video feel intentional instead of episodic.
And stills let you storyboard before you generate. Ten images reviewed in a grid tell you more about your film than ten loose clips scattered across a timeline. Fixing a weak composition takes a minute in an image editor. Fixing a weak clip usually means regenerating it and hoping.
How Image-to-Video Actually Works
Understanding the pipeline at a conceptual level pays off immediately, because it tells you which knobs are worth turning and which are noise.
The Pipeline in Plain Language
An image-to-video model takes a starting frame, encodes it into a compressed latent representation, and then generates a sequence of subsequent frames that continue that representation over time. Instead of predicting a single finished image, the model predicts a trajectory through image space. Your prompt and your control signals steer that trajectory.
This is why small prompt changes matter so much. You are not describing a picture; you are describing a direction of travel. "A woman in a red coat" produces a still. "A woman in a red coat turns her head slowly toward the camera as rain streaks past the window" produces a shot.
Why Temporal Consistency Is the Hard Part
Every frame in a clip inherits the flaws of its neighbors. If the model drifts on a face in frame 40, frames 41 through 90 inherit that drift and the whole shot reads as uncanny. This is the root cause of the classic failure modes: melting hands, clothing that changes color halfway through, backgrounds that quietly rearrange themselves.
Three practical levers reduce drift:
- Shorter clips. Generate four to six seconds at a time and cut between them. Long single takes give drift more room to accumulate.
- Simpler motion. A slow push-in or a gentle head turn is far more stable than a full-body sprint across a crowded street.
- Strong anchors. A crisp, well-lit source image with a clear subject and uncluttered background gives the model less to misinterpret.
Where Quality Is Won or Lost
Ranked by impact, the decisions that shape output quality are: source image quality, motion description specificity, clip duration, resolution, and finally the model choice itself. Most beginners invert this order and obsess over model selection while feeding in a blurry 400-pixel thumbnail with no motion direction. Fix the first three items and even a mid-tier model will produce usable footage.
Choosing the Right Generation Tool
There is no single best image-to-video tool, only the right tier for a given shot. Thinking in tiers keeps you from over-spending on simple shots and under-delivering on hero moments.
Model Tiers and What They're Good At
| Tier | Typical Strengths | Best Used For |
|---|---|---|
| Photoreal flagship | Skin detail, natural light, realistic physics | Hero shots, product close-ups, talking-head inserts |
| Balanced mid-tier | Good motion, fast turnaround, wide prompt tolerance | Social clips, b-roll, rapid iteration passes |
| Stylized / open models | Distinct aesthetics, strong style adherence, fine control | Animation, surreal sequences, music-video looks |
| Specialist tools | Specific controls such as depth, pose, or camera paths | Locked-off shots, character consistency, previz |
Decision Criteria That Actually Matter
Ask four questions before you commit to a tool for a project:
- Does it accept my source image as-is, or does it need resizing and cleanup? Tools that handle odd aspect ratios gracefully save real time.
- How much motion control do I get? Some tools accept only a text prompt; others take camera paths, depth maps, or motion brushes. More control is not always better, but for narrative work it usually is.
- How consistent is the output across repeated runs? Run the same image and prompt three times. If the results vary wildly, plan for extra generation passes.
- How well does it handle faces and hands? These are the two areas where audiences notice failure instantly. Test with a close-up before trusting a tool with your whole project.
Building a Small Personal Benchmark
Create a five-image test set: one portrait, one full-body shot, one product close-up, one wide landscape, and one complex interior with reflections. Run every new tool against the same five images with the same prompts. Within twenty minutes you'll have a far more useful opinion than any review can give you, and you'll have a reusable baseline for future comparisons.
The Image-to-Video Workflow, Stage by Stage
Here is a workflow that scales from a single social clip to a multi-scene short film.
Stage One: Prepare the Source Frame
Upscale anything below 1080 pixels on the short side, and clean up obvious artifacts before generating. Crop to your delivery aspect ratio early — a 16:9 image pushed into a 9:16 frame loses the composition you designed. Keep a master folder with the original, the cropped version, and a note about what motion you intend for each frame.
Stage Two: Write the Shot, Not the Scene
A scene description belongs in your outline. A shot description belongs in the generator. Replace "a tense conversation in a diner" with "medium close-up, woman in green jacket, steam rising from coffee cup, slow push-in, background patron out of focus." Specificity about framing and motion beats poetic language every time.
Stage Three: Generate in Short Passes
Produce four to six second clips. Generate three variations of each shot rather than one, because the hit rate on any single pass is unpredictable. Label them by shot number and take letter so your editing timeline stays sane.
Stage Four: Select and Assemble
Drop the takes into an editing timeline in story order before you judge them individually. A clip that looks mediocre in isolation often works perfectly as a one-second transition, and a beautiful clip that runs eight seconds may be dead weight at three.
Stage Five: Repair and Polish
Fix small defects with standard post tools. Speed-ramp through a two-frame glitch. Mask and replace a hand that curls incorrectly. Add grain or a subtle color grade over the whole sequence so the clips feel like they came from the same camera even if they came from different tools.
Prompting for Motion, Not Just Scenes
Prompt writing for video differs from image prompting in one crucial way: verbs carry more weight than adjectives.
A Motion Vocabulary That Works
Group your motion language into four families and mix one from each:
- Subject motion: turns, steps forward, glances up, raises a hand, exhales, blinks, smiles slowly
- Camera motion: slow push-in, pull-back, lateral truck, handheld sway, crane up, orbit
- Environmental motion: rain falling, curtains drifting, steam curling, crowd passing, dust motes
- Temporal cues: gradually, steadily, suddenly, in one continuous take, at half speed
A prompt that uses all four families reads like a shot list and produces far more predictable results than a paragraph of atmosphere.
Negative Prompts and Failure Modes
Most tools accept a negative prompt or an exclusion field. Use it surgically rather than dumping a list of twenty fears into it. Start with the three failures you actually saw in your last batch — often things like fast motion, camera shake, or text overlays — and add one term at a time until the failure stops appearing.
Prompt Length and Specificity
Two to four sentences is the sweet spot for most models. Under ten words and the model invents details you did not want. Over a hundred words and the model starts dropping constraints, usually the ones at the end. Put your most important instruction first.
Iterate on One Variable at a Time
Change the camera move OR the subject action OR the lighting description, never all three. This is slower in the moment and dramatically faster across a project, because you learn what each change actually does instead of guessing at a blur of simultaneous edits.
Camera Language and Cinematography for AI Clips
AI video rewards directors who think like camera operators. The model has no taste; it follows instructions.
Framing and Focal Length
Specify shot size explicitly — extreme wide, wide, medium, medium close-up, close-up, extreme close-up. Then add a lens feel: wide-angle with visible distortion, 50mm natural perspective, 85mm compressed background. This single addition does more for perceived production value than any other prompt technique.
Movement That Reads as Intentional
Slow, deliberate movement almost always outperforms fast movement in generated footage. A two-second slow dolly reads as a deliberate choice. A two-second whip pan reads as a mistake even when it was intentional, because the model rarely renders motion blur convincingly.
Lighting Continuity Across Shots
Decide on one lighting direction per scene and describe it in every shot prompt: window light from camera left, overhead practical, backlit rim with soft fill. Generative clips have no memory of your previous shots, so continuity is something you author repeatedly, not something the tool provides.
Coverage Strategy
Generate a wide establishing shot, a medium of your subject, a close-up of a detail, and an insert of a relevant object for every scene. That four-shot minimum gives any editor enough material to build a rhythm, and it costs far less than generating a dozen variations of one angle.
Editing Generated Clips into a Real Film
Raw generated clips look like raw generated clips. Editing is where they become a film.
Continuity and Eyeline
Keep subject position and facing direction consistent across cuts. If your character looks left in one shot and right in the next, the audience reads it as a jump rather than a cut. When in doubt, insert a neutral establishing shot between two mismatched angles.
Rhythm and Cutting on Motion
Cut on movement — a head turn, a step, a hand gesture — rather than on stillness. Motion hides the exact frame of the cut and makes transitions between mismatched clips feel seamless. Keep the first thirty seconds of any piece fast; attention is earned before it is kept.
Sound Design Does Half the Work
Room tone, footsteps, fabric rustle, and a music bed with a clear emotional direction will carry clips that are visually imperfect. Silence makes every AI artifact visible. Add ambience under dialogue-adjacent scenes and a subtle low-frequency layer under tense moments.
Color and Grain as Unifiers
Apply one grade across the whole project and one grain setting on top. A shared look is what convinces viewers that a sequence of independently generated clips came from a single camera. Consistency beats perfection.
Quality Control, Troubleshooting, and Common Mistakes
The Five-Point Clip Check
Before a clip goes into the timeline, verify: does the subject's face hold for the full duration, do hands stay anatomically plausible, does the background remain stable, is there any unintended text, and does the motion complete rather than stutter to a stop? Failing two or more checks means regenerate, not repair.
Common Mistakes and Their Fixes
- Using a low-resolution source. Fix: upscale and sharpen before generating.
- Asking for long, complex takes. Fix: generate short clips and cut between them.
- Prompting scene instead of shot. Fix: write framing, subject, action, camera, and lighting in that order.
- Mixing radically different styles in one project. Fix: standardize one look and apply it everywhere.
- Judging clips in isolation. Fix: review in context on the timeline.
- Ignoring aspect ratio. Fix: crop the source before generation, not after.
- Skipping sound. Fix: build a rough audio bed before you finalize the edit.
When to Regenerate vs. When to Edit
If the defect is small, localized, and in a single frame range, edit it. If it moves, changes size, or affects the face, regenerate. Chasing a moving artifact through post-production costs more time than three fresh generations.
Scaling Into a Repeatable Pipeline
Once a single clip works, the challenge becomes consistency across dozens of them. Build a small production system rather than relying on memory.
Maintain a prompt library organized by shot type, with your best-performing phrasings saved verbatim. Keep a character sheet with reference images and a written description of each recurring subject. Track which tool produced which shot so you can reproduce a look later. Standardize export settings and naming conventions from day one; renaming forty files at the end of a project is pure waste.
Batch similar tasks. Generate all your establishing shots in one session while the prompt style is fresh in your mind, then all close-ups, then all inserts. Context switching is the quiet productivity killer in AI video work.
Finally, review your pipeline monthly. Tools change quickly, and a step that required manual cleanup last month may now be handled automatically. A pipeline you never revisit slowly becomes a pipeline that wastes your time.
FAQ
How long should each generated clip be?
Four to six seconds is the reliable range for most models. Longer clips are possible but drift accumulates, and a two-second stretch inside a long clip often ruins the whole take. Cutting between short clips also gives you more editorial control.
Do I need a powerful computer?
For cloud-based generation, no. For local open models, a modern GPU with plenty of video memory makes a large difference in both speed and the resolution you can attempt. If you only generate occasionally, cloud tools are usually the simpler path.
What makes a good source image?
Sharp focus on the subject, clear separation between subject and background, even lighting, and no clutter near the edges. A striking image is not automatically a good source; a clean, readable one usually is.
Can I keep a character consistent across many shots?
Yes, with discipline. Reuse the same reference image, repeat the same descriptive phrases word for word, and keep costume and lighting descriptions identical between shots. Consistency comes from repetition, not from the model remembering your character.
Why does my output look worse than my source image?
Usually because the model is spreading detail across many frames and drifting as it goes. Shorten the clip, simplify the motion, and specify a slower camera move. If quality still drops, your source may be too complex or too low-resolution for the model to hold.
How do I handle hands and faces?
Favor wider framing where these details occupy fewer pixels, keep subject motion slow, and check results in the first second rather than the last. Close-ups are worth attempting only after you have confirmed a tool handles them well in testing.
Is prompt engineering really necessary?
Some level of it, yes. You can get acceptable results with vague prompts, but the difference between vague and specific is the difference between footage you tolerate and footage you use. A structured five-part prompt template costs nothing and improves every clip.
What should I learn first?
Shot description. Before you touch settings, resolution, or model comparisons, learn to describe a single shot in terms of framing, subject, action, camera movement, and lighting. That skill transfers across every tool you will ever use.
