
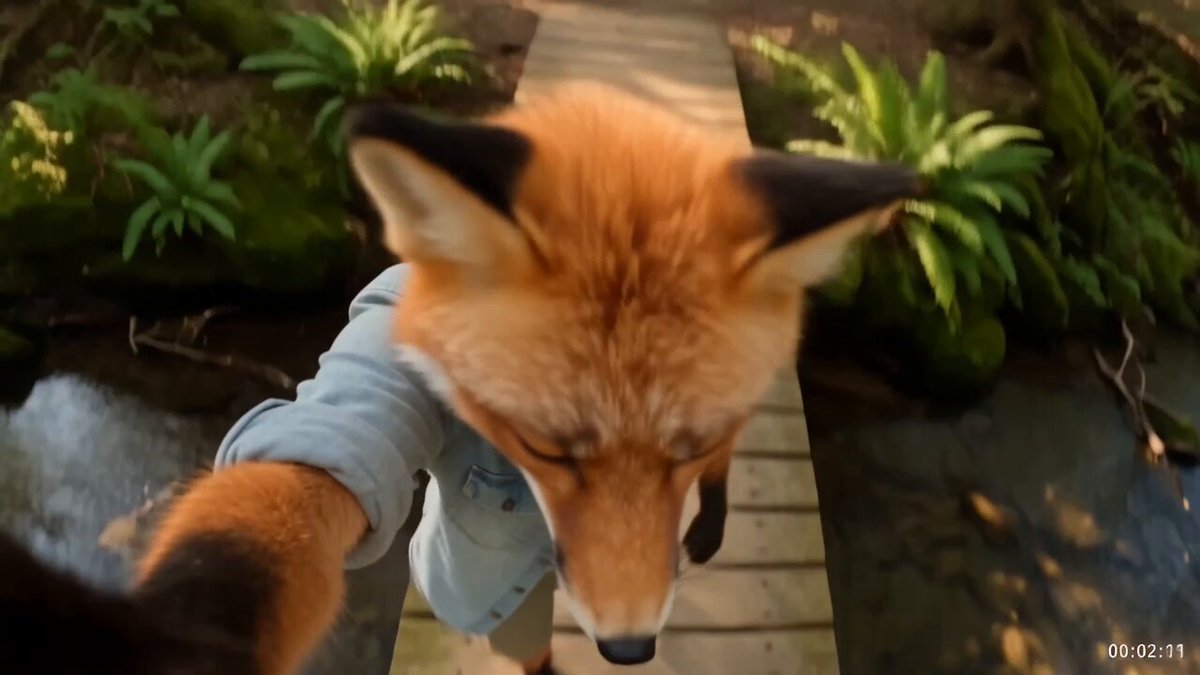
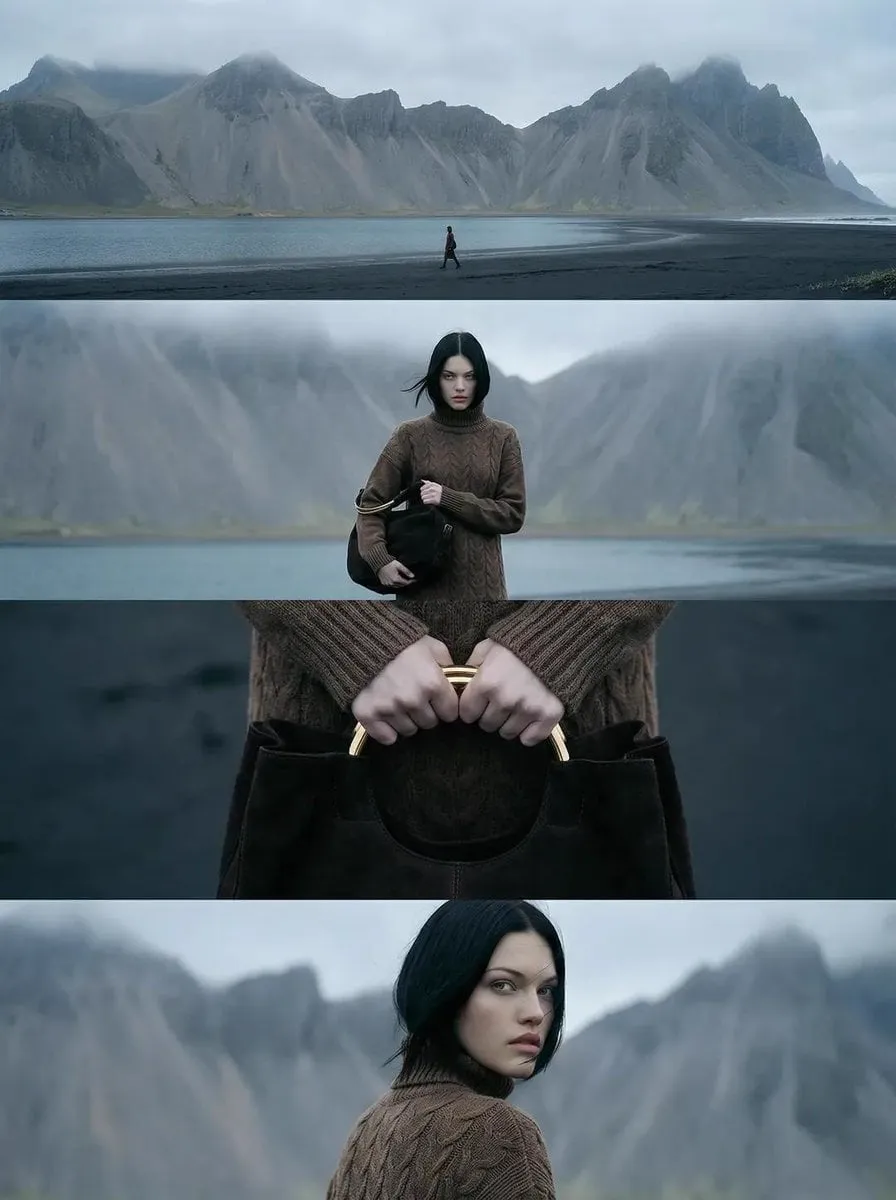
Most short-form video pipelines start with a blank timeline and a vague idea. An image-first pipeline flips that order: you begin with a frame that already looks good, then teach it how to move. That inversion is why still-to-motion generation has become the default entry point for creators who need volume without surrendering visual control.
This guide is a working manual, not a list of tools. It covers how the underlying models behave, how to choose between them, how to write motion prompts that survive contact with reality, and how to assemble individual clips into a reel that holds attention past the third second.
Why image-first production wins on short-form platforms
Short-form feeds reward two things above all: a legible first frame and continuous micro-movement. A static, perfectly composed photograph satisfies the first condition instantly. It fails the second, and the feed punishes stillness faster than it punishes imperfection.
Starting from an image also solves the hardest problem in generative video, which is intent. When you generate from text alone, the model invents composition, lighting, subject, and camera all at once. Any one of those going wrong ruins the shot. When you generate from an image, composition and lighting are already locked. The model only has to answer one question: what moves, and how?
There is a production argument too. Photographers, product teams, and illustrators already sit on libraries of usable frames. Storyboards, mockups, archival photos, and 3D renders can all be animated without a reshoot. For social teams operating on a weekly cadence, that backlog is the cheapest source of new video that exists.
Finally, image-first work is far easier to review. A client or stakeholder can approve a still in seconds. Approving a generated clip takes longer, but at least the disagreement is about motion rather than about whether the subject looks right.
How still-to-motion generation actually works
Understanding the mechanics changes how you prompt. Every major model does roughly the same thing: it encodes your source frame into a latent representation, then predicts a sequence of latent frames conditioned on your text instruction and on a motion prior learned from video data.
Motion priors and temporal consistency
A motion prior is the model's statistical expectation of how things move. It expects water to ripple, hair to sway, crowds to drift, and cameras to glide or push. When your prompt conflicts with the prior, you get artifacts: rubbery limbs, warping backgrounds, subjects that melt at the edges.
The practical rule is to ask for motion the model already believes in. Small, physically plausible changes read as cinematic. Large, physically implausible changes read as broken. A subtle head turn with a slight parallax on the background will almost always beat an ambitious full-body spin.
Temporal consistency is the second constraint. Every frame must agree with the frames around it. Long clips give the model more chances to drift, which is why short generations are consistently cleaner than long ones. Two clean four-second clips, cut together, beat one muddy ten-second clip almost every time.
What duration, resolution, and aspect ratio mean for reels
Most current generation models produce clips in the two-to-ten second range from a single still, with vertical and square outputs widely supported. For reels, treat four to six seconds as the sweet spot: long enough to establish motion, short enough that drift never has time to set in.
Resolution matters less than people assume, because most platforms re-encode aggressively anyway. What matters is aspect ratio discipline. Decide up front whether you are delivering 9:16, 4:5, or 1:1, and generate natively in that ratio. Cropping a wide generation into vertical is a reliable way to lose the composition you carefully built.
Choosing the right model for the shot
No single model wins every category. The productive approach is to build a small stable of tools and route each shot to the one that fits.
Decision criteria that actually matter
- Motion ambition: Does the shot need a locked-off micro-movement, or a real camera move? Conservative models handle the first beautifully and fail at the second.
- Style fidelity: Some models preserve illustration and anime line art cleanly; others smear it. Test with your own source material, not with demo reels.
- Character consistency: If the same face appears in multiple shots, prioritize models with strong reference conditioning.
- Generation speed: For iteration-heavy work, a fast, slightly weaker model you can run fifteen times beats a slow model you can run twice.
- Output control: Prefer models that expose camera controls, motion strength, and seed locking rather than a single prompt box.
- Licensing and commercial terms: If the output is client work, read the terms before you build a dependency.
Well-known model families and where they fit
Runway's generation tools are strong generalists with useful camera and motion controls, well suited to stylized and cinematic shots. Luma Dream Machine tends to produce smooth, organic camera movement and handles natural scenes gracefully. Kling is frequently chosen for human motion and expressive faces. Pika leans toward playful, stylized, and effect-driven clips. Wan and similar open-weight options appeal to teams that need self-hosting or fine-tuning. Google's Veo family is often used when prompt adherence and longer coherent shots matter most. Minimax Hailuo is another common choice for expressive character motion.
The correct move is not to pick a winner but to run the same source frame through three models on the lowest settings, compare the four-second results, and keep a note of which one handled your specific subject. That small test costs minutes and saves hours later.
Prompt engineering for motion
Text prompts in image-to-video do not describe the scene. The image already did that. Prompts describe change over time. That is a different grammar, and it is where most beginners lose quality.
The motion sentence formula
A reliable structure is: subject action, then secondary motion, then camera behavior, then atmosphere.
- Subject action: the woman turns her head slowly toward the window
- Secondary motion: steam rises from the cup in her hands, a curtain drifts
- Camera behavior: slow push in, shallow depth of field, no shake
- Atmosphere: soft golden light, gentle film grain
Written as one line: a woman turns her head slowly toward the window, steam rising from the cup in her hands, a curtain drifting behind her, slow push in, shallow depth of field, soft golden light, gentle film grain.
Keep the total instruction concise. Long prompts dilute attention and cause the model to satisfy half of every clause.
Camera language that models understand
Use plain cinematic vocabulary: slow push in, pull back, pan left, tilt up, orbit around the subject, handheld drift, locked-off tripod, dolly forward. Avoid contradictory pairs in the same prompt, like both locked-off and handheld, or both slow push in and pull back. If you want a move, name one move.
Motion strength settings are the second lever. High strength produces dramatic movement and more warping; low strength produces subtle, believable life. For portraits and product shots, stay low. For landscapes and abstract plates, you can push higher.
Handling artifacts with negative instructions
When a model offers negative prompts or an exclusion field, use it. Useful entries include warping, morphing, extra fingers, distorted face, flickering, jitter, text artifacts, watermark, and duplicate limbs. If your tool does not support negative prompts, bake the intent into positive phrasing: keep facial features stable, maintain consistent background, no camera shake.
Keyframe control and continuity across a sequence
A single generated clip is not a reel. Continuity is what separates a montage from a story.
First-frame and last-frame conditioning is the most powerful control available. If a model accepts a start image and an end image, you can dictate exactly where a shot begins and ends, which makes cutting between shots far smoother. It also lets you chain clips: use the last frame of shot one as the first frame of shot two, and the transition becomes nearly invisible.
Multi-image fusion takes this further. By feeding several reference images of the same subject, character, or location, you anchor identity across shots. This is how you keep a recurring presenter or a product looking identical across six clips without fine-tuning.
Practical continuity checklist:
- Fix a seed for each shot and only change the prompt between iterations.
- Keep lighting direction consistent across all source frames before you generate.
- Match motion strength across clips in the same sequence; a sudden jump from locked-off to dramatic orbit reads as an error.
- Maintain a shared color grade, applied after generation rather than baked in.
- Keep a written log of model, prompt, seed, and strength for every approved clip.
Building a shot list from a photo library
Before generating anything, audit what you already have. Sort images into four buckets: hero frames (the subject, perfectly lit), texture plates (backgrounds, skies, surfaces), detail shots (hands, packaging, fabric), and transitions (blurred foregrounds, doorways, silhouettes).
A thirty-second reel typically needs eight to twelve clips of two to three seconds each, plus a hook. Map your buckets onto a beat structure:
- Hook (0-2s): the single most striking frame, with the most dramatic but simple motion.
- Context (2-8s): two or three clips that establish place and subject.
- Development (8-20s): the core sequence, alternating wide and detail shots.
- Turn (20-25s): one clip with a clear directional change or reveal.
- Payoff (25-30s): a held shot with minimal motion and a clear end card.
Good source frames share three properties: clean edges around the subject, clear separation between foreground and background, and at least one element that can plausibly move. Images with busy, cluttered detail and no depth tend to produce muddy results.
A repeatable production workflow, step by step
- Assemble and normalize source frames. Crop to the target aspect ratio, correct exposure, and upscale weak images before generation. Garbage in, garbage out applies double here.
- Write the shot list with motion notes. One sentence per clip describing the movement you want, plus the model you intend to use.
- Run cheap tests. Generate at the lowest quality setting with two or three models to compare motion character. Delete aggressively.
- Lock the seed and refine the prompt. Change one variable at a time. If the first frame looks wrong, fix the source image, not the prompt.
- Upscale and interpolate the winners. Frame interpolation raises the frame rate and smooths motion; upscaling restores detail. Do the interpolation first, then upscale.
- Grade and stabilize. Apply a single look to the whole sequence. Add subtle stabilization to handheld-style clips, but leave intentionally dynamic shots alone.
- Cut to a music bed. Place your strongest motion on the downbeats and keep cuts on the beat. For voiceover-driven reels, cut on sentence ends instead.
- Add text, captions, and the end card. Keep overlays in the safe zone, away from platform UI elements at the top and bottom.
- Export and version. Deliver a clean master plus a platform-ready file. Keep the project file, source frames, and generation log archived.
Quality control, exports, and delivery
Watch every export on a phone before you publish. Desktop monitors hide vertical framing problems, and phone speakers reveal audio that felt fine in headphones.
A short pre-publish checklist saves entire campaigns:
- The first frame reads clearly at thumbnail size.
- Motion begins within the first half second.
- No clip exceeds four seconds without a cut or a deliberate hold.
- Captions are legible against every background, not just the first one.
- Audio is normalized, with no clipping at transitions.
- The end card is visible for at least one and a half seconds.
For exports, a high-bitrate 1080x1920 H.264 file is the safest universal delivery. Keep a higher-resolution master for reuse in other formats.
Common mistakes and how to fix them
Overloading the prompt. If you describe four actions, the model will do one badly. Fix: one primary action per clip.
Ignoring the source image. Warping at the edges usually traces back to a low-quality or low-contrast source frame, not the model. Fix: upscale and sharpen before generating.
Generating too long. Drift, face changes, and background melt all scale with duration. Fix: generate short and cut more often.
Inconsistent lighting across clips. A sequence generated from frames shot at different times of day looks assembled, not directed. Fix: normalize color and contrast across all source frames first.
No hook. A beautiful opening clip with no movement in the first second loses viewers before the reel starts. Fix: open with the shot that has the most motion or the most contrast.
Chasing model features instead of a workflow. Every tool produces good output occasionally. Consistency comes from a repeatable pipeline, not from a new model.
Forgetting the audio layer. Motion without sound design feels unfinished. Even a single ambient bed and a soft whoosh on a cut lifts perceived quality dramatically.
Frequently asked questions
How many images do I need to build a reel?
Eight to twelve usable frames is a comfortable starting point for a thirty-second vertical video. You can produce a strong fifteen-second reel with four: a hook, two development shots, and a payoff.
Should I generate in vertical or crop later?
Generate natively vertical. Cropping a wide generation into 9:16 usually destroys the composition and pushes the subject out of frame, especially with camera movement.
How do I keep the same character across multiple clips?
Use reference-image conditioning or multi-image fusion anchored to a consistent, well-lit portrait. Keep the seed fixed where the tool allows it, and describe the character identically in every prompt.
Why does my output look warped or rubbery?
Usually because the requested motion exceeds the model's motion prior. Reduce motion strength, simplify the action to something physically plausible, and check that your source frame has clean edges around the subject.
Is frame interpolation worth it?
Yes, in most cases. Interpolation smooths the stepping that short generated clips often show. Apply it before upscaling so the upscaler receives clean, dense frames.
Can I use generated clips for client work?
That depends entirely on the terms of the specific tool you use. Check commercial usage and licensing before building a client deliverable on top of any model, and keep a record of which tool produced which asset.
How do I make a reel feel less obviously AI-generated?
Anchor everything in real photographic structure: consistent lighting, believable camera language, natural pacing, and deliberate sound design. The tell is rarely the model; it is the absence of editorial decisions.
Where to go from here
Pick three source frames you already own, run each through two different models at low settings, and compare the four-second results side by side. That single experiment will teach you more about motion priors, prompt phrasing, and model fit than any list of settings.
From there, build the boring parts of the pipeline: a normalized frame library, a shot-list template, a naming convention for exports, and a generation log. The creative work gets easier when the mechanical work is repeatable. Image-first reels are not a shortcut around craft; they are a way to spend more of your time on the decisions that actually show up on screen.
