
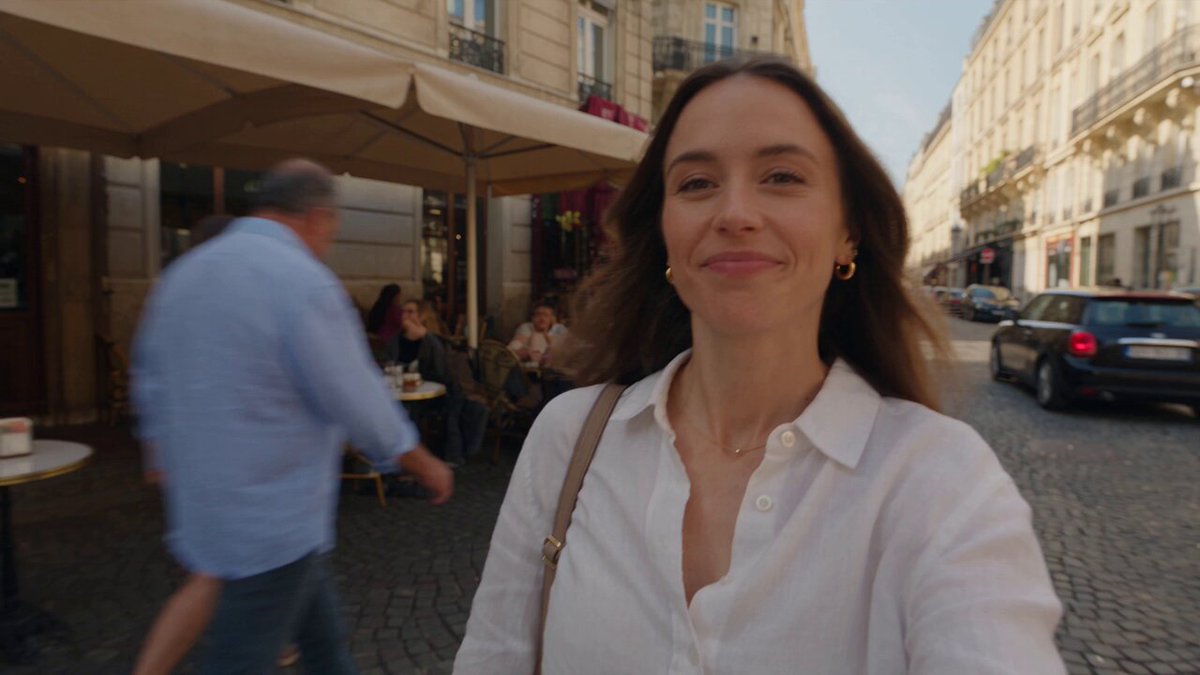
Why identity drift breaks photorealistic AI video
A photorealistic AI video lives or dies on a single promise: the person on screen is the same person from the first frame to the last. When that promise breaks — a jawline that widens, eyes that change spacing, a hairstyle that mutates between shots — viewers stop reading the clip as footage and start reading it as a glitch. The story collapses, and no amount of cinematic lighting rescues it.
Identity drift is not a cosmetic problem. It shows up in very specific places:
- Narrative series, where audiences track a character across episodes and notice a changed nose instantly.
- Ad campaigns, where a spokesperson must look identical across cutdowns, aspect ratios and localized versions.
- Product films, where licensed talent must not morph into a different person mid-sequence.
- Mixed pipelines, where several models touch the same shot and each interprets the same text prompt differently.
The usual fixes are weak. Repeating a phrase like same woman, thirties, brown eyes in every prompt does nothing, because the model rebalances facial geometry to satisfy whatever else the prompt asks for. Locking a seed only helps while the lighting, angle and wardrobe stay identical. The moment a scene changes, the face slides.
The Lego Pixel technique attacks the problem at its source. Instead of describing a person and hoping, you build the identity from small, standardized, reusable blocks and fuse those blocks at generation time. The blocks stay constant. Only the scene around them changes.
What the Lego Pixel technique actually means
The name comes from the way a complex object is assembled from a small set of identical interlocking bricks. Applied to AI video, it means decomposing a character into a handful of reusable components, each of which can be reused verbatim in every shot.
A practical decomposition looks like this:
- Structure block — skull proportions, interocular distance, nose bridge width, jaw angle, chin projection, ear placement.
- Surface block — skin tone map, texture, freckles, pores, age markers, natural asymmetry.
- Grooming block — hairline, hair silhouette, part line, facial hair pattern, eyebrow shape.
- Wardrobe block — garments, fabric behaviour, accessories, jewellery that stays constant across a sequence.
- Light response block — how that specific skin reacts to key light, rim light and bounce.
- Camera block — lens length, camera distance, depth of field, grain and grade.
Multi-image fusion instead of one reference photo
Single-image prompting gives the model one lighting condition and one angle, then asks it to invent everything else. Multi-image fusion constrains several axes at once. You supply a reference set where each image carries one or two blocks cleanly, plus a scene prompt that only specifies what is allowed to change.
Why it beats prompt-only consistency
Text is a poor carrier of identity. A model reading the same description twice will produce two plausible faces, not one repeated face. Reference images carry far more information per token of effort, and when they are structured as blocks, they do not fight each other. This is the difference between describing a face and shipping one.
Building a reusable character reference pack
Before you render a single second of video, build the asset that makes every later shot cheap: a reference pack for each cast member.
The shot list of a good pack
- Front-facing, neutral expression, even light
- Three-quarter left and three-quarter right
- Full profile, both sides
- Slight upward and slight downward angles
- Two or three expressions: neutral, speaking, light smile
- Two lighting conditions: soft daylight and harder directional key
- Full body or three-quarter body shot for proportions
- One wardrobe variant if the sequence changes clothing
Twelve to thirty sharp images is the useful range. Fewer than ten and the model guesses; more than forty and the identity starts averaging toward a generic face.
Quality rules that matter more than quantity
Keep every image sharp, free of motion blur and free of heavy filters. One face per frame, neutral background, no other people. Never mix ages or drastically different body weights in the same pack — the model will blend them. And be careful with beauty retouching, because smoothing that alters bone structure is exactly the information you are trying to preserve.
Write a portable identity packet
Alongside the images, keep a short text packet: the anchor description, the wardrobe block, the finish block, and a list of which reference file carries which block. This packet is what lets you move the character between tools without rebuilding the identity from scratch.
The Lego Pixel workflow, step by step
Step 1 — Audit and lock anchors
Generate a single hero still of the character in the target grade. Compare it against the reference pack with side-by-side crops. Adjust the reference set, not the prompt, until the hero still is unmistakably the same person. This is the cheapest place to fix a problem, because everything downstream inherits it.
Step 2 — Generate one hero frame per scene
For each shot, generate a still image first — never go straight to video. Change only the variables that belong to the scene: pose, wardrobe, environment, lighting direction. Keep the identity packet untouched. When a still drifts, you have lost seconds rather than minutes.
Step 3 — Propagate with image-to-video and reference conditioning
Feed the approved still into the video model as the first frame, and attach the reference pack where the tool supports multi-reference conditioning. Keep motion prompts short and physical: what the body does, how the camera moves, what the light does. Do not re-describe the face.
Step 4 — Fine-tune a personal model for recurring casts
If a character appears in dozens of shots, train a small personalization model on the cleaned pack. Use consistent captions, remove duplicates, and hold back a few images to test against. A dedicated model removes most drift at the source and makes downstream shots dramatically more predictable.
Step 5 — Assemble, grade and repair
Edit shots together, apply one unified grade, then inspect for flicker and identity jumps. Repair individual frames with targeted inpainting rather than regenerating whole clips, which resets continuity. Keep the timeline and the reference pack versioned together so you can roll back.
Prompt patterns that keep a face stable across scenes
A stable prompt is modular. Each line carries one block, and only the scene lines change between shots.
Identity: reference set A, blocks 01-06 locked
Wardrobe: charcoal wool coat, as in reference 07
Action: turns from the window and speaks one line to camera
Camera: 50mm equivalent, chest-up, shallow depth of field
Light: soft window key from camera left, warm practical behind
Environment: apartment interior, late afternoon
Finish: fine 35mm grain, neutral grade, no skin smoothing
What to avoid is just as important. Do not rewrite the facial description in every shot. Do not stack contradictory attributes such as soft even light and hard side key in the same prompt. Do not ask for extreme expressions in the same take where identity matters most. And do not change resolution or aspect ratio mid-sequence, because reframing forces the model to reinterpret geometry.
A simple habit helps: separate the prompt into a constant block and a variable block, and copy the constant block without editing it. Most drift in amateur workflows is accidental prompt editing.
Choosing models and settings for photorealism and consistency
Not every video model handles identity the same way. When you evaluate one, score it against these criteria:
- Reference conditioning — how many reference images it accepts, and whether they influence identity or only style.
- Image-to-video strength — whether it preserves a first frame instead of reinventing it.
- Temporal stability — how much the face flickers across a five-second clip.
- Resolution and detail ceiling — whether skin texture survives at your delivery size.
- Fine-tune support — whether you can train a personal character model.
- Motion realism — hands, hair and cloth, which are where photorealism usually fails.
- Commercial licensing and API access — needed for anything client-facing.
For stills, diffusion pipelines with ControlNet-style conditioning and ComfyUI-style node graphs give you the most control over identity blocks. For motion, current generation models from Runway, Kling, Luma, Pika and Google's video models all handle reference conditioning differently, so test the same pack on two or three before committing a project. Upscale late and gently; aggressive enhancement smooths pores and quietly changes the face.
Quality control: catching drift before it costs a day
Build a review pass that takes minutes, not hours.
- Contact sheet — every shot of the character in one grid, in order. Drift becomes obvious at thumbnail size.
- Normalized crops — crop the face to the same pixel box across shots and compare side by side.
- Embedding check — run a face-similarity metric across shots and flag outliers for repair.
- Detail pass — hands, teeth, ears and eyelines, which break before the face does.
- Motion pass — watch at full speed for flicker and lip-sync drift.
- Grade pass — confirm one consistent look across the whole sequence, not per shot.
Log the version of the reference pack and the model settings used for each approved shot. When something breaks three shots later, the log tells you whether the pack changed, the model changed, or the prompt quietly drifted.
Common mistakes and how to fix them
- Too many references. The model averages them into a stranger. Cut to the images that carry distinct blocks.
- Contradictory references. Different ages, weights or lighting extremes fight each other. Keep the pack internally consistent.
- Rewriting the identity description per shot. Freeze the constant block and copy it verbatim.
- Changing resolution or aspect ratio mid-sequence. Reframe by cropping in post instead of re-rendering at a new ratio.
- Over-upscaling. Two aggressive enhancement passes will erase the texture that sells photorealism.
- Switching models mid-sequence without re-anchoring. Re-approve a hero still in the new model before continuing.
- Ignoring wardrobe and height continuity. Identity is partly silhouette, not just the face.
Commercial applications and what changes at scale
In advertising, the Lego Pixel approach turns a single talent shoot into a reusable identity asset: one pack supports multiple scripts, cutdowns, seasonal wardrobe swaps and localized versions without reshooting. In episodic content, it keeps a cast stable while locations and props change around them. In ecommerce and training video, it lets a presenter appear across dozens of products with consistent framing and lighting.
At scale, three things matter more than raw quality: versioning of identity packs, documented approval checkpoints, and clear consent and licensing records for any face you generate. If a character represents a real person, get written permission for the AI use, respect platform disclosure rules, and store the signed record next to the reference pack so every shot is traceable.
FAQ
How many reference images does a character need?
Twelve to thirty sharp, varied images covering angles, two lighting conditions and a couple of expressions. Quality and variety beat volume every time.
Can I use this technique without training a custom model?
Yes. Multi-reference conditioning plus image-to-video propagation handles most short projects. Fine-tuning becomes worthwhile when a character appears in many shots or across multiple episodes.
Why does the face change when the lighting changes?
Because skin is a light-responsive surface. Include a light response block in the pack — one soft-light and one hard-light reference — so the model learns how that face behaves under both.
Does it work for talking-head and dialogue shots?
Yes, and it is where drift is most visible. Generate an approved still per line, keep the camera block constant across the sequence, and repair mouth areas with targeted inpainting only when lip sync fails.
Can the same workflow handle animals or stylized characters?
Yes, with the same logic. Replace facial anchors with coat pattern, ear shape and body proportions, and expect stylized characters to forgive drift more easily than photoreal ones.
What is the fastest way to diagnose drift?
A contact sheet of normalized face crops. If a shot looks off in a thumbnail grid, it will look worse in motion, and you can fix it before rendering the rest of the sequence.
How do I keep quality consistent across a long series?
Freeze three things: the reference pack version, the constant prompt block, and the finish settings for grain and grade. Change one at a time, and re-approve a hero still after every change.
