
What "Lego Pixel" Thinking Actually Means in AI Video
Most people who generate video with AI hit the same wall within a week of experimenting. A single shot looks stunning. Ten shots cut together look like ten different films. The face shifts, the jacket changes color, the lighting resets itself between cuts, and the background architecture quietly rearranges. The problem is not that the models are weak. It is that most prompting treats a scene as one indivisible lump of text, when the underlying image is really a stack of independently controllable parts.
The "Lego pixel" idea is a mental model rather than a specific product feature. It says: stop thinking of a frame as a picture, and start thinking of it as a construction kit. A frame is made of reusable units — a face geometry, a hair silhouette, a fabric pattern, a light direction, a color palette, a camera distance. Each unit can be extracted, stored, swapped, and recombined. When you treat those units as building blocks, style transfer stops being a global filter and image fusion stops being a lucky accident.
This is not a new idea in computer vision. Neural style transfer has separated content from style since the early Gram-matrix experiments. ControlNet separated structure from rendering. Reference-adapter techniques separated identity from pose. What is new is that video generation has matured enough that these separations can be enforced across time, not just within one still image. That is the practical shift worth understanding.
Why Consistency Breaks in the First Place
Before fixing continuity, it helps to name the failure modes precisely, because each one demands a different remedy.
Identity drift. The model regenerates the character from scratch in each shot. Small probabilistic differences in eyes, jawline, and skin tone accumulate. By shot six, the lead looks like a cousin of the lead.
Style bleed. A texture intended for one element leaks into everything. You ask for a knitted sweater and the walls become knitted too.
Palette churn. Global color grading is re-inferred per frame, so shadows move from teal to olive across a cut.
Temporal flicker. Within a single shot, high-frequency detail shimmers because the model has no memory of what it rendered two frames ago.
Geometric instability. Architecture, props, and furniture subtly morph, which the eye reads as a continuity error even when nothing "important" changed.
Modular pixel control addresses all five, but not equally. Identity drift and style bleed respond to reference-based conditioning. Palette churn responds to locked look-up tables and consistent style embeddings. Flicker responds to temporal conditioning and interpolation-friendly frame budgets. Geometric instability responds to structure-preserving controls such as depth, edge, or pose guidance.
The mistake most creators make is treating these as one problem and throwing a longer prompt at it. Prompts describe; they do not constrain. Constraints come from conditioning inputs.
Style Transfer, Reframed as Decomposition and Reassembly
Classic style transfer works by optimizing an image so that its high-level content matches a content image while its low-level statistics match a style image. In video, that framing breaks down, because optimizing every frame independently destroys temporal coherence.
The modular approach reframes the task into three separable decisions.
Separating global content from local style
Content is what must not change: subject placement, pose, silhouette, camera framing. Style is what may change but must change consistently: surface texture, brush character, grain, edge softness, color temperature bias.
In practice you enforce this by feeding the generator separate signals. Structure comes from a depth map, a pose skeleton, or a rough graybox render. Style comes from a reference image or a style embedding. When you separate them this way, changing the style no longer risks changing the staging.
Building a reusable pixel vocabulary
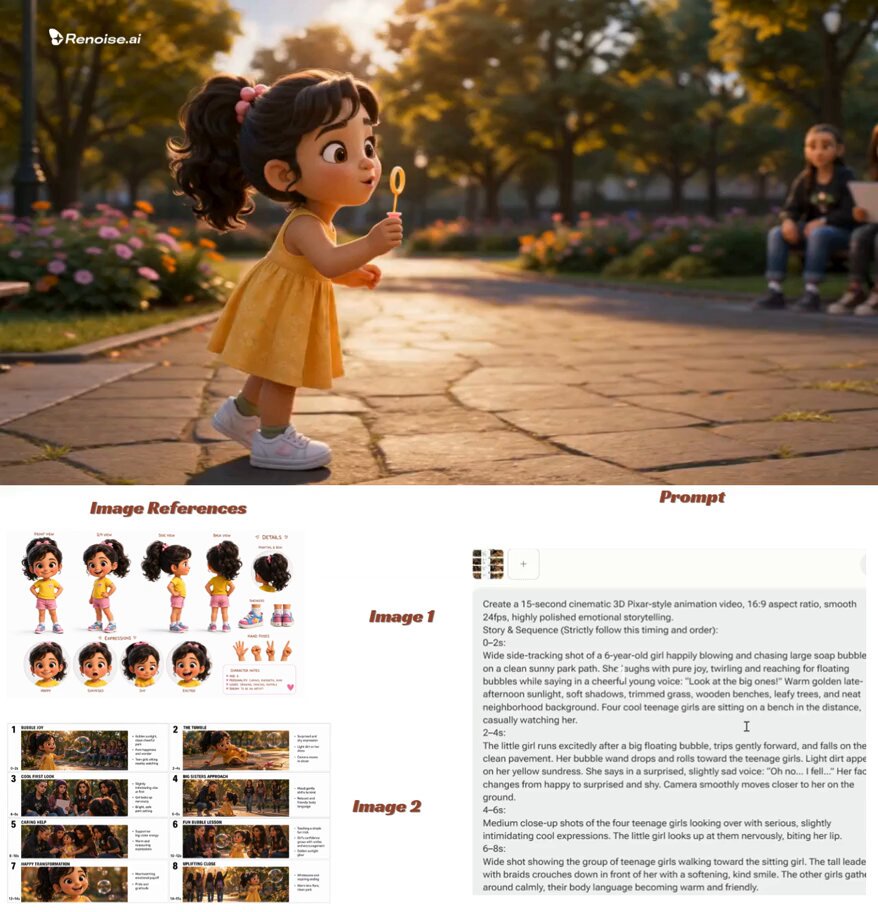
A useful exercise: take a hero frame you love, then crop and label its components into a small library.
face_base.png— neutral expression, front facingface_profile.png— three-quarter turnhair_silhouette.png— shape reference onlywardrobe_fabric.png— texture tilepalette.png— five to seven swatches with hex valueslight_key.png— a reference showing direction and quality of lightenvironment_motif.png— the repeating architectural or natural pattern
This library becomes your style contract. Every new shot references the same library, so the model has less room to improvise. Improvisation is where drift lives.
Choosing where style transfer is worth it
Not every project needs heavy stylization. If you are producing a straightforward product demo, a locked camera and consistent lighting will do more for you than any stylization pipeline. Style transfer earns its complexity when the look itself is the selling point: animation-inspired shorts, painterly brand films, retro game aesthetics, or a distinct visual identity that competitors cannot easily copy.
Decision rule: if a viewer could describe your video using only the word "clean," you probably do not need style transfer. If they would describe it using three or four adjectives about texture and color, you do.
Image Fusion as the Consistency Engine
Image fusion is where continuity is actually manufactured. The idea is simple: instead of letting the model invent a character in every shot, you fuse evidence from previous shots into the current generation.
Keyframe anchoring
Generate or select a canonical frame for each character and location. That frame becomes the anchor. For every subsequent shot, the anchor is injected as a reference, often with a mask that limits its influence to the character region so the background can vary naturally.
Two anchors per character is usually enough: a frontal and a three-quarter. Add a profile anchor only if your shot list includes turns.
Reference stacking
Modern conditioning supports multiple reference images with relative weighting. A practical weighting scheme for a dialogue shot:
| Signal | Relative weight | Purpose |
|---|---|---|
| Face anchor | High | Identity lock |
| Wardrobe reference | Medium-high | Texture continuity |
| Environment anchor | Medium | Location recognition |
| Style reference | Medium | Global look |
| Pose or depth map | High | Staging accuracy |
If total conditioning pressure is too strong, motion becomes stiff and the output looks like a slideshow. If it is too weak, drift returns. Tune weights in small increments and always evaluate on a moving subject, not a still.
Handling motion and deformation
References describe appearance, not deformation. A face anchor does not tell the model how a cheek compresses during a laugh. This is why pure reference stacking produces slightly rubbery performances.
Three practical remedies:
- Motion references. Add a short video clip of similar motion as a temporal conditioning signal, not just a still.
- Pose sequences. Drive the shot with a pose track so the model inherits realistic articulation while the reference supplies likeness.
- Short bursts. Generate three to five second bursts and edit them together rather than requesting long continuous takes. Shorter windows accumulate less drift.
Fusion in latent space versus pixel space
Fusing at the pixel level gives you maximum control and maximum artifacts. Fusing in latent space produces smoother blends but gives you less precise control over edges. A hybrid workflow is usually best: composite hard-edged elements such as logos, UI overlays, or text at the pixel level, and let everything organic blend in latent space.
A Practical Step-by-Step Workflow
This is a workflow that works for both short-form social pieces and longer narrative sequences. It assumes you have access to a diffusion-based image generator, a video generator with reference conditioning, and a standard editing suite.
Step 1: Write the look before you write the prompts
Produce a one-page style sheet. Include: three adjectives for texture, a five-color palette with hex codes, one sentence describing the light, and one sentence describing what the camera is allowed to do. Everything downstream is graded against this sheet.
Step 2: Build the reference board
Generate twenty to forty stills quickly and cheaply. Do not aim for perfection. Aim for a range. Then select the strongest ten and crop them into the component library described earlier.
Step 3: Lock identity anchors
Pick the two best character frames. Clean them: remove stray background elements, fix asymmetry, normalize white balance. Anchors should be boring and correct, not dramatic. A dramatic anchor drags its drama into every shot.
Step 4: Generate short test bursts
Before committing to a full sequence, generate five separate three-second clips of the same character in different framing. Play them back to back with no sound. If the identity holds across all five, your conditioning is calibrated. If it wobbles, fix it now — not after you have generated forty shots.
Step 5: Fuse and re-inject style
Process your approved takes through a fusion and re-stylization pass. Apply style uniformly across the whole sequence at once, not shot by shot. Uniform application is what prevents the palette from drifting between cuts.
Step 6: Stabilize and interpolate
Run temporal smoothing or frame interpolation carefully. Over-aggressive interpolation smears fine texture and can undo the crisp modular look you worked for. Use the lowest strength that removes visible judder.
Step 7: Grade as a sequence, not as clips
Import everything into your editor and apply one master grade across the timeline. Shot-by-shot grading is the single most common cause of the "ten different films" feeling.
Step 8: QA against the style sheet
Watch the sequence once with sound off, once at 2x speed, and once with your eyes half-closed. The half-closed pass catches palette jumps. The 2x pass catches rhythm problems. The silent pass catches whether the visuals carry the story alone.
Choosing the Right Toolchain for Modular Control
Tool choice matters less than pipeline discipline, but there are real differences worth weighing.
Node-based composition environments give you the most explicit control over conditioning graphs. They are the right choice if you want reproducibility, reusable templates, and the ability to inspect every step. The cost is a steeper learning curve.
Single-purpose web video generators are faster to start and often handle reference conditioning gracefully. They are the right choice for marketing teams producing a handful of clips per week. The cost is less transparency about how references are weighted.
Local image diffusion setups are the best place to build your component library, because cropping, inpainting, and controlled variation are easier and cheaper at the still level.
Traditional editing and compositing suites remain essential. Fusion pipelines produce plates; editors produce films.
Criteria to evaluate against, in priority order:
- Can it accept multiple references with independent weights?
- Does it support structural conditioning such as depth or pose?
- Can you reproduce a previous result exactly from saved parameters?
- How long does a three-second test burst take?
- Does it let you composite at the pixel level for hard-edged elements?
If a tool fails the first or third criterion, it will not support serious modular workflows no matter how good its demo reel is.
Prompting Patterns That Support Modular Control
Prompts describe; conditioning constrains. Still, prompt structure affects how obediently a model uses your conditioning.
Front-load invariants. Put the fixed identity and style descriptors at the very start, before anything about the action. Models weight early tokens more heavily.
Separate the sentence layers. One sentence for identity, one for wardrobe, one for action, one for camera, one for light. This makes it trivial to swap the action while keeping everything else frozen.
Avoid contradictory texture words. "Smooth knitted matte silk" gives the model no coherent target. Pick one surface language per element.
Name the camera move explicitly. "Slow push in, 35mm equivalent" outperforms "cinematic camera work," which is a mood, not an instruction.
Use negative prompts for drift, not for taste. Negatives work best on structural defects: extra fingers, warped text, duplicated limbs, melted edges. Using negatives to express aesthetic preference rarely helps.
Common Mistakes and How to Avoid Them
Over-conditioning. Stacking too many references produces stiff, lifeless motion. If a character moves like a mannequin, reduce conditioning weight before you rewrite prompts.
Reusing a stylized frame as an identity anchor. Style and identity are different signals. Pull your anchors from clean, neutrally lit renders, then apply style afterwards.
Generating long takes. Long generations accumulate drift and limit your editing options. Generate short and cut.
Ignoring audio-visual timing. If dialogue or music drives the edit, generate to the beat map rather than cutting to fit the generated footage.
Skipping the reference board. Creators who skip straight to generation end up doing the reference work anyway, just with more wasted generations.
Treating one good shot as proof. A single impressive shot proves the model works. Five consecutive consistent shots prove your pipeline works.
Frequently Asked Questions
Do I need a local GPU setup to do this?
No, but it helps. Local still-image generation makes building the component library dramatically cheaper. The video generation itself can be handled by hosted services.
How many reference images is too many?
For most models, three to five total references with tuned weights outperform ten references with equal weight. Prioritize identity and structure, then style.
Can I apply this to existing footage rather than generating from scratch?
Yes. Shoot live action, extract depth and pose, then use fusion to restyle while preserving the original performance. This is often the fastest route to a stylized look with believable acting.
What is the minimum viable sequence length to test a pipeline?
Five shots of three seconds each, featuring the same character in different framing. If identity and palette hold, scale up.
How do I keep text and logos from melting?
Generate the plate without text, then composite typography in your editor at the pixel level. Text generation should be treated as a separate discipline.
Is a consistent look more valuable than a striking single frame?
For anything longer than a few seconds, yes. Audiences forgive ordinary frames far more readily than they forgive an inconsistent character.
Where to Take This Next
The modular mindset scales in three directions. Horizontally, you can expand your component library into a shared studio asset — brand palettes, recurring characters, signature lighting setups — so every new project starts from a known baseline rather than a blank prompt. Vertically, you can push into longer formats, where continuity discipline pays off more with every additional minute. Technically, you can automate the boring parts: scripted reference injection, batch fusion passes, and automated QA checks that flag palette outliers before a human ever watches the cut.
Start small. Build one character, two anchors, five shots. Get those five shots to feel like one continuous world. That single exercise teaches more about style transfer and image fusion than any amount of reading, because the lesson is not really about models. It is about deciding, in advance, which parts of your image are allowed to change — and which parts are not.
