
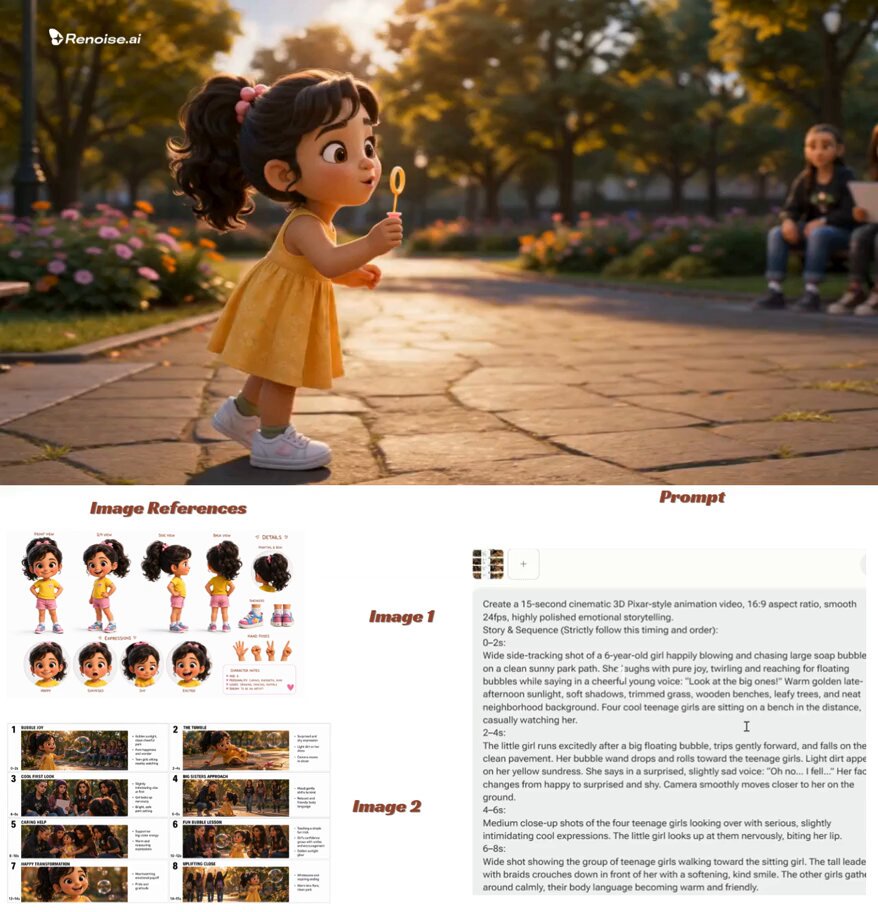
Ask anyone who has tried to build a short film with generative video tools what the hardest part is, and the answer is rarely motion quality. It is identity. A character looks convincing in the first shot, the jaw is slightly wider in the second, the hair changes length by the fifth, and somewhere around the ninth shot the audience quietly stops believing the story. Multi-image fusion exists to close that gap. Instead of describing a person in words and hoping the model remembers, you hand it several still images of the same character and let it blend them into one stable visual identity that survives camera moves, lighting shifts, and scene changes.
The core insight is simple: one reference image is a guess, several reference images are a constraint. Generative models resolve ambiguity by inventing detail. Show a model a single three-quarter portrait and it has no idea what the character looks like from behind, so it improvises, and the improvisation becomes the new truth two shots later. Show it a front view, a profile, a back view, and two expression plates, and most of that ambiguity disappears. The model no longer needs to invent a face. It needs to reproduce one.
Fusion also solves a second, less obvious problem: style continuity. A character who is perfectly consistent but lit differently in every shot still reads as inconsistent to an audience. By pairing character plates with environment and lighting references, you give the model a complete visual contract instead of a partial one.
The Reference Stack: What Each Image Is Doing
The phrase reference stack is deliberate. References are not a folder of nice pictures; they are a layered system where each image answers a different question the model would otherwise answer badly. A practical stack usually has four layers.
Identity anchors
These are close, sharp, evenly lit images of the face: front, three-quarter left, three-quarter right, and one profile. Resolution matters more than count. Four clean images at 1024 pixels or higher will outperform twelve soft screenshots taken from a phone. Keep expressions neutral in the anchors so the model learns bone structure rather than a mood. If a character has distinctive features such as a scar, freckles, a gap in the teeth, or strong brow shape, at least one anchor should show them clearly and without heavy shadow.
Wardrobe and silhouette plates
Full-body images tell the model how the character occupies space: shoulder width, posture, hair length relative to the torso, how the coat falls. This layer is what prevents the classic failure where a face stays perfect but the body quietly changes build between shots. Include one front-facing full body and one side-facing full body in the main costume of the scene.
Expression and pose plates
If the script calls for laughter, anger, or exhaustion, supply those expressions up front rather than asking the text prompt to invent them. Expression plates reduce the intensity of the drift that happens whenever a model is asked to generate an emotion it has never seen the character perform. Do not overload this layer. Two or three expressions per episode is usually enough.
Scene and lighting plates
Finally, give the model environment references: a wide shot of the location, a colour reference for the light, and any prop the character interacts with. These plates do not describe who the character is, but they anchor how the character is rendered, which is what makes cut-to-cut transitions feel like one continuous world.
How the Model Blends Your References Behind the Scenes
You do not need to understand the architecture to get good results, but a rough mental model helps you debug. Every reference image is converted into a numeric representation, an embedding, that captures appearance rather than pixels. The text prompt becomes another embedding. During generation, the model attends to all of them at once and tries to satisfy the whole set.
Embeddings, attention, and the token budget
Each reference consumes part of a limited attention budget. Add more images and each one gets a smaller share of influence. That is why twenty mediocre references produce worse results than five excellent ones. It is also why the ordering of images can matter: many pipelines give a higher weight to the first references in the list. Put your strongest identity anchor first, then the supporting angles, then wardrobe, then environment.
Weight, order, and conflicts
When references disagree, the model does not stop and ask. It averages, and averaging is what produces the uncanny middle faces that look like nobody. Common conflicts include two different hairstyles in the same stack, mismatched skin tones caused by different white balance, and wardrobe from two different scenes. Audit your stack for contradictions before you blame the tool.
Reference strength versus prompt strength
Most image-to-video and reference-conditioned pipelines expose some way to trade off between fidelity to the reference and freedom to follow the prompt. High fidelity keeps identity but can freeze motion and produce stiff acting. Moderate fidelity gives livelier motion with slightly softer likeness. Lock identity in the keyframe stage at high fidelity, then relax the setting slightly for the motion stage, and you get both.
Building a Character Bible Before You Generate a Single Frame
A character bible is the cheapest insurance policy in AI video production. It is a short document plus a folder, and it prevents most continuity disasters before rendering costs anything.
What to record
Write one page per character and keep it factual. Include exact eye colour, hair colour and length in centimetres, height relative to other characters, age range, build, notable marks, and the default costume for each scene. Then add the fixed description string you will paste into every prompt. Consistency comes from repetition of identical words, not from elegant variation. If you call the character a woman in a charcoal wool coat once and a lady in a dark jacket the next time, you have created two characters.
Freezing the look
Once the anchors are approved, treat them as locked assets. Name files predictably, for example char-camila-anchor-front-01, and store them beside the approved keyframes. When a shot drifts, you can compare it against the locked reference and immediately see whether the problem is the reference stack or the motion prompt.
A Practical Workflow: From Script to Locked Sequence
The following sequence works for a thirty-second vertical clip and scales to a multi-minute narrative.
Step one: break the script into shots
Number every shot and note camera angle, framing size, action, and emotional beat. Group shots that share a location so you render them in batches. Batching matters because lighting and wardrobe drift usually appear at the boundary between batches, not inside them.
Step two: generate keyframes with fused references
For each shot, produce a still image first using the character stack plus the scene plate. Review stills in a contact sheet rather than one by one. Continuity problems are far easier to spot when the images sit next to each other.
Step three: animate from the approved keyframe
Feed the locked keyframe into an image-to-video model and describe motion only: what the camera does, what the character does, and how long the shot lasts. Do not re-describe the character in the motion prompt beyond a short identity reminder. Over-describing at this stage invites the model to redraw the face.
Step four: quality gate
Score every clip against four criteria: likeness, wardrobe match, lighting match, and motion naturalness. Anything below your threshold gets re-rendered with one variable changed at a time. Changing three settings at once teaches you nothing.
Step five: assemble and match
Bring clips into an editor, apply a single colour treatment across the sequence, and check the cut points. A shared grade hides small lighting mismatches and makes the sequence read as a single shoot.
Choosing the Right Tool for the Shot
No single model wins at everything. Build a small comparison of the tools you have access to and score them on the dimensions that matter to you.
| Criterion | Why it matters | What to test |
|---|---|---|
| Identity retention | Determines whether the face survives motion | Same anchor, three different motions |
| Reference support | Sets how many plates you can supply | Does quality hold at four or five images? |
| Motion realism | Affects whether acting feels alive | Walking, turning, subtle head movement |
| Prompt adherence | Controls how well you direct the shot | Exact camera move and timing requests |
| Duration per generation | Fewer cuts, more continuity | Longest usable clip before drift |
| Latency and spend | Shapes how many iterations you can afford | Time and cost per approved second |
Practical guidance from working pipelines: use a strong still-image model with character reference support for keyframes, then a video model with solid image conditioning for animation. Keep one specialist model in reserve for close-up dialogue shots where likeness is most visible, and a cheaper, faster model for wide shots where the face occupies few pixels. If a character reappears across many episodes, consider training a small identity adapter on twenty to forty curated images; it costs setup time but pays back quickly on long series.
Prompt Templates That Hold a Character Together
Keep two separate prompts: one for the still, one for the motion. The still prompt carries appearance; the motion prompt carries action.
Still keyframe prompt structure:
- Fixed identity string, copied verbatim every time.
- Wardrobe string, also copied verbatim.
- Scene and lighting string.
- Framing and lens language: medium close-up, 50mm look, shallow depth of field.
- Expression and action beat.
Motion prompt structure:
- Camera instruction: slow push in, static tripod, gentle handheld follow.
- Character action in plain verbs: she turns her head, he lifts the cup.
- Pace and duration.
- Negative list, kept short: no facial morphing, no extra fingers, no text overlays, no costume change.
Two habits separate clean sequences from messy ones. First, never paraphrase your identity string; copy and paste it. Second, keep negatives minimal. Long negative lists often introduce the very artefacts they are trying to prevent, because the model still processes the concepts.
Troubleshooting: Drift, Identity Bleed, and Costume Swaps
| Symptom | Likely cause | Fix |
|---|---|---|
| Face changes across a cut | Conflicting anchors or soft references | Replace with four sharp, consistent plates |
| Body proportions shift | No full-body reference | Add front and side full-body plates |
| Two characters look alike | Overlapping costumes and similar features | Differentiate colour, build, and hair silhouette |
| Wardrobe swaps mid-shot | Costume described differently in prompt | Freeze one wardrobe string per scene |
| Motion looks frozen | Reference fidelity too high | Lower fidelity slightly, raise motion strength |
| Flickering textures | Interpolation mismatch on stitch | Re-render at consistent frame rate, avoid mixed sources |
| Wide shots lose likeness | Face too small to influence generation | Use a closer framing or a dedicated wide-shot model |
| Hair changes length | Hair described inconsistently or cropped oddly | State hair length in the fixed string and show it in a plate |
When a shot fails repeatedly, stop iterating on the prompt. Rebuild the reference stack instead. Most stubborn identity problems live in the references, not in the wording.
Consistency Across Episodes, Teams, and Long Projects
Individual shots are manageable. Series are where discipline pays off. Treat your reference assets like source code: version them, review changes, and never overwrite an approved stack. Keep a changelog that records which stack version produced which finished clip, so you can trace a continuity complaint back to its source.
Standardise your review checklist so different editors judge likeness the same way. A short list works: does the face match at this framing, does the costume match, does the light match, does the motion feel natural? Anyone can run it in under a minute.
Finally, plan for character ageing, costume changes, and new locations as deliberate version bumps rather than accidents. When a story jumps forward a year, create a new stack with the same identity anchors plus updated wardrobe plates and label it clearly. That way the older episodes remain reproducible, and the new look is intentional rather than the result of drift nobody noticed.
FAQ
How many reference images should I use?
Four to six well-chosen plates cover most needs: three face anchors, one or two full-body shots, and one expression plate. More images dilute attention rather than adding information, so only add a plate when it answers a question the current stack cannot.
Do I need a full-body reference if my video is all close-ups?
Yes, if the character ever stands, walks, or appears in a wider framing. Even in close-ups, body references help the model understand neck length, shoulder line, and hair volume, all of which affect likeness at the edge of the frame.
Why does my character look right in stills but wrong in motion?
Motion models reinterpret the frame as they animate. Reduce the amount of appearance description in the motion prompt, keep the identity string short, and hold the keyframe fidelity reasonably high so the model has less room to reinterpret.
Can I mix references from different sources, like photos and generated images?
You can, but match white balance, sharpness, and framing first. A single soft, warm-lit photo mixed with crisp neutral renders will pull the average skin tone and contrast somewhere you did not intend.
How do I keep two characters from blending into each other?
Give them opposite visual anchors. Different hair silhouettes, different palette families, and different body builds. If they must wear similar uniforms, vary the small details and keep them apart in frame whenever the shot allows it.
Is training a custom identity adapter worth it?
For a one-off clip, no. For a recurring character across many episodes, yes. A small adapter trained on curated images tends to hold identity more reliably than prompt-only approaches, and it reduces the number of plates you need per generation.
What is the fastest way to diagnose drift?
Generate the same shot twice with two different anchor sets and compare. If the drift persists, the problem is in the motion stage. If it disappears, the problem was the reference stack, and you have your answer in two renders instead of twenty.
