
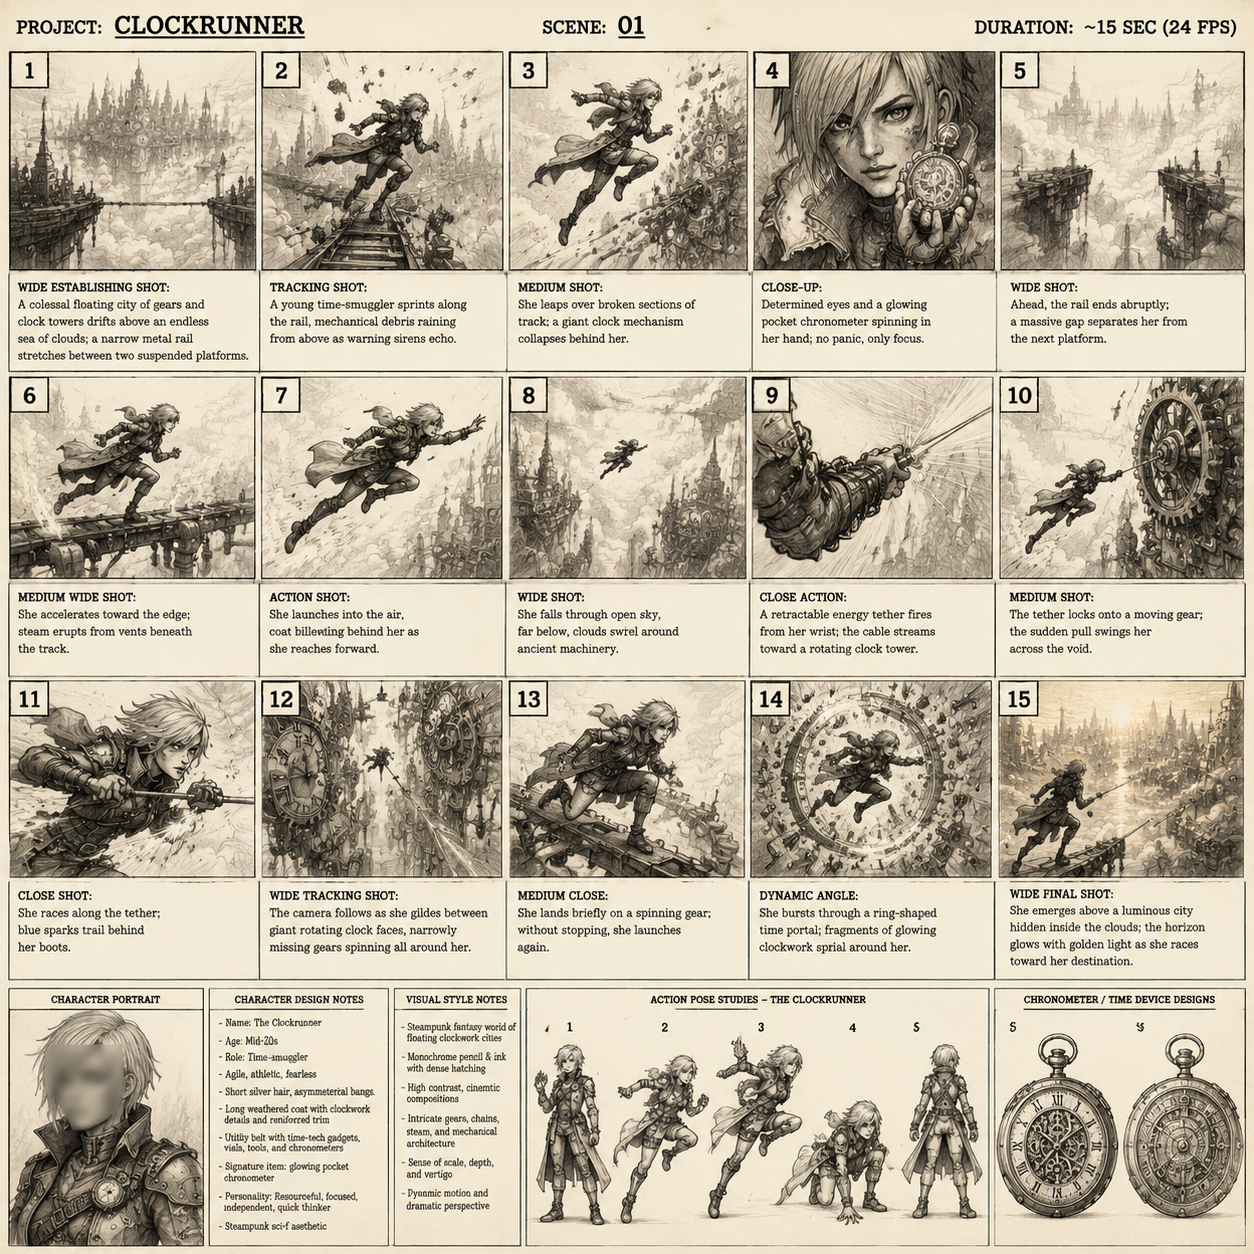
Why single-image generation usually breaks a story
Ask anyone who has tried to build a short film with early text-to-video tools what went wrong, and you will hear the same complaint. The first shot looks great. The second shot looks like a different movie. The character's jacket changes color, the jawline shifts, the lighting direction flips, and the camera seems to have teleported to another location. Nothing is technically broken, yet the sequence does not read as a story.
That failure is a consistency problem, not a rendering problem. Diffusion models are excellent at inventing a plausible frame from noise. They are far worse at remembering what they invented ninety seconds ago. When you generate each shot independently, every frame re-rolls the dice on faces, wardrobe, color grade, and spatial layout. The result is a collection of attractive stills stitched together, not a film.
Multi-image fusion is the practical answer. Instead of asking a model to invent everything from a paragraph of text, you hand it a small set of reference images that define what must stay true, and let it generate motion, framing, and expression around those anchors. The reference set acts like a visual contract: this face, this palette, this set, this costume. The model fills in what changes.
This article is a working guide to that approach. It covers how image-sequence fusion actually behaves, how to build a reference set that survives motion, how to direct camera work without fighting the model, and where the workflow tends to break. It is written for people who want repeatable output rather than one lucky clip.
What multi-image fusion actually does under the hood
The phrase sounds like marketing, but the mechanism is fairly concrete and worth understanding before you plan a shoot.
A conventional image-conditioned video model takes one still and a text prompt and predicts the next frames. It has a single visual anchor. Multi-image fusion extends that idea in three directions at once.
First, it accepts several references in a single conditioning pass rather than one. The model does not treat them as a slideshow to interpolate. It extracts identity features, palette information, and structural cues from each, then blends them into a shared conditioning space. A portrait contributes facial geometry. A wide shot contributes environment and lighting. A color swatch or graded still contributes the look.
Second, it decouples the elements that must remain stable from the elements that are allowed to change. Identity, wardrobe, and set design are treated as constraints. Pose, expression, camera movement, and micro-motion are treated as free variables. This separation is what lets you push a character through a range of actions without their face drifting.
Third, it maintains that conditioning across multiple shots when you generate a sequence rather than a clip. The reference set persists between generations, so shot two inherits the same identity tokens as shot one. This is the difference between a series of related clips and an actual continuous scene.
The practical consequence is that your job changes. You stop writing longer and longer text prompts hoping to describe the exact face you want. You start assembling a small, well-chosen library of images that show the model what is fixed, and then you describe only what moves.
The reference set is the script: how to build one that survives motion
Most fusion failures trace back to a bad reference set, not a weak model. The set is doing the heavy lifting, so it deserves the most care in the whole pipeline.
A reliable reference set for a character-driven sequence usually has four to six images with distinct jobs:
- A clean, front-facing portrait with neutral lighting. This carries identity. Avoid extreme expressions, heavy shadow, or dramatic angles here.
- A three-quarter or profile view of the same subject. This teaches the model that the face exists in three dimensions, which dramatically reduces profile drift when the camera turns.
- A full-body or wardrobe shot showing silhouette and costume details. Boots, coats, and accessories are the most common drift points, and text prompts rarely pin them down.
- A location plate with no characters in it. Empty sets give the model uncontaminated information about geometry and light direction.
- One or two graded stills that establish the color direction, such as a teal-shadow noir look or a warm daylight look.
- Optionally, a prop close-up if a specific object matters to the plot.
Three rules govern how those images should behave together.
Keep the lighting consistent across the set. If your portrait is lit from the left and your location plate is lit from the right, the model receives contradictory information and will average it into something mushy. Match a single imagined sun.
Keep the resolution and aspect ratio consistent. Mixing a square crop with an ultrawide frame forces the model to reconcile geometry that does not belong together, and you will see artifacts at the edges of the frame.
Keep the number small. More references is not more control. Past roughly eight images, additional inputs tend to dilute the conditioning rather than sharpen it, and identity tokens start competing. Six well-chosen images beat twenty random ones every time.
If you do not have any of these images, generate them first as stills. Locking identity in a still image is far cheaper and faster than discovering after a long render that a face does not hold.
Planning the sequence before you generate a single frame
Fusion rewards planning and punishes improvisation. Before generating, write a shot plan. It does not need to be elaborate, but it should force four decisions for every shot.
State the shot purpose in one sentence. "Establish the workshop at dawn" and "reveal the character's reaction to the letter" demand completely different camera and lighting choices. A shot that exists only to look pretty is usually a shot you can cut.
Specify the camera movement explicitly. Push in, pull out, truck left, tilt up, orbit, or hold. Vague words like "dynamic" produce unpredictable motion that cannot be fixed inedit. If the model supports it, name the movement; if not, describe camera behavior in plain physical terms.
Name only what changes from the previous shot. If the set, wardrobe, and character are already pinned by the reference set, your per-shot prompt should mostly describe action, emotion, and camera. Re-describing the character's face in every shot wastes prompt budget and can actually push the model away from the reference.
Set a shot length target. Short shots, two to four seconds, hide motion artifacts and cut faster. Long shots demand smoother motion and more compute. A sequence of six two-second shots will usually feel more cinematic than two six-second shots, and it will be cheaper to iterate.
A shot plan for a thirty-second piece might look like this:
- Establish, wide, slow push in, three seconds, empty set plate plus character entering frame.
- Medium, character at work, gentle truck left, two seconds, identity clearly readable.
- Close-up, hands and prop detail, static, two seconds, tests whether small objects hold.
- Reaction, close on face, slight tilt up, three seconds, the highest-drift shot, generate first as a test.
- Wide, environment change, hold, three seconds, new location plate.
- Final beat, medium wide, slow pull out, four seconds, returns to the opening framing for symmetry.
Note what this plan does: it front-loads the riskiest shot. Close-ups on faces and hands are where consistency breaks first. Generate them early, while changes are cheap, rather than discovering the problem after everything else is done.
Keeping characters consistent when the camera moves
Camera movement is the single most common trigger for identity drift, because rotation and translation expose parts of a subject the model never saw in the reference set.
Three techniques solve most of this.
Add angular coverage to the reference set. If a shot orbits from front to profile, your reference set needs at least a three-quarter view, ideally a profile as well. Models cannot invent a convincing ear, jaw profile, or hair fall from a single frontal image.
Move the camera on the axis the reference supports. A slow push in from the front is nearly always safe. A ninety-degree orbit from a frontal-only reference set reliably produces a face that melts around the cheekbone. If you need the orbit, supply the missing angles first.
Reduce motion complexity per shot. Combining a large camera move with a large character action, such as a spin kick during a whip pan, produces the highest failure rate of any configuration. Split it into two shots. The cut will read as intentional editing rather than as a compromise.
For dialogue or performance shots, generate several takes at different lengths and pick the best. Varying the seed while keeping the reference set and prompt fixed gives you a cheap way to search the model's output space, and the difference between two takes of the same prompt is often substantial.
Directing camera work with an intelligent scene layer
Text prompts are a poor interface for camera language. Words like "cinematic" or "dramatic angle" are artistically meaningless to a model trained on literal descriptions. What works far better is a directing layer that translates intent into concrete proposals you can accept, reject, or modify.
A useful assistant in this mode behaves in a specific way. You describe a scene in plain language, and it proposes a small set of shot options with explicit camera behavior. Something like: a low-angle wide establishing the space with a slow push in, or a handheld medium tracking behind the character with a slight tilt. Each option names an angle, a movement, and an approximate duration. You pick one, and the system converts that choice into the technical parameters the video model needs.
This is valuable for two reasons. It keeps you out of the business of guessing which magic words produce a dolly move, and it enforces consistency of grammar across your shots. If every shot in your sequence is described in the same vocabulary of angle, movement, and duration, the final edit cuts together cleanly.
The practical workflow looks like this:
- Write the scene in plain prose, including emotional intent and what the audience should notice.
- Ask for three to five shot proposals covering the beat, ideally with variation in scale and pacing.
- Select and reorder the proposals into a shot list.
- Translate each shot into a generation request using the reference set plus the named camera behavior.
- Render the risky shots first, verify consistency, then render the rest.
The reason step two asks for several options is that scene composition is where human judgment matters most. Models can propose a competent shot quickly, but choosing between a low angle and an eye-level medium is a storytelling decision that depends on how the sequence should feel. Keep that decision.
Deepening narrative with character consistency
Consistency is not only a technical achievement. It is a narrative resource, and treating it that way changes how you edit.
When a face holds across shots, you can cut on emotion rather than on continuity. A close-up reaction can land directly on the next line because the audience already knows who is reacting. When identity drifts, editors instinctively compensate by adding wider shots, cutting away to scenery, and shortening close-ups, which flattens the emotional arc.
Consistency also enables techniques that are impossible otherwise. Recurring visual motifs, such as the same character in the same doorway at the beginning and end of a piece, only read as deliberate if the wardrobe and face match. A callback shot that looks like a different person reads as an error, not a rhyme.
Practically, this means you should reserve your best reference sets for the shots that carry the story. Background characters and one-off extras do not need six-image sets. Spend the effort where the audience will be looking.
It also means you should generate emotionally important shots in multiple variants and choose deliberately. If the story hinges on a hesitation, a glance, or a small gesture, treat that shot as a casting decision rather than a render job.
Where image-sequence fusion still struggles
Honest limits, stated plainly, save more time than optimistic feature lists.
Hands remain the weakest point. Fine finger articulation across fast motion still breaks. Keep hand-heavy action short, partially occluded, or slightly out of focus if the shot does not need the detail.
Text in frame is unreliable. Signs, books, and screens rarely render with correct lettering across a moving shot. Avoid plot-critical on-screen text, or add it in post.
Fast, complex cloth and hair simulation can produce flicker. Long hair in wind and flowing garments are beautiful when they work and distracting when they stutter. Shorter shots hide this well.
Extreme scale changes between consecutive shots, such as a wide landscape cutting to an extreme macro, can cause the model to lose environmental anchoring. Bridge with a medium shot when you need both.
Long continuous takes, beyond roughly eight to ten seconds, start to accumulate drift even with good references. Plan cuts. Cuts are not a failure of the technique; they are how film has always managed exactly this problem.
Mirrors and reflections are close to unsolvable at present for character work, because the model must reproduce identity under a flip that is not well represented in the reference set. Storyboard around them.
A practical end-to-end workflow
Here is the whole process in the order it should be executed.
Define the piece. Decide duration, number of shots, aspect ratio, and the one visual idea the audience should remember. Ten to twelve shots for a thirty-second video is a comfortable density.
Build the reference library. Generate or collect four to six images per principal character or location. Enforce consistent lighting, resolution, and aspect ratio.
Lock identity in stills. Before any video, verify that the reference set reads as the same person from every supplied angle. If two images look like different people, the video will too.
Write the shot plan. One purpose, one camera behavior, one duration, and one line of change per shot. Front-load close-ups and hand shots as tests.
Generate risky shots first. Render a short version of each problem shot, inspect for drift, and adjust the reference set rather than the prompt when identity slips.
Fill in the safe shots. Reshoot stable wide and medium shots in batches once the reference set is proven.
Assemble and cut. Trim aggressively. Shortening a shot is the fastest fix for motion artifacts, and a hard cut is often better than a lingering frame.
Review against a checklist. Same face, same wardrobe, same light direction, no flickering text, no mirrored inconsistencies, and no orphan shots that break the visual grammar.
Grade in post. A unified color pass hides small inconsistencies in exposure and white balance between shots that were generated separately. This is the single highest-return post step.
Choosing the right tool for each stage
Different tools win at different stages, and mixing them is normal. A workable split looks like this.
For reference stills, a strong image model with good inpainting and identity support is the right choice. You need tight control over faces and wardrobe, and you need to fix small details without regenerating an entire image.
For motion, prioritize models that accept multiple image inputs and support explicit camera controls. A single-image model with excellent motion still loses on consistency, and consistency is what the whole sequence depends on.
For assembly, any competent editor works. Look for frame-accurate trimming, simple speed ramps, and a color workspace. Fancy effects are not the bottleneck.
For dialogue or narration, generate audio separately. Do not expect visual models to nail lip sync on stylized faces. Record or synthesize voice first, cut the visuals to it, and the piece will feel more controlled.
Whatever you choose, keep the reference set portable. Storing your images, prompts, and shot plans in a plain folder means you can move the project to a different model when a better one appears, which happens regularly.
Building a reusable visual bible
Once you have completed a piece, resist deleting the reference set. It is the beginning of a visual bible, and it is the most valuable asset you will produce.
A useful bible contains the character and location references, the shot plan, the prompts that produced good results, seed values for successful takes, and notes on what failed. Over three or four projects in the same style, you accumulate a library that makes each new piece faster.
This compounds. A location plate reused across six pieces gives your body of work a coherent identity. A wardrobe set reused for a recurring character means a callback shot in a later piece works on the first try. Individually these savings are small; across a channel or a campaign they are substantial.
Tagging matters more than folder structure. A flat folder with consistent filenames such as character-name-front-neutral or location-workshop-dawn-wide will serve you better than a deep tree you forget the shape of.
Common mistakes and how to avoid them
Reaching for a longer prompt. When identity drifts, the instinct is to describe the face in more detail. This almost never works. Fix the reference set instead.
Using one reference for everything. A single frontal portrait cannot support a profile shot. Coverage matters.
Mixing art styles in the reference set. A photoreal portrait next to a stylized illustration creates an ambiguous target, and the model will produce something in between.
Overloading a shot with action and camera movement. Split it. Two simple shots cut together beat one complicated shot that almost works.
Ignoring light direction. Inconsistent lighting across references is the quiet cause of a lot of muddy output.
Skipping the test render. Rendering a full sequence before checking the hardest shot wastes the most time of any mistake on this list.
Refusing to cut. Perfectionism at the shot level damages the piece at the sequence level. Cut on motion, cut early, and let editing do the work.
Frequently asked questions
How many reference images should a character use?
Four to six is the useful range for most work. One frontal portrait for identity, one three-quarter or profile for angular coverage, one full body for wardrobe, and one or two graded stills for the look. More than eight usually dilutes conditioning.
Can I mix characters in one shot?
Yes, if each character has their own small reference set and the shot prompt clearly separates their actions. Keep interactions simple. Two characters exchanging positions during a camera move is a known failure case; split it into cuts.
Do I need the same aspect ratio across all references?
Yes, or as close as you can get. Mismatched framing forces the model to reconcile geometry that does not belong together, and the artifacts usually appear at the edges of the frame.
How long can a generated shot be before consistency decays?
With a solid reference set, roughly six to eight seconds is comfortable. Beyond that, drift accumulates and small details start to wander. Plan cuts rather than pushing length.
What should I do when a face changes mid-shot?
Stop and fix the reference set, not the prompt. Add the angle you are missing, check that lighting is consistent, and regenerate. Prompt tweaks rarely solve identity drift.
Is post-processing a band-aid or a legitimate step?
Legitimate. Real productions grade, stabilize, and retouch. A unified color pass and aggressive trimming fix exposure mismatch and motion artifacts that would be expensive to solve at generation time.
Do I need a different reference set for a night scene?
You need graded references that show your intended color direction, yes. Keep the identity images the same, but substitute outdoor location plates for night equivalents so the model does not fight between daylight references and a night prompt.
Final thoughts
Multi-image fusion turns video generation from a lottery into a production process. The model stops guessing who your character is, and you stop writing paragraphs trying to describe a face. What remains is craft: choosing the right references, planning shots that respect the model's limits, and cutting with discipline.
The workflow is not complicated, but it is unforgiving of shortcuts. Build a small, lit-consistently reference set. Test your hardest shot first. Keep camera moves simple enough that identity survives them. Plan cuts instead of chasing long takes. Grade and trim at the end.
Do those things and the output stops looking like a collection of generated clips and starts looking like a film, which is the entire point of the technique.
