
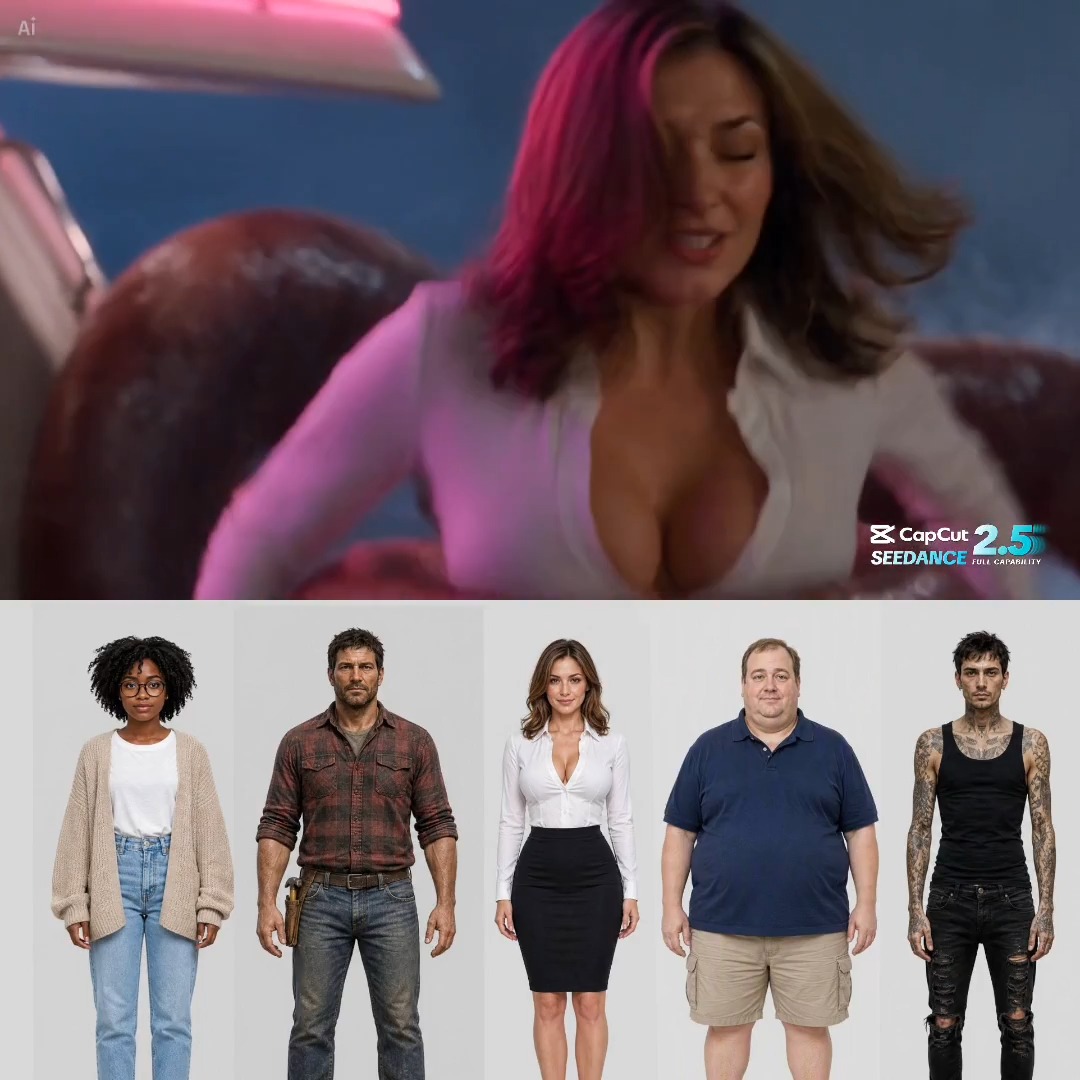
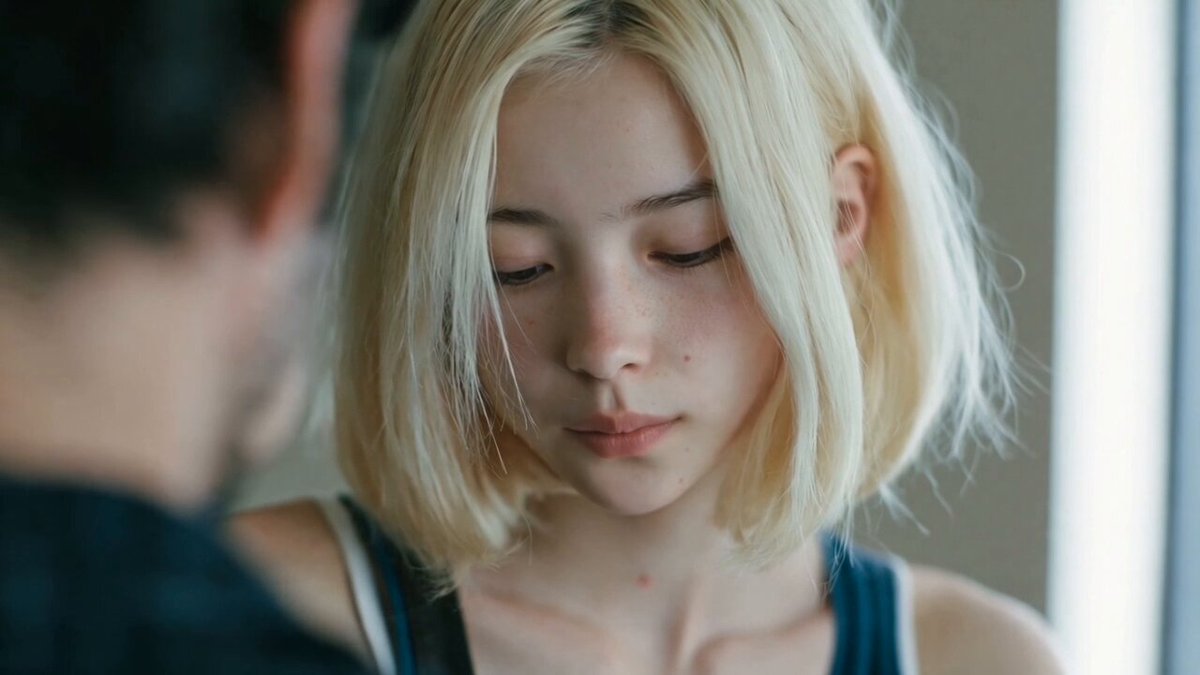
What "Photorealistic" Really Means in Generated Media
Photorealism is not one quality. It is four overlapping qualities that audiences judge almost instantly, often before they can explain what feels wrong. Resolution is the easiest: pixel count, sharpness, and noise floor. Perceptual realism is next: the image looks like something a camera could have captured, with familiar depth, focus falloff, and dynamic range. Physical plausibility is harder: light behaves correctly, materials respond the way skin, glass, and fabric actually behave, and shadows agree with their sources. Behavioral plausibility — mostly relevant to video — covers motion, weight, and timing.
Most generators now clear the first bar effortlessly and stumble on the third. That is why so many outputs look impressive in a thumbnail and unsettling at full size. The tell is rarely the face anymore. It is a reflection that does not match the window, a lens flare with no source, pores that repeat in a grid, or a hand whose fingers bend at an impossible joint.
A useful exercise: view a candidate image at three scales — thumbnail, 100 percent, and heavily cropped around the hands, ears, hairline, and background text. If it survives all three, it is close to production-ready. If it only survives the thumbnail, it belongs in a moodboard, not a campaign.
Understanding this hierarchy changes how you prompt, which model you choose, and how much post-processing you plan for. It also prevents the most common wasted effort in generative work: polishing a render that was never physically believable in the first place.
Inside the Model Stack: Why Generated Images Look Real
Modern realism is the product of several architectural decisions layered on top of each other. None of them alone explains the jump in quality; together they do.
Diffusion, flow matching, and shorter sampling paths
Diffusion models learn to reverse a noise process. Early versions needed dozens or hundreds of sampling steps and still produced mushy detail. Newer approaches — flow matching and consistency-style training among them — learn straighter trajectories from noise to data, which means convincing images in far fewer steps. Fewer steps means lower latency, and latency is what makes iterative creation practical. When a render takes seconds rather than minutes, you can explore ten variations of a lighting setup instead of committing to one.
Latent space and text conditioning
Generating directly at full resolution is wasteful. Most systems compress an image into a latent representation, denoise there, then decode. The text prompt steers that process through an encoder, and the fidelity of that conditioning determines how literally the model follows your instructions. Better conditioning explains why modern tools respond to phrases like "85mm lens, f/1.8, overcast daylight" instead of collapsing everything into a generic "portrait."
Lighting physics over surface pattern
The most consequential shift has been from pattern-matching to light simulation. Older models learned what skin looks like as texture. Current ones increasingly model how light interacts with a surface — subsurface scattering, specular highlights, the way a rim light wraps a jawline. This is why skin tone and translucency improved so dramatically while other areas, like hands, lagged behind.
Training data: diversity matters more than volume
A model trained on a narrow slice of imagery produces a narrow look: the same cheekbones, the same golden-hour palette, the same architectural style. Diversity in the training set is what allows a prompt for "elderly fisherman in harsh noon light" to produce something other than a slightly older version of the same stock face. When evaluating any tool, look for range across age, skin tone, body type, and lighting condition — not just peak quality on one flattering example.
Prompting for Photorealism: Structure Over Keyword Soup
Keyword soup — stacking "hyperrealistic, 8K, ultra detailed, masterpiece, cinematic" — was a workaround for weak conditioning. It mostly adds noise now. Structure works better.
The five-part prompt skeleton
Write prompts in five movements:
- Subject and material: who or what, in specific physical terms — "a 60-year-old ceramicist, forearms dusted with clay."
- Action and setting: what is happening, where, and at what time of day.
- Lens and framing: focal length, aperture, distance, angle — "35mm, waist-up, slightly low angle."
- Light: source, direction, quality — "single window camera-left, soft, cool daylight."
- Texture and imperfection: the details that signal a real camera — "faint motion blur on hands, slight grain, no retouching."
That skeleton gives the model a coherent scene graph rather than a pile of adjectives.
Words that quietly hurt realism
"Hyperrealistic," "perfect," "flawless," and "beauty retouch" push toward plastic skin and over-smooth surfaces. "Rendered," "3D," and "digital art" pull toward a synthetic look. "Cinematic" is overused to the point of meaning nothing; say what you actually want — anamorphic flare, shallow depth of field, tungsten practicals.
Negative constraints and parameter hygiene
Keep negatives short and specific: "extra fingers, warped text, plastic skin, duplicated jewelry, watermark." Long negative lists create their own conflicts. Fix the same issue with positive description when you can — describing a hand "loosely holding a mug, thumb resting on the rim" reduces finger errors more effectively than listing what fingers should not do.
Keep one variable per iteration. If you change lens, light, and seed at once, you learn nothing about which change actually helped.
The Cinematography Layer: Lenses, Light, and Camera Imperfection
Realism lives in camera behavior, not subject detail.
Focal length changes how much of a scene appears and how faces distort. Long lenses compress background and flatter faces; wide lenses introduce perspective distortion and environmental context. Aperture controls depth of field: wide apertures separate subject from background, but too shallow looks like a phone portrait mode artifact. Specify both, and specify shooting distance — the same lens at two distances tells a different story.
Lighting should be motivated. Every visible highlight needs a plausible source, and every shadow needs a direction consistent with that source. Mixed color temperature — warm interior practicals against cool window light — reads as documentary and is hard to fake badly. When a render feels off, the problem is usually a light source with no origin.
Camera imperfection is the finishing signature: sensor grain, slight chromatic aberration at high-contrast edges, a small amount of motion blur where things move, mild lens vignetting. Used sparingly, these cues are more persuasive than any amount of added detail. Used heavily, they read as a filter and undermine the illusion.
A practical trick: decide in advance how much imperfection the shot should carry. For a clean commercial product shot, almost none. For documentary-style portraiture, a noticeable amount. Naming that quantity before you generate keeps a series visually coherent.
Identity, Reference, and Series Consistency
Single striking images are easy. Campaigns need the same person, product, or location across dozens of frames — and consistency is where workflows break.
Reference images and identity locking
Use reference images rather than long descriptions of a face. Two or three well-lit references from different angles outperform paragraphs of adjectives. Where the tool supports it, lock identity separately from scene so you can change wardrobe or location without altering the subject.
Multi-image conditioning
Modern systems accept several references at once: one for identity, one for lighting, one for pose or composition. Treat each reference as answering exactly one question. Overloading a single image with multiple roles usually produces a blend of everything and a match for nothing.
Scene continuity
For locations, build a small "location bible": five to eight approved renders of the same space from different angles, plus notes on time of day, key light direction, and palette. Every new shot is then generated against that bible instead of from scratch. This is the single most effective habit for keeping a series coherent, and it saves hours of guesswork later in the edit.
From Stills to Photorealistic Video
Photorealistic video adds time, and time exposes everything.
Motion budget
Short clips hide flaws. Long clips accumulate them. If your shot needs a lot of camera movement, keep it brief; if it needs length, keep the camera steady and let the subject move. Plan a motion budget per shot: how much the camera moves, how much the subject moves, and how many objects change state. More than two of those at once is where artifacts appear.
Temporal artifacts to watch
The first failures are usually subtle: shimmering texture on fabric, a background element that drifts, hair that resolves differently frame to frame, lips that desynchronize from dialogue. Warping appears at occlusions — a hand passing in front of a face — and at reflections. Locking a reference frame and keeping the camera path simple reduces most of these.
Finishing: sound and grade
Photorealistic footage often reads as fake because of what is missing, not present. Add room tone matched to the space, correct reverb for interiors, and small asymmetries in performance. A gentle grade — consistent black point, slight highlight roll-off, subtle grain — unifies generated shots with any real footage in the same edit.
A Repeatable Production Workflow
Phase 1: Look development
Collect 20 to 40 references. Define a look: palette, contrast, lens character, light quality. Produce six to ten test renders of a single subject across variations. Stop when two consecutive variations look like they belong to the same shoot.
Phase 2: Shot list and generation
Write the shot list before generating anything. For each shot, record subject, framing, lens, light, and one or two alternatives. Batch generation by scene so lighting and palette stay aligned across the sequence.
Phase 3: Selection and refinement
Select ruthlessly — a 10 percent keep rate is normal. Refine only the keepers, with single-variable changes. Small local edits fix costumes and props faster than regenerating the whole image, and they preserve everything that was already working.
Phase 4: Motion, audio, and finish
Animate only approved stills. Keep motion simple, review at full speed before checking frame by frame for warping. Layer sound early; it changes how viewers judge image quality and surface problems you would otherwise miss visually.
Phase 5: Compliance and QA
Check for accidental trademarks, recognizable faces you lack rights to, legible text errors, and any claim implied by the image. Log prompts and seeds for every approved asset so a shot can be reproduced or extended later.
Quality Control: A Practical Checklist
- Hands: finger count, joint direction, nail consistency, grip plausibility.
- Eyes: catchlight position matching the key light, symmetric pupils, natural wetness.
- Hair and fabric: strands resolving individually, no merging, no grid-like repetition.
- Background text and signage: legible, spelled correctly, or intentionally blurred.
- Reflections and shadows: direction, softness, and color consistent with the light source.
- Skin: visible pores at 100 percent, variation across the face, no uniform smoothing.
- Perspective: horizon lines and vanishing points consistent with the stated lens.
- Continuity: wardrobe, props, and time of day matching adjacent shots.
Run this list on a calibrated display and again on a phone. Mobile viewing hides detail but exaggerates contrast and color inconsistency, which is exactly where series-level problems show up first.
Common Mistakes, Evaluation Criteria, and Where Craft Still Wins
Mistakes show up in patterns. Chasing resolution instead of lighting. Regenerating the whole image to fix one prop. Using a single reference for identity, pose, and lighting simultaneously. Letting the model choose the composition instead of blocking it first. Skipping the location bible, then spending hours trying to match a background. And ignoring post-production, where most believable work is actually finished.
When comparing tools, evaluate on: instruction fidelity (does it follow the lens and light you specified), identity consistency across a series, local editing quality, output resolution without upscaling artifacts, video coherence over several seconds, latency for iteration, licensing terms for commercial use, and how much control you retain over seeds and parameters. Peak demo quality matters least — range and repeatability matter most.
Human craft still decides the outcome. The strongest results come from people who know why a shot looks the way it does: key light placement, lens choice, blocking, and edit rhythm. Generative tools shorten execution, not judgment. Teams that storyboard, block, and light deliberately consistently outperform teams that prompt randomly and hope.
FAQ
Do I need a powerful machine?
Not necessarily. Many capable systems run through browser interfaces; local setups help mainly for high-volume work, privacy requirements, or fine-tuning on a specific look.
Can I get truly photorealistic results from text alone?
Yes for many subjects, but hands, text, and complex occlusion still benefit from reference images and local edits. Text-only prompting is best for exploration, not final assets.
How many references should I use?
One to three, each with a distinct role. More references often blur identity rather than refine it.
Why do my images look over-smoothed?
Usually prompt language plus post-processing. Remove "perfect" and "flawless," describe skin texture directly, and stop applying additional smoothing after generation.
Is generated imagery safe for commercial use?
It depends on the tool's licensing and your jurisdiction's rules on likeness and disclosure. Keep records of prompts, references, and approvals, and follow any labeling requirements in your market.
How do I keep a character consistent across dozens of shots?
Lock identity with references, build a location bible, and generate in batches with fixed seeds where possible. Consistency is a process, not a prompt.
What is the fastest way to improve results?
Fix your lighting vocabulary. Understanding soft versus hard light, and where a source sits relative to the subject, improves output more than any model upgrade.
Should I animate every approved still?
No. Animate only shots where motion adds meaning. Static hero frames are often stronger, cheaper, and easier to keep believable.
