
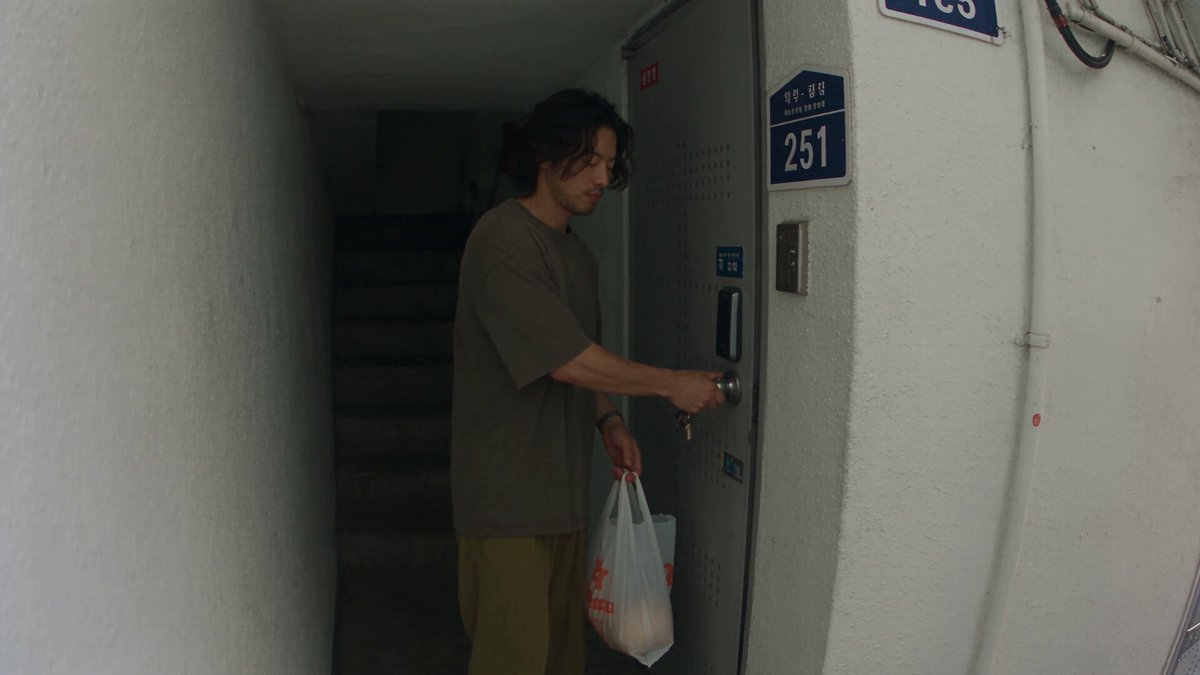
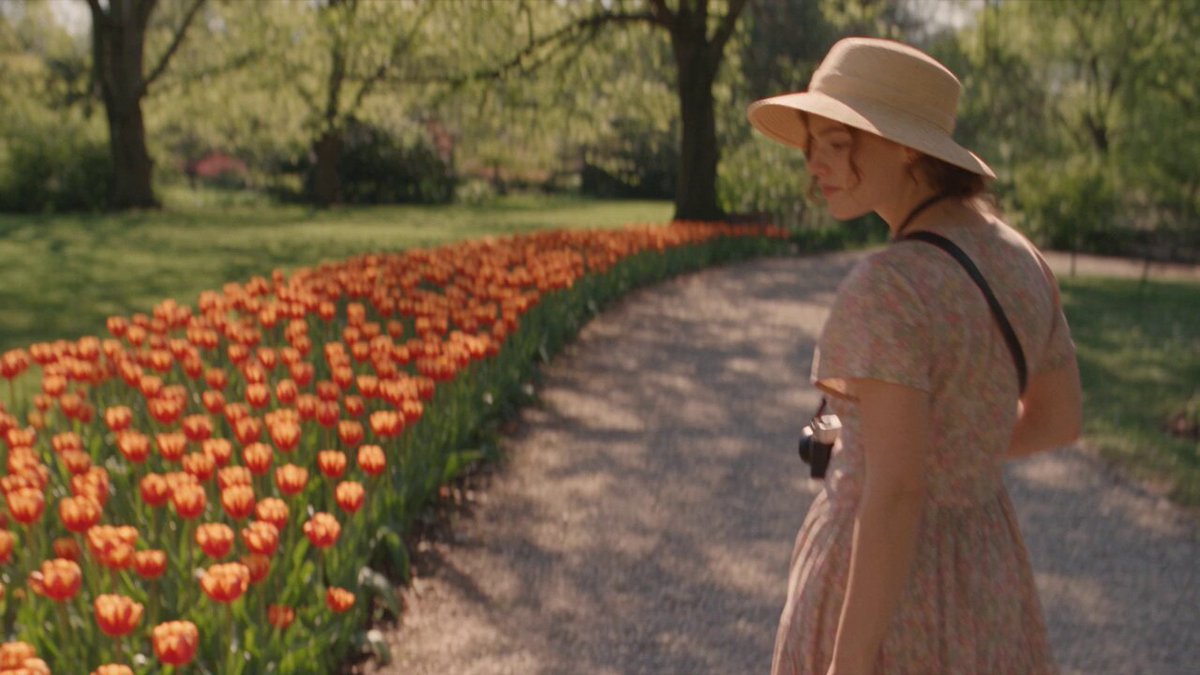
Photorealism is no longer a bonus feature in AI video. It is the entry ticket. Audiences who once marveled at any moving generated frame now scroll past anything that reads as synthetic within half a second, and that judgment happens before they can articulate why. The good news is that photorealism is not a single setting or a magic model. It is the sum of dozens of small, controllable decisions across model choice, prompt structure, reference handling, lighting logic, motion cadence, and finishing.
This guide walks through that entire chain. It is written for people who already know the basics of text-to-video and want to close the gap between "impressive demo" and "looks like it was shot on a camera."
What photorealism actually means in AI video today
Most people equate photorealism with resolution. That is the least important variable. A 4K render with plastic skin and strobing motion blur looks fake, while a 1080p render with believable falloff, grain, and micro-texture can pass on a phone screen without question. Realism is about consistency of signals, not pixel count.
The four signals viewers read unconsciously
Micro-texture. Skin pores, fabric weave, brushed metal, dust on a lens. When a generator smooths these into a uniform surface, the brain flags it as CG immediately. Real footage is never uniform.
Optical behavior. Depth of field that matches the lens you implied, motion blur that matches the shutter, mild chromatic aberration on high-contrast edges, halation around practical lights. Cameras leave fingerprints, and those fingerprints are what viewers recognize as "filmed."
Physical plausibility of motion. Weight, inertia, secondary motion in hair and cloth, believable deceleration. Generators tend to move objects with a slightly floaty, low-mass quality.
Lighting coherence. One dominant motivated source, believable falloff, consistent color temperature, and shadows that agree with each other. Scenes that mix three unrelated light directions read as composited even when nothing else is wrong.
Where generators still fail
Even strong models struggle with hands at small scale, teeth inside a moving mouth, legible text, reflections that should track a moving subject, crowds in the mid-ground, complex occlusion, thin hair against bright backlight, specular highlights that flicker between frames, and fast lateral camera movement across detailed backgrounds. Knowing this list is a production advantage: you can design shots that avoid the weak zones instead of hoping the model gets lucky.
Choosing the right generation model for each shot
The most common beginner mistake is picking one model for an entire project. Professional-looking output usually comes from matching models to shots, the same way a real production chooses different cameras and lenses for different setups.
Group models by behavior, not by brand
Broadly, generalist text-to-video models excel at atmosphere, wide establishing shots, slow dolly moves, and stylized-but-ground movement like Dream Machine, Sora, or Runway. Motion-first engines handle faster action, more physical camera work, and complex choreography. Image-first diffusion models such as Flux-class tools are often better for stills, keyframes, and product beauty shots, which you then animate. Some engines lean cinematic and filmic out of the box; others lean crisp and digital, which is great for commercials and terrible for period drama.
A practical selection matrix
| Shot type | Best fit | Why |
|---|---|---|
| Wide landscape, atmosphere | Generalist cinematic model | Strong global coherence, slow motion tolerance |
| Dialogue close-up | Model with strong face stability | Identity lock and lip-region stability |
| Product macro | Image model + short animated clip | Texture fidelity, controllable specular |
| Action or chase | Motion-first engine | Handles velocity and camera whip |
| Recurring character | Model with image reference support | Consistency across shots |
| Stylized realism | Fine-tuned or stylized model | Consistent art direction, less drift |
Why mixing models inside one sequence can hurt
Different engines have different grain structures, color science, motion blur behavior, and default sharpening. Cut three models together and you get a subtle visual stutter than no viewer can name but everyone feels. If you must mix, unify afterward with a shared grade, matched grain, and a slight overall softness or halation layer that makes the differences feel intentional.
Prompt architecture: writing for physics, not adjectives
Prompt writing for realism is closer to writing a camera report than to writing poetry. Adjectives like "beautiful," "epic," and "cinematic" carry almost no information. Numbers, materials, and spatial relationships carry a lot.
The five-layer prompt
Build every prompt in this order:
- Subject and wardrobe — age, build, clothing fabric, condition.
- Environment and time — location, weather, time of day, ambient detail.
- Camera and lens — focal length, aperture character, height, angle, movement.
- Light — key direction, quality, color temperature, contrast ratio.
- Motion and duration — what physically happens, how fast, over what runtime.
A weak prompt says: "cinematic shot of a woman in a cafe." A strong prompt says: "35mm lens at f/2.0, waist-height, slow push-in; woman in her thirties in a wool coat seated at a window table; overcast daylight from camera left, soft falloff, warm practical lamp behind her; steam rising from a ceramic cup; 4 seconds, gentle handheld."
Camera language that actually changes output
Focal length changes compression and background separation. Aperture character changes depth of field and highlight shape. Camera height changes the emotional read — low angle feels powerful, eye level feels neutral, slightly above eye level feels vulnerable. Movement type changes how much of the frame the model has to invent: a locked-off shot is far easier to keep photoreal than a fast dolly through a busy street.
Negative guidance and artifact suppression
Explicitly name what you do not want: plastic skin, waxy faces, over-sharpening, watermark-like artifacts, duplicate limbs, floating objects, text overlays, oversaturated colors, and strobing. Many engines respond to these lists more reliably than to positive adjectives.
Reference images, keyframes, and character consistency
Consistency is where amateur AI video collapses. A beautiful shot that cannot be repeated is a demo, not a scene.
Start frame, end frame, and storyboard control
If your engine supports first-frame and last-frame conditioning, you effectively gain storyboard-level control. Draw or generate a start frame and an end frame, describe only the transition between them, and the model stops inventing composition. This single technique removes most composition drift.
Multi-image referencing and identity locking
When using reference images, separate style references from subject references. A style reference should show lighting, palette, and texture. A subject reference should be neutral: front-facing, evenly lit, sharp, no accessories that obscure features, no extreme expression. Mixing the two in one image confuses the model and produces a character who looks like a sibling rather than the same person.
Building a look bible
Write down your lens set, palette, contrast ratio, grain amount, and any signature optical effect. Apply it to every shot with the same wording. The look bible is what makes six separately generated clips feel like one film, and it is also what makes handoffs to an editor or colorist possible.
Lighting, lenses, and materials: the strongest realism levers
If you only optimize one thing, optimize light. Lighting communicates more realism than model choice, resolution, or prompt length.
Light like a gaffer, not like a search engine
Describe a motivated source: a window, a practical lamp, a streetlight, the sun through blinds. Give a direction and a quality (hard, soft, diffused, bounced). Give a ratio — for example, key two stops above ambient. Then give a color temperature relationship: cool daylight outside, warm tungsten inside. When a scene contains only one dominant source with believable falloff, realism improves dramatically even in mediocre renders.
Lens and sensor artifacts that read as real
Depth of field should match the focal length and aperture you described. Slight focus breathing during a push-in adds realism. Halation around bright practicals, a faint vignette, and mild lens softness at the frame edges all read as optical rather than digital. Use lens dirt and flares sparingly — and only when something in the scene motivates them, like a practical light just outside the frame.
Skin, fabric, and metal
Realism in close-ups depends on subsurface scattering (light bleeding through skin edges), specular roughness (dry lips versus glossy lips), and textile detail (the weave of wool versus the sheen of satin). Name the material and its condition — dusty, wet, worn, pressed — instead of naming a color.
Motion realism: what breaks the illusion
Viewers forgive a soft render but rarely forgive wrong motion. Motion has its own rules that have nothing to do with resolution.
Frame rate and shutter
Film-standard motion is 24 frames per second with a 180-degree shutter, which produces motion blur equivalent to roughly 1/48 of a second. Generators frequently render with too little blur, producing a crisp, strobing, "soap opera" quality. If your tool exposes shutter or motion-blur settings, use them. If not, add a subtle directional blur in post on fast-moving shots.
Camera moves that hide errors versus moves that expose them
Slow pushes, gentle pans, and slight handheld drift flatter AI footage because the model only needs to invent moderate parallax. Fast whips, long tracking shots through complex environments, and rapid rack focus force the model to fabricate details it usually gets wrong. Choose movement that serves the story and happens to be generation-friendly.
Physics that still trip models
Cloth folding, hair strand separation, liquid volume, smoke dissipation, reflections that follow a moving subject, foot contact with the ground, and object weight when lifted. When a shot depends on one of these, shorten it, obscure it, or handle it with a practical edit rather than fighting the model.
Post-processing that preserves the render
Finishing is where good clips become convincing footage — and where over-processing destroys them.
Order of operations
Start from the highest-quality native render you can justify for final output. Run a temporal consistency check before anything else, because upscaling a flickering clip makes the flicker permanent. Then upscale, then match grain, then grade, then apply halation and optical effects, and finally compress for delivery. Do not sharpen early.
Grain, halation, and chromatic aberration as unifying tools
When you cut together clips from different engines, a shared grain plate, a matched halation curve, and a very slight chromatic aberration on high-contrast edges make the differences disappear. These three moves solve more "why does this look fake" problems than any model upgrade.
Color grading for realism
Avoid aggressive teal-and-orange looks. Protect skin tones, keep highlights from clipping, and let shadows hold detail. A gentle film emulation with slight highlight roll-off adds a believable camera response. Grade in a wide, log-like space if your pipeline allows, and monitor on a calibrated screen if the work is commercial.
Sound is half the illusion
Audiences rate video realism partly by audio. Room tone, cloth rustle, footsteps that match weight, and subtle reverbs make even imperfect footage feel grounded. Silence under a photoreal clip is the fastest way to break the spell.
Quality control checklist and common artifacts
Skipping QC is how projects ship with an obvious flaw in the first three seconds.
A five-pass review
- Thumbnail strip. Scan all frames at a glance for composition drift or exposure jumps.
- Slow scrub. Review at quarter speed to catch warping, melting, and texture boiling.
- Freeze-frame inspection. Check hands, faces, teeth, text, and reflections.
- Muted playback. Watch silently to judge pure visual continuity.
- Phone screen test. Watch on a small screen with sound, which is how most viewers will see it.
Common artifacts and fixes
Face warping during turns usually means the shot is too long or the subject rotates too fast — shorten and simplify. Melting hands can be cropped, obscured, or re-rendered with hands out of frame. Texture boiling on backgrounds responds to a slightly higher render resolution or a mild temporal denoise. Flicker in highlights is best suppressed with matched grain and a small halation pass. Duplicate limbs require a re-render with a simpler action description. Gibberish text should be removed from the scene entirely — add signage or screens in post.
Building a repeatable photoreal pipeline
Talent shows up in consistency. A repeatable pipeline turns one good clip into a library of usable footage.
Pre-production
Build a lookbook with reference stills, write a shot list with lens and lighting notes, and create a prompt library where each prompt is stored with the settings that produced it. Version your prompts like code: change one variable at a time and record the result.
Production discipline
Generate four to eight variations per shot rather than one. Iterate at a lower resolution and only render final high-quality passes once composition and lighting are locked. Keep seeds for anything that worked. Batch similar shots together so you can reuse prompt scaffolding and keep the visual language consistent.
Planning your render budget
Estimate iterations per shot honestly — usually three to five rounds for hero shots and one to two for background plates. Reserve the most expensive settings for the final pass. Track how many generations each shot consumed so you can forecast the next project instead of guessing. Reusing a locked look across shots is the single biggest savings in any AI video pipeline.
Knowing when to stop generating
If a shot has failed repeatedly, the problem is usually the concept rather than the prompt. Simplify the action, change the camera move, or cover the moment with two shorter shots and an edit. Editing around a limitation is faster than generating through it.
FAQ
Do I need the most expensive model to get photorealism? No. Lighting description, shot design, motion blur, grain, and finishing matter more than the model tier. A well-lit, well-composed clip from a mid-tier engine often beats a poorly directed clip from a flagship one.
How long should AI shots be? Most photoreal AI shots work best between two and five seconds. Longer shots accumulate drift, and drift is what kills the illusion. Cut more, hold less.
Should I upscale before or after grading? Upscale first, then grade. Grading before upscaling bakes in artifacts and makes flicker more visible once resolution increases.
Why do my characters change faces between shots? Usually because reference images were inconsistent in lighting or angle, or because prompts described the character differently each time. Lock one neutral reference and copy the character description verbatim.
Is real footage cheating? No. Combining AI shots with practical footage, stock plates, or real audio is a legitimate finishing strategy and often the fastest route to something that looks photographed rather than computed.
What single change improves realism the most? Replace adjective-heavy prompts with lens, light direction, and material specificity. It costs nothing and changes everything.
Photorealism in AI video is a craft problem, not a settings problem. Design shots your tools can execute, describe light like a gaffer, control motion like an editor, and finish like a colorist. Do that consistently, and viewers will stop asking whether it was generated — which is exactly the point.
