
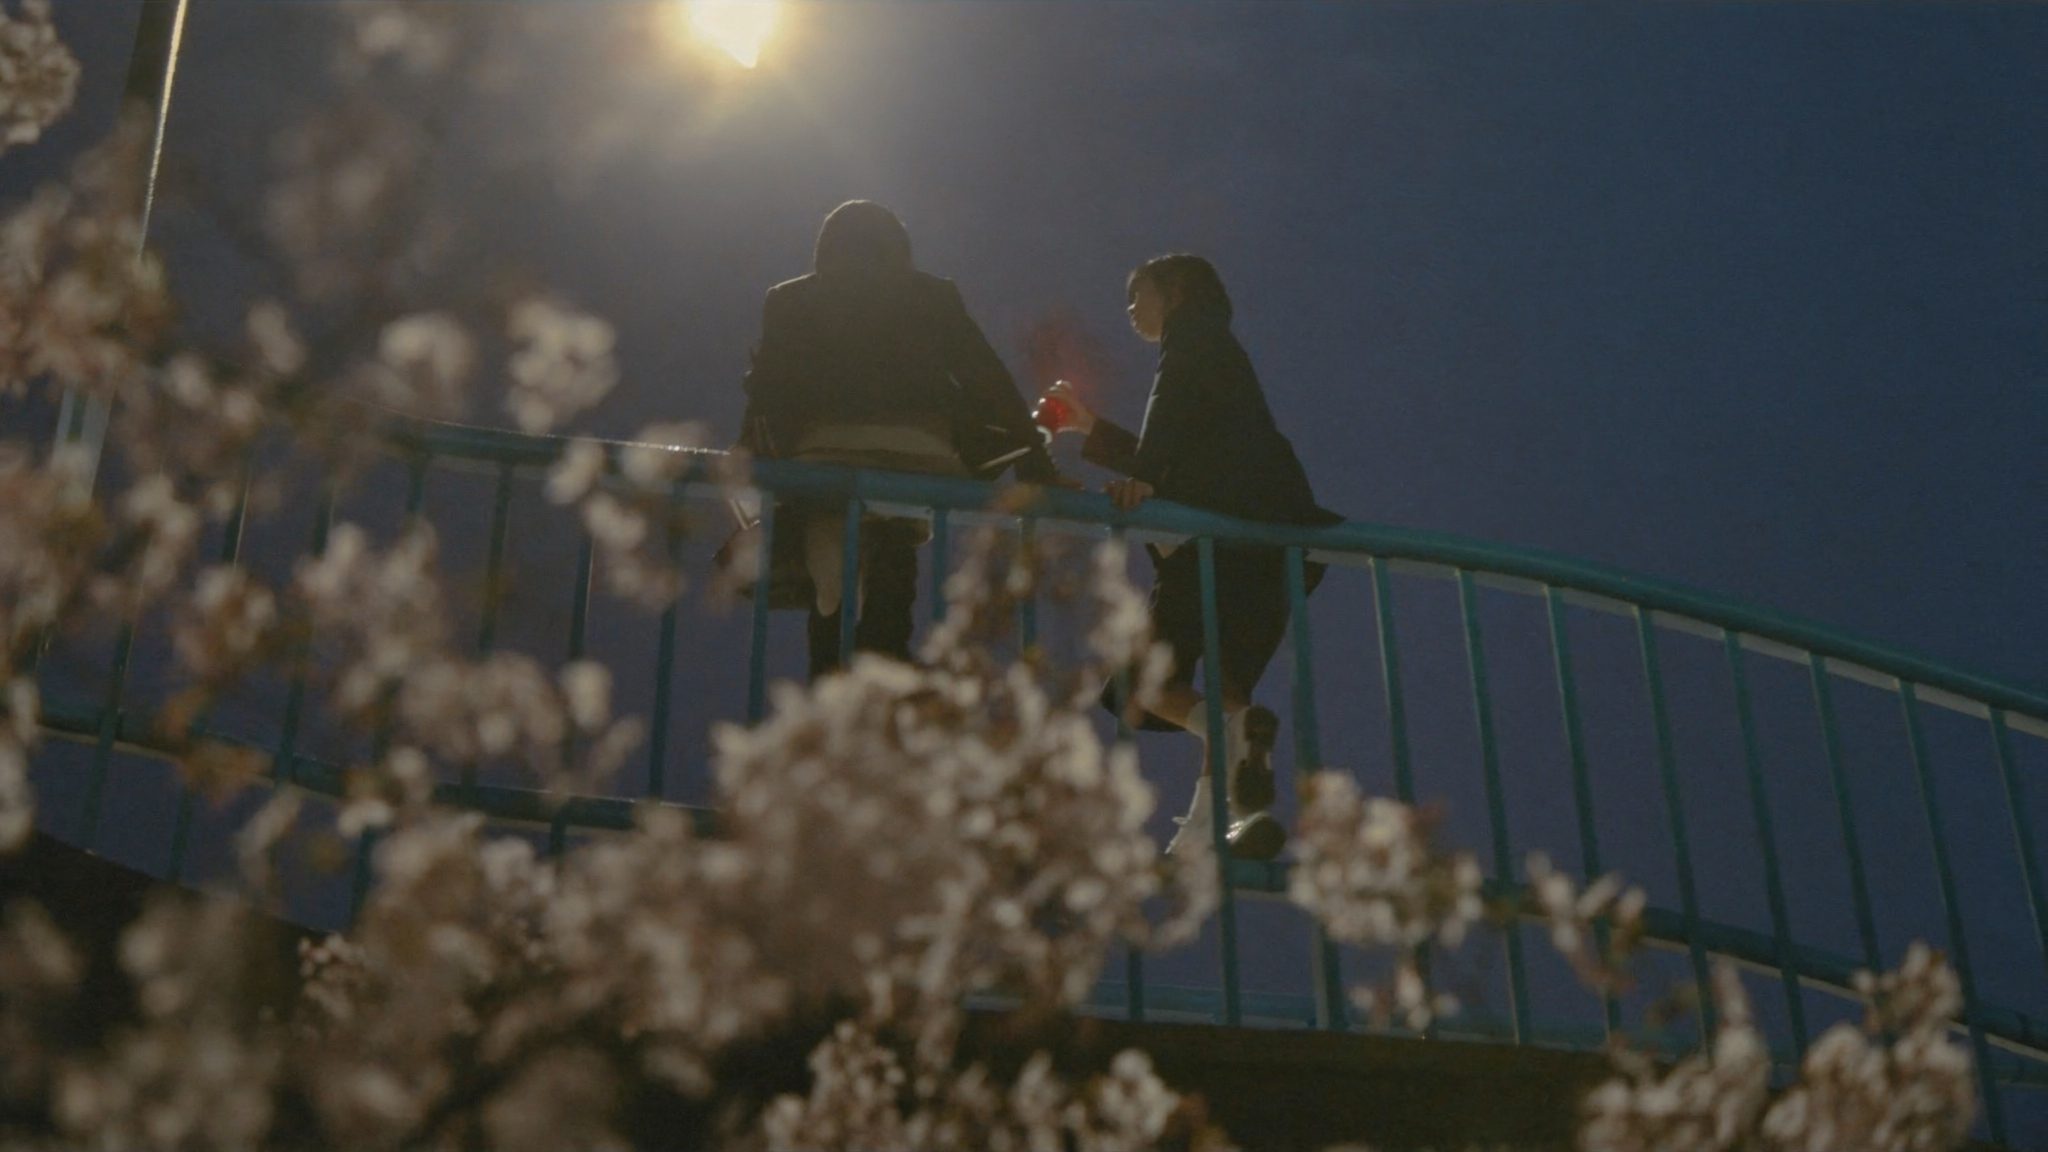
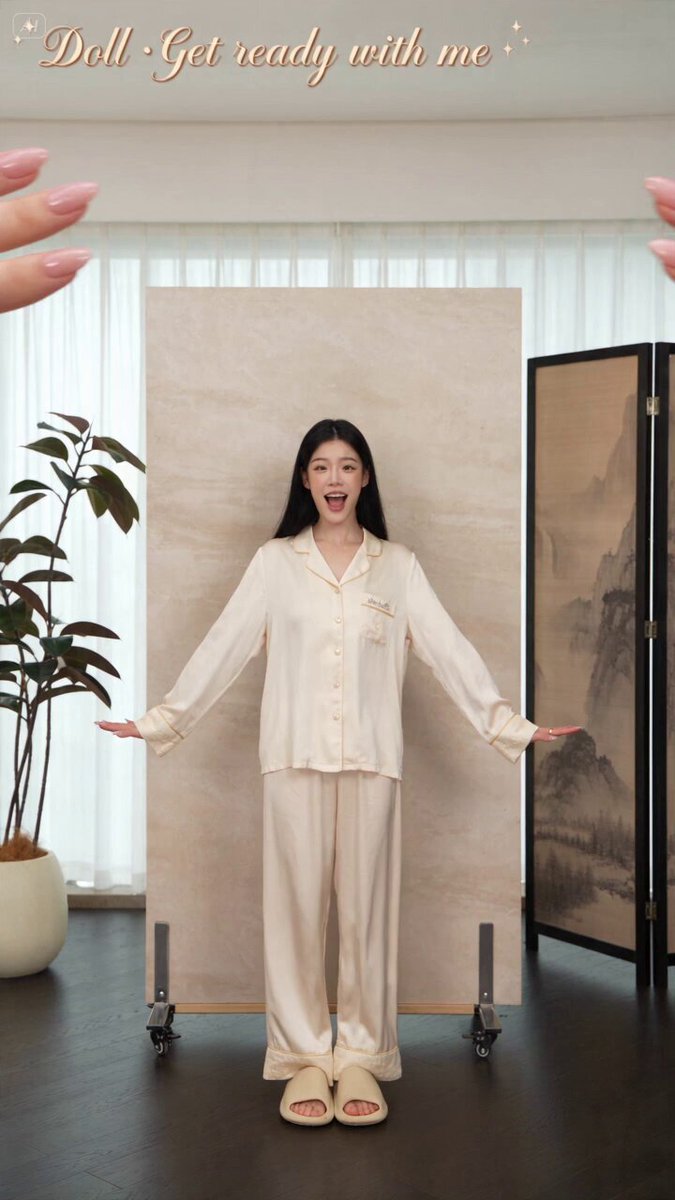
Why Photorealism Became the Baseline Expectation
A few years ago, an AI-generated clip only had to move convincingly to impress an audience. Today the bar sits much higher. Viewers have been trained by streaming platforms, high-bitrate phone footage and cinematic game engines to expect skin that scatters light properly, fabric that folds with weight, and camera motion that behaves like a real operator holding real glass. When a generated shot breaks those cues, the reaction is immediate and visceral: something feels wrong, even if the viewer cannot name why.
That shift matters for anyone producing video at scale. Photorealism is no longer a premium aesthetic reserved for hero shots. It is the default register that product demos, social ads, explainers and narrative shorts are judged against. If your generated footage reads as synthetic, the message you are delivering gets discounted along with it.
The good news is that the techniques for reaching convincing realism are now well understood. They are not a single prompt trick or a single model. They are a layered practice: choosing the right generation approach for each shot, controlling identity and continuity, borrowing cinematography rules from live action, and treating audio as part of the image rather than an afterthought. This guide walks through that practice end to end, with the decision criteria and failure modes that matter in real production.
What "Photorealistic" Actually Means in Generative Video
Before optimizing anything, it helps to break realism into separate problems, because they are solved in different places.
Material fidelity is how surfaces respond to light. Skin has subsurface scattering, slight oil sheen on the nose and forehead, and fine vellus hair catching rim light. Metal has anisotropic highlights. Wood has grain that runs in one direction and never repeats exactly. Models that fail here produce the plastic-face look: uniformly smooth, uniformly bright, no micro-variation.
Temporal coherence is consistency frame to frame. A face that morphs between frames, a shirt pattern that crawls, or a shadow that flips direction will destroy realism faster than any static imperfection. Temporal artifacts are the number one giveaway in short clips, because motion draws the eye to change.
Camera behavior is the physical logic of the shot. Real cameras have depth of field that follows focus distance, rolling shutter on fast pans, lens breathing, and handheld micro-jitter. Generated clips that glide perfectly with infinite depth of field look like animation, not footage.
Lighting physics is whether shadows, reflections and bounce light agree with each other. Two light sources that imply opposite key directions, or a reflection in a window that shows nothing, break the illusion instantly.
Motion physics is weight and momentum. Cloth that does not lag behind the body, hair that does not react to a turn, or liquid that moves without viscosity all read as fake.
Treat these as five separate QA passes rather than one vague quality score. You will catch far more problems, and you will know which stage of your pipeline to fix.
Choosing a Generation Model for the Shot You Need
There is no single best model. There is a best model for a specific shot, at a specific duration, with a specific control requirement.
Text-to-video versus image-to-video
Text-to-video is fastest for exploration. It is ideal for mood boards, establishing shots, backgrounds and abstract transitions where identity does not need to persist. Its weakness is control: you get a plausible shot, not the shot you described.
Image-to-video starts from a still and animates it. This is the workhorse for photorealism, because you can iterate on the still until it is perfect, then commit to motion. Most believable character work starts as a carefully composed image, whether that image came from a generator, a photo shoot or a 3D render.
A practical rule: use text-to-video to find the idea, image-to-video to lock the look, and reference-driven generation to keep a character or product stable across a sequence.
Reference-driven and control models
Models that accept multiple reference images, depth maps, pose skeletons or motion references give you the control that narrative work demands. They cost more compute per second and require more setup, but they eliminate the retry loop that eats entire afternoons. If a shot must match an existing wardrobe, a specific actor, or a locked camera move, refuse to start without a control channel.
Resolution, duration and cost trade-offs
Longer clips are not automatically better. A four-second shot that holds up under inspection beats a twelve-second shot with a morph at second nine. Build sequences from short, verified shots and edit them together. This also mirrors real production: coverage is assembled, not captured in one take.
When you are budget-constrained, spend on the shots the audience will study. Faces, hands and hero products deserve the highest fidelity setting. Wide establishing shots and motion-blurred transitions can be generated more cheaply without anyone noticing.
The Prompt Stack: How to Talk to a Photoreal Model
Prompts for realism are structured, not poetic. Think of them as five stacked layers.
Subject and wardrobe. Be concrete. "A woman in her late thirties" beats "a person." Name fabrics, colors and fit. Vague clothing descriptions let the model invent a default wardrobe that rarely matches across shots.
Action and micro-action. Describe what changes during the clip, not just what exists. "She turns her head slightly toward the window and exhales" gives the model motion to resolve. Simpler clips with one clear action produce fewer artifacts than clips stacked with three simultaneous events.
Camera. Specify shot size, angle, movement and lens. "Medium close-up, 50mm equivalent, slow push-in, shoulder height, subtle handheld" gives the model a physical rig to imitate. Camera language is one of the highest-leverage additions you can make, because it forces depth-of-field and parallax behavior.
Light. Name the source, direction and quality. "Soft window light from camera left, warm practical lamp behind subject, deep falloff into the background" produces believable contrast. Avoid stacking contradictory sources.
Finish. Describe the grade and capture medium. "Slight halation on highlights, gentle film grain, muted teal shadows" nudges output away from the over-sharpened digital look that reads as synthetic.
A compact negative list helps as well: no warped hands, no extra fingers, no text artifacts, no duplicated limbs, no identity drift, no sudden lighting changes. Keep negatives short, since long negative lists can push models into odd territory.
Prompt templates worth saving
Keep a small library of tested templates for recurring shot types: interview close-up, product macro on a turntable, walking tracking shot, drone reveal, and hands-on-desk insert. Templates reduce variance and make batch production realistic. When a template starts underperforming, adjust one layer at a time so you know what actually changed the result.
Character Consistency Across Multiple Shots
Identity drift is the most common complaint about AI video, and it is almost always a pipeline problem rather than a model problem.
Build a character reference sheet first
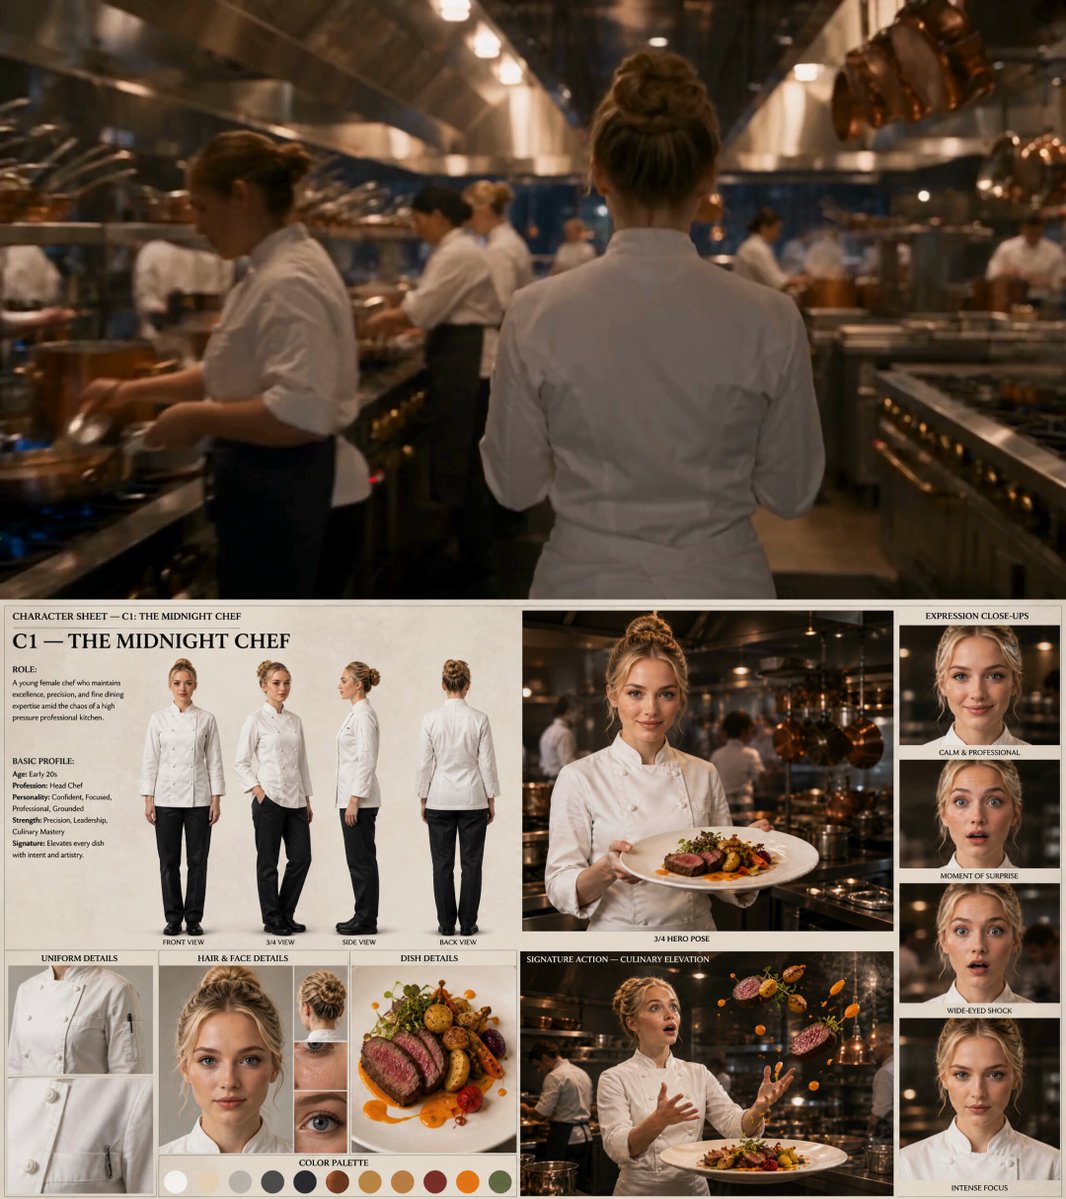
Create four to six reference images of the same character: straight-on neutral, three-quarter view, profile, and one with a strong expression. Keep the same lighting and wardrobe. Use these references every time the character appears. Consistency improves dramatically when the model sees the same face from multiple angles rather than one repeated image.
Use keyframe control for shot boundaries
Generate or select a start frame and an end frame for each shot, then let the model interpolate. This gives you authority over blocking and composition while letting the model handle motion. Where possible, generate the last frame of shot A and the first frame of shot B from the same reference set so cuts feel like the same scene.
Anchor wardrobe, props and location
Consistency is not only the face. A jacket color that shifts between shots, a mug that changes shape, or a room whose window moves all break continuity. Keep a written scene bible with hex values for wardrobe, a prop list, and a simple floor plan. Then reference it in every prompt rather than relying on memory.
Handle hands and profile shots deliberately
Hands remain the hardest subject. Compose shots that keep hands partially occluded, in motion, or out of frame when the story allows. When hands must be visible, generate at a higher setting, use shorter clips, and check every finger across the full duration. Extreme profile views and fast head turns are similarly risky, so plan coverage that avoids them unless the shot is essential.
Cinematography Layer: Lens, Motion and Light
Photorealism is largely a photography problem, and the fastest way to improve output is to think like a camera operator.
Depth of field should follow subject distance. If a character leans in, the background should soften. If the camera pulls back, more of the environment should come into focus. Specify this explicitly, because many models default to uniformly sharp frames that look like phone snapshots rather than cinema.
Camera motion should have a reason. A slow push-in builds tension. A lateral track reveals space. A handheld drift suggests documentary intimacy. Random motion reads as noise. Choose one movement per shot and commit to it.
Lighting should have a motivation you can name. Window light, practical lamps, overcast sky, or a single soft source are all readable to an audience. Mixed unmotivated sources create the flat, overlit look that signals synthetic footage. Shadows are your friend: they give depth and hide detail you cannot render convincingly.
Finally, embrace imperfection. Slight grain, subtle lens flare, minor focus falloff and a hint of motion blur make footage feel captured rather than computed. A perfectly clean frame often looks the least real.
The Audio Gap: Where Most AI Video Falls Apart
Audiences forgive a slightly soft image far more readily than bad sound. Silent generated clips, mismatched room tone, or dialogue that does not sync with mouth movement will undermine otherwise excellent visuals.
Build audio in three layers. First, ambience: room tone, street noise, wind. This layer does more for believability than any visual tweak, because it convinces the ear that the space is real. Second, foley: footsteps, fabric, object handling. These sounds should match the surface and the weight of what you see. Third, dialogue or voiceover, recorded or synthesized with attention to pacing and breath.
Where lip sync is required, treat the mouth as a post-production element: generate a clean neutral performance, then align audio carefully and check at quarter speed. If sync is imperfect, cut away to reaction shots or use the classic technique of framing the speaker from behind or in profile.
Music should support, not dominate. Keep it under the ambience and duck it slightly under speech. A short, well-mixed clip with modest music beats a loud, unmixed one every time.
A Repeatable Production Workflow
Here is a sequence that scales from a single clip to a weekly batch.
1. Script and shot list
Write the script, then convert it into a numbered shot list with duration, framing, action and audio notes. Every shot should be short enough to verify frame by frame. If a shot cannot be described in two sentences, split it.
2. Look development
Generate ten to twenty stills to establish palette, wardrobe, lens character and lighting. Choose two or three reference images per scene. Do not proceed until the stills alone look photographic.
3. Reference and prompt preparation
Assemble character sheets, prop references and depth or pose guides where needed. Write prompts using the five-layer stack, and save them into a versioned document so you can diff changes later.
4. Batch generation
Generate multiple variants of each shot rather than one. Two or three candidates per shot is usually enough; more than five rarely improves the outcome. Generate in short durations to keep render times and revision costs manageable.
5. Review and select
Review at full speed for feel, then at quarter speed for artifacts. Watch hands, eyes, teeth, text, reflections and shadow direction. Mark each clip pass, retry or discard, and note why. Patterns in your notes tell you which prompt layer to fix.
6. Assemble and finish
Edit for rhythm, add audio layers, apply a subtle unifying grade, and add grain or halation if the footage looks too digital. Final polish should be light; heavy effects on generated footage usually amplify artifacts rather than hide them.
7. Version and archive
Store prompts, references and settings alongside each finished clip. When you need a sequel or a reshoot, this archive turns a two-day process into an hour of work.
Quality Control: Catching the Uncanny Before Your Audience Does
Run a fixed checklist on every clip. Identity: same face, same skin tone, no drifting age. Anatomy: hands, ears, neck length, limb count. Continuity: wardrobe, props, hair state, time of day. Physics: cloth weight, hair reaction, liquid behavior, object weight. Optics: consistent depth of field, stable horizon, believable lens behavior. Light: one coherent key direction, shadows that match. Audio: ambience present, sync tight, no clipping.
View everything on a phone screen as well as a monitor. Small screens hide fine detail problems but expose timing and sync issues, which is where audiences actually watch. If a clip survives both, it is ready.
Common Mistakes That Destroy Realism
Trying to fix composition in motion. If the still is wrong, the clip will be wrong. Iterate on the image first.
Stacking too many actions. Two or three beats per clip maximum. Complexity multiplies artifacts.
Skipping references. Rebuilding a character from text every shot guarantees drift.
Over-sharpening. Aggressive sharpening reveals synthetic texture. Add grain instead.
Ignoring sound. Silent clips are almost never convincing.
Chasing perfection on unimportant shots. Wide shots and five-second inserts do not need hero-level fidelity.
Not keeping a log. Without records, you repeat mistakes and lose the settings that worked.
FAQ
How long should each generated clip be?
Three to six seconds is the sweet spot. Model coherence degrades with length, and shorter clips are cheaper to regenerate. Build longer sequences in the edit.
Do I need a paid tier to get photorealism?
Higher tiers usually unlock longer durations, higher resolution and control features. You can learn every technique on entry-level access, but control channels are what make multi-shot work practical.
Why does my character's face change between shots?
Almost always because references changed, lighting changed, or the prompt described the person differently. Lock the reference set and the scene bible, then re-run.
Is it better to generate in high resolution and downscale?
Usually yes. Generating larger and delivering smaller hides minor artifacts and gives you room to reframe. Downscale with a mild sharpening pass rather than a heavy one.
How do I make footage look less like AI?
Add camera imperfection: slight handheld motion, shallow depth of field, motivated lighting, a little grain and halation. Cut on motion. Add real ambience under every scene.
Can I mix generated shots with real footage?
Yes, and it often works better. Match the grade, add the same grain to both, and keep generated shots shorter than live-action ones so the difference in micro-detail is less noticeable.
What is the single highest-impact improvement?
Audio. Ambience, foley and clean dialogue raise perceived realism more than any resolution bump.
Bringing It Together
Photorealistic AI video is a craft problem with a clear skill ladder. Get the still right, control identity with references and keyframes, borrow camera and lighting logic from live action, treat audio as half the image, and verify every clip against a fixed checklist. None of these steps require exotic tools; they require discipline and a repeatable process.
Start small. Pick one shot type, build a template, and run it ten times until the output is boringly consistent. Then expand to sequences. Consistency, not spectacle, is what makes generated footage usable in real productions, and consistency is exactly what a disciplined workflow delivers.
