
AI video generation has moved from a novelty to a working production tool. Yet the gap between a clip that looks like a demo and a clip you would actually drop into an edit rarely comes down to which model you opened. It comes down to the prompt: how precisely you described the subject, the motion, the light, and the limits. This guide walks through a practical, repeatable approach to writing video prompts that hold up across tools, with templates, examples, decision criteria, and the failure patterns worth avoiding.
Why Prompt Engineering Decides the Quality of AI Video
Text-to-video models are probabilistic. They do not read your mind; they complete a pattern. When a prompt is vague, the model fills every gap with the statistical average of its training data. That is why so many unprompted clips share the same look: a slow drifting camera, warm golden-hour light, a subject who walks purposefully toward nothing in particular.
A precise prompt narrows the range of plausible outputs. Every concrete detail you add removes a degree of freedom and pulls the render toward the frame in your head. Lens choice, direction of travel, time of day, wardrobe texture, the speed of a hand movement, the color of the light in the background: each one is a constraint that makes the result more predictable.
It helps to stop thinking of prompting as a vocabulary trick and start thinking of it as briefing. A director does not tell a cinematographer to make something cinematic. They say: medium shot, 50mm, she enters from the left, window light from camera right, hold on her face for two seconds before she turns. Video prompts work the same way. You are writing a shot description, not a mood board caption.
The compounding effect matters too. One good prompt is luck. A prompt structure that produces usable results across ten shots is a production system, and that system is what allows you to plan a sequence instead of generating one-offs and hoping the edit saves you.
The Anatomy of a Strong Video Prompt
Most reliable prompts can be broken into six layers. You do not need all six every time, but knowing which layer is missing tells you why a render failed.
Subject and action
Describe who or what is on screen, what they are doing, and how they are doing it. Age range, wardrobe, physical detail, posture, and the specific verb all matter. A woman walks is weak. A pastry chef in her late forties folds dough on a stainless-steel counter, working at a steady rhythm, is a shot.
Include one clear action per clip. Models handle a single continuous motion far better than a sequence of events. If you need three beats, plan three shots.
Environment and time
Name the location, the time of day, and the weather if it matters. A rain-slicked alley at 3am reads differently from the same alley at noon. Mentioning the environment also anchors background behavior: crowds, traffic, foliage movement, reflections in glass.
Camera and lens
Camera language is the highest-leverage layer and the most commonly skipped. Specify framing (wide, medium, close-up), lens feel (wide-angle, 50mm equivalent, telephoto compression, macro), and depth of field (shallow with soft background, or deep and sharp throughout).
Lighting and atmosphere
Lighting carries the emotional read. Say where the light comes from and what quality it has: a hard key from camera left, soft overcast daylight, warm practical lamps, cold neon spill, moonlight through blinds. Add atmospheric texture when it helps: haze, dust motes, steam, film grain.
Motion and pacing
Describe how fast things move and how the camera behaves over the duration. Slow push-in, handheld follow, static locked-off frame with the subject moving, or a quick whip pan all produce different results. Add tempo words only when they are actionable: slow, deliberate, hurried, mechanical, relaxed.
Audio and dialogue cues
Some engines accept audio or dialogue hints, and even when they do not render sound, mentioning ambient character often nudges the visual performance. Keep it short: quiet room tone, distant traffic, no music.
A complete example using all six layers:
Medium close-up of a pastry chef in her late forties, flour dust on her apron,
folding dough on a stainless-steel counter. She works at a steady rhythm and
glances off-camera once. Slow push-in from chest height, 50mm equivalent,
shallow depth of field. Warm window light from the left, cool kitchen
fluorescents in the background, faint steam. Quiet room tone, no music.
A Reusable Prompt Template You Can Adapt
Templates remove the blank-page problem and make troubleshooting easier because you always know which slot to change. A workable structure looks like this:
[Shot size and subject] + [specific action] + [location and time]
+ [camera move and lens] + [lighting and atmosphere] + [mood or pacing]
+ [exclusions]
Fill it in once for your hero shot, then vary only the parts that should change between shots. If your sequence has three beats, keep everything identical except the shot size and the action. That single discipline produces far more usable continuity than any post-processing trick.
Two practical rules make the template work harder. First, order matters less than clarity, but put the subject and action early; some models weight the beginning of a prompt more heavily. Second, keep the total length reasonable. Long prompts are useful for narrative context, but past a certain point you are diluting the instructions that actually control the image.
Adapting Prompts Across Different Video Models
Every engine has a personality. Moving a prompt between them without translation is one of the most common sources of disappointment.
Longer narrative versus compact instruction
Some models reward descriptive, paragraph-length prompts that read like a shot from a screenplay. Others respond better to short, dense instructions of one or two sentences. If a model ignores your details, cut the prompt in half before you change anything else.
Keyframes, references, and image-to-video
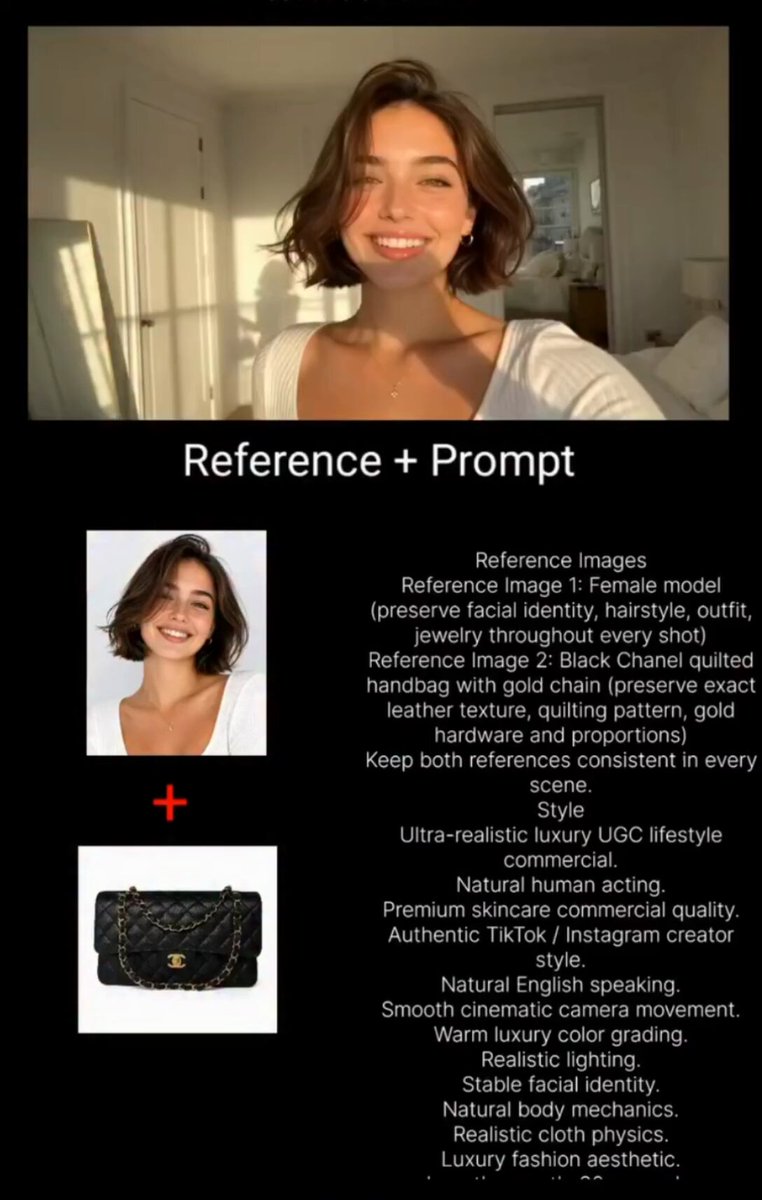
Several tools accept a starting image, an ending image, or both. When you have them, use them. A first frame locks subject appearance, framing, and lighting far more reliably than a sentence can. Reference images are also the fastest route to consistent characters and products across a sequence.
Model-specific strengths
Some engines excel at photoreal humans, others at stylized motion, physically plausible camera moves, or longer clip durations. Rather than memorizing feature lists, run a standard test prompt through any new tool: one human action, one camera move, one lighting condition, no text. Compare the results side by side. You will learn more in ten minutes of testing than from any comparison table.
Timing and duration
Clip length changes how much action fits. If your engine produces short clips, write prompts that describe a single continuous beat rather than a mini-story. Trying to squeeze three actions into a short clip almost always produces morphing or a rushed, unreadable result.
Directing the Frame: Camera, Lighting, and Atmosphere
This is where amateur and professional output diverge most sharply, so it deserves its own vocabulary list.
Camera moves that read clearly
Use one move at a time. Combining a dolly with an orbit and a tilt usually produces mush.
- Static locked-off: the safest choice, ideal for dialogue and product detail.
- Push in: builds attention and tension.
- Pull out: reveals context, good for endings.
- Dolly or truck left and right: lateral movement that feels cinematic.
- Handheld follow: energy and documentary realism; add slight instability language.
- Crane or rise: emphasizing scale or transitions.
- Orbit: circling a subject; use sparingly and slowly.
- Whip pan: fast and stylized; best used as a transition.
- Rack focus: shifting attention between foreground and background layers.
Pair the move with a speed. A slow push-in and a fast push-in are different shots, and most models will honor the distinction if you state it.
Lighting that carries mood
Describe the source and the quality, not the emotion. Warm practical lamps and cold window light in the same frame tells the model you want contrast. Backlit haze, hard midday sun with deep shadows, soft overcast, single-source noir, or diffuse bounce from a white wall all produce distinct, repeatable looks. When you also want a color story, name it plainly: desaturated teal shadows, amber highlights, monochrome with a single red accent.
Texture and filmic detail
Small additions like subtle film grain, anamorphic flare, gentle highlight bloom, or slight lens vignette can lift a render out of the uncanny valley. Use one or two, not five. Too much texture competes with the subject and makes the image feel synthetic rather than photographic.
Consistency Across Shots
Consistency is the hardest problem in AI video, and it is solved with structure rather than better adjectives.
Start with a character sheet you copy verbatim into every prompt: age range, hair, wardrobe, one distinguishing feature. Do not paraphrase between shots. If shot one says gray wool coat over a white shirt, shot four must say the same thing word for word.
Do the same for locations. Keep a frozen paragraph describing the room, street, or set, and paste it unchanged. Small variations in wording are read as new locations.
Where the tool allows it, lock seeds, reuse reference images, and use first-and-last-frame generation for shots that must connect. When nothing works, design around the limitation: cut on motion, insert a detail shot, or place a reaction shot between two moments where the character would otherwise change appearance. Editors have solved continuity problems for a century; a well-placed cut is cheaper than a hundred re-renders.
Negative Prompting, Weighting, and Iteration Discipline
Negative instructions tell the model what to avoid. Depending on the tool, you either fill a dedicated field or add exclusions in prose. Useful exclusions include on-screen text, watermarks, logos, extra limbs, distorted hands, jittery motion, warped faces, sudden cuts, and letterbox bars. Keep the list short and relevant to the failure you are seeing. A generic wall of exclusions dilutes the rest of the prompt.
Weighting lets you signal which elements matter more. Syntax varies widely between tools, and it is not worth memorizing every variant. What matters is the principle: emphasize the subject and action, de-emphasize background detail, and avoid adding weight to things you have not described clearly in the first place.
Then comes the part most people skip: iteration discipline. Change one variable at a time. Keep a written log of prompt, model, settings, and result. Evaluate renders against a fixed checklist rather than vibes.
A checklist that works:
- Is the subject recognizable and anatomically correct?
- Does the camera move match what I asked for?
- Is the lighting direction and color consistent with the description?
- Does motion look physically plausible without strobing or morphing?
- Is it usable in an edit at this duration and aspect ratio?
If a render fails two or more checks, do not tweak adjectives. Simplify the prompt, cut a camera move, and render again.
A Practical End-to-End Workflow
Here is a sequence that scales from a single social clip to a short branded film.
- Write the brief in plain language. One paragraph, no jargon: what the viewer should feel and what they should see.
- Break it into a shot list. Each row is one clip with a purpose, a duration, and a frame size.
- Build the prompt for each row using the six-layer template. Freeze character and location descriptions before you start.
- Gather references. Stills, mood frames, and product photos reduce ambiguity faster than words.
- Generate low-cost test renders first. Check composition and motion before investing in higher quality output.
- Score each render against the checklist. Log the score.
- Refine one variable, then re-render. Repeat until a shot passes.
- Upscale or extend only the shots that pass.
- Assemble in the editor. Cut on motion, add sound design, and use inserts to cover weak transitions.
- Save every winning prompt into a searchable library with notes on why it worked.
Step ten is what turns a hobby into a pipeline. After a few projects you will have reusable building blocks for interviews, product beauty shots, drone-style establishes, and atmospheric textures, each already tuned to your preferred models.
Common Mistakes and How to Fix Them
Over-describing everything. When a prompt lists twenty details, the model has no priority. Keep three to five visual elements and one action.
Conflicting instructions. Static camera with a fast dolly forward means the model will pick one at random. Read your prompt once and remove contradictions.
Multiple actions per clip. Two actions in one short clip produce morphing. Split them into separate shots.
Asking for readable text or logos. Text rendering remains unreliable. Add typography in post-production.
Ignoring aspect ratio. Vertical, square, and widescreen compositions need different framing language. State the frame shape when the tool supports it, and design shots accordingly.
Expecting perfect continuity. Plan for cuts, inserts, and reaction shots rather than betting the sequence on a single flawless render.
Never logging prompts. Without a log, you cannot reproduce a win or diagnose a loss. A simple spreadsheet column is enough.
FAQ
How long should a video prompt be?
Long enough to cover subject, action, camera, and lighting; short enough that the instructions stay legible. For most tools, two to four sentences is the sweet spot. Use longer narrative prompts only when the model is specifically designed for them and you have verified the gain.
Do camera terms like dolly and truck actually work?
Yes, more often than you would expect, provided you use one move and state its speed. Terms borrowed from real production carry meaning because training data includes shot descriptions, screenplays, and technical documentation.
Why does my character change between shots?
Because appearance was described differently each time, or because the model re-sampled freely. Fix it by freezing a verbatim character description, locking seeds, and using reference or keyframe images where available.
Should I include negative prompts everywhere?
Only when there is a specific artifact to suppress. A short, targeted exclusion list helps. A long generic one competes with your actual instructions.
Is image-to-video better than text-to-video?
For continuity and product accuracy, almost always yes. For exploring an idea quickly, text alone is faster. Many teams do both: text to explore, images to finalize.
How many test renders should I budget per shot?
Plan on three to six for a simple shot and more for anything with human hands, crowds, or complex camera movement. Test at lower quality first, then commit to the passing version.
Can one prompt be reused across different models?
Not without translation. The visual content transfers; the density and syntax usually need adjusting. Keep a compact version and a narrative version of every prompt so you can switch quickly.
What is the fastest way to improve at this?
Write a shot list, render it with one model, and score the results against a fixed checklist. Structured repetition beats reading about prompting, because the feedback loop is where the skill actually forms.
The underlying skill is not memorizing keywords for a specific engine. It is learning to describe an image in motion with enough precision that any capable model can reproduce it, and then building a small library of those descriptions you can trust. Once you have that, changing tools stops being a threat and becomes a simple substitution.
