
Why Most AI Video Looks Generic — and Prompts Are the Reason
AI video generators have reached the point where almost anyone can type a sentence and get back a moving image. That accessibility is a triumph, but it has also created a flood of competent, interchangeable clips: a slow drone shot over mountains, a neon city at night, a slow-motion portrait with particles drifting through the air. The tool is not the bottleneck anymore. The instruction is.
Cinematic output rarely happens by accident. Professional-looking footage — whether shot on a physical camera or generated by a diffusion model — is the result of deliberate decisions about framing, light, movement, lens behavior, and pacing. When you prompt an AI video generator with "a woman walking down a street, cinematic," you are outsourcing every one of those decisions to the model's statistical average. The model will give you what "cinematic" most often means in its training data, which is exactly what everyone else gets.
Prompt engineering, done well, is the practice of taking those creative decisions back. It means describing the shot the way a director would communicate with a cinematographer: subject and action first, then environment, then camera behavior, then light, then texture and grade. This guide walks through each layer of that process, with concrete phrasing you can adapt, a repeatable structure, and the most common failure points to avoid.
The Anatomy of a Cinematic Prompt
A strong video prompt is not one long poetic sentence. It is a stack of clearly separated variables the model can parse. Think of it as a shot specification rather than a description. The core layers, in the order that tends to work best, are:
- Subject: who or what is in frame, described specifically (age, build, wardrobe, material, mood) rather than vaguely.
- Action: what happens during the clip, expressed as a single continuous motion, not a sequence of events.
- Environment: where it happens, with enough spatial detail for the model to ground the subject.
- Camera: shot size, angle, lens character, and any movement.
- Lighting: source, direction, quality, and color.
- Style and grade: the visual treatment — film stock feel, color palette, grain, era references.
A practical formula looks like this: subject + action + environment + camera + lighting + style. For example: "A weathered fisherman in a yellow raincoat coiling rope on a dock at dawn, medium close-up, handheld camera with subtle sway, 35mm lens look, soft overcast light from the left, muted teal-and-gray palette, shallow depth of field."
Notice what this prompt does that "cinematic fisherman video" does not. It locks the shot size so the model cannot drift to a wide establishing frame. It specifies one continuous action, which protects temporal coherence. It names the light source and direction, which is the single biggest lever on perceived production value. Every layer you define is a layer the model cannot fill with its default average.
Speaking the Camera's Language in Text
The fastest way to upgrade your output is to borrow vocabulary from real cinematography. Models trained on footage and shot descriptions respond strongly to these terms because they compress a huge amount of visual information into a few words.
Shot size and framing
Use precise framing terms instead of adjectives like "nice" or "epic": extreme wide shot, wide shot, medium shot, medium close-up, close-up, extreme close-up, over-the-shoulder, insert shot. Each one constrains the composition dramatically. "Close-up of hands kneading dough, flour dust in the air" will look intentional; "baking bread, cinematic" will drift.
Lens and depth cues
Terms like 24mm, 35mm, 50mm, 85mm, wide-angle, telephoto compression, shallow depth of field, deep focus, rack focus, bokeh, and macro all steer how space is rendered. A telephoto prompt compresses background layers; a wide-angle prompt exaggerates foreground geometry. If faces look plasticky, specifying a natural 50mm portrait look with soft falloff often helps more than adding the word "realistic."
Camera movement
Name the movement and its quality: slow dolly-in, static tripod shot, handheld with subtle shake, smooth crane rise, tracking shot moving parallel to the subject, whip pan, steadicam glide. Two tips matter here. First, one move per clip — a dolly-in that also orbits and cranes usually produces warping. Second, describe the quality of the movement ("slow, almost imperceptible push-in") because the model defaults to exaggerated motion when given only a verb.
Angles and height
Low angle, high angle, eye level, Dutch tilt, top-down, worm's-eye view. Angle carries emotional subtext, and models render it reliably. A low angle on a subject reads as power; a high angle reads as vulnerability. If you care about tone, specify the angle rather than hoping tone words alone will do it.
Lighting: The Highest-Leverage Layer
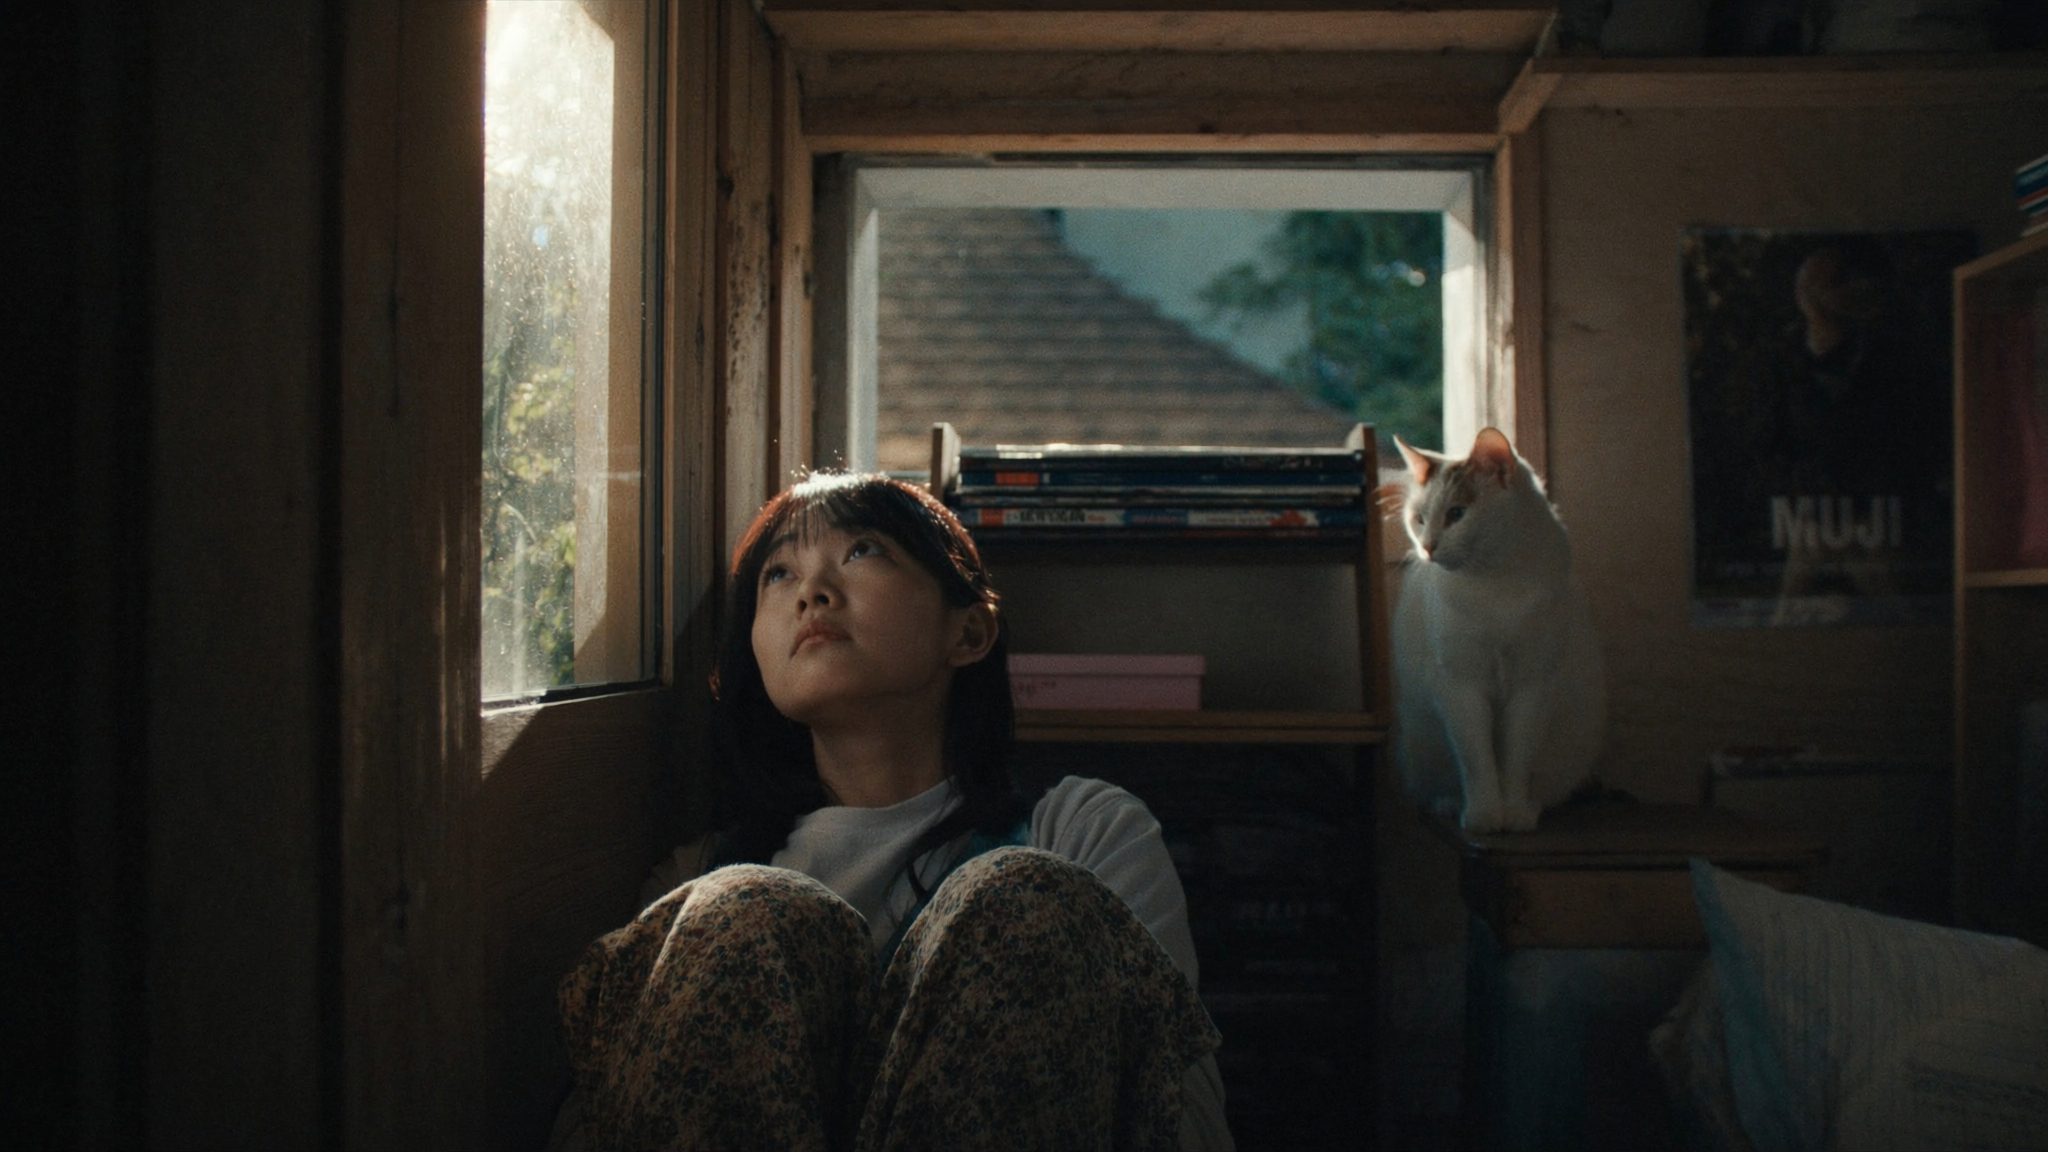
If you change only one habit, make it this: always specify light. Nothing separates amateur-looking output from cinematic output faster than lighting language, because lighting determines contrast, shadow shape, color mood, and how the subject separates from the background.
Useful lighting vocabulary includes:
- Direction: backlit, rim-lit, side-lit, front-lit, top-lit, three-quarter key light.
- Quality: soft diffused light, hard directional light, dappled light through leaves, shafts of window light, practical lights in frame.
- Time and source: golden hour, blue hour, overcast, moonlight, neon signage, candlelight, single practical lamp.
- Contrast mood: high-key and airy, low-key and moody, chiaroscuro, silhouette.
Pair lighting with a color grade reference for a complete look: "warm amber practicals against cool blue shadows," "desaturated palette with lifted blacks," "teal and orange grade, filmic contrast," "Kodak Portra color response, gentle grain." These phrases pull the render toward a coherent, graded look instead of the flat, evenly-lit default that instantly reads as synthetic.
A useful test: read your prompt and ask whether a cinematographer could light the scene from your description alone. If the lighting section is missing or generic ("good lighting"), the model will improvise, and improvised light is the number one tell of AI-generated footage.
Controlling Motion and Temporal Coherence
Video generation adds a dimension image models do not have: time. The hardest technical problems are temporal coherence (things staying consistent across frames) and plausible motion. Your prompt can reduce both problems.
Specify one continuous action. "She pours coffee, steam rising" is coherent. "She wakes up, gets dressed, and leaves the apartment" asks the model to perform three scene changes in a few seconds, which almost guarantees morphing. Break narratives into shots and generate them separately, exactly as a film production would.
Describe motion speed and character. Slow motion, real-time, time-lapse, gentle breeze, rapid movement, fluid motion, stuttering handheld. Speed adverbs matter: "slowly turns her head" produces far cleaner results than "turns her head," because slow motion gives the model more frames per unit of action to keep the subject consistent.
Anchor unstable elements. Faces, hands, text, reflections, and complex limb interactions are the classic failure zones. Reduce their screen time, keep them partially occluded when possible, or use closer framing with slower motion. If you need a specific on-screen object, keep it simple and large; fine printed text and intricate logos will usually degrade.
Use camera stillness as a tool. A locked-off static shot with only the subject moving is the most coherent generation mode available. When you are iterating on a character's appearance or testing a lighting setup, start with a static camera, confirm the look, then add movement in a refined generation pass.
A Layered Prompt Framework You Can Reuse
Different creators structure prompts differently, but a four-layer framework keeps long prompts readable for you and parseable for the model:
- Scene layer: subject, wardrobe, action, environment. This is the "what."
- Camera layer: shot size, angle, lens, movement. This is the "how it is framed."
- Light and grade layer: source, direction, quality, palette, grain. This is the "how it feels."
- Constraint layer: negative prompts, aspect ratio, duration, realism anchors. This is the "what to avoid."
Writing in that order produces prompts that read like shot briefs. Here is the framework applied end to end:
"A jazz trumpeter in a wrinkled white shirt performing alone in an empty rehearsal room, sweat on his forehead, slowly leaning into a high note. Medium close-up, eye level, 85mm lens look, shallow depth of field, slow dolly-in. Warm tungsten practical light from a floor lamp camera-left, deep shadows behind him, dust motes in the beam, low-key chiaroscuro, subtle film grain. No distorted hands, no extra fingers, no text overlays, no morphing."
Every clause earns its place, and if the output misses, you know exactly which layer to adjust. That diagnosability is the real payoff of structured prompting: iteration becomes targeted editing instead of random re-rolling.
Negative Prompting: Removing Cinematic Flaws Before They Render
Most platforms support negative prompts — instructions describing what the model should avoid. Used well, they are a quality filter; used carelessly, they can strip your scene of useful content. A few principles:
- Target known failure modes, not aesthetics. Common negatives include warped hands, extra fingers, melting faces, flickering, duplicated limbs, watermark, text overlay, jittery motion, and sudden background shifts.
- Avoid contradiction. If your main prompt says "shallow depth of field with bokeh," do not negative-prompt "blur" — you will fight yourself.
- Keep the negative list short and specific. Long negative lists dilute attention across dozens of constraints. Six to ten targeted negatives outperform a wall of banned words.
- Add anti-CG anchors when needed. Phrases like "no plastic skin, no video-game rendering, no oversaturated colors" push output toward photographic realism, though on some models these work better in the positive prompt as "photorealistic skin texture, natural color science."
Treat negatives as the final trim pass. Get the scene right in the positive layers first, then remove recurring artifacts.
Adapting Your Prompt to Different Models
No two video generators weigh prompt language identically. Photorealism-focused models tend to reward dense, technical descriptions with lens and film-stock references. Stylized and animation-leaning models respond better to strong art-direction phrases — "Studio Ghibli-inspired watercolor background," "stop-motion claymation texture," "graphic novel cel shading" — and can look worse when overloaded with photographic terminology.
Practical adaptation habits:
- Run a controlled comparison. Take one canonical prompt and run it unchanged across the models you have access to. Note which model honors camera movement, which holds faces best, and which renders lighting direction most faithfully. Keep those notes as your personal routing table: realism work goes to one model, stylization to another, fast drafts to a third.
- Match prompt length to the model. Some models attend strongly to early tokens and degrade on very long prompts; others handle layered detail well. If output ignores your camera layer, try moving it closer to the front.
- Respect each model's grammar. Some platforms respond well to comma-separated tag-style prompts; others prefer natural sentences. If a model was trained heavily on caption-style text, full sentences with connectors ("as the camera slowly dollies in...") often integrate motion more smoothly.
- Calibrate one variable at a time. When testing a new model, change only the lighting layer, regenerate, then change only the movement layer. This isolates cause and effect and teaches you the model's behavior in a handful of runs.
A Full Workflow: From Concept to Shot List
Cinematic results come from a process, not a single prompt. Here is a workflow that scales from a single social clip to a multi-shot sequence:
- Write the shot intent. One sentence per shot: what the audience should feel and learn. Example: "Establish isolation — a lone figure in a vast, cold landscape."
- Build the master prompt. Draft one detailed prompt for your hero shot using the four-layer framework. This is your calibration prompt.
- Generate low-cost drafts. Run short durations at lower resolution, static camera, to lock subject, wardrobe, and lighting. Iterate only the failing layer.
- Add motion incrementally. Once the still composition is right, introduce one camera move and confirm coherence survives. If it does not, slow the move down or reduce its distance.
- Expand into a shot list. Derive the remaining shots by varying one layer at a time from the master prompt — change shot size for coverage, change angle for emphasis, keep lighting constant for continuity. Reusing the same lighting and grade language across shots is what makes a sequence feel like one film rather than a slideshow.
- Assemble and grade in the edit. Bring clips into your editor, trim to rhythm, apply a consistent color grade and grain layer across all shots, and add sound design. A shared grade and a good sound bed do more for perceived production value than any single generation.
- Archive winning prompts. Keep a personal library of prompts organized by look ("moody low-key interior," "golden-hour exterior wide"). Over time this library becomes your fastest path to consistent output.
Common Mistakes That Keep Output Looking Amateur
Almost every disappointing result traces back to one of these habits:
- Stacking multiple scenes into one prompt. One shot, one prompt. Sequences are an editing problem, not a prompting problem.
- Adjective inflation. "Stunning, breathtaking, ultra-HD, masterpiece" adds noise without information. Replace each adjective with a concrete specification it was pretending to describe.
- Ignoring aspect ratio and duration. A vertical clip prompted like a widescreen film will crop badly. State the frame from the start and compose for it.
- Overmoving the camera. Two or more simultaneous moves multiply warping risk. Pick one.
- Trusting the first result. Professionals iterate. Budget for five to ten variations on a hero shot and treat the first generation as a diagnostic, not a deliverable.
- Skipping sound. Silent AI footage reads as unfinished. Even simple ambient sound and a score transform perceived quality instantly.
Frequently Asked Questions
How long should a cinematic video prompt be? Long enough to cover all six layers — typically 60 to 120 words. If you cannot cut anything without losing control, it is the right length. If it contains atmosphere words but no camera or lighting layer, it is too short.
Should I reference real films or directors in prompts? Style references like "in the style of a 1970s paranoid thriller" can effectively pull grading and composition toward a coherent aesthetic. They work best as the final style clause, not as a substitute for specifying shot and light. Note that some platforms discourage naming living artists; era and genre references are safer and nearly as effective.
Can I keep the same character consistent across shots? Partially. Repeat identical wardrobe, hair, and physical descriptors verbatim across prompts, keep lighting constant, and consider tools that support image-to-video or reference-image conditioning, which anchor identity far better than text alone.
Why does my footage flicker or morph? Usually because the prompt demands too much change per second: fast action, multiple actions, big camera moves, or fine detail like text. Slow the motion, simplify the action, and shorten the duration per generation.
Do camera terms really work, or is it placebo? They measurably work on well-trained models because shot vocabulary is dense in captioned footage data. Run an A/B test yourself: the same prompt with and without "medium close-up, shallow depth of field, slow dolly-in." The constrained version will compose with visible intent.
What is the single fastest improvement for a beginner? Add a lighting clause. One line — "backlit by late-afternoon sun, warm rim light, deep soft shadows" — will raise perceived production value more than any other single edit to your prompts.
Cinematic AI video is not a lottery. It is shot design expressed in language: define the frame, command the light, choreograph one clean motion, and remove the known flaws. Creators who prompt like directors will consistently outperform those who prompt like searchers — regardless of which generator they use.
