
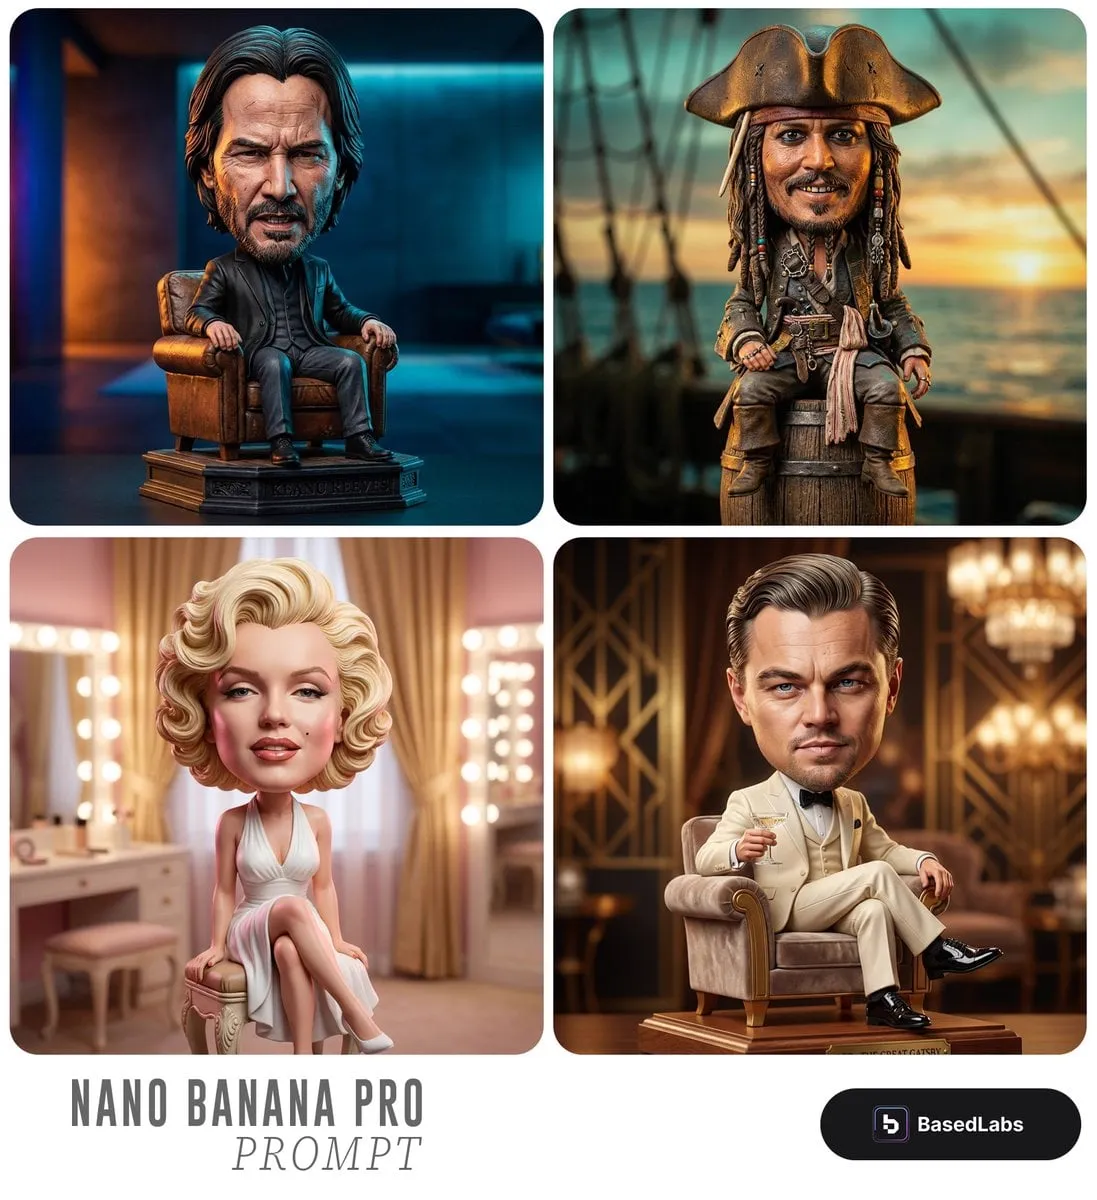
Short-form video rewards speed, but it punishes inconsistency. A single scroll-stopping frame can carry a clip, yet a series of clips with mismatched lighting, faces, and color will lose an audience faster than a bad hook. That tension is exactly why text-to-image generation has become the quiet engine room of modern video production. You brainstorm in words, you output frames, and those frames become the raw material for motion.
This guide walks through a complete, tool-agnostic workflow: how to write prompts that survive editing, how to keep a series visually coherent, how to choose between competing image models, and how to hand a still frame to a video model without losing the look you worked for. It is written for creators who publish regularly and need a repeatable process rather than a one-off experiment.
Why Prompt-to-Image Pipelines Became the Backbone of Short-Form Video
The economics of short-form content changed the moment image generation became good enough to storyboard with. In the past, a creator who wanted a stylized scene had three options: shoot it, license it, or settle for stock footage that looked like everyone else's. Each option carried a cost measured in money, time, or originality.
Generated frames collapse that trade-off. A concept that would have needed a location scout, a costume, and a lighting rig can now be explored in twenty variations before lunch. More importantly, the exploration itself becomes useful content. Prompt experiments, side-by-side model comparisons, and behind-the-scenes breakdowns of how a frame was made are all formats that perform well in feeds.
The practical shift is that images are no longer the final product. They are intermediate assets. A single well-crafted frame can become a thumbnail, a background plate, an animated insert, a title card, and a loop point in a longer sequence. That multiplicity is what makes an efficient image pipeline worth building, and it is also why sloppy prompts compound: one weak frame can contaminate five downstream assets.
The Anatomy of a Prompt That Survives Editing
Most prompt advice focuses on making an image look impressive in isolation. The better question is whether the image still works after it has been cropped to a vertical aspect ratio, darkened by a caption bar, and animated with a slight push-in. Prompts that pass that test share a recognizable structure.
Subject, Action, and Framing
Lead with what is in the frame and what it is doing. "A ceramicist" is a subject. "A ceramicist lifting a wet bowl from a spinning wheel" is a shot. The action gives the video model something to animate and gives you a natural edit point. Framing belongs in the same sentence: wide environmental shot, medium portrait, extreme close-up on hands. Naming the framing early prevents you from generating beautiful images that have nowhere to put text.
Camera and Lens Language
Borrow the vocabulary of photography, because image models were trained on it. Focal length, aperture, and camera position all produce visible differences. A 24mm wide angle exaggerates space and depth; an 85mm portrait compresses features and flatters faces; a macro lens turns texture into subject matter. Terms like "low angle," "over-the-shoulder," and "dutch tilt" give you editorial control that adjectives like "epic" never will.
Light, Color, and Mood
Lighting is the single highest-leverage clause in any prompt. Specify direction (backlit, side-lit, overhead), quality (soft, hard, diffused), and time of day (golden hour, blue hour, overcast noon). Then anchor color explicitly: warm amber and teal, desaturated pastels, high-contrast monochrome. If a series needs to feel cohesive, this clause should be nearly identical across every prompt in that series.
Style Anchors and Reference Notes
Style descriptions work best when they describe technique rather than imitate a named artist. "Editorial fashion photography with shallow depth of field and muted earth tones" is more controllable than a proper noun, and it avoids legal and ethical ambiguity. If you do use references, keep them to movements, eras, or materials: brutalist concrete, 1970s print advertising, wet-plate collodion texture.
What to Leave Out
Negative space in a prompt is intentional. Avoid stacking contradictory instructions, avoid three adjectives where one precise one will do, and avoid vague intensifiers. If a frame keeps coming back with an unwanted element, describe the desired state rather than listing what you do not want, because many models handle affirmations more reliably than negations.
Building a Repeatable Image Workflow
A workflow beats inspiration because it produces usable output on a schedule. The following four stages compress into roughly an hour once they become habitual.
Stage 1: Lock the Concept Before You Write a Prompt
Write one sentence describing the video's promise, and one sentence describing how it should feel. Everything generated afterward must serve those two sentences. This sounds like obvious advice, but the most common failure mode in AI-assisted production is generating attractive images that do not belong to the same project.
Stage 2: Build a Shot List, Not a Prompt List
List the shots you need in editing order: establishing frame, subject introduction, detail insert, reaction, closing frame. This list is your contract with yourself. It prevents the endless-generation spiral where you produce fifty variations of the opening shot and never reach the ending.
Stage 3: Generate in Batches, Select Ruthlessly
Run four to eight variations per shot, then stop. Pick one primary and one backup, and move on. Keep a rejection note for each discard explaining why it failed, because patterns emerge quickly: repeated anatomy problems, repeated composition clashes, repeated color drift. Those notes tell you which prompt clause needs rewriting.
Stage 4: Grade Before You Animate
Do color and contrast adjustments on the still image, not on the finished video. Still images are cheap to iterate, and a corrected frame gives the video model a cleaner starting point. Crop to your target aspect ratio at this stage so you can verify that the composition survives vertical framing.
Keeping a Series Visually Consistent
Consistency is what separates a channel from a collection of unrelated clips. Three kinds of continuity matter most.
Character Continuity
Keep a written character sheet: age range, hair, wardrobe, distinguishing features, and one signature accessory. Reuse the exact same descriptive phrasing every time. When a model supports reference images or multi-image conditioning, feed two or three approved frames rather than relying on text alone. Never introduce a new detail mid-series unless the story requires it.
Style Continuity
Freeze a style clause and treat it as immutable. If your clause reads "soft diffused daylight, muted sage and clay palette, 35mm film grain," do not casually swap in "vibrant" for one shot. One outlier frame will read as an error, not a creative choice.
Palette and Texture
Build a small reference palette of five to seven colors and sample from it deliberately. Texture is equally load-bearing: grain, halation, paper stock, and dust all signal a shared visual world. When in doubt, match texture rather than subject matter, because viewers notice surface continuity before they notice narrative continuity.
Matching the Image Model to the Shot
Different models excel at different jobs, and using one for everything is the fastest route to mediocre output. The table below outlines general decision criteria you can apply regardless of which tools you subscribe to.
| Shot type | What to prioritize | Practical approach |
|---|---|---|
| Photoreal human portrait | Skin texture, eye detail, natural asymmetry | Use a photoreal-tuned model, generate at higher resolution, plan for minor retouching |
| Product or object hero | Edge fidelity, controllable lighting, reflections | Choose a model with strong prompt adherence for materials and studio lighting terms |
| Stylized illustration | Line weight, flat color control, repeatability | Prefer models that respond well to medium-specific language (gouache, risograph, ink wash) |
| Environment or establishing shot | Depth, scale, atmospheric perspective | Generate wide, then crop; request consistent horizon height across the series |
| Text-heavy graphic | Legibility, layout discipline | Generate the image without text and add typography in a design tool |
Two practical rules follow from this. First, generate at the highest resolution that is practical, then downscale, because detail survives downscaling but never survives upscaling. Second, keep a shortlist of two models per category so you are never blocked by an outage or a disappointing update.
From Still Image to Motion: Handing Frames to a Video Model
The moment an image becomes a clip, three new variables appear: duration, motion direction, and temporal coherence. Handling them well is mostly about choosing the right starting frame.
Choose Frames That Imply Movement
A still that already contains directional cues animates beautifully: hair mid-swing, fabric in motion, a hand reaching, water mid-splash. A static symmetrical portrait gives the model almost nothing to work with, which is why those clips often end up as an unnatural head turn.
Describe Motion, Not Story
Motion prompts should cover camera behavior and subject action, in that order. "Slow dolly in, subject turns slightly toward camera, steam rising from cup" gives a video model a set of physical instructions. "A powerful emotional moment" gives it nothing.
Control Pacing With Clip Length
Short clips of two to four seconds cut together more convincingly than one long generated shot. Treat each generated clip as b-roll and assemble the rhythm in the edit. This also hides temporal artifacts, since small inconsistencies read as camera movement rather than errors.
Check the First and Last Frame
If your video model supports keyframe conditioning, use the last frame of clip A as the first frame of clip B. This technique, sometimes called frame chaining, produces far more believable multi-shot sequences than prompting each clip independently.
Aspect Ratios, Safe Zones, and Export Hygiene
Vertical formats dominate short-form feeds, which changes composition rules. Keep the subject's eyes in the upper third, avoid placing critical detail in the bottom quarter where captions and interface elements live, and leave roughly ten percent of the frame as margin on all sides for platform cropping differences.
Export hygiene matters more than most creators expect. Standardize on one resolution and one frame rate per project, use a high bitrate for intermediate renders, and avoid repeated re-encodes. If you plan to animate a frame, export it as a lossless PNG rather than a compressed JPEG, because compression artifacts become visible motion shimmer once a video model starts interpreting them as detail.
Common Mistakes and How to Fix Them
Anatomy problems in hands and eyes. Reduce the number of subjects in frame, specify hand position and action, and increase resolution. If the problem persists across a whole batch, the model is the issue, not the prompt.
Color drift across a series. Move lighting and palette language into a fixed template you copy verbatim. Drift is almost always caused by paraphrase.
Over-stuffed prompts. If a prompt exceeds roughly sixty words, split it into two shots. Detail belongs in the shot list, not in a single sentence.
Inconsistent backgrounds. Specify horizon line, ground material, and background depth in every prompt. Backgrounds are where continuity breaks first because creators focus on the subject.
Generating final assets too early. Iterate at low resolution, approve composition, then commit to the final render. High-resolution generations are for approved shots only.
Neglecting the edit. No image pipeline fixes weak pacing. If a sequence feels flat, cut two seconds out of it before regenerating anything.
A 60-Minute Production Sprint
A workable rhythm for a single short-form piece looks like this. Spend the first ten minutes writing the one-sentence promise, the shot list, and the frozen style clause. Use the next twenty minutes to generate four to eight variations of each shot, selecting one primary per shot and discarding the rest without regret. Spend ten minutes cropping, grading, and checking vertical safe zones. Use the final twenty minutes to generate motion clips from the approved frames, chain them for continuity, and assemble a rough cut with music and captions.
The value of a fixed sprint is that it makes the process measurable. Once you know a piece takes an hour, you can decide whether a concept deserves three sprints or none, and you stop treating every idea as equally worth pursuing.
FAQ
How many prompt variations should I generate per shot? Four to eight. Fewer than four rarely explores enough of the space; more than eight usually produces diminishing returns and decision fatigue.
Should I write prompts in English if my audience speaks another language? Most image and video models perform best with English prompts because of training data distribution. Write prompts in English, then handle captions, voiceover, and on-screen text in your audience's language.
Can one image style work across several platforms? Yes, if you standardize on the strictest aspect ratio first and letterbox or crop outward from there. Build the vertical version first, since it is the hardest constraint.
How do I stop characters from changing between shots? Freeze descriptive phrasing word for word, use reference images when available, and keep wardrobe and lighting clauses identical across the series.
Is it worth generating at maximum resolution every time? No. Iterate low, approve, then render high. Maximum resolution everywhere slows you down and tempts you to keep mediocre shots because they took effort.
What is the best way to learn prompt craft quickly? Run controlled experiments: change exactly one clause between generations and compare results. Structured comparison teaches more in an afternoon than weeks of unstructured tinkering.
A reliable image pipeline is less about finding a magic prompt and more about removing variance. Freeze the style clause, work from a shot list, grade before animating, and chain frames for continuity. Do those four things consistently and your output stops looking like a pile of experiments and starts looking like a body of work.
