
What "Prompt to Picture" Really Means in an AI Video Pipeline
A prompt is not a film. It is a compressed instruction that a model expands into pixels, and that expansion rarely matches the movie playing in your head on the first attempt. The phrase prompt to picture describes the discipline of controlling the expansion: deciding what the frame must contain, generating a still that proves the idea, then animating it so composition, identity, and intent survive the transition into motion.
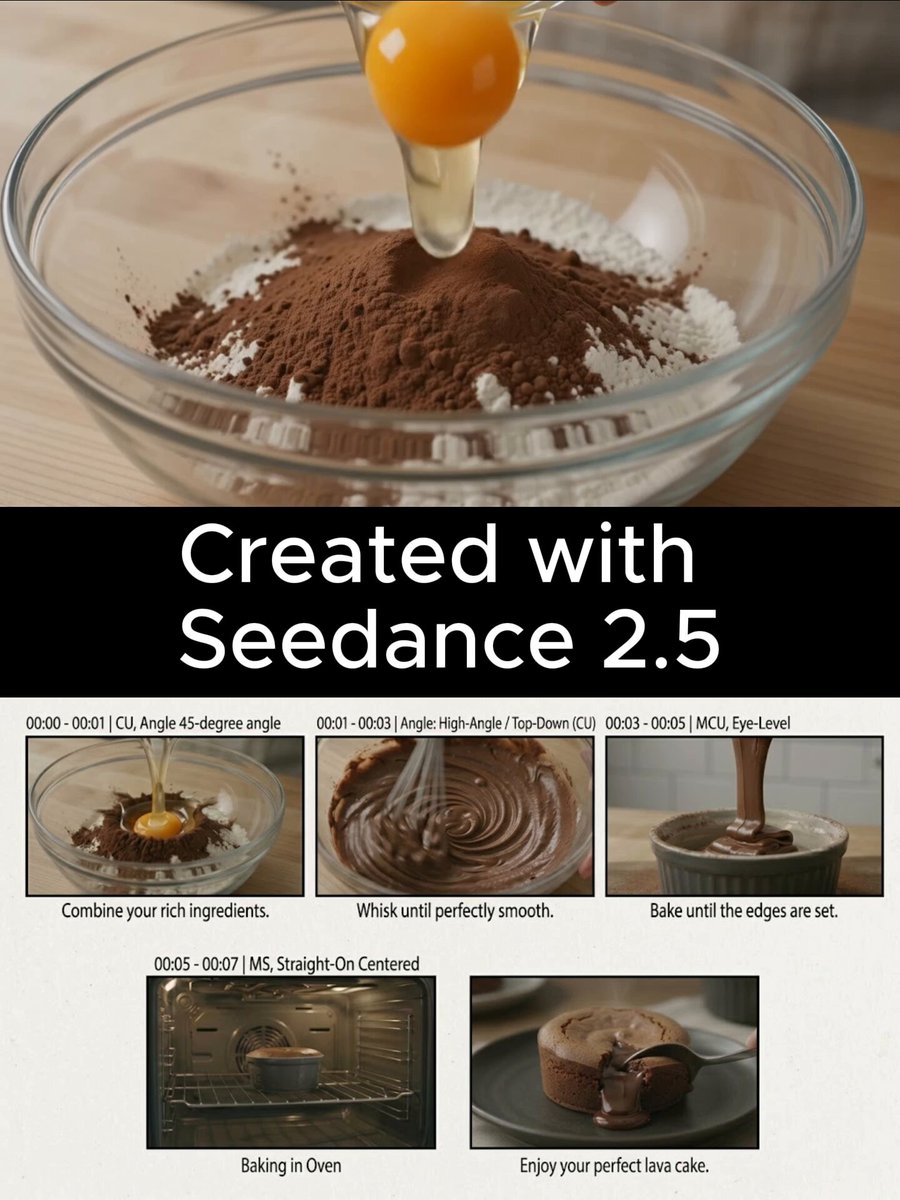
Generative video tooling has settled into two broad families. The first is single-shot text-to-video, where a paragraph of prose produces a few seconds of movement. The second is a layered pipeline: story beats, shot list, keyframe images, image-to-video animation, then editing, sound design, and color. The layered approach feels slower at the beginning and is dramatically faster overall, because mistakes get caught when they cost a rewritten sentence instead of a full re-render.
Four stages matter in almost every project:
- Intent — what the shot must communicate emotionally and narratively.
- Still — a generated image that locks composition, casting, lighting, and palette.
- Motion — an animation pass that adds camera behavior, performance, and physics.
- Assembly — cutting shots together with sound and grade so the sequence reads as one world.
Most disappointing AI video comes from collapsing these stages into one. The fix is not a better prompt. It is a better pipeline.
Layer One: Story Architecture Before Any Generation
Cinematic coherence starts on paper. Before you open a generative tool, write the sequence as a beat sheet: what changes between the first frame of the scene and the last. A character who begins the scene hopeful and ends it frightened needs at least one visual marker of that shift — posture, light, distance from camera, or the space around them.
From the beat sheet, build a shot list. A useful shot list has six columns:
| Column | What it captures |
|---|---|
| Shot number | Editorial order, not generation order |
| Purpose | The single job this shot performs |
| Framing | Wide, medium, close, insert |
| Camera move | Static, push in, pull out, pan, tracking |
| Duration | Target seconds on screen |
| Continuity notes | Wardrobe, props, time of day, weather |
A three-shot scene is enough to learn the craft: an establishing wide, a medium that carries dialogue or reaction, and a close insert that lands the emotional beat. Writing purpose into every row prevents the most common failure in AI video — beautiful shots that do not belong to the same film.
The shot list also tells you where to spend effort. If a shot is four seconds long and plays under narration, image quality matters more than motion complexity. If a shot is a hero moment held for eight seconds, motion quality matters more than a perfect still. Budget attention accordingly, not evenly.
Layer Two: Designing Keyframes That Survive Motion
A keyframe is the still image your animation pass will bring to life. Treat it as a contract: whatever is true in the keyframe tends to remain true in the clip, and whatever is ambiguous in the keyframe tends to wobble.
First-to-last frame control
Many modern video models accept both a starting frame and an ending frame. This is the single most powerful storytelling control available today, because it turns generation into interpolation between two intentional compositions. Instead of asking a model to invent a journey, you define the departure and the destination and let it animate the distance between them.
Practical uses:
- Reveals — start on a closed door, end on the room beyond.
- Transformations — start on a rain-soaked street, end on the same street at dawn.
- Performance beats — start with a character's back to camera, end on their face.
Generate the last frame first when the ending is the point of the shot. It is much easier to build backward toward a strong image than to hope a strong image appears at the end of a random animation.
Composition rules for generated stills
- Leave negative space in the direction the camera will travel. A push-in needs room to push into.
- Avoid faces smaller than roughly a tenth of the frame height unless the shot is intentionally a wide. Small faces drift.
- Keep hands visible and simple. Complex finger arrangements are still the most fragile detail in generative video.
- Match horizon lines and vanishing points between shots that share a location.
- Lock aspect ratio at the keyframe stage. Cropping 16:9 footage into a vertical frame after the fact destroys composition that took effort to build.
Layer Three: Character, Prop, and Lighting Consistency
Consistency is not a single feature; it is a habit. Across a sequence you are managing at least five continuities: face, wardrobe, props, lighting direction, and color palette.
Reference sheets and multi-image fusion
Build a reference sheet for every recurring character: a neutral front view, a three-quarter view, a profile, and one expression. Multi-image fusion techniques — feeding several references into a single generation instead of one — let a model average identity features rather than guessing from a single angle. The same logic applies to locations. A reference shot of a room establishes wall colors, window placement, and the direction light enters.
When identity matters, keep the model, seed, and reference set identical between shots. Changing any one of those variables between shots is the most common cause of a character who looks like a sibling rather than the same person.
Wardrobe, palette, and lens continuity
Pick a limited palette — three dominant colors plus one accent — and write it into every prompt. It sounds like an aesthetic choice, but it is really a technical one: models drift toward generic color, and a named palette pulls them back. Likewise, fix a lens language. If the scene was established with a wide lens, do not suddenly generate a compressed telephoto close-up; the perceptual jump reads as an error even to viewers who cannot name it.
Lighting direction is the sneakiest continuity. A character lit from the left in shot one and from the right in shot two will feel wrong without anyone knowing why. Note the light source in the shot list and repeat it verbatim.
Layer Four: Directing Motion With Cinematic Language
Once you have a keyframe, motion comes from written direction. Vague verbs produce vague movement. Use camera terminology that a cinematographer would recognize and that a model has seen thousands of times in captions.
Camera directives that actually work
- Slow dolly in, shallow depth of field, subject remains centered
- Locked-off static shot, subtle handheld breathing
- Crane up revealing the city skyline behind the subject
- Slow arc left around the subject, background parallax clearly visible
- Rack focus from foreground object to background figure
Combine exactly one camera move with exactly one subject action. Two moves plus two actions is where motion coherence collapses.
Motion budget and clip length
Every model has a motion budget: a quantity of change it can render before artifacts appear. Fast action, crowded frames, and long durations all spend that budget. Shorten clips when motion is complex, and lengthen them when the shot is a slow push across a still environment. Most cinematic work lives comfortably between three and six seconds per shot.
Negative instructions help here too. Naming what must not happen — no camera shake, no morphing hands, no background pedestrian changes — is often more effective than adding another positive detail.
Choosing the Right Model for Each Shot
Different models excel at different jobs, and mixing them per shot is normal in professional workflows. Rather than chasing a single best tool, classify each shot and match it to a model personality.
| Shot need | Model personality to look for |
|---|---|
| Fast concept draft | Low-latency text-to-video, resolution secondary |
| Hero motion shot | High-fidelity image-to-video with strong physics |
| Photoreal keyframe | Image model with strong lighting and skin rendering |
| Stylized animation | Model trained heavily on illustration or 3D looks |
| Long continuous take | Model with extended-duration or interpolation support |
| Precise camera control | Model exposing trajectory, depth, or motion controls |
Practical selection rules:
- Draft on the cheap, finish on the strong. Use fast models to test composition and timing, then re-render approved shots on a high-fidelity model.
- Read the failure, not the prompt. If hands dissolve, the model is weak at fine detail. If lighting flattens, the model is weak at photoreal light. Swap models rather than rewriting endlessly.
- Keep a personal scorecard. Score five clips per model on identity, physics, camera obedience, and texture. That table will outperform any opinion you read online.
The best model is the one that matches your shot's dominant risk.
Assembling the Cut: Sound, Pacing, and Post
AI video is silent, weightless, and slightly too clean. Assembly is where it becomes cinema.
Editing for rhythm. Cut on motion rather than on stillness. If a character is walking, cut in the middle of a stride. If a camera is pushing in, cut while it is still moving. Matching motion across a cut hides imperfections and creates momentum.
Sound design. Layer three tracks under every scene: ambience, spot effects, and music. Ambience (room tone, rain, distant traffic) does more for realism than any render setting. Spot effects — footsteps, cloth, a door latch — sell contact with the world. Music carries emotion but should sit under the ambience, not over it.
Color and finishing. Apply one grade across all shots before fixing individual ones. A shared LUT or look-up approach unifies mismatched renders faster than any per-shot correction. Slight grain and a gentle contrast curve also reduce the "too clean" quality that makes generated footage feel artificial.
Temporal smoothing. Where motion is choppy, interpolation can help — but use it sparingly. Aggressive interpolation produces soap-opera results and ghosting around edges.
Vertical and horizontal deliverables. If you need both, reframe rather than crop: regenerate or re-stage key shots for the vertical frame so the subject is not trapped in a letterboxed band.
Common Mistakes and How to Fix Them
| Symptom | Likely cause | Fix |
|---|---|---|
| Character looks different each shot | Different references, seeds, or model versions | Lock the reference set and reuse seeds |
| Clip feels weightless | No ground contact, no motion blur, no sound | Add ambience, footstep effects, and slower moves |
| Composition drifts mid-shot | Too much motion for the frame | Shorten the clip or simplify the camera move |
| Everything looks like stock footage | Generic prompts, no palette, no lens language | Name palette, lens, and lighting direction explicitly |
| Shots do not feel like one film | Inconsistent grade and pacing | Single grade pass, consistent cut-on-motion rule |
| Hands and small details melt | Model weakness at fine detail | Reframe wider, or switch to a stronger model for that shot |
The meta-mistake is treating generation as the whole job. Generation is one department. Story, continuity, motion, sound, and grade each own a share of the result.
A Repeatable Production Sprint
When you are learning, a fixed sprint beats open-ended experimentation. Try this structure across a single week, roughly ninety minutes per session:
- Session one — story. Write a one-page beat sheet and a shot list of eight to twelve shots for a thirty-second piece.
- Session two — keyframes. Generate stills for every shot at final aspect ratio. Approve composition before approving detail.
- Session three — references. Build character and location reference sheets, then regenerate any keyframe whose identity drifted.
- Session four — motion. Animate in order of narrative importance. Compare two models on the hero shot.
- Session five — editing. Build a rough cut with temp music. Cut on motion. Watch it three times without pausing.
- Session six — sound. Add ambience and spot effects. Lower the music until dialogue or narration sits clearly.
- Session seven — grade and export. Apply one look, then export every required aspect ratio.
Repeat the sprint with a new story rather than polishing the old one. Speed comes from repetition, and each pass teaches you something about which controls actually move the needle.
Frequently Asked Questions
How long should an AI-generated shot be?
Three to six seconds is the sweet spot for most cinematic work. Longer clips invite identity drift and physics errors; shorter clips can feel like a slideshow unless you cut on motion.
Do I need an image model if my video tool accepts text prompts?
Not strictly, but image-first workflows give you far more control. Approving a still is faster than approving a clip, so you catch composition and casting problems before paying the cost of animation.
How do I keep the same character across a whole scene?
Lock a reference sheet, reuse the same seed and model version, describe wardrobe and lighting identically in every prompt, and avoid changing aspect ratio mid-scene.
Why does my footage look artificial even when the render is clean?
Usually sound and grade. Add ambience and spot effects, unify the color across shots, and add subtle grain. Cleanliness without texture reads as synthetic.
Should I use one model for everything?
No. Draft on fast models, finish on high-fidelity ones, and keep a personal scorecard of which model handles which shot type best.
What is first-to-last frame control good for?
It is the most reliable way to direct a shot. Define the opening composition and the closing composition, and the model interpolates between them — perfect for reveals, transformations, and performance beats.
How many shots do I need for a thirty-second film?
Eight to twelve is comfortable. Fewer than six feels static; more than fifteen starts to feel like a montage rather than a scene.
The workflow that produces cinematic results is not a secret prompt. It is a sequence: story first, stills second, motion third, and sound always. Build that habit and every tool you pick up afterward becomes easier to direct.
