
Why Prompt-to-Pixel Workflows Became a Real Production Discipline
Turning a sentence into moving footage used to be a demonstration, not a method. You typed something poetic, waited, and received a few seconds of surreal motion that looked impressive in isolation and fell apart the moment you tried to cut it into a sequence. That era is over. The interesting problem today is not whether a model can produce a moving image, but whether a small team can produce a coherent, finished sequence without a studio pipeline behind it.
The shift came from three directions at once. Control mechanisms matured: keyframes, reference images, motion masks, and camera instructions now let you steer composition instead of hoping for it. Model diversity exploded, so different tools specialize in different looks and speeds. And iteration got cheap enough that professionals can treat generation like photography — shoot a lot, select carefully, finish the few frames that matter.
That last point is the mental model worth adopting. You are not asking a machine to make a film. You are directing a very fast, very literal camera operator who needs precise instructions and a clear shot list.
The metric that separates hobbyists from working creators is what you might call the usable second ratio: how many seconds of generated footage survive into the final edit. Beginners often get one usable second out of thirty. Skilled operators flip that ratio, not because they have better tools, but because they plan, prompt, and review in a disciplined loop.
The Anatomy of a Prompt That Renders the Way You Imagine
Most disappointing outputs trace back to vague language. A prompt is a specification, not a wish. The most reliable structure follows a fixed order: subject, action, environment, camera, light, style. Keeping the order consistent makes it easy to change one variable at a time and see exactly what caused the difference.
Here is a worked example:
A ceramicist in her sixties with silver braided hair lifts a wet clay bowl from a spinning wheel, dust drifting in the air, warm window light from the left, slow dolly-in at eye level, 35mm lens, shallow depth of field, muted earthy palette, soft 16mm grain.
Every clause does work. Nothing is decorative. Compare that to "a potter making art, cinematic, beautiful," which gives the model almost nothing to anchor on.
Subject, action, and environment
Ambiguous nouns produce averaged results. "A woman" becomes a generic face. "A woman in her sixties with silver braided hair and a linen apron" gives the model a specific person to render consistently. Describe wardrobe, age, posture, and one distinctive detail.
Actions should be single and continuous. Models handle "picks up a bowl and turns toward the window" reasonably well; they struggle with state changes such as "finishes the bowl, then walks outside, then it starts raining." Split compound ideas into separate clips and join them in the edit.
Camera, lens, and light
Camera vocabulary delivers the biggest perceived quality jump per word. Terms that map cleanly include dolly in, dolly out, truck left or right, crane up, orbit, handheld, whip pan, drone push, and locked-off static. Lens language matters too: wide 24mm for spatial drama, 35 to 50mm for neutral realism, 85mm and above for compressed intimacy, macro for texture.
Lighting is where amateurs leave the most on the table. Name the source and its direction: golden-hour rim light from behind, overcast soft top light, neon practicals on the right side of frame, hard single-source key with deep shadows. Directional language prevents the flat, evenly lit look that reads as artificial.
Style, medium, and texture
"Cinematic" is nearly meaningless on its own. Specify the medium and its artifacts: 16mm film grain, digital anamorphic flare, stop-motion paper texture, cel-shaded animation, watercolor bleed. Add a palette instruction — muted earth tones, high-contrast teal and orange, pastel desaturation — so multiple shots feel like they came from the same world.
Constraint and negative language
Most generators accept a negative field. Use it to name the failure modes you keep seeing: warped hands, text artifacts, morphing faces, jitter, oversaturated skin, duplicated limbs. Positive constraints are useful too. Phrases like "single continuous shot," "no cuts," and "camera remains static" resolve ambiguity about whether the model should move the frame.
Iterating without starting over
Change one clause per run and keep a log: prompt version, seed, model, resolution, notes. When a render is eighty percent right, do not rewrite the prompt. Keep the seed, adjust the failing clause, and re-render. Rewriting everything resets the dice and wastes the progress you already made.
Selecting a Model Family for the Job
There is no single best generator, only families with different trade-offs. Thinking in categories keeps you from overpaying for draft work and under-delivering on hero shots.
Fast draft models are cheap and quick, with lower resolution and looser motion. They are perfect for previz, timing checks, and testing whether an idea reads at all. High-fidelity cinematic models produce richer detail and better physics at higher cost and slower turnaround. Reference-driven and image-to-video models condition on one or more stills, which is the single most effective way to lock a character or product across shots. Specialized tools handle narrow jobs: lip-sync, human performance transfer, background replacement, or animation-specific stylization.
Decision criteria that actually matter:
- Maximum clip length and whether the tool supports extension beyond it
- Keyframe support for first frame, last frame, or both
- Presence of camera controls and motion strength sliders
- How well it accepts multiple reference images
- Output resolution and whether upscaling is built in
- Consistency behavior across repeated runs with the same seed
Match the model to the shot, not the project to a single model. A chase sequence might use a draft model for the wide establishing beats and a high-fidelity model for the two hero close-ups that carry the story.
Story Structure Before Pixels: Shot Lists, Boards, and Duration Budgets
Pre-production does not disappear in AI video; it becomes cheaper. Write a shot list with columns for shot number, description, target duration, model choice, reference images, audio notes, and continuity flags. A one-minute piece typically needs ten to fifteen clips, since most generators produce four to ten seconds per run.
Generate one to two seconds of extra handles on every clip. Handles give you room to trim to the beat, to match action across a cut, and to hide the moment where motion starts to degrade.
Board with stills first
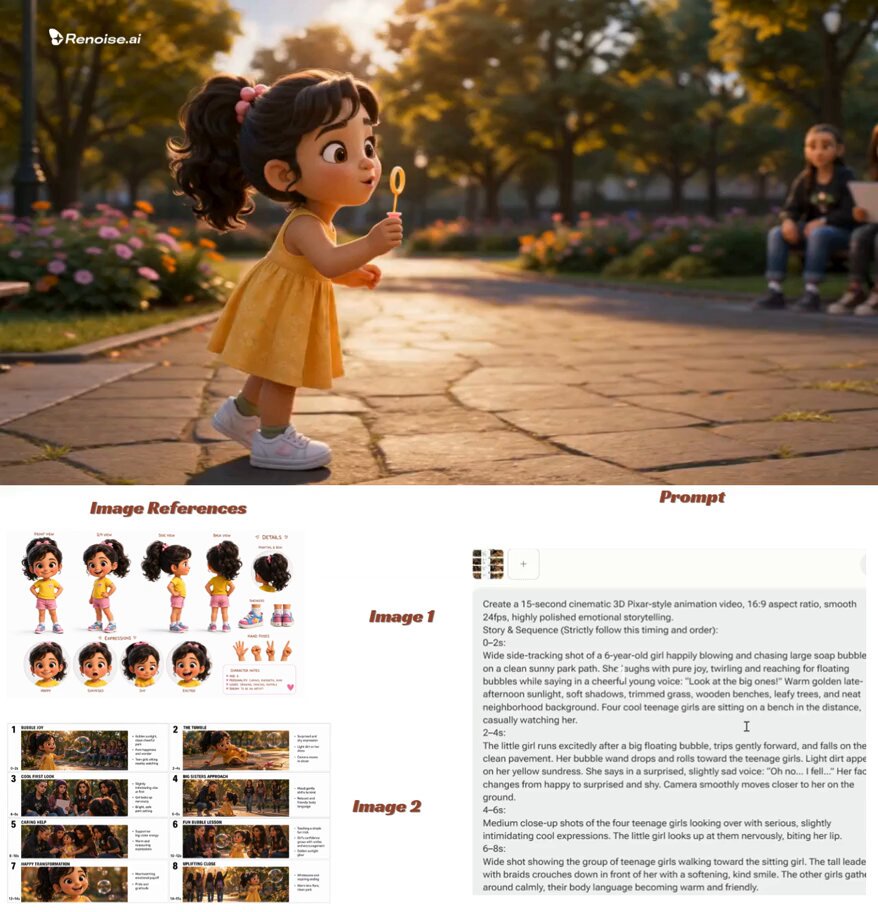
Generate a still frame for every shot before generating motion. Stills are faster, cheaper, and easier to compare side by side, which makes style alignment far simpler. Many video models accept a still as first-frame conditioning, so the still is not throwaway work — it becomes the anchor for the shot.
Write continuity notes
Track wardrobe, prop placement, light direction, time of day, and color temperature in a shared document. In a ten-shot sequence, small drifts — a jacket changing color, light flipping sides between shots — are the fastest way to make an otherwise polished piece feel wrong.
Consistency: Characters, Wardrobe, and World
Consistency is the hardest problem in AI video and the one most worth solving early, because it cannot be fixed in post.
Build reference packs
Create a character pack of four to eight images: front, three-quarter, profile, full body, plus two expression variations. Add two wardrobe images. Multi-image fusion conditions generation on several references at once, so all shots draw from the same visual truth. Never mix images from two different packs in the same shot — the model will average them and produce someone new.
Use keyframes as anchors
Set a first frame to control the opening composition and pose. Set a last frame when you need a controlled landing, especially for smooth camera moves or match cuts. Interpolation between two keyframes is more reliable for continuity than seed locking alone, because it constrains both ends of the motion.
Seeds, style tokens, and naming conventions
Seeds stabilize randomness. Style tokens stabilize look. Naming conventions stabilize your sanity. Use a consistent scheme like project-shot03-v05-seed88421 so you can find any version months later without guessing.
Know when to lock and when to re-roll
Re-roll when the composition is wrong, the subject is wrong, or the motion reads as broken. Lock when the shot meets the minimum bar and move on. Perfectionism on shot two burns the time you need for shot nine.
Directing Motion: Camera Language the Models Understand
Motion is where generated footage most often reveals itself. Two fixes solve most of it: precise movement verbs and restrained motion strength.
Movement vocabulary
Use one movement per clip. Combining "orbit around the subject while dollying in and tilting up" usually produces mush. Pick the movement that serves the story beat and let the cut provide variety.
Speed, easing, and motion strength
Replace vague adverbs with relative ones: slow, gentle, moderate, rapid. If your tool exposes a motion strength parameter, keep it moderate for dialogue and character work, and push it higher only for impact shots or abstract transitions. Excessive strength causes warping at the edges of the frame and rubbery faces.
Plan transitions at generation time
Generate clips with the edit in mind. Match action across the cut, cut on movement, use an occluder wipe, or generate a short bridging clip that carries the eye between two unrelated spaces. Editors can only work with the frames they are given.
Finishing the Sequence: Upscaling, Interpolation, Color, and Sound
Generated clips are raw material. Finishing is what makes them feel like a single piece.
Upscaling and detail recovery
Upscale before frame interpolation in most cases, since interpolation benefits from cleaner source detail. AI upscalers can over-sharpen, so keep an eye on skin texture and fine patterns — a light blend with the original often looks more natural than a full-strength pass.
Frame interpolation and cadence
Many generators output at lower frame rates or with slightly uneven cadence. Interpolating to a consistent 24 fps gives a filmic feel; 30 or 60 fps suits screen content and fast action. Watch for ghosting around fast-moving limbs and reduce the interpolation ratio if artifacts appear.
Grade, grain, and format delivery
Apply a single grade across all clips so color temperature and contrast match. A touch of unified grain hides small differences in source fidelity remarkably well. Deliver in the aspect ratio and codec your platform expects, and keep a high-bitrate master for future re-cuts.
Sound design and lip-sync
Most generated clips are silent, so audio is where a beginner sequence becomes convincing. Layer ambience, foley, and music. Use a dedicated lip-sync tool for dialogue shots, and keep spoken lines short — long monologues expose synchronization errors quickly.
A Complete Example: A Thirty-Second Product Story
Here is the workflow end to end for a short branded piece.
- Write the premise in one sentence. "A watch is assembled by hand, then worn on a city rooftop at dusk."
- Beat it into six shots. Macro of tools, hands setting the movement, watch face detail, wrist close-up, rooftop wide, final product hero.
- Generate six stills. Compare them side by side and adjust palette and lighting until they feel like one world.
- Draft every shot at low resolution. Three variations each, no more than five seconds per clip.
- Select, then re-render the two hero shots at high fidelity using the winning seed and prompt, with the still as first-frame conditioning.
- Upscale, interpolate to 24 fps, and apply one grade across the sequence.
- Build the sound bed — room tone, tool clicks, distant traffic, a single music cue that rises into the rooftop wide.
- Assemble and trim to the beat, adding the product name on the final frame.
The total time depends far less on rendering speed than on how disciplined steps three and four are. Skipping the still pass is the most common reason a project needs to be restarted.
Mistakes That Waste Hours
- Generic prompts with no camera, light, or palette instructions
- Cramming multiple actions into one clip
- Ignoring light direction between shots, which flips shadows mid-sequence
- Mixing reference images from different character packs
- Re-rolling when a small prompt edit would fix the shot
- Generating at final resolution before composition is approved
- Stacking conflicting camera moves in a single prompt
- Working without a continuity document
- Leaving audio planning until the very end
- Delivering ungraded clips that each look like a different film
Quality Control: A Repeatable Review Pass
Review in three passes rather than one. Technical: check for warped anatomy, flicker, jitter, and resolution mismatches. Narrative: confirm each shot advances the beat and that the sequence reads without explanation. Consistency: verify wardrobe, props, light direction, and color temperature across every cut.
A simple checklist prevents most revisions: does the first frame hold for at least a beat, does motion resolve rather than trail off, is the grade uniform, does the sound bed mask transitions, and does the piece land under the target duration without a rushed ending?
FAQ
How long should each generated clip be? Four to six seconds is the sweet spot for most models. Longer clips drift and lose coherence, while shorter clips are harder to cut smoothly without handles.
Should I rely on seeds or keyframes for consistency? Use both, but treat keyframes as the stronger lever. Seeds stabilize texture and randomness; keyframes constrain composition and pose, which is usually what breaks continuity.
Is image-to-video better than text-to-video? For anything with a recurring character, product, or location, yes. Text-to-video is excellent for establishing shots, abstract transitions, and previz.
How do I stop faces from morphing? Shorten the clip, reduce motion strength, add a reference image, and specify a slower camera move. Avoid profiles turning into frontal views within the same shot.
Do I need expensive hardware? Not necessarily. Browser-based tools handle most generation, but local upscaling and rendering benefit from a decent GPU if you produce at volume.
How do I keep the same look across many shots? Fix a palette, a lighting direction, a lens range, and a style descriptor, then reuse that block of text verbatim in every prompt. Consistency comes from repetition, not from rewriting.
What about dialogue? Keep lines under a few seconds, generate the performance first, and use a dedicated lip-sync pass afterward. Plan the audio before you shoot, not after you cut.
