
Why realistic AI video is now a production decision, not a novelty
For years, generated video lived in its own lane. You used it for a stylized transition, a mood board, or a proof of concept that you later reshot properly with a camera. Realism was a party trick, and audiences saw through it within seconds.
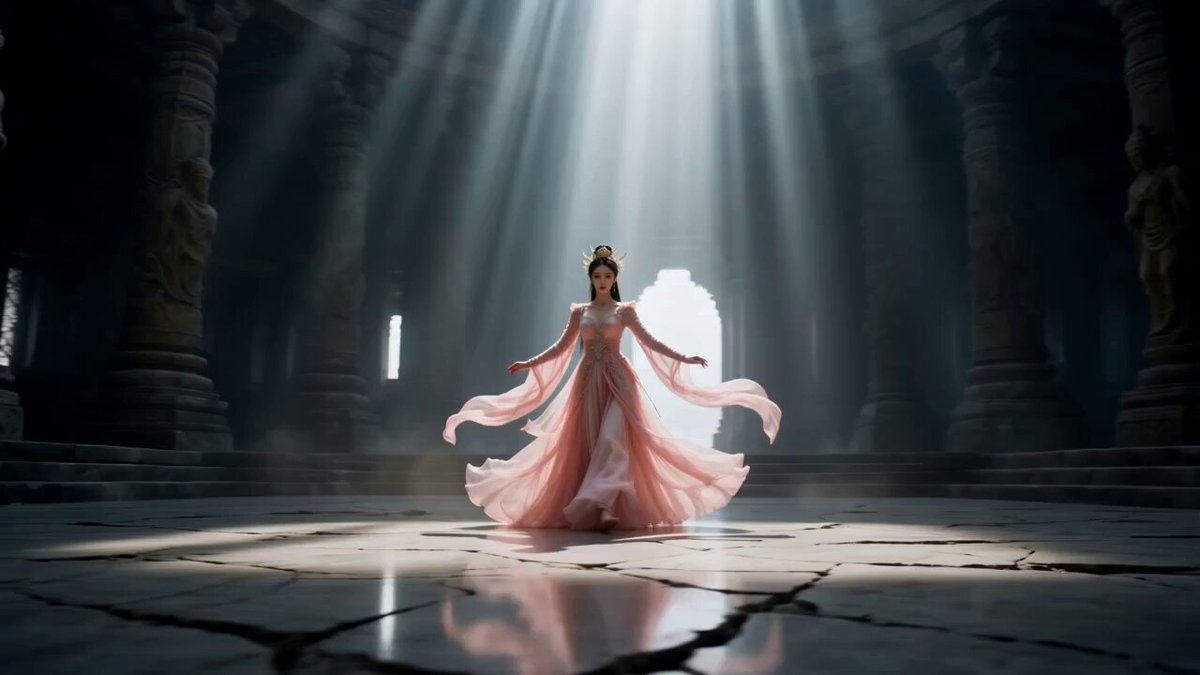
That lane has closed. Modern diffusion video models — Luma's newest generation is the clearest example — can hold a face consistent through a pan, let cloth fold under gravity, and render a believable reflection in a wet street. When all three happen at once, viewers stop asking whether the footage is synthetic and start asking where it was shot.
The production consequence is straightforward: generated shots now belong in scheduling conversations. Directors, agency producers, and small in-house teams are deciding, shot by shot, whether an image is faster, cheaper, or simply better when it is generated rather than filmed. That is a workflow question, not a technology question, and the rest of this guide treats it that way.
What actually changed in the current generation of models
Temporal coherence is the headline improvement
Early models were image generators with a time axis bolted on. Every frame looked plausible on its own; the sequence did not. Hair changed length between frames, a hand lost a finger for six frames, a jacket swapped colour mid-motion. Temporal coherence — the model remembering what it already drew — is what fixed that, and it is the single biggest reason generated video now survives a second viewing.
Practically, coherence means you can ask for longer, slower, more deliberate camera moves. A six-second dolly across a room used to be a gamble. Now it is a routine request, and that changes how you block a scene.
Scene understanding and physics
The newer architectures reason about three dimensions rather than only pixels. They infer that a table is a solid object, that a person walking behind it should be partly hidden, that a glass knocked off an edge should fall rather than drift. You notice this most in reflections, shadows, and contact points — exactly where earlier generations gave themselves away.
For a producer, this is the difference between a model that renders a beautiful still and a model that renders a shot. Physics-consistent footage needs fewer repair passes in post, and repair passes are where generated video budgets quietly explode.
Parametric control and in-shot editing
The other shift is control. Instead of accepting or rejecting an entire clip, you can now adjust camera motion, pacing, and framing parameters, and in many cases edit a region of an existing generation without rebuilding the whole thing. That turns generation from a slot machine into something closer to a camera rig with settings.
In practice, teams use this to iterate on one shot instead of starting over: keep the performance, change the lens; keep the lens, adjust the timing; keep everything, replace an object in the background. Each of those moves saves a full generation cycle.
Why this changes a production budget
When a model can hold continuity and physics, the cost curve inverts. A shot that once needed a location, a permit, an actor, a lighting package, and a crew of nine can sometimes be produced by one person with a written brief and a reference folder. That does not make crews obsolete. It changes which shots deserve a crew. A realistic split is emerging: dialogue, performance, and anything requiring genuine human chemistry on camera go to a camera; almost everything else becomes candidate material for generation.
A nine-stage workflow for realistic AI video
The workflow below is what a small team can actually run in one or two days. It is deliberately front-loaded, because most realism failures are planning failures rather than rendering failures.
Stage 1 — Write a shot brief, not a prompt. A brief states intent: who is in frame, what they want, what the camera is doing, and how the shot ends. Prompts describe appearance. Briefs describe behaviour, and behaviour is what makes motion read as real.
Stage 2 — Build a reference kit. Collect six to ten stills: the character, the wardrobe, the location, the lighting mood. References cut iteration sharply because they remove ambiguity before you spend a generation cycle discovering it.
Stage 3 — Layer the prompt. Start with subject and wardrobe, add action, then camera, then light, then physics cues. One layer per sentence stops the model from averaging competing instructions into mush.
Stage 4 — Generate breadth before depth. Produce four to six inexpensive variations of the same shot with small deliberate changes: lens, pacing, angle. Choose a direction at that stage rather than after ten attempts at a single framing.
Stage 5 — Lock continuity across the sequence. Once a look is chosen, freeze wardrobe, palette, and lens language in a written style sheet that every later prompt quotes word for word.
Stage 6 — Run a physics check. Watch each clip at quarter speed and study contact points, shadows, and reflections. Synthetic frames fail there first, and finding a broken contact point early is far cheaper than discovering it during a client review.
Stage 7 — Plan the finishing pass. Assume you will add motion blur, grain, a grade, and sound design. Footage that edits well beats footage that looks polished but has no handles for a cut.
Stage 8 — Version everything. Name files by project, shot, take, and date, and keep the prompt that produced each take in the same document. A rough assembly must always be able to find its source.
Stage 9 — Deliver in the right container. Match the delivery specification from the start: resolution, frame rate, colour space, and audio loudness. Generating at an unusual frame rate and converting later costs more time than configuring it correctly on day one.
Prompt architecture: the six layers that matter
A prompt is not a sentence to be admired; it is a specification. The most reliable prompts in production are written in six layers, each answering one question.
Subject and wardrobe
Describe the person and clothing with facts the model can hold steady: age range, build, hair length, garment type, fabric, one distinctive accessory. Avoid poetic adjectives. Poetic language moves the image in unpredictable directions between takes, which is fatal when you need shot four to match shot two.
Action and intent
Say what the subject is doing and why, using one clear verb. Crossing a plaza to catch a departing bus is a different shot from walking across a plaza, even though both contain the same motion. Intent gives the model a reason to pick a specific posture, speed, and gaze direction.
Camera and lens
Name the move, the height, and the lens character: slow push-in at chest height, 50 mm equivalent, shallow depth of field. Camera language is the fastest way to make generated footage feel intentional rather than accidental, and it is usually the first thing reviewers notice.
Light and atmosphere
Specify the source and the time of day: low sun through a window on the left, hazy air, warm highlights, cool shadows. Light direction is the strongest realism signal in a frame, and vague lighting descriptions produce flat, plastic-looking results that no grade can rescue.
Physics cues
Mention the materials that must behave correctly: wet asphalt reflecting, loose fabric in wind, dust lifting from gravel. Naming the material tells the model which simulation deserves the most attention in that shot.
Negative constraints
List what must not appear: extra fingers, warped faces, floating objects, burned-in text, logos, sudden cuts. Keep the list short and specific, because long negative lists start suppressing detail you actually wanted.
Continuity control across shots: a working checklist
Single shots are easy to admire and easy to fake. Sequences are where realism is won. Build a continuity sheet before you generate, and update it as you go.
- Wardrobe and palette frozen in a written style sheet
- Lens and camera height recorded for every shot
- Screen direction consistent between adjacent shots
- Light direction matching across a scene, even when shots are generated days apart
- Props counted and positioned identically wherever they appear
- Motion vector continuity maintained, so a subject exiting frame right re-enters frame left unless an insert separates the shots
- Frame rate and resolution identical across the whole sequence
- One colour reference frame saved for the grade
Two habits make this sheet workable. First, generate an anchor frame per scene before generating motion: one still that defines wardrobe, palette, and light, referenced by every following prompt. Second, generate inserts on purpose. A five-frame insert of a hand, a cup, or a passing car is the cheapest continuity fix in the medium, because it resets the audience's attention and hides small inconsistencies between two otherwise incompatible takes.
Choosing between generation and traditional capture
Decision criteria worth putting in a pitch
Four criteria decide most shots. Performance: if the shot depends on a subtle emotional beat, film it. Legality: if the shot depicts a real, identifiable person, film it or obtain explicit consent for a synthetic version. Scale: if the shot needs a crowd, a landmark at dusk, or weather you cannot book, generate it. Revision cost: if the client is likely to ask for eleven changes, generation is usually cheaper, because you can adjust parameters instead of reshooting.
A practical rule many teams use: generate anything that would require more than two hours of travel or more than three crew members, and film anything where the audience is watching a face for more than four seconds. Faces in close-up are still the hardest test for temporal coherence, and a nervous performance is impossible to generate.
Render time, iteration, and compute budgets
Treat rendering like a shoot day with a fixed number of usable hours. Explore at preview resolution and only escalate approved takes. Batch heavy jobs overnight and keep lighter tasks — storyboards, matte ideas, title design — for daylight hours when people are awake to make decisions.
Track the metric that matters: usable seconds per session, not clips per session. A session that produces four seconds of approved footage is better than one that produces sixty clips and no decision. Save every prompt version with its output, so a good take can be reproduced rather than approximated. And never re-render a full clip to fix a one-second problem: cut around it, cover it with an insert, or fix it in post.
Common realism-breaking mistakes
- Describing appearance without action. A perfectly described face standing still reads as a photograph that moved. Motion needs a verb and a goal.
- Changing too many variables at once. If you alter lens, light, and wardrobe in the same iteration, you learn nothing from the result.
- Ignoring the first twelve frames. Many clips settle into coherence after a beat. If you cannot cut around the opening, generate a slightly longer shot and trim into it.
- Opening on an extreme close-up of a face. Give the model a wider frame to establish physics and lighting before you ask for skin texture.
- Overloading negative constraints. A twenty-item exclusion list flattens the image. Keep it to the five errors you actually see.
- Skipping sound design. Audiences forgive soft focus far less readily than a silent room. Footsteps, cloth, room tone, and air sell realism faster than any sharpening pass.
- Delivering clips with no handles. Ask for two extra seconds on each end so the edit has room to breathe.
- Mixing frame rates across a sequence. It reads instantly as a mistake, even to viewers who cannot name the problem.
- Grading before continuity lock. A beautiful grade on an inconsistent sequence just makes the inconsistency sharper.
Ethics, rights, and client conversations
Realism raises real obligations. Likeness is the first: generating a recognisable person without permission is a legal and reputational risk, regardless of what the model allows. Written consent, or a synthetic performer who does not resemble anyone, is the safe path.
Disclosure is the second. Some markets and broadcasters already require a label on synthetic footage depicting real events, and many clients now ask for one regardless. Decide early whether the work carries an on-screen disclosure, a description note, or nothing, and put that decision in the contract rather than in a hallway conversation.
Provenance is the third. Keep the prompts, references, and take history for every delivered shot. If a claim arises about where footage came from, a tidy archive answers it in minutes. Also confirm your licence terms cover commercial use of the specific model version you are generating with, and check whether your source references — photographs, artwork, stock — carry their own restrictions.
Finally, be honest in the pitch. Clients respond well to a clear statement of what generation does better and what it cannot yet do. Promising a synthetic lead performance in close-up is how teams lose trust, and trust is the only thing that gets you the second project.
Putting it together: a two-day short film
Here is what the workflow looks like end to end for a ninety-second brand piece with fourteen shots.
Day one, morning. Write fourteen shot briefs, gather references, and build a style sheet with wardrobe, palette, and lens language. Generate one anchor still per scene — three scenes, three stills — and get them approved before any motion is generated.
Day one, afternoon. Generate preview-resolution versions of all fourteen shots, four variations each, and watch them at quarter speed. Approve the best direction for each shot, then regenerate only the six that failed the physics check. Assemble a rough cut with temporary sound.
Day two, morning. Escalate approved takes to final resolution. Run the finishing pass: motion blur, grain, a single grade built from the colour reference frame, and full sound design with room tone, footsteps, and an ambient bed.
Day two, afternoon. Client review, notes, one round of parameter adjustments rather than full regeneration, and delivery in two aspect ratios with titles burned and clean. Total generation time is rarely the bottleneck. Review and decision time is.
FAQ
How long does a single realistic shot take?
For a four-second shot with an approved look already established, plan twenty to forty minutes of generation and review. The first shot of a new scene takes longer because you are still defining wardrobe, light, and lens. Once the anchor frame is locked, later shots in the same scene move quickly.
Do I need an expensive workstation?
Not for iteration. Preview resolution and short durations run comfortably on a capable laptop, and heavier final renders can be queued and left running. What genuinely helps is storage and organisation: fast drives, predictable file names, and a documented prompt history.
Why do hands and faces still fail?
They are the most detail-dense, most scrutinised parts of a frame, and they change shape constantly. Mitigate by keeping them partly occluded, cutting around them, or framing wider. A hand behind a cup is invisible; a hand spread across the frame invites inspection.
How do I keep a character consistent across shots?
Use one reference image, quote the same wardrobe sentence in every prompt, and keep lens and light direction fixed per scene. If a shot drifts, regenerate from the anchor frame instead of tweaking words and hoping.
How many variations should I generate per shot?
Four to six at preview resolution, varying one element at a time. Fewer than four and you accept a weak take out of impatience. More than six and you spend your session watching instead of deciding.
Can generated footage be used commercially?
Often yes, but the answer depends on the specific model licence, your source references, and the nature of the content. Confirm terms before delivery, keep consent paperwork for any real likeness, and disclose synthetic footage where required.
Should I edit before or after generating the finishing pass?
Edit first. Lock the cut, then spend finishing effort only on frames that survive into the final timeline. Generating polish for a shot you later trim out is the most common way teams burn a day.
Realistic AI video is not a magic button; it is a discipline with a short feedback loop. Write the brief, build the reference kit, lock continuity, check the physics, and finish with sound and a grade. Do those five things consistently and the audience stops asking how the shot was made — which is the only realism test that has ever mattered.
