
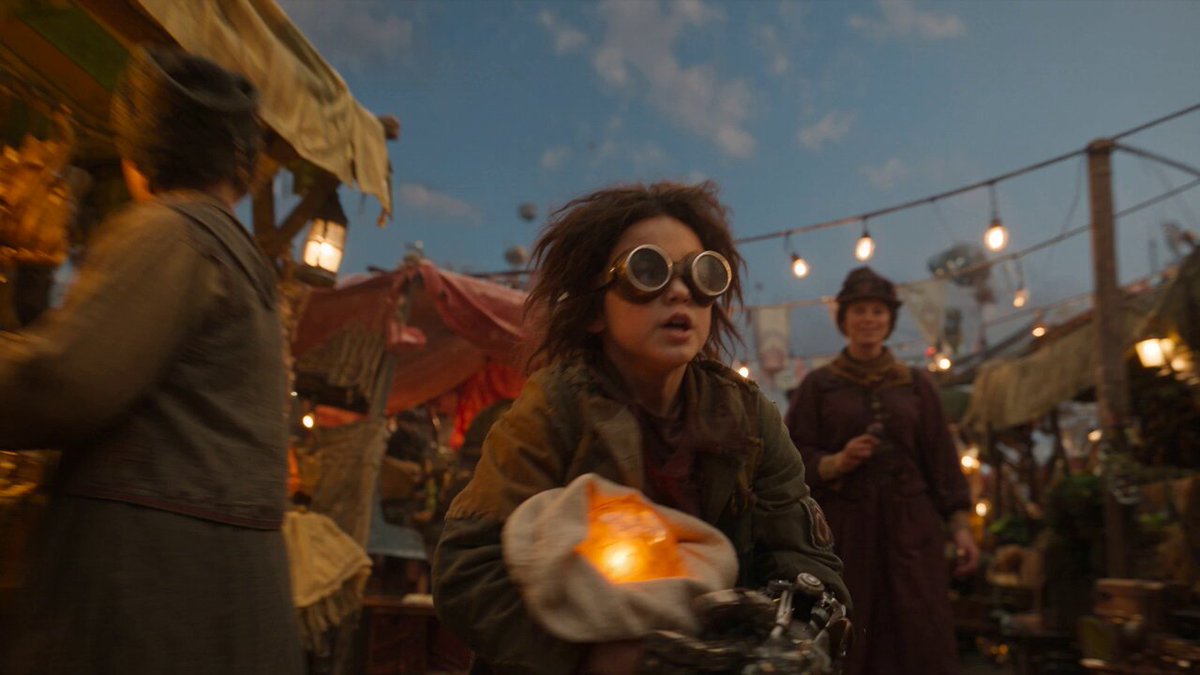
Turning a script into finished scenes used to require a crew, a location, insurance, and weeks of scheduling. Today, a small team or a single creator with a disciplined shot list can generate cinematic footage from text prompts, iterate on takes in minutes, and assemble a coherent sequence on a laptop. That shift does not remove craft — it relocates it. The work moves from operating a camera to designing what the camera should see, and from managing a set to managing continuity across dozens of generated clips.
This guide walks through a complete text-to-scene workflow for professional-looking video: how to break a script into shots, how to write prompts that behave like camera directions, how to keep characters and locations stable, how to work around the physical limits of generation, and how to edit generated clips into something that feels intentional rather than assembled.
Why text-to-scene workflows are reshaping production planning
The most important change is not that video can be generated. It is that generation collapses the feedback loop between idea and image. A director can describe a shot at breakfast, see a rough version of it before lunch, and decide whether the scene works before committing budget to it. That changes how projects are planned: storyboards become motion tests, moodboards become style references the model can read, and the edit becomes the place where the film is actually found.
For teams, this means pre-visualization is no longer a luxury reserved for large productions. A writer can hand over a sequence, a designer can render a look, and a producer can evaluate pace and coverage without booking a stage. For solo creators, it means the barrier is no longer equipment but clarity — the quality of the output tracks closely with how precisely you can describe what you want.
The trade-off is real. Generated footage rarely survives scrutiny as a single unbroken take of complex action. It works best when you treat it like a collection of short, deliberate pieces: a look, a gesture, a camera move, a reaction. Films have been built that way for a century. The difference is that now each piece costs minutes instead of hours.
Anatomy of a text-to-video pipeline
A reliable pipeline has four stages: interpretation, generation, selection, and assembly. Skipping any of them shows up on screen, usually as inconsistent characters or a sequence that feels like unrelated clips stitched together.
From script to shot list
Start by breaking the script into beats, then into shots. A beat is a change in the scene — someone enters, a decision lands, a threat appears. A shot is the smallest unit that carries one piece of information. Write each shot as a single sentence that names the subject, the action, the framing, and the mood. If a sentence contains the word "and" twice, it is probably two shots.
A practical target is three to eight seconds of screen time per generated clip. Short clips generate more reliably, give you more options in the edit, and hide the seams where continuity drifts.
Prompt structure that mirrors camera language
A useful prompt has five slots: subject, action, camera, lighting, and style. Keep them in that order so you can adjust one variable without rewriting everything.
- Subject: who or what, with two or three identifying details that repeat across every shot (wardrobe, hair, a prop).
- Action: one verb, present tense, plus the emotional register. "She hesitates before opening the letter" beats "she is sad."
- Camera: framing and movement — wide, medium, close-up, slow push in, handheld follow, static tripod.
- Lighting: time of day, source, contrast. "Late afternoon sun through dusty windows, hard shadows" is more controllable than "cinematic lighting."
- Style: film stock, lens character, color palette, era. Keep this identical across an entire scene.
Model and style selection criteria
Different generators excel at different things: some favor photoreal humans, others stylized motion, others long camera moves. Rather than chasing a single best tool, match the tool to the shot. Build a small matrix of the two or three generators you trust, and note which one handles faces, which handles landscapes, and which handles quick action. Test them on the same prompt before a project starts, not during a deadline.
Writing prompts that behave like shot directions
The fastest way to improve output is to stop writing descriptions and start writing directions. A description tells the model what exists. A direction tells it what to do with the frame.
One action per shot
Models blend actions poorly. "He walks in, sits down, and pours coffee" produces a smear of motion. Split it into three shots, or choose the single most expressive moment. A shot of a hand reaching for a cup can say more than a full action sequence, and it will render cleanly.
Control the camera explicitly
Camera language is your strongest continuity tool. Decide on a small vocabulary for each scene and reuse it: an establishing wide, a medium two-shot, a close-up, and one moving shot. If every clip uses a different framing and movement, the edit will feel restless no matter how good the images are.
Use negative prompts deliberately
Most generators accept some form of exclusion. Keep the list short and specific to recurring failures — warped hands, extra fingers, text artifacts, jittery edges, sudden zoom. A bloated negative list often removes detail you wanted along with the problems you did not.
Iterate in one variable at a time
When a shot fails, change exactly one thing: the action, the framing, or the lighting. Changing three variables at once teaches you nothing and burns time. Keep a simple log of prompt, generator, and result so successful combinations can be reused later.
Keeping characters and locations consistent
Continuity is the single hardest problem in AI video, and it is mostly a documentation problem. The model cannot remember your character; your project notes can.
Build character and location sheets
Write a short reference block for every recurring element and paste it verbatim into prompts. For a character: age range, build, hair, wardrobe, distinguishing feature, and how they carry themselves. For a location: architecture, materials, time of day, weather, and one memorable detail. Consistency comes from repetition, not from variation.
Anchor with reference images
If your workflow supports image conditioning, generate a clean reference still first and use it as the base for subsequent shots. A single well-lit character portrait can lock a face across an entire scene. Do the same for locations: one establishing image, then angle variations derived from it.
Lock style tokens
Choose a fixed style phrase — lens, stock, palette, grain — and never paraphrase it. Small wording changes cause visible shifts between clips. Write the phrase once, save it, and paste it into every prompt in that scene.
Plan around the cuts you cannot hide
Some continuity gaps are cheaper to solve in the edit than in the generator. Cutting away to a reaction, a prop, or a wide shot can bridge a wardrobe change or a lighting mismatch. Design your shot list with a few neutral cutaways available for exactly this purpose.
Motion, physics, and where generation breaks
Generated motion is convincing at short durations and moderate speeds. Push past that and you get sliding feet, rubbery limbs, and objects that change shape mid-move.
Choose camera moves that flatter the model
Slow pushes, gentle pans, and subtle handheld sway read as intentional and hold up well. Fast whips, complex arcs, and long tracking shots through crowds are where artifacts appear. When you need energy, get it from cutting and sound rather than from a single aggressive move.
Respect weight and contact
Anything that requires believable contact — a hand on a door, a foot on a step, an object landing — needs a short clip and a clear, simple action. If a shot requires sustained physical interaction, shoot it as separate beats: approach, contact, reaction.
Use duration as a tool
Most generators look best between three and six seconds. If a scene needs to feel longer, build it from multiple angles rather than stretching one clip. Longer generations tend to drift in identity and lighting, which is far more damaging than an extra cut.
Know when to stop generating
If a shot has failed six or seven times with meaningful prompt changes, the problem is the concept, not the prompt. Rewrite the shot as something simpler, or solve it with a still, a graphic, or a cutaway. Persistence past that point rarely pays off.
From generated clips to a cut
Raw clips are not a film. The edit is where pace, performance, and meaning are created, and it is the stage most creators rush.
Assemble a paper edit first
Before touching a timeline, write the sequence as text: shot number, duration, purpose. This reveals redundancy fast. If two shots do the same job, one of them is costing you pace.
Cut on motion and intention
Place cuts where the eye is already moving — a turn of the head, a hand entering frame, a light change. Matching motion across a cut makes two unrelated generations feel like one continuous scene.
Sound carries performance
Generated visuals rarely deliver a convincing vocal performance on their own. Record or synthesize dialogue separately, add room tone, footsteps, and cloth movement, then let the sound design establish rhythm. A mediocre shot with excellent audio reads as professional; the reverse does not.
Finish with a consistent grade
Apply a single look across the whole sequence — contrast curve, palette, grain — so clips from different generators feel like one camera. This step is short and does more for perceived quality than another round of generation.
A worked example: a ninety-second narrative scene
Imagine a short scene: a courier delivers a package to an apartment, hesitates at the door, and leaves without knocking.
Pre-production (about an hour). Write the script as six beats. Convert to eleven shots: building exterior, stairwell, hallway approach, hand on the door, close-up of the package, the courier's face, a nervous shift of weight, the hand withdrawing, a step back, the hallway wide as they leave, and the package alone on the floor. Write reference blocks for the courier, the hallway, and the package. Pick one style phrase and one lighting condition.
Production (about two hours). Generate four variants of every shot at four seconds each, using the same style phrase throughout. That is forty-four clips. Discard anything with warped hands, drifting wardrobe, or unexpected camera movement. Expect roughly a third to be usable on the first pass, which is normal and not a sign of failure.
Pickups (about thirty minutes). For weak shots, simplify: replace the stairwell walk with a static shot of feet on steps, replace the withdrawal of the hand with a tighter close-up. Simplicity almost always solves a stubborn shot.
Assembly (about two hours). Lay the clips in order, then cut aggressively. Four-second clips usually survive at two to three seconds. Add door handle, footsteps, and hallway ambience. Record the courier's breathing. Grade everything to one look.
Review. Watch once with sound off to check visual continuity, then once with picture off to check audio rhythm. Most continuity problems reveal themselves in the silent pass.
Common mistakes and how to avoid them
Writing prose instead of directions. Long, literary prompts produce vague images. Compress to one action and one camera instruction.
Changing style mid-project. A new adjective in the style phrase will visibly shift the footage. Freeze the phrase before you generate anything.
Generating before planning. Without a shot list, you accumulate attractive clips that cannot be edited together. Plan first; the generation is fast, the assembly is not.
Over-relying on long takes. Long generations drift. Prefer more, shorter clips and let editing create the sense of duration.
Ignoring audio until the end. If sound is treated as an afterthought, the edit will feel thin no matter how strong the visuals are. Plan the sound pass in the schedule from the beginning.
Skipping a naming convention. With hundreds of files, a consistent scheme — scene, shot, take — saves hours during assembly and makes refilming a single shot trivial.
Building your stack: what to evaluate
When choosing tools, judge them against your actual workflow rather than feature checklists.
- Prompt adherence: does the model do what the sentence says, or does it add its own ideas? Adherence matters more than beauty.
- Consistency support: image conditioning, seed control, and reference inputs for characters and locations.
- Clip length and resolution: enough for your delivery format, and adjustable without losing quality.
- Iteration speed: how long between prompt and preview. This determines how many ideas you can test.
- Editing integration: clean exports, consistent frame rates, and predictable color handling.
- Licensing and usage terms: confirm commercial rights and any content restrictions before you build a project around a tool.
The right stack is usually two generators plus an editor, not ten. Depth of familiarity beats breadth of options.
Frequently asked questions
How long should each generated clip be?
Three to six seconds is the reliable zone for most models. Build longer scenes from multiple angles rather than one extended generation.
Can I keep the same character across an entire video?
Yes, with discipline. Write a fixed character reference block, reuse a single style phrase, and anchor with reference images where supported. Expect to regenerate some shots and plan cutaways to bridge continuity gaps.
Do I still need a script?
More than ever. The script is what the shot list is derived from, and the shot list is what the prompts are derived from. Weak scripts produce unfocused prompts, which produce unusable footage.
How much footage should I generate per shot?
Three to five variants is a reasonable baseline. Fewer leaves you without options; more rarely improves the result and slows the review pass.
What kind of project suits this workflow best?
Narrative shorts, explainers, product storytelling, music videos, and pre-visualization for larger productions. Anything requiring sustained complex physical action or precise human interaction remains difficult.
How do I keep costs and time predictable?
Fix the shot list before generating, cap variants per shot, and batch similar shots in one session so prompts and style phrases stay consistent. Unplanned exploration is the main source of runaway schedules.
Will the result look artificial?
Badly assembled sequences do. The tell is usually inconsistent style, erratic motion, and weak audio rather than any single clip. A unified grade and a strong sound pass remove most of the uncanny feeling.
Where to go next
Start small: one scene, one location, one character, eleven shots. Finish it end to end — generate, cut, sound, grade — before expanding. That single completed scene teaches more about the pipeline than weeks of isolated tests.
Then build a personal library: reference blocks for characters, location sheets, style phrases, and a log of prompts that worked. Reusable assets compound faster than new tools. The technology will keep improving, but the discipline of planning shots, writing precise directions, and treating the edit as the place where the film is made will remain the difference between footage and a finished piece.
