
Why structured synthesis replaced prompt roulette
A year ago, generating a good-looking AI video clip was mostly a game of chance. You typed a sentence, waited, and hoped the model would produce something usable. Sometimes it did. Often it produced a beautiful image with broken motion, a coherent motion with drifting faces, or a style that changed halfway through the shot. The output was impressive as a demo and frustrating as a production asset.
The tools have changed, but more importantly, the method has changed. The creators who consistently ship watchable AI video are not using secret prompts. They are working with a structured approach that treats generation as a composition problem rather than a text problem. They decide what the shot is made of before they decide what to type.
This article walks through that approach in practical terms. It covers the mental model behind semantic block synthesis, how multi-image fusion gives you real control over style, how to build a reference set that a model can actually follow, and a step-by-step workflow you can run on a real project. It also covers the mistakes that waste the most time and how to troubleshoot output that refuses to cooperate.
The core mental model: pixels as semantic blocks
From pixel grid to meaning unit
Every generative video model ultimately outputs a grid of pixels. But the useful abstraction for a director is not the pixel. It is the semantic block: a small region of the frame that carries a consistent meaning, material, and behaviour across time. A cheekbone, a jacket seam, a window reflection, a patch of wet asphalt. Each of these is a unit that should stay coherent when the camera moves.
The "block" framing is a mental model, not a literal rendering technique. Think of it this way: rather than asking a model to invent an entire frame from a vague description, you give it a set of anchor references that define what each meaningful region should look like. The model then assembles the frame from those anchors the way a builder assembles a structure from standardized pieces. Each piece is small, defined, and reusable. The result is a shot that holds together because its components were defined before generation started.
The practical payoff is predictability. When your anchors are consistent, the model has far less room to invent something that contradicts the rest of your film.
Why block-level thinking simplifies shot design
Once you think in blocks, shot planning becomes concrete. Instead of writing "a detective walks through a rainy alley," you break the shot into components:
- Subject block: face, wardrobe, hair, posture
- Environment block: architecture, ground material, light sources
- Atmosphere block: rain density, fog, haze, colour of ambient light
- Camera block: lens length, height, movement, speed
Each block can have its own reference images or short description. The model receives a much denser signal, and you get a shot that looks intentional rather than accidental. This also makes revisions surgical. If the alley looks wrong but the actor looks perfect, you change one block instead of rerolling the entire frame.
Multi-image fusion: how style control actually works
What fusion does under the hood
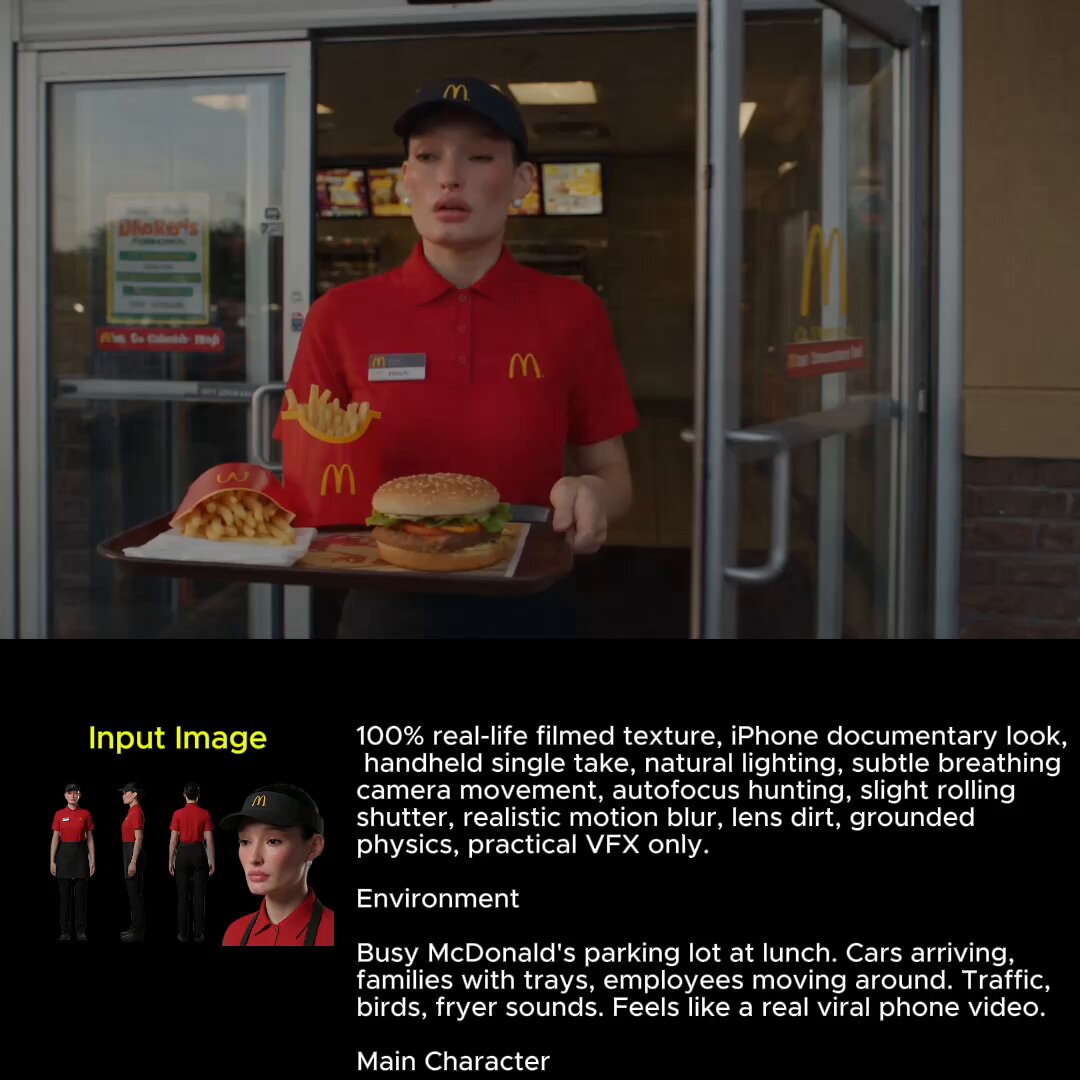
Multi-image fusion is the technique of conditioning a generation on several reference images at once rather than a single starting frame. Modern pipelines can accept a small set of references — typically between three and eight — and blend their visual characteristics into the output. One image might carry the face, another the lighting, a third the colour palette, a fourth the texture of the environment.
Different tools expose this differently. Some call it reference conditioning, some call it image prompting, some expose node-based control where you weight each input. The mechanism varies, but the goal is the same: give the model enough evidence that it stops guessing.
The key insight is that weights are not decoration. If you weight a face reference too heavily, the model will paste that face onto every frame with no respect for camera angle, producing an uncanny sticker effect. If you weight it too lightly, the identity drifts. Finding the balance is a skill, and it is usually found somewhere between 0.4 and 0.75 for identity references, with environment references sitting lower.
Reference hygiene: what to include and what to cut
Most bad fusion results come from bad reference sets, not bad models. Three rules help:
Rule one: match the lighting. If your references were shot under wildly different lighting, the model will average them into mud. Choose references that share a light direction and colour temperature.
Rule two: match the framing. A tight beauty shot and a wide environmental shot carry very different information. Use references that are roughly in the same range as the shot you want.
Rule three: cut the noise. Every reference adds information, including information you do not want. If a reference image has a distracting background, a stray logo, or a competing colour cast, either crop it or leave it out.
A tight reference set of four images that agree with each other will beat a sprawling set of twelve that fight.
Building a style bible your model can follow
A style bible is a short document that defines the look of the project so it can be reproduced shot after shot. In a traditional production it is a PDF full of stills. For AI video, it needs to be machine-friendly as well as human-readable.
A working AI style bible contains:
- A colour block. Four to six hex values with names like "cold steel," "signal amber," "wet concrete." These go into prompts as plain words and into grading later as reference swatches.
- A lighting block. One sentence describing the dominant key-light direction, plus a note on contrast ratio. "Low key, lit from frame left, deep falloff" is more useful than "moody."
- A lens block. Focal length and depth-of-field behaviour. Models respond noticeably to phrases like "35mm, deep focus" versus "85mm, shallow focus."
- A texture block. Film grain, digital cleanliness, halation, bloom. This is where a lot of "AI look" complaints get solved or created.
- An anchor set. Six to ten reference stills that represent the target look, ideally generated by you rather than pulled from other people's work.
The rule of thumb: if a new collaborator could not reproduce your look from the style bible alone, it is not finished.
A practical workflow from concept to final cut
Step 1: Freeze the scene grammar
Before generating anything, write the scene in blocks. One page maximum per scene. List the subject, environment, atmosphere, and camera behaviour for every shot. Decide what is allowed to change between shots and what must stay locked. This is the single highest-leverage hour in the whole process, because every later decision references it.
Step 2: Build the reference set
Collect or generate four to eight references per scene. Generate the key character still first if you do not have footage, because a clean, well-lit character frame becomes the anchor for everything else. Save references in a folder named by scene and shot so that you never mix context between shots.
Step 3: Generate in disciplined batches
Generate six to twelve variations per shot, not sixty. Change one variable at a time between batches so you learn what is actually affecting the output. If you change the prompt, the seed, the reference weights, and the motion strength all at once, you learn nothing and you burn your afternoon.
Keep a simple log: shot number, prompt, references used, weights, seed, and verdict. This takes two minutes and saves hours when you return to a project a week later.
Step 4: Repair rather than regenerate
When a shot is 80 percent right, do not reroll it. Isolate the problem. If the face drifts in the last second, cut the tail and extend from a clean frame. If the background is wrong, composite the subject over a generated plate. If colour is off, fix it in the grade rather than asking the model for a different palette. Regeneration discards everything that was working.
Step 5: Edit, sound, grade
AI clips become films in the edit. Cut on motion, keep shots shorter than feels comfortable, and let sound design do the heavy lifting for continuity. A consistent grade across all shots will do more for perceived quality than any individual generation. Resolve, Premiere, and Final Cut all handle this well; the important thing is applying one look to everything rather than grading shot by shot.
Keeping characters and environments consistent
Character consistency is the hardest problem in AI video, and it is solved with discipline rather than a magic setting.
Use a locked character anchor. One high-quality still that shows the face clearly at a neutral angle. Regenerate it until it matches your intent, then treat it as immutable.
Control the camera, not the character. Models drift most when the camera does something unusual. If you need a difficult move, generate the character in a simple framing and add the camera move in post with a subtle push or parallax.
Limit wardrobe changes. Every costume change is a new identity problem. Design your story so characters stay in the same outfit within a scene block.
Accept the three-quarter rule. Most models handle three-quarter and profile angles better than extreme close-ups and full-frontal symmetry. Design shots around the angles your tool does well.
For environments, consistency is easier. Reuse the same environment references across every shot in a location, and keep the light direction identical. If a scene takes place at night, it is night in every shot, with the same practical light sources visible in the same positions.
Choosing the right tool for each job
No single engine wins every task. A practical way to decide is to match the engine to the shot type rather than to brand loyalty.
| Shot type | What matters most | What to look for |
|---|---|---|
| Talking character, medium shot | Face stability | Strong identity conditioning, low motion ambition |
| Environment establishing shot | Texture and depth | High detail retention, slow camera moves |
| Action beat | Motion coherence | Physics-aware motion, short durations |
| Stylised animation | Style adherence | Strong reference conditioning, painterly output |
| Product insert | Clean edges | Sharp detail, minimal hallucination |
A useful habit is to test a new engine on your own hardest shot rather than its demo reel. Five minutes of testing on your material tells you more than an hour of watching other people's results.
Common mistakes that wreck otherwise good generations
Overtalking the prompt. Long prompts filled with adjectives dilute the signal. Blocks beat poetry.
Mixing lighting across references. This is the single most common cause of muddy output.
Rerolling instead of repairing. Rerolling feels productive and usually destroys progress.
Ignoring motion strength. High motion values break faces. Low values produce slideshows. Tune this before anything else.
Generating without a locked look. If every shot has its own palette, the edit will feel like a collage no matter how good the individual clips are.
Skipping sound. Silent AI footage always looks more artificial than the same footage with ambience, foley, and music.
Working at maximum resolution too early. Iterate at low resolution, then upscale the final selections. You will save hours.
Troubleshooting: when the output fights the prompt
Face changes between shots. Reduce motion strength, increase identity reference weight, and shorten the clip. Long takes accumulate drift.
Style flattens out. Your references are too similar. Introduce one reference with a stronger, clearly different characteristic to give the model something to latch onto.
Everything looks plastic. Add texture language to the style bible, reduce sharpening in post, and consider adding grain in the grade instead of asking the model for it.
Motion is jerky. Lower the motion value and increase the number of frames rather than asking for more movement. Smoothness is usually a frame-count problem, not a creativity problem.
The model ignores the reference entirely. Check the aspect ratio and framing of your reference images. A portrait reference will not steer a widescreen generation reliably.
Colours shift across a scene. Grade after the edit with a single look applied to the whole timeline. Fixing colour inside generation is a losing battle.
FAQ
Do I need a powerful local machine? Not necessarily. Cloud generation handles most workflows, but local setups give you more control over custom pipelines and batch processing. Choose based on how much iteration you do per week rather than on raw specs.
How many reference images is ideal? Four to six for most shots. More references add conflicting information faster than they add control.
Should I write prompts in a specific format? Yes — separate subject, environment, atmosphere, and camera into distinct clauses. Models parse structured text more reliably than flowing prose.
How long should a generated clip be? Generate short, around three to five seconds, and cut in the edit. Long generations drift and are harder to repair.
Can I mix engines in one project? Yes, and most serious projects do. Match the engine to the shot, then unify everything in the grade and sound design so the seams disappear.
What is the fastest way to improve? Generate the same shot twenty times with one variable changing between batches. Deliberate iteration teaches more than watching tutorials.
How do I handle dialogue? Generate the visual performance first, then record or synthesise dialogue separately and cut to it. Trying to make the model produce lip-sync from scratch is the slowest possible path.
Is a storyboard still useful? More than ever. A storyboard is your block map. It tells you which references you need before you open a single tool.
Putting it together
The shift toward structured synthesis is not about a particular engine or a particular setting. It is about deciding, before generation begins, what each part of the frame is made of and how it must behave across time. Build a reference set that agrees with itself. Write a style bible short enough to memorise. Generate in small, logged batches. Repair instead of rerolling. Unify everything in the edit.
Do those things consistently and the question stops being "did the model give me something good?" and becomes "which take best serves the scene?" That is a much better place to work from — and it is the difference between collecting impressive clips and finishing an actual film.
