
Why text-to-video and image-to-video changed production planning
A few years ago, producing a thirty-second cinematic clip meant booking a camera crew, a location, and a lighting setup. Today, a single person with a laptop can generate that same clip from a paragraph of text or a single reference image — and then iterate on it twenty times before lunch. That shift is not about replacing filmmakers. It is about compressing the distance between an idea and a watchable version of that idea.
Text-to-video models take a written description and synthesize motion, lighting, and camera behavior from scratch. Image-to-video models take an existing still — a product photo, a character illustration, a storyboard frame — and animate it while trying to preserve what makes that still recognizable. The two approaches solve different problems, and most real projects use both in the same timeline.
The practical consequence is that production planning now looks more like software development than like a traditional shoot. You define a spec, generate candidates, evaluate them against criteria, and iterate. Teams that understand this loop ship faster and waste less.
The four layers of a reliable AI video pipeline
Regardless of which tool you open, a dependable pipeline has four layers. Skipping any of them is the most common reason beginners get inconsistent results.
Layer 1: The prompt layer
This is where intent becomes language. A good prompt names the subject, the action, the environment, the lighting, the lens behavior, and the emotional register. Vague prompts produce vague video, because the model has to guess on every axis you leave open.
Layer 2: The reference layer
References are your control surface. A first frame locks composition. A last frame locks the endpoint of a camera move. A character sheet locks a face. A style still locks color and texture. The more control you need, the more references you should supply — up to the point where contradictory references confuse the model.
Layer 3: The model layer
Different model families excel at different things: photoreal humans, stylized animation, precise camera moves, long takes, or fast iteration. A professional workflow usually routes each shot to the model most likely to nail it rather than committing to one tool for everything.
Layer 4: The assembly layer
Generated clips are raw material, not finished products. Editing, sound design, color correction, and captions are what turn a set of five-second fragments into something an audience will actually watch to the end.
Choosing between model families without guessing
Model choice should follow from the shot, not from brand loyalty. Here is how to think about the trade-offs.
Cinematic realism and physical plausibility. Some models are tuned for believable light, skin, fabric, water, and crowd behavior. They are the right pick for brand films, fashion, and anything that has to pass as real footage. They tend to be slower and more expensive per second, so reserve them for hero shots.
Camera control and editorial flexibility. Other families emphasize controllable camera movement, motion brushes, and integration with editing timelines. If your shot list is full of specific moves — a slow push-in, a whip pan, a locked-off product rotation — prioritize models with explicit camera parameters over models with the best textures.
Stylized and animated output. For illustration, anime, or painterly looks, stylized-first models often beat photoreal models given the same reference, because they were trained on art rather than on footage. Asking a photorealism model to produce a watercolor world usually means fighting it.
Speed and volume. Some tools generate in seconds and are ideal for storyboarding, social variants, and A/B testing hooks. Their output may not be final-quality, but it is good enough to validate a concept before you spend real time on it.
A simple decision rule: storyboard with the fastest model, lock the shot with the most controllable model, finish hero frames with the most photoreal model.
A step-by-step text-to-video workflow
This is the loop that consistently produces usable footage.
Step 1 — Write the shot, not the video
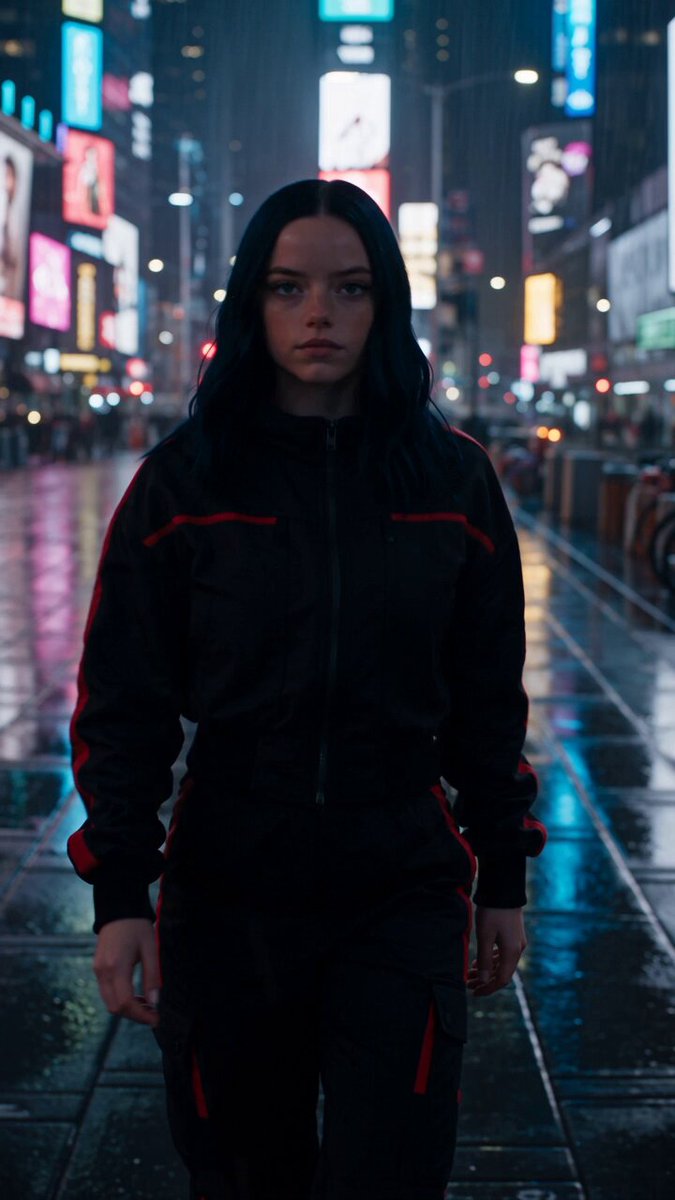
One prompt should describe one shot. "A cyclist rides through a rainy neon city at night, camera tracks alongside at wheel height, reflections ripple in puddles" is a shot. "A story about a cyclist" is not. Break your script into shots before you open any tool.
Step 2 — Define the constraints
Decide aspect ratio, duration, frame rate, and style before generating. Vertical short-form, widescreen brand film, and square social cuts need different compositions. Generate vertical footage and you will crop away half your framing later.
Step 3 — Build the prompt in blocks
Use a consistent order: subject, action, environment, lighting, camera, style, mood. Example: "A ceramicist's hands shaping wet clay, close-up, warm workshop light from the left, slow handheld drift, shallow depth of field, documentary realism, calm and focused mood." Block structure makes differences between variations obvious.
Step 4 — Generate in batches of four to six
The first attempt is rarely the best. Generate several variations with one variable changed at a time — camera angle, lighting, or pacing — so you learn what the model responds to. Keep notes; patterns emerge fast.
Step 5 — Select, then refine
Pick the best candidate and change only what bothers you. If the motion is too fast, adjust pacing rather than rewriting the whole prompt. If the composition is wrong, supply a first-frame image instead of fighting with words.
Step 6 — Extend or stitch
Most models generate short clips. If you need a longer shot, either extend within the tool using the last frame as the new starting point, or cut between related shots in the edit. Cutting is usually more reliable than extending, and it is what editors do anyway.
Step 7 — Finish in the edit
Add sound, music, color treatment, and titles. Sound is disproportionately important: audiences forgive imperfect motion far more readily than they forgive silence or mismatched audio.
Image-to-video: the consistency playbook
Image-to-video is where most professional work actually happens, because it solves the hardest problem in AI production: keeping things the same across shots.
First-frame control. Feed the model the exact composition you want as frame one. This eliminates composition drift and gives you a repeatable starting point for every variation.
First and last frame. Supplying both endpoints turns the model into a tweening engine. It is the cleanest way to execute a specific camera move or a transformation sequence.
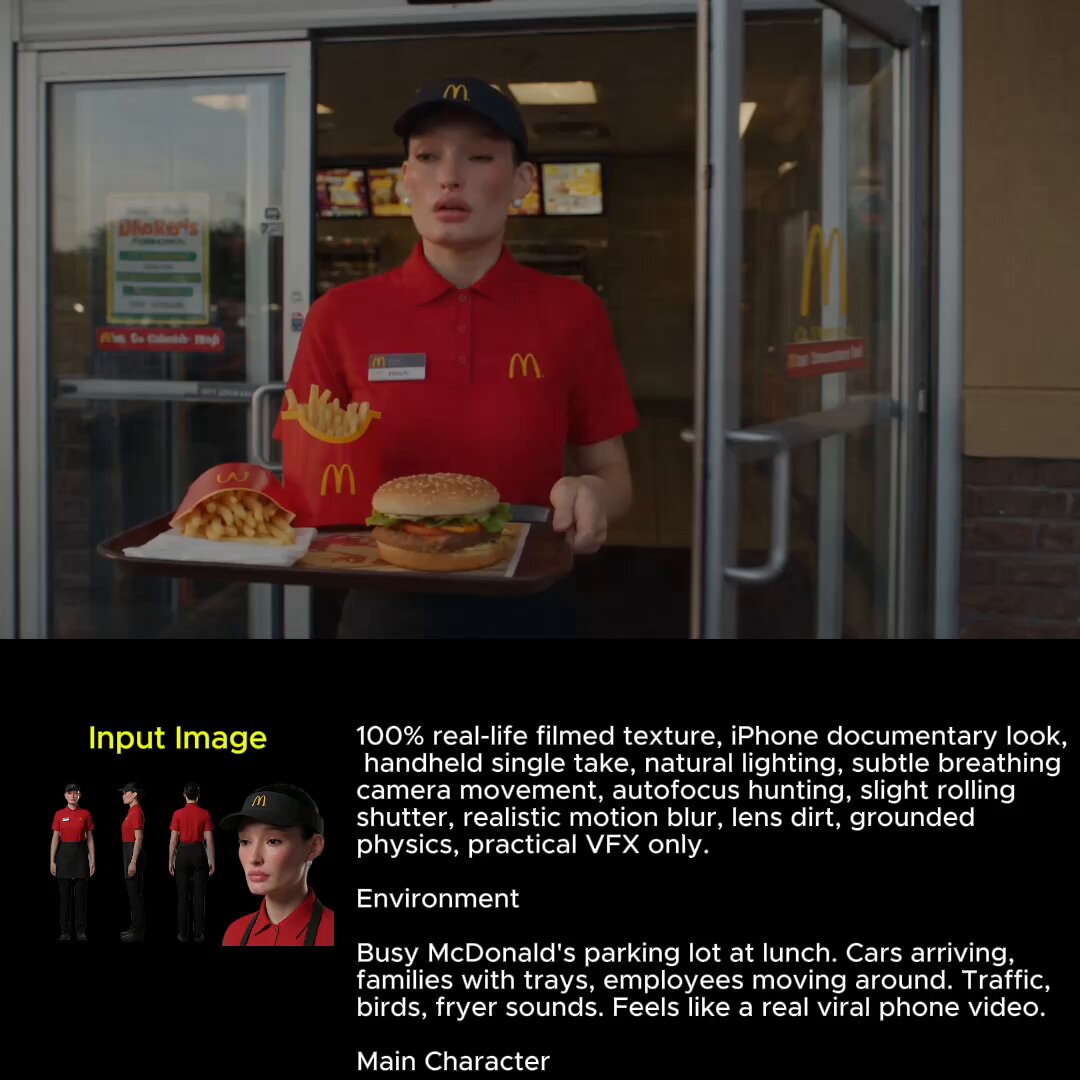
Character references. To keep a person recognizable across shots, build a small reference sheet: front, three-quarter, and profile views in consistent lighting. Reuse it every time. Changing the reference between shots is the fastest way to lose identity.
Style locks. If your project has a defined look, keep a style still alongside your character reference. Describe the look in words too — "muted teal shadows, warm highlights, fine film grain" — so both text and image are pushing in the same direction.
Environment continuity. Save establishing frames for each location and reuse them. Audiences track spatial logic even when they cannot articulate it, and shifting window placement between shots reads as a mistake.
Prop and wardrobe consistency. Small details sell continuity. Naming a specific jacket color or a specific product geometry in every prompt is tedious but effective.
Prompt patterns that produce believable motion
Motion is where AI video most often falls apart. A few habits help.
Use camera verbs, not adjectives. "Slow dolly in" and "handheld follow" give the model a physical instruction. "Cinematic" gives it a mood with no motion attached.
Give the subject one clear action. Two simultaneous actions — walking and turning and gesturing — often produce mush. One action per clip, then cut.
Respect physics explicitly. If a liquid pours, say so. If hair moves in wind, say so. Models default to smooth, weightless motion unless you ask for gravity, drag, and impact.
Control pacing with words. "Slow, deliberate" versus "quick, energetic" changes the entire feel of the same shot. Pacing is one of the most underused controls in prompting.
Use negatives sparingly and specifically. "No text overlays, no lens flare" is useful. A long list of prohibitions tends to flatten the image.
Match the shot length to the action. A three-second clip should contain one beat. Trying to fit an entire scene into five seconds produces a blur rather than a story.
Quality control: reviewing AI footage like an editor
Reviewing generated clips well is a skill. Run this checklist on every candidate.
Watch at normal speed first. Pause-free viewing reveals rhythm problems that frame-stepping hides. If it feels wrong at 1x, it is wrong.
Check faces early. Faces are the most scrutinized element and the most likely to degrade. Look for eye symmetry, teeth, and hair edges.
Check hands and interaction points. Anything touching something else — a hand on a railing, a cup on a table — can warp. Interaction points are where artifacts cluster.
Watch the background. Warping architecture, morphing crowds, and flickering windows are common. A stable background is a strong signal of a usable clip.
Verify continuity against neighbors. Compare the clip to the shot before and after it. Color temperature, exposure, and direction of movement should flow.
Score candidates against criteria. Note realism, motion quality, prompt fidelity, and continuity on a simple scale. Scoring prevents you from choosing the flashiest clip instead of the correct one.
Reject fast. If a clip fails two criteria badly, move on. Repairing a broken generation is usually slower than regenerating with a better reference.
Common mistakes and how to fix them
Overloading a single prompt. Ten ideas in one prompt produces a clip that does none of them well. Split into multiple shots.
Generating at final length from the start. Long generations are slow and expensive. Prototype short, then extend the winners.
Ignoring aspect ratio until the end. Cropping a widescreen generation to vertical destroys framing. Choose the delivery format first.
Changing five variables at once. You will not learn anything. Change one thing per batch.
No shot list. Without a plan, you generate clips that cannot be edited together. The shot list is what makes a folder of clips into a film.
Skipping color grading. A single grade across all clips unifies inconsistent generations almost instantly. It is the highest-leverage five minutes in post.
Forgetting audio. Silent AI video feels artificial. Even simple ambience and a music bed transform perceived quality.
No naming convention. With hundreds of files, shot_04_v3_firstframe.png beats final_final2.png every time.
Building a repeatable team workflow
Once the process works for one person, it needs structure to work for five.
Asset library. Keep approved character sheets, style stills, location frames, and brand colors in one shared place with clear version names. Most inconsistency in team projects comes from people using different reference files.
Prompt templates. Document the block order and the vocabulary your team uses. Shared language shortens onboarding dramatically.
Review gates. Define who approves a shot at storyboard, at first generation, and at final. Approving too late wastes generation time; approving too early locks in weak ideas.
Batch discipline. Assign generation work in batches tied to a shot list rather than ad hoc requests. It keeps throughput predictable.
Budgeting time, not just output. Estimate per shot: prompt building, generation, selection, and finishing. Most beginners underestimate selection and finishing by a wide margin.
Post-production integration. Decide early how generated clips enter your editing pipeline — resolution, frame rate, color space, and naming all matter before you have a hundred files to convert.
FAQ
Can I use AI-generated video commercially? Licensing varies by tool and plan. Check the terms of the specific platform you generate with, and keep records of which model produced which shot.
How long should a generated clip be? Short clips are more reliable. Generate three to five seconds, then cut or extend. Long single generations tend to drift.
Do I still need a script? More than ever. Models execute intent; they do not invent structure. A shot list is what turns generation into storytelling.
How do I keep a character consistent across shots? Use a reference sheet with multiple angles, reuse it unchanged, and restate key traits in text. Consistency comes from repetition of references, not from longer prompts.
Is image-to-video better than text-to-video? For controlled work, usually yes. Text-to-video is faster for exploration; image-to-video is better once you know what you want.
How many variations should I generate per shot? Four to six is a practical starting point. If none work, the problem is usually the reference or the shot definition, not luck.
What separates amateur from professional output? Editing, sound, and color. The generation step is only the beginning of the process.
Do I need multiple tools? Not necessarily, but most serious workflows use at least two: one fast model for exploration and one controllable model for final shots.
