
Why a Text Prompt and a Still Image Are Enough to Start
A few years ago, producing a video that looked intentional — good light, coherent motion, a real sense of style — required a camera, a crew, a location, and weeks of editing. Today the barrier has collapsed. You can write two sentences, drop in a reference image, and get back a five-second clip that reads as cinematic. That shift is not a novelty; it is a change in how content gets made.
The practical consequence is that the scarce resource is no longer equipment. It is taste, structure, and iteration speed. Anyone can generate a clip. Far fewer people can generate a clip that looks deliberate, fits a brand, and survives being watched on a phone at arm's length.
The most reliable approach today combines two inputs rather than relying on one:
- Text defines intent — subject, action, camera behavior, mood, pacing, and constraints.
- Images define appearance — palette, lighting direction, wardrobe, texture, composition, and the specific identity of a character or product.
Used together, they cover each other's weaknesses. Text alone drifts toward generic. Images alone tend to produce motion that ignores your narrative. Combining them gives you a controllable pipeline that behaves more like directing than like gambling.
This guide walks through the full process: how the technology works at a high level, how to select a generator for your use case, a repeatable production workflow, prompt patterns that consistently work, the mistakes that waste the most time, and a pre-publish checklist.
How AI Video Generation Actually Works
You do not need to understand the internals to get good results, but a working mental model saves enormous trial and error. Almost every modern video generator operates in three stages.
Stage one: the first frame
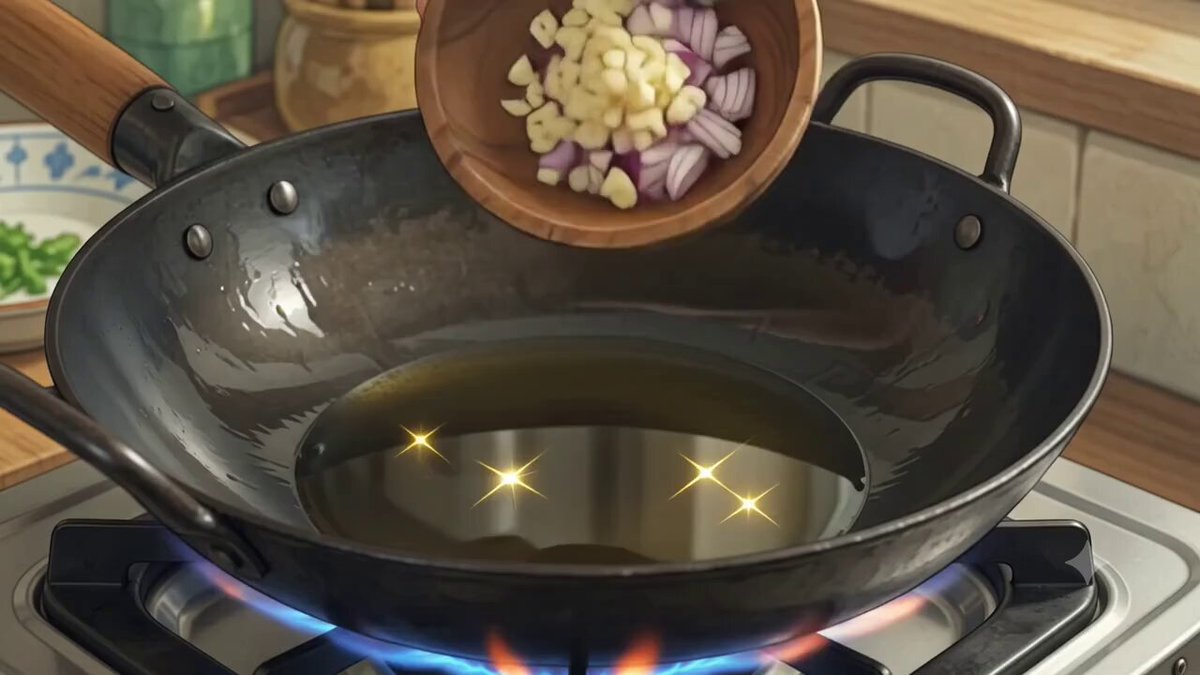
A diffusion-style model renders a still image from your text. This image determines roughly 70% of whether the final clip looks good. If the first frame has awkward hands, muddy lighting, or a cluttered background, motion will not rescue it. Professionals treat the first frame as a deliverable in its own right: generate stills, review them like a photographer reviewing contact sheets, and only animate the ones that already look right.
Stage two: motion synthesis
The model predicts how pixels move across a sequence of frames. Two families of technique dominate:
- Text-to-video invents everything from language. Maximum flexibility, least control over specific identity.
- Image-to-video animates a supplied still. Maximum control over appearance, but the model may invent details you did not ask for as soon as the subject turns or the camera moves.
A third approach — frame-to-frame or keyframe interpolation — sits between them. You supply two or more stills and let the model bridge the gap. This is how you lock a specific opening and closing composition while still getting smooth motion in between.
Stage three: temporal consistency
The hardest problem in AI video is keeping things stable over time. Faces warp, logos melt, fabric patterns crawl, backgrounds breathe. Generators solve this with varying degrees of success using reference conditioning, motion priors, and post-hoc stabilization.
Your job is to reduce the burden. Fewer moving parts means fewer things that can break. A single subject, a slow camera move, and a simple background will almost always beat an ambitious multi-character scene with fast action.
Choosing a Generator: Decision Criteria That Matter
There is no single best tool. There is a best tool for a specific shot, a specific deadline, and a specific budget. Evaluate options against these axes rather than against a feature list.
Control versus convenience
Some tools expose camera parameters, motion strength, seed locking, and negative prompts. Others give you a text box and a generate button. Convenience wins for volume work where "good enough and fast" is the goal. Control wins for hero content: product launches, title sequences, brand films. Most teams end up using both, routing simple shots to the fast tool and complex shots to the controllable one.
Realism versus stylization
Models trained heavily on photographic data produce believable skin, fabric, and reflections but struggle with illustration and anime. Models tuned for stylized output produce gorgeous graphic looks but make humans look uncanny. Match the model's bias to your brand rather than fighting it. If your brand is photographic, do not pick a stylized generator and try to prompt your way out.
Cost structure and throughput
Look at how pricing scales with resolution, duration, and retries. A cheap per-second rate is irrelevant if you need eight attempts per usable clip. Measure the real metric: cost per finished second, including failures. Also check queue behavior — a slow generation tier that costs less can still be the wrong choice when you are iterating against a deadline.
Duration limits and how they shape editing
Most generators produce short clips. This is a constraint, not a flaw. Treat generation as a shot factory and assemble sequences in a conventional editor. Teams that try to generate a full narrative in one pass almost always get worse results than teams that generate six three-second shots and cut them together.
Rights, licensing, and commercial use
Before building a pipeline, confirm that your chosen tool permits commercial use of outputs, that training data claims are acceptable to your legal team, and that you can document provenance if a client asks. This is unglamorous and it is the single most common reason a pilot project never ships.
The End-to-End Workflow: From Text and Images to Aesthetic Video
Here is a repeatable production process that works for solo creators and small teams alike.
Step 1: Write a shot list, not a prompt
Before touching any generator, write down what the finished piece needs to communicate. Then break it into shots. A 30-second piece typically needs six to ten shots.
For each shot, note four things:
- Subject and action — who or what, doing what.
- Framing — wide, medium, close, or extreme close.
- Camera behavior — static, slow push, orbit, tilt, handheld drift.
- Emotional tone — calm, tense, playful, luxurious.
This document becomes the source of truth. It also prevents the most common failure mode in AI video: generating attractive clips that do not connect to anything.
Step 2: Build a small reference library
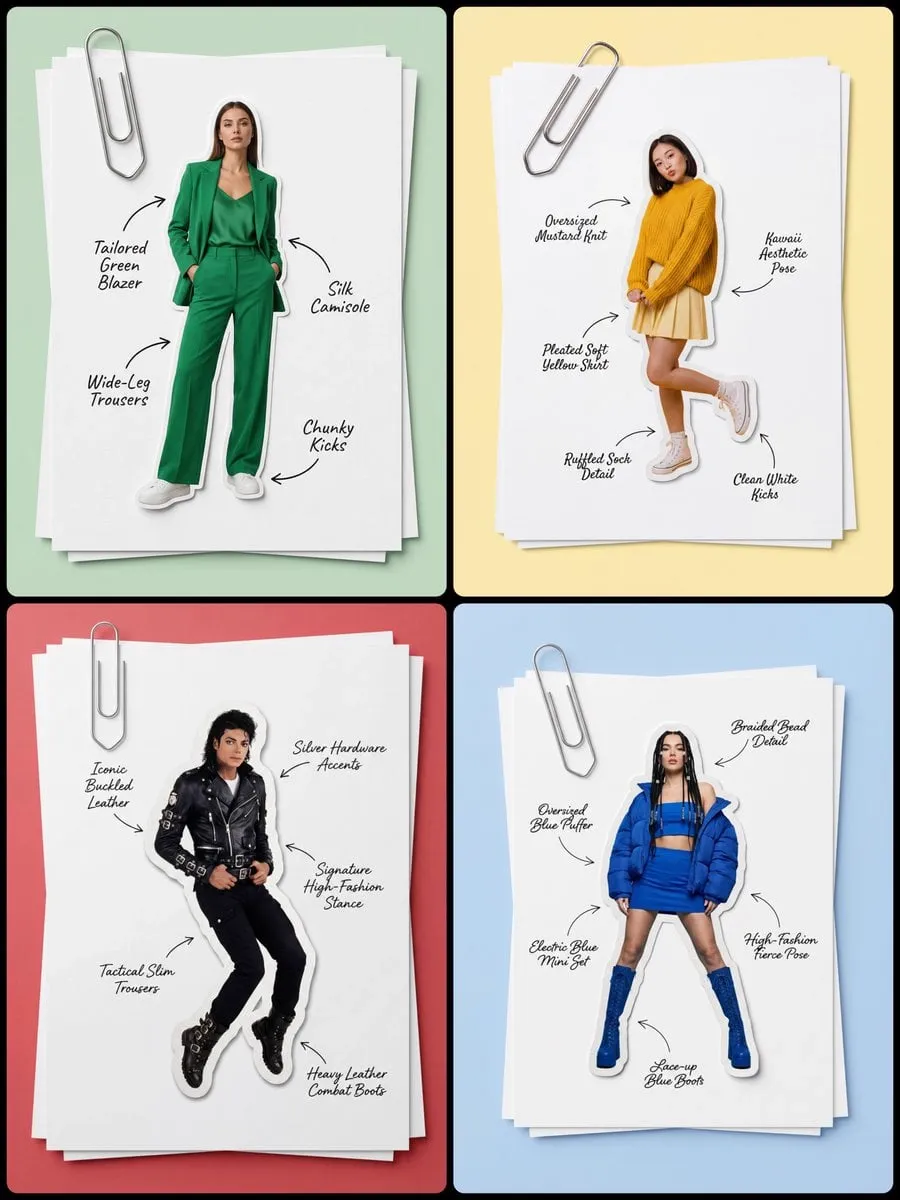
Gather or generate three to eight still images that define the visual language: a color palette reference, a lighting reference, a wardrobe or product reference, and one or two character references if people appear.
Keep the set small and consistent. Feeding a generator contradictory references produces mush. If your brand palette is warm amber, do not include a cold blue reference "for variety."
When characters recur across shots, create a dedicated reference sheet: front view, three-quarter view, and a close-up of the face. This single habit fixes more continuity problems than any prompt trick.
Step 3: Generate in small batches and review ruthlessly
Generate three to five variations per shot, not thirty. Review immediately, kill weak results fast, and adjust one variable at a time. If you change subject, lighting, and camera in the same revision, you learn nothing about which change helped.
Keep a simple log: shot number, prompt version, seed, and a one-word verdict. After twenty shots you will have a personal playbook of what your chosen model responds to.
Step 4: Stabilize, upscale, and grade
Raw generations rarely look finished. The polish comes from the post steps:
- Stabilization to remove micro-jitter, used sparingly — over-stabilizing creates a warped, rubbery look.
- Upscaling to your delivery resolution, ideally with a model trained on video rather than stills.
- Grading to unify color across shots that were generated at different times. A single look-up table applied to every clip does more for perceived quality than any individual generation.
- Grain and texture at a low opacity to blunt the overly clean, synthetic edge that gives AI footage away.
Step 5: Add sound, captions, and delivery formats
Sound carries more perceived quality than most creators expect. Three layers are usually enough: a bed of ambience, a music track, and one or two designed accents at cut points. If there is dialogue, generate or record it separately and edit to picture — do not rely on generated lip movement for anything close to the camera.
Export at least two aspect ratios. Vertical for short-form feeds, and 16:9 or 1:1 for web and presentations. Design your framing so the subject stays inside a central safe area; this lets you crop without re-rendering.
Prompt Patterns That Consistently Produce Aesthetic Results
Most bad prompts are vague in the dimensions that matter and over-specified in the ones that do not. These patterns fix that.
Describe the camera as if it were a person
Instead of "dynamic camera movement," write "slow dolly forward at eye level, subject centered, shallow depth of field." Instead of "cinematic," write "backlit by a low sun, warm rim light on the shoulder, soft haze in the background." Generators respond to concrete physical description far better than to adjectives borrowed from marketing.
Specify light before style
State the direction, quality, and color of the light. Hard or soft, warm or cool, from behind or from the side. Almost every "aesthetic" look is really a lighting decision. Once lighting is right, you can layer style words on top with far better results.
Use constraints to remove failure modes
Negative prompts and explicit exclusions save retries. Common ones worth adding:
- No text or watermarks in frame.
- No extra limbs, no duplicated faces.
- No rapid cuts within a single generation.
- No camera shake unless intentionally requested.
Keep prompts consistent across a sequence
When generating a multi-shot piece, reuse the same descriptive sentence for shared elements — the character, the location, the light — and change only the framing and action lines. Copying and pasting the stable core is faster and more accurate than rewriting prose each time.
Common Mistakes and How to Fix Them
Chasing realism instead of coherence. A slightly stylized clip with stable faces reads better than a photoreal clip where the subject's eyes change shape. If consistency fails, stylize.
Overloading a single prompt. Ten subjects in one shot means none of them render correctly. Split into multiple shots and edit.
Ignoring the first frame. If the opening still is weak, the clip is weak. Fix the still, then animate.
Generating at final length immediately. Iterate at low resolution and short duration, then re-render the winner at delivery quality. This alone can cut production time in half.
Skipping continuity references. Characters and products drift between shots without a reference sheet. Build one before you generate anything with a recurring subject.
Treating output as final. Nearly every publishable clip passes through stabilization, upscaling, and grading. Budget time for post or the work will look unfinished.
Ignoring the audio layer. Silent AI video feels like a demo. A music bed and two sound effects make it feel like a production.
Quality Control Checklist Before You Publish
Run every sequence through the same gate:
- Faces and hands hold their shape for the full duration.
- No logos, text, or brand marks appear that you did not intend.
- Color temperature is consistent from first shot to last.
- Motion is motivated — the camera moves for a reason, not by default.
- The first two seconds communicate the subject without sound.
- Captions are legible on a phone in bright light.
- Aspect ratios are exported for every platform you plan to use.
- You can document how each asset was generated if asked.
Where This Fits in a Real Content Calendar
AI generation is strongest at three jobs: filling gaps, testing angles cheaply, and producing scale that would otherwise be impossible.
A practical weekly rhythm looks like this. Use generated stills to mock up ten thumbnail concepts in an hour and test them before committing to production. Use short generated clips as B-roll under voiceover when a shoot would be disproportionate to the value. Use a consistent character reference to build a recurring series, which is where AI video genuinely outperforms traditional production — not because it looks better, but because it can sustain a weekly cadence without a crew.
Keep a library of approved prompts and reference images. Over time, this library becomes the real asset: a documented visual system that any team member can reproduce, regardless of which generator is fashionable that month.
FAQ
How long should a generated clip be?
Three to five seconds is the sweet spot for most work. Longer clips accumulate drift — faces soften, backgrounds wander. Generate short and assemble in an editor.
Do I need an image, or is text enough?
Text is enough for abstract or atmospheric footage. The moment a specific person, product, or location appears, an image reference will save you many retries.
Why do my results look generic?
Usually because the prompt describes a mood instead of a scene. Replace abstract adjectives with light direction, lens behavior, and concrete subject detail.
How do I keep a character consistent across shots?
Build a reference sheet with multiple angles, reuse the identical descriptive sentence in every prompt, and generate in the same session so your settings stay stable.
Can I use generated video commercially?
It depends entirely on the tool's terms. Check the license, keep records of how each asset was made, and confirm with your legal team before a client project ships.
What resolution should I deliver?
Generate at a workable intermediate size, then upscale to 1080p vertical or 4K horizontal depending on the platform. Upscaling after generation almost always looks better than generating at maximum size and accepting a high failure rate.
