
Why Text-to-Video Became a Real Production Tool
A few years ago, asking a model to turn a paragraph of prose into watchable footage produced surreal, melting results. Faces drifted, hands multiplied, and the camera seemed drunk. That era is over. Today's text-to-video systems understand camera language, respect compositional instructions, and can hold a character's identity across multiple shots. What changed is not just raw image quality — it is semantic accuracy, temporal stability, and the arrival of control layers that let a director shape a sequence rather than gamble on a slot machine.
The practical consequence is that a solo creator can now produce content that once required a crew, a location scout, a lighting package, and a week of shooting. Advertisements, explainer videos, social clips, music visuals, and even short narrative films can be assembled from written descriptions plus a handful of reference images.
But the tooling is only half the story. The creators who get consistently good results are not the ones who type the longest prompts. They are the ones who run a disciplined pipeline: script first, shot list second, model choice third, and a tight review loop at every stage. This guide walks through that pipeline end to end, from the first beat sheet to the final export.
Start With the Script, Not the Model
The most common beginner mistake is opening a generator before knowing what the video is about. Text-to-video rewards preparation because every generation costs time and compute, and vague inputs produce expensive randomness.
Begin with a beat sheet. Write down what the viewer should understand or feel at each moment, in plain sentences. A 60-second piece usually breaks into eight to twelve beats. Each beat becomes one shot or a small cluster of shots.
Turn beats into a shot list
A shot list is a table with five columns: shot number, duration, description, camera notes, and audio notes. Here is a compact example:
- Shot 01 (3s) — Wide establishing shot of a rain-slicked city street at dusk. Camera: slow push in. Audio: distant traffic, low synth drone.
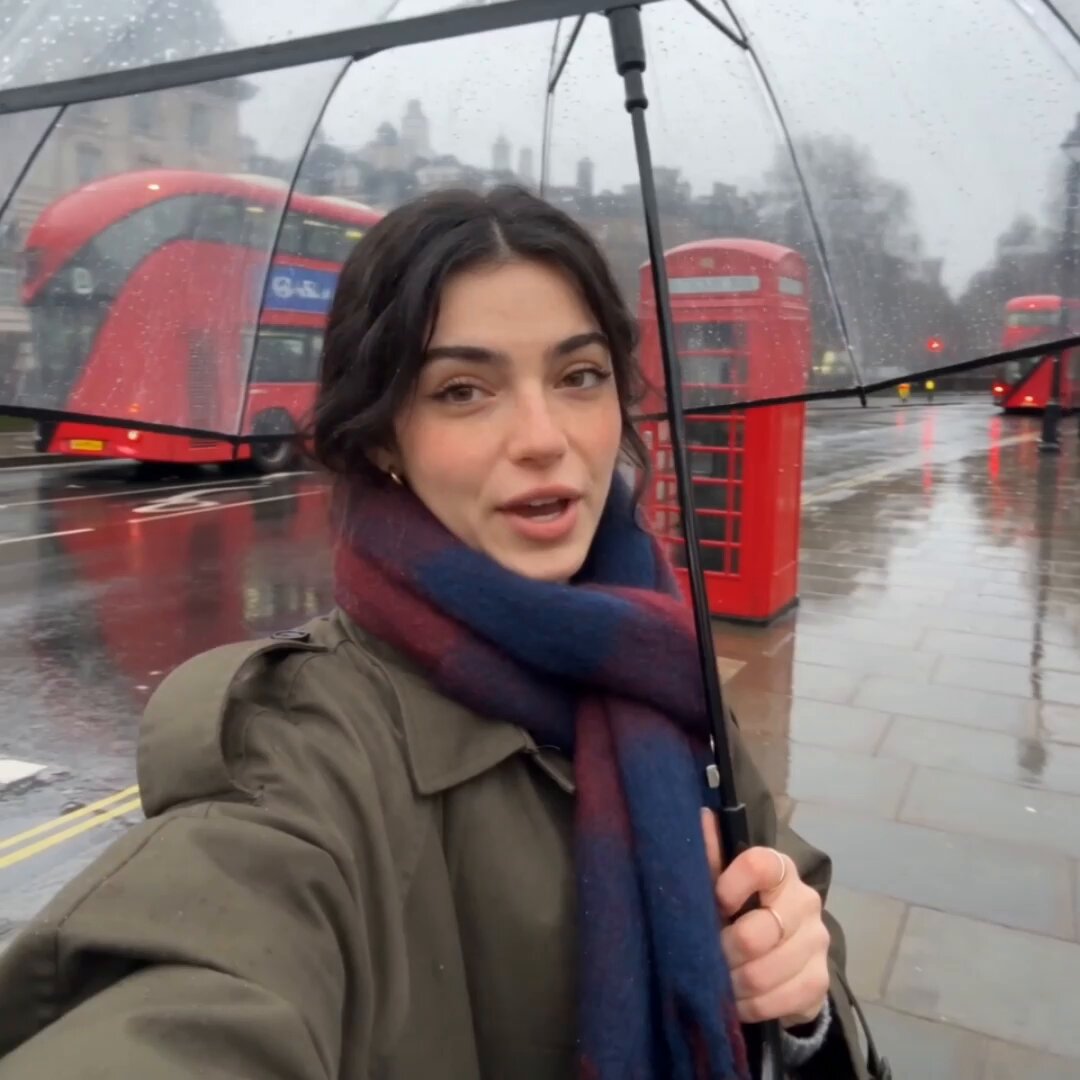
- Shot 02 (2s) — Close-up of a woman's hand closing an umbrella. Camera: static, shallow depth of field. Audio: fabric snap.
- Shot 03 (4s) — Medium shot, she walks toward a lit doorway. Camera: tracking left to right. Audio: footsteps, rising strings.
This level of detail matters because most video models accept references to shot size (wide, medium, close-up) and camera behavior (pan, tilt, dolly, crane) directly. If your shot list already speaks that vocabulary, translating it into prompts is nearly mechanical.
Define the look before you generate anything
Write a one-page visual bible: color palette, lighting mood, lens character, aspect ratio, and wardrobe. Keep it short enough to paste fragments into prompts. Consistency across a project comes from repeating the same stylistic anchors, not from hoping the model remembers.
Finally, decide the delivery format early. A vertical 9:16 clip for social feeds needs different framing than a 16:9 hero video. Generating in the wrong aspect ratio and cropping later destroys composition.
Choosing the Right Model for Each Shot
No single text-to-video model dominates every category. Some excel at photoreal human faces, others at stylized animation, others at fast motion or long continuous takes. Treat model selection as a casting decision.
Match capability to shot type
- Dialogue-heavy shots need strong lip sync and facial micro-expression. Prioritize models with dedicated audio or speech-driven modes.
- Action and sports need high motion coherence. Look for models that handle fast movement without smearing.
- Product and architectural shots need geometric accuracy, clean edges, and stable textures.
- Stylized or animated work benefits from models with strong artistic priors rather than photoreal fidelity.
- Landscapes and ambient B-roll are forgiving and often the fastest, cheapest way to test a new model.
Test before you commit
Run a standard test clip through any new model: one wide shot with movement, one close-up of a face, one shot with text or a logo, and one shot with a complicated hand action. Score each on prompt adherence, temporal stability, texture quality, and speed. Keep those test results in a spreadsheet. Within a few projects you will have a personal model matrix that saves hours.
Build a small bench, not a giant list
It is tempting to chase every new release. In practice, a working set of four to six models covers almost everything: one photoreal workhorse, one stylized option, one fast draft model for storyboards, and one specialist for close-up faces or dialogue. Rotate the bench slowly, only when a new model clearly beats an incumbent on your test clips.
Prompt Structure That Survives Rendering
Prompts are not incantations. They are structured briefs. A prompt that reliably produces usable footage usually contains six components, in roughly this order.
The six-part prompt formula
- Subject — who or what, described with two or three concrete details.
- Action — a present-tense verb phrase describing a single visible movement.
- Setting — location, time of day, weather, and era.
- Camera — shot size, angle, and movement.
- Lighting and color — key light direction, mood, palette.
- Style and texture — film stock, lens, render style, level of realism.
An example that follows this pattern: A woman in a charcoal wool coat walks toward a lit doorway; medium tracking shot from the left, dusk, wet pavement reflecting amber streetlights; soft key from the doorway, cool blue shadows, teal and amber palette; 35mm film look, subtle grain.
Notice that the prompt describes one action, not a sequence. If you want her to walk in and then sit down, that is two shots.
Say what the camera does, not what the story does
Models interpret literal camera instructions far better than emotional narration. "Slow dolly in" works. "The shot feels lonely and introspective" does not, unless you translate it into visual terms: wide framing, large negative space, muted desaturated palette, static camera.
Use negative guidance sparingly
Negative prompts help with recurring artifacts — extra fingers, distorted text, warped faces, jittery edges. But long lists of prohibitions can flatten the output. Start with three or four specific issues, and remove them once the model stops producing them.
Iterate in one variable at a time
When a shot fails, change one thing: the action verb, the camera move, the lighting, or the style reference. Changing everything at once means you learn nothing about what caused the improvement.
Consistency Across Shots: Characters, Props, and Locations
A sequence falls apart the moment the protagonist's face, jacket, or hairstyle shifts between cuts. Modern tools offer several ways to lock identity, and the strongest results come from stacking them.
Reference frames and identity anchors
Generate or select one clean, well-lit reference image of each main character. Use it as an image-to-video starting frame or as an identity reference within the model. Avoid reference images with dramatic shadows, motion blur, or extreme angles — they confuse the identity encoder.
Lock wardrobe and props in text
Even with reference images, describe the same clothing in identical words in every prompt. "Charcoal wool coat, brass buttons, burgundy scarf" repeated verbatim is more reliable than "dark coat" in one prompt and "heavy jacket" in the next.
Keep locations stable with a master plate
For each location, create one approved wide shot. Reuse its palette and lighting description in every subsequent shot at that location. If a model offers scene or style references, attach that master plate.
Accept controlled variation
Perfect pixel-level consistency is not the goal — believable continuity is. Small changes in lighting direction or framing read as natural coverage. Large changes in facial structure read as a different actor. Fix the latter; tolerate the former.
Directing Motion, Camera, and Pace
Motion is where AI video most often disappoints, and it is also where a few deliberate choices make the biggest difference.
Choose one dominant motion per shot
If the subject moves, keep the camera mostly still. If the camera moves, keep the subject relatively static. Two competing motions — a running figure with a whipping handheld camera — frequently produce mush. Save that combination for models with proven high-motion handling.
Match camera speed to emotional tempo
Slow pushes and gentle parallax create tension or intimacy. Fast whip pans and handheld energy create urgency. Because generated clips are short, pacing is largely created in the edit, but the camera move you request determines what the editor can do with the clip.
Generate handles for editing
Ask for a second or two of extra motion at the start and end of each clip. These handles give you room to trim on the beat without cutting into the action. Also, generate two or three variations of any shot that carries narrative weight — options are cheap compared to reshoots.
Respect physics, then break it deliberately
Models handle gravity, weight, and cloth reasonably well when the action is simple. Complex interactions — a person catching a falling object, a liquid pouring into a moving glass — still fail often. Simplify the action, or cut around it with a reaction shot.
Audio, Dialogue, and Lip Sync
Silent video is useful for B-roll and mood pieces, but most projects need sound. Two approaches dominate.
Generate dialogue inside the model
When a model supports speech, write short lines and keep the speaker's face clearly visible and evenly lit. Long monologues are hard; break them into sentences and alternate with reaction shots. Check phoneme alignment after generation — a consistent mismatch between mouth shapes and syllables is easier to redo than to fix in post.
Build audio separately and sync in the edit
For narration-driven content, record or generate a voice track first, then generate visuals to match. This is often faster and gives you tighter control over timing. Editing software with automatic sync aligns mouth shapes to audio even when the generated performance is imperfect.
Design the sound bed early
Ambience, music, and foley do enormous work. A slightly stiff generated shot with convincing rain, footsteps, and a low drone reads as intentional. The same shot in silence reads as a test render.
Editing and Post-Production Workflow
Editing is where generated clips become a film. A reliable workflow looks like this:
- Assemble rough order — drop all approved clips on the timeline in shot-list order, ignoring polish.
- Cut to rhythm — trim to the music or narration beat. Most generated clips are too long; shorten aggressively.
- Stabilize and smooth — apply subtle stabilization, and use optical-flow or frame interpolation only where judder is distracting.
- Color match — apply a shared grade across all shots so palette drift disappears. A simple LUT plus slight contrast adjustment goes a long way.
- Composite fixes — clean up hands, remove artifacts, or replace a background using masking and inpainting tools.
- Sound design — layer ambience, foley, and music. Duck music under dialogue.
- Titles and graphics — add captions, lower thirds, and end cards.
- Export and review on multiple devices — watch on a phone, a laptop, and a large screen before publishing.
Keep a naming convention for generated files that includes shot number and take letter. When a project has two hundred clips, searchable filenames save more time than any plugin.
Quality Control, Iteration, and Common Mistakes
A short checklist before you approve any shot:
- Does the shot match the script beat, not just look pretty?
- Is the subject's identity consistent with the previous shot?
- Are hands, teeth, eyes, and text legible and undistorted?
- Does motion stay coherent from first frame to last?
- Is the lighting direction consistent with neighboring shots?
- Does the clip have enough handles for trimming?
Mistakes that waste the most time
Generating before scripting. Without a shot list, every prompt is a guess.
Overloading prompts. Ten actions in one prompt produce a muddled average of all of them.
Ignoring aspect ratio. Cropping a 16:9 composition into vertical ruins framing and headroom.
Chasing perfection on every clip. A shot that reads correctly in a two-second cut rarely needs a seventh take.
Skipping the sound pass. Weak audio undermines strong visuals far more than weak visuals undermine strong audio.
Never archiving prompts. Store the exact prompt, seed, model, and settings for every approved shot. Reproducibility is your safety net when a client asks for one more variation.
Budgeting iterations
Assume three to five generations per finished shot, with more for complex action or dialogue. Front-load the hardest shots early in the project so you discover problems while you still have schedule room. Batch similar shots — same character, same location — to keep the model's context stable and your own attention efficient.
FAQ
How long should a generated clip be?
Generate three to eight seconds per shot, then cut down in the edit. Longer generations tend to drift in identity and motion. If a scene needs twenty seconds, build it from three or four shots rather than one long take.
Do I need to know how to shoot real video to get good results?
It helps, but you do not need equipment experience. What you need is the vocabulary: shot sizes, camera moves, lighting direction, and continuity rules. Learning those terms improves AI output faster than learning another tool.
What is the fastest way to fix an inconsistent character?
Go back to a clean reference image. Use it as the starting frame, repeat the exact same wardrobe and feature description in every prompt, and keep lighting consistent. If the model still drifts, reduce shot variety around that character for a few cuts.
Can I use generated video commercially?
That depends on the model's license and your local rules. Check the terms of the specific model you use, keep records of your inputs, and avoid generating recognizable real people, trademarks, or copyrighted characters unless you have rights.
Should I generate video at the final resolution?
Not always. Draft at lower resolution to approve composition and motion, then regenerate approved shots at full quality. This saves significant time on long projects.
How do I handle text and logos in generated footage?
Generated text is unreliable. Add titles, captions, and logos in post-production where you control typography, spelling, and placement.
What if a shot keeps failing no matter what I change?
Change the approach, not the wording. Split the action into two shots, switch to a reaction close-up, or cover the moment with a prop insert. Text-to-video is a coverage tool, and editors have solved difficult moments with coverage for a century.
How many models should I keep in rotation?
Four to six is plenty for most creators: a photoreal workhorse, a stylized option, a fast drafting model, and one or two specialists. Re-test your bench every few months and replace only what underperforms.
Is a storyboard necessary if the model generates from text?
Yes, in some form. Even a rough thumbnail per beat keeps you from generating clips that look good individually but do not cut together.
The bottom line: text-to-video rewards the same discipline that traditional filmmaking always has — clear intent, prepared coverage, consistent continuity, and a ruthless edit. The models will keep improving, but the workflow is what turns a folder of impressive clips into a video people actually watch to the end.
