
Why text-to-video is now a normal production step
A few years ago, turning a written script into footage meant cameras, lighting, actors, locations, and a schedule. Today a single creator with a laptop can produce a forty-second explainer, a product teaser, or a social ad without ever leaving the desk. The interesting part is not that this is possible at all. It is that the output has become good enough to publish.
The real shift is not that one tool does everything well. It is that the ecosystem has split into many specialized engines, each with a different feel, a different strength, and a different failure mode. Some handle realistic human motion beautifully but struggle with stylized environments. Others generate gorgeous landscapes but lose facial detail the moment a character turns. A few are excellent at fast camera moves, and others excel at slow, cinematic drift.
That fragmentation is the actual challenge. Beginners assume the hard part is writing a clever prompt. In practice, the hard part is knowing which engine to point that prompt at, how to keep a character recognizable across five shots, and how to stitch the results into something that feels intentional rather than assembled.
This guide walks through a complete text-to-video workflow: planning shots, writing prompts that survive iteration, choosing a model based on the shot rather than the hype, maintaining visual continuity, and running quality control before anything goes live. It is written for people who want a repeatable process, not a list of tools to collect.
The four stages of a text-to-video pipeline
Most failures in AI video come from skipping a stage or doing them out of order. Treat the process as four distinct phases, each with its own success criteria.
Stage 1: Script to shot list
A script is not a shot list. The script says what the video communicates. The shot list says what the camera sees, in what order, for how long, and with what motion. Before touching any generation tool, write a table with one row per shot containing: shot number, description, duration in seconds, camera behavior, and the on-screen text if any.
A twenty-second video usually needs four to six shots. A sixty-second video usually needs ten to fourteen. If your shot list has one shot per sentence, it will feel restless. If it has one shot for thirty seconds, viewers will drift.
Stage 2: Shot generation
This is where model choice matters most. Generate shots individually rather than trying to render a whole sequence in one pass. Individual shots give you the ability to re-roll only what failed, which keeps iteration fast and predictable.
Label every output file the moment you download it: shot number, engine used, prompt version, and take number. A folder full of output_final_2.mp4 files will cost you more time than any rendering delay.
Stage 3: Assembly and sound
Bring the clips into a standard editor. Trim each clip to the beat it needs, not to the length the generator returned. Add music, voiceover, and sound effects here rather than trying to bake them into generation. Sound design is what separates an AI demo from a finished piece of video.
Stage 4: Delivery and versioning
Export in the aspect ratios your channels require, then keep the project file intact. Text-to-video work almost always comes back for revisions, and being able to re-render one shot without rebuilding the edit is a huge advantage.
Choosing an engine: decision criteria that actually matter
Model comparison charts tend to rank everything on a single quality axis. Production work needs a more practical set of questions.
Shot type compatibility
Ask what the shot is. A talking-head close-up has very different requirements from a wide drone-style establishing shot. Some engines produce convincing skin texture and lip movement in close-ups but render crowds as mush. Others excel at sweeping environmental motion but distort faces at medium distance. Match the engine to the shot category, not the project as a whole.
Motion complexity and camera control
Simple motion — a hand reaching for a cup, steam rising, hair moving — is broadly solved. Complex motion — a dancer spinning through a crowd, a car turning while the camera orbits — is where engines diverge sharply. If your shot depends on a specific camera move, test that move in isolation before committing the whole sequence to one engine.
Visual consistency across a series
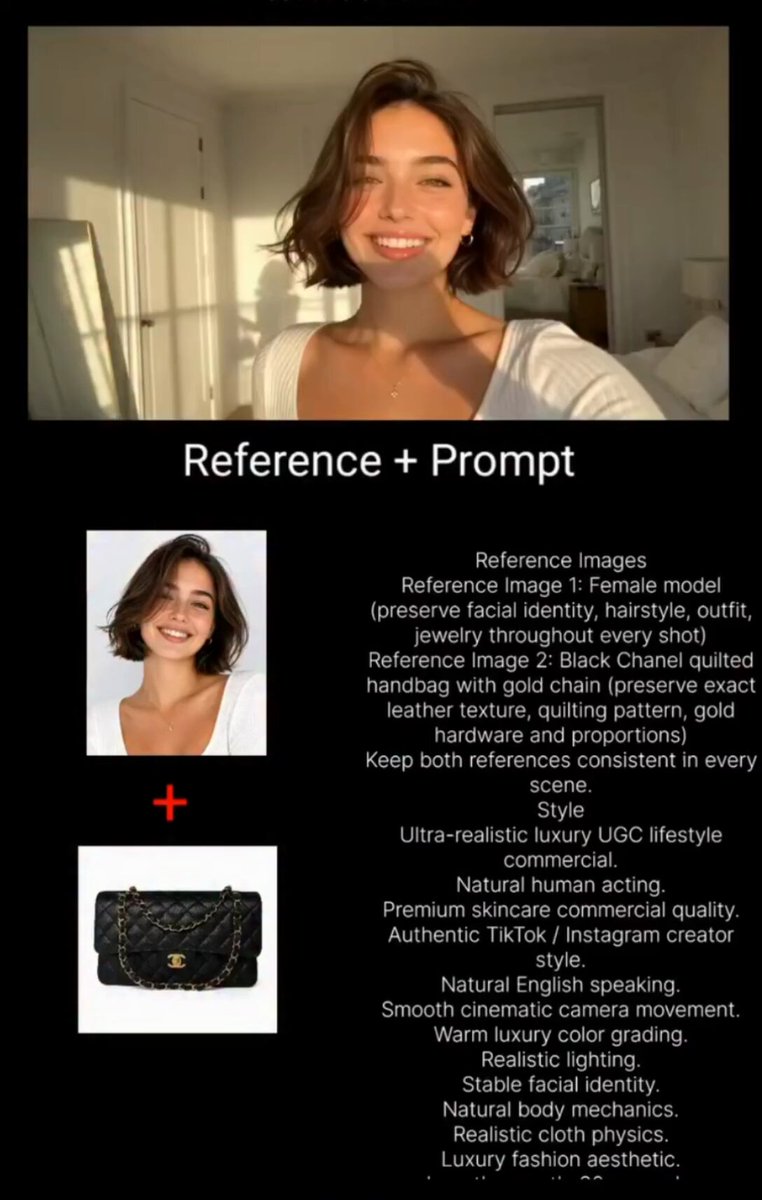
If you are producing one video, consistency is a nice-to-have. If you are producing a series with the same presenter, product, or location, consistency becomes the primary criterion. Choose the engine that lets you anchor to a reference image or a first frame, even if its raw aesthetic is slightly less impressive.
Duration and resolution limits
Most engines have a sweet spot. Generating four to six seconds usually produces the cleanest results; pushing far beyond that tends to introduce drift, morphing, or sudden changes in lighting. Plan your shot list around the sweet spot and use cuts rather than long continuous takes.
Iteration speed and cost predictability
Fast iteration beats perfect first output. A tool that returns a usable take in thirty seconds lets you explore five variations and pick the best one. A tool that takes ten minutes per attempt forces you to accept the first result. Budget your time around how many attempts you realistically need per shot — usually three to six.
Text-to-video versus image-to-video
Text-to-video is best for establishing shots, abstract sequences, and anything where exact composition does not matter. Image-to-video is best when composition matters: product shots, character close-ups, branded environments. Generate or source a still image first, approve it, then animate it. This one habit removes most continuity problems before they start.
Prompt architecture: the structure that reduces re-rolls
Freeform prompts produce unpredictable results. A structured prompt produces results you can debug, because when something goes wrong you know which slot caused it.
The six-slot prompt
Write every prompt in the same order:
- Subject — who or what, described specifically (age, wardrobe, material, color).
- Action — the single verb-driven change happening in the clip.
- Camera — framing and movement (static wide, slow push in, handheld follow).
- Lighting — direction and quality (soft window light from the left, hard noon sun, neon spill).
- Style — the look reference (documentary, glossy commercial, matte film, clean 3D render).
- Constraints — what must stay stable and what must not appear.
A worked example: "A ceramic coffee cup on a pale oak table, steam rising slowly, static medium close-up with a very slow push in, soft morning light from the left with visible shadow, clean commercial product style, no text, no hands, stable background."
Every slot earns its place. Remove the lighting slot and the clip may look flat. Remove the constraint slot and you may get a logo or a stray hand.
Style and look control
Style words behave like a dial, not a switch. Stacking four style adjectives usually produces muddy results. Pick one primary look and one secondary modifier: "documentary" plus "slightly desaturated," not "cinematic hyperrealistic moody dramatic 8K." If the engine supports style references or look-up presets, use them — they are more reliable than adjectives.
Negative prompts and constraint lists
Negative prompts are the cheapest quality improvement available. Keep a reusable block: no text, no watermarks, no extra limbs, no warped faces, no sudden cuts, no camera shake. Add project-specific exclusions as you discover them. Every time a generation fails in a new way, add that failure to the block.
Iterating without losing what worked
Change one slot at a time. If a take has perfect lighting but the action is wrong, keep everything else and rewrite only the action. This sounds obvious, but most people rewrite the whole prompt and then cannot tell which change helped. Keep a prompt log with version numbers so good results stay reproducible.
Consistency across shots: characters, props, and locations
Continuity is where amateur AI video becomes obvious. A jacket changes color between shots. A room's window moves. A character's face subtly shifts. Fixing this requires deliberate anchoring.
Reference images and first-frame anchoring
The most reliable continuity method is to generate a still of the character or location, approve it, and use it as the starting frame for every shot in that scene. The engine then animates a known-good image rather than inventing a new one. This costs an extra step and saves entire afternoons.
Wardrobe and color locking
Describe wardrobe in exhaustive, unpoetic detail: "olive canvas jacket, brass zipper, dark grey t-shirt underneath." Vague descriptions invite drift. Also lock your color palette: if the video uses a warm ochre and teal palette, say so in every prompt. Consistent palette is often what makes a sequence feel professionally graded even when individual shots vary.
Location continuity and lighting direction
Decide once where the light source is and repeat it in every prompt for that scene. If shot one has window light from the left, shot two must too, or the cut will feel wrong even to viewers who cannot explain why. Write the lighting direction into your shot list so you never have to remember it.
Pacing, aspect ratio, and sound decisions
Choosing aspect ratio
Vertical 9:16 for short-form social, square 1:1 for feed placements, 16:9 for websites and presentations. Decide before generating, because reframing after the fact crops composition and often cuts off motion that mattered. If you need multiple ratios, generate the widest version first and crop down.
Shot duration rhythm
Alternate longer and shorter shots rather than keeping everything at four seconds. A rhythm like 5-2-3-6-2-4 feels intentional. Uniform durations feel mechanical. Match duration to information density: a shot with a lot of new visual information needs more time; a reaction shot needs almost none.
Voice, music, and sound effects
AI generation produces silent clips, and silence reads as unfinished. Three layers fix this: a music bed for energy, a voiceover for explanation, and small effects — whooshes on transitions, a subtle click on a product reveal — for polish. Sound effects are also the cheapest way to hide a slightly imperfect transition.
Captions and readability
Most social video is watched muted. Burn in captions or provide a subtitle track, keep them to two lines maximum, and place them away from faces and key product detail. Check readability on a phone at arm's length, not on a desktop monitor.
Worked example: a thirty-second product explainer
Step 1 — Write backward from the call to action
Start with the final line and the final image. If the video ends on a product shot with a clear action, everything before it exists to make that ending land.
Step 2 — Build five shots
- Problem shot — a cluttered desk, slow push in, natural light.
- Frustration close-up — hands sorting papers, static shot.
- Transition — the product placed on the desk, macro detail, slow orbit.
- Benefit shot — the tidy result, wide static shot with warm light.
- Call to action — product centered, clean background, minimal motion, room for text.
Step 3 — Generate in batches and label everything
Generate three takes per shot, download, and label. Reject anything with unstable edges or shifting background geometry immediately — those rarely survive the edit.
Step 4 — Edit for rhythm
Cut the first eight frames of most generated clips; the opening often contains a settle-in wobble. Trim to the beat, add music, then add a voiceover recorded to picture rather than the reverse.
Step 5 — Finish
Add captions, apply one consistent color adjustment across all clips so the palette matches, and export both 16:9 and 9:16 versions. The color pass is what makes five separately generated clips look like one video.
Common mistakes and how to fix them
Overloading a single prompt. If your prompt contains three actions, the engine will pick one or blend them badly. Fix: one action per clip.
Ignoring the first and last frames. Generators often drift at the edges. Fix: plan to trim the beginning and end of every clip.
Mixing engines without a visual pass. Different engines have different color science. Fix: a shared grade, a shared LUT, or a shared palette instruction in every prompt.
Using long takes for convenience. Long generations drift. Fix: more shots, shorter durations, harder cuts.
Skipping sound until the end. Fix: lay in scratch music before you edit picture so you cut to rhythm.
Rendering at the wrong resolution. Upscaling a low-resolution generation rarely looks clean. Fix: generate at the highest practical resolution for hero shots.
No version discipline. Fix: name files shot03_engine_v2_take02 and never rename during the edit.
Quality-control checklist before publishing
Run every video through the same list: Is the subject stable across cuts? Does lighting direction stay consistent? Are hands and faces clean at full size? Is there flicker in the background? Does the first second communicate the subject without sound? Are captions free of typos and inside safe margins? Does the video end with a clear next action? Does it hold up at 50% brightness on a phone screen?
If any answer is no, fix that item before adding anything new. Polishing a weak structure wastes time; fixing structure first compounds quality.
FAQ
How many takes should I plan per shot?
Three to six for hero shots, one to three for supporting shots. Budget time for iteration rather than assuming the first result will be usable.
Is text-to-video or image-to-video better for branded work?
Image-to-video, almost always. Approving a still first gives you composition control and makes continuity dramatically easier.
How long should each generated clip be?
Four to six seconds is the reliable zone for most engines. Build longer sequences from multiple short clips rather than one long generation.
What is the fastest way to improve overall quality?
Add a consistent color pass and a sound design layer. Those two steps change perceived quality more than switching engines.
Can I mix multiple engines in one project?
Yes, and it is often smart. Just unify the look afterward with a shared grade and a shared palette instruction during generation.
How do I keep a character consistent across a series?
Create one approved reference image, reuse it as the first frame in every scene, and describe wardrobe and features identically in every prompt.
What should I do when a shot keeps failing?
Simplify it. Reduce the action to a single verb, remove secondary motion, and shorten the duration. Complexity is the usual cause of repeated failure.
