
Why Text-to-Video Became a Core Production Skill
Text-to-video generation has quietly stopped being a party trick. A couple of years ago, the technology was judged by whether a clip looked impressive for five seconds. Today it is judged by whether it survives an edit — whether the footage cuts together, whether the character still looks like the same person in shot twelve, and whether the whole thing can be delivered on a deadline without the budget of a traditional shoot.
That shift matters because it changes what you optimize for. A generative demo rewards spectacle. A production rewards reliability, repeatability, and control. When you are building an ad variant, a short explainer, a social hook, or a previsualization pass for a client pitch, you are not looking for the single most beautiful frame. You are looking for a system: a repeatable way to turn a script into shots, shots into clips, and clips into something a viewer will actually watch to the end.
This guide is a working method for that system. It assumes you have access to a handful of generative video tools — some strong at motion, some strong at realism, some strong at stylized animation, some strong at image-to-video with reference locking — and it focuses on the part that most tutorials skip: deciding which tool to point at which shot, and how to keep the result coherent when you switch between them.
The Core Workflow: From Script Beat to Approved Clip
Most disappointing AI video projects fail before generation starts. The script was never broken into shots that a model could plausibly render, so every clip is fighting a losing battle against an impossible brief. The fix is a short, disciplined pipeline.
Step 1: Break the script into beats. One idea per three to six seconds. If a sentence contains two ideas — a character walks in and notices something — that is two beats, and probably two shots.
Step 2: Convert beats into a shot list with intent. Every shot gets a single sentence describing what the viewer must understand from it. This sentence is your acceptance criteria. If a generated clip is beautiful but does not communicate the intent, it is not done.
Step 3: Lock the look before you animate. Generate still frames first wherever the tool supports image-to-video. Stills are cheap, fast, and easy to iterate. Once you have approved frames, animating them removes most of the chaos that comes from prompting motion directly.
Step 4: Produce three to five variants per shot with small prompt deltas. Change one variable at a time — camera move, lighting, wardrobe color — so you can attribute the difference and learn what your model responds to.
Step 5: Select on story clarity, not wow factor. The most cinematic clip is often the one that draws attention away from the point of the shot.
Step 6: Assemble, then repair continuity. Editing reveals problems that individual clips hide: mismatched color temperature, inconsistent pacing, a prop that jumps sides between cuts.
A thirty-second product teaser built this way typically needs six to nine shots and somewhere between forty and eighty generated clips. That sounds excessive until you compare it to the alternative: fifty generations of the same five-second shot, hoping for a miracle.
How to Choose the Right Model for Each Shot
Different generative video models have genuinely different personalities, and treating them as interchangeable is the fastest way to waste time. Before you open a tool, write down the criteria that actually matter for the shot in front of you:
- Motion fidelity — how well the model handles complex, physically plausible movement.
- Prompt adherence — how literally it follows the specifics of your description.
- Duration ceiling — the longest usable clip length before quality decays.
- Consistency controls — image references, character locking, seed reuse, or style presets.
- Audio and lip sync — whether dialogue and voice can be generated with the picture.
- Throughput — how fast you can get a usable take, not just how good the best take is.
- Resolution and upscaling path — the native output size and how gracefully it scales up.
- Licensing and commercial terms — what you are allowed to do with the output.
With that list in hand, shot types sort themselves fairly quickly.
Dialogue and close-ups
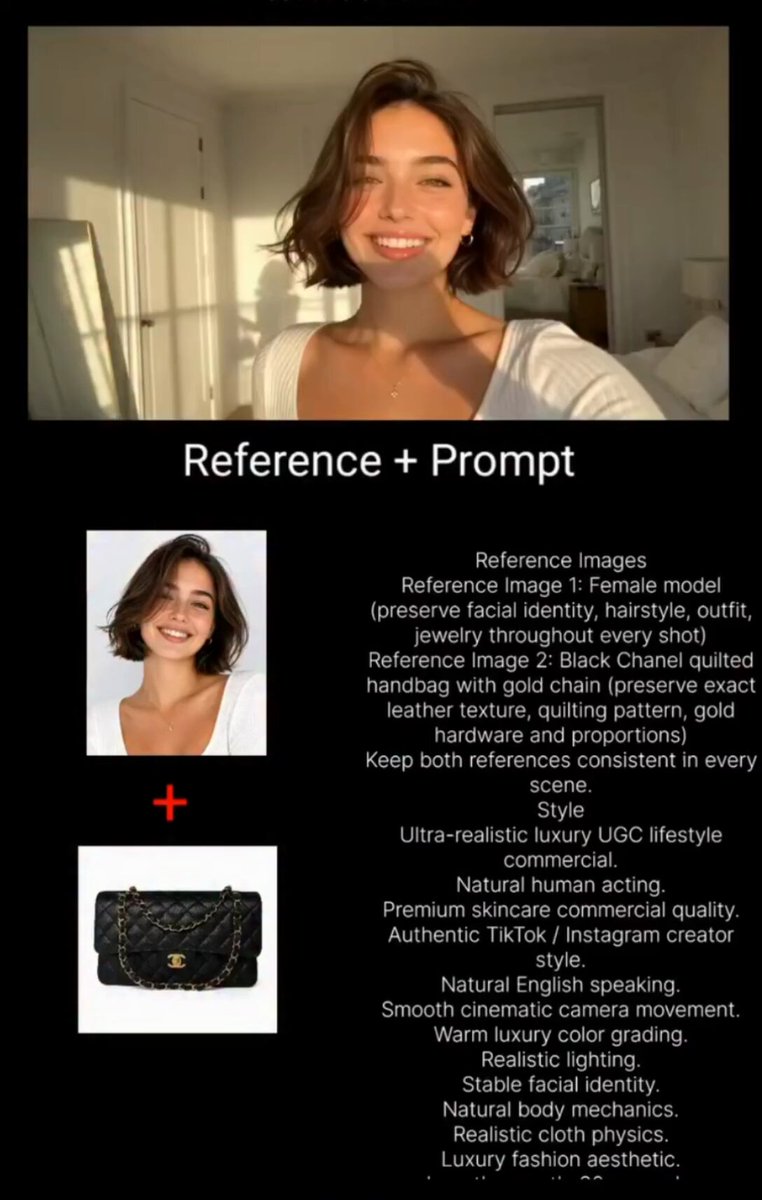
Prioritize facial stability and lip sync over camera ambition. Use models with strong image-reference support so the same face carries across shots, and keep camera movement minimal — a slow push or a static frame. Talking heads are where over-eager camera work looks worst, because the audience is reading the face, not the frame.
Wide establishing shots and landscapes
Here you want scale, atmosphere, and slow movement. Models that excel at large-scale environments often handle parallax and haze better than they handle people, which is fine: an establishing shot rarely needs a recognizable protagonist. Generate these early, because they set the color palette the rest of the edit will follow.
Action, sports, and camera moves
Fast motion is the hardest case. If the tool supports image-to-video with a defined start frame, use it. Avoid stacking a moving camera on top of a fast-moving subject — pick one. When in doubt, generate the action at a calmer camera speed and add energy in the edit with cuts and sound.
Product, food, and packshots
These live or die on detail fidelity: label legibility, surface texture, liquid behavior. Realistically, most generative models still struggle with small text and precise branding. A pragmatic hybrid works better — generate the environment and camera movement, then composite a real product photograph or a rendered 3D element into the frame during post.
A Prompt Framework That Works Across Models
Every model has its own quirks, but a consistent prompt structure makes switching between them far less painful. A reliable formula looks like this:
Shot size and camera move + subject with two or three stable descriptors + one action verb + only the environmental details that matter + lighting direction + lens or film look + one explicit constraint.
A weak prompt: "A woman in a city looking sad, cinematic."
A stronger prompt: "Medium close-up, slow handheld push-in. Woman in her thirties, dark curly hair, olive wool coat, standing under a shop awning. She glances down at her phone and exhales. Rain on the pavement behind her, neon signs out of focus. Cool blue key light from above, warm spill from the shop window. 50mm lens, shallow depth of field. No text in frame."
The difference is not length — it is specificity that the model can act on. "Sad" is a performance direction; "exhales after glancing at her phone" is a visible event.
Two habits make this framework compound in value. First, build a style bible: one or two sentences describing palette, lens, grain, and mood, repeated verbatim in every prompt for a project. That single repeated line does more for visual coherence than any post-processing filter. Second, keep a prompt log — a spreadsheet with the prompt, model, seed, and a rating. After a week you will know which phrasing your tools actually respond to.
On negative prompts: some models honor them well, some ignore them entirely, and some treat them as suggestions that subtly distort the image. Whenever possible, phrase constraints positively. Instead of "no crowds," write "empty street."
Consistency: The Hardest Problem in AI Video
Nothing breaks the illusion faster than a character whose face, hair, or jacket changes between cuts. Consistency is not a single feature you enable; it is a set of overlapping habits.
Build a cast sheet. For every recurring character, write a short markdown file: age range, hair, distinguishing features, wardrobe, and a shortlist of three approved reference images. Paste the same descriptors into every prompt that features them, in the same order. Order matters more than you would expect.
Prefer image-to-video for recurring characters. A locked still is the strongest identity anchor available. Generate the still, approve it, then animate it — and reuse the same still as a reference across the sequence.
Keep camera distance similar. A face that holds up in a medium shot may fall apart in an extreme close-up. If a character must appear in both, generate the tighter shot separately and check it before committing.
Batch in one session. Model versions and default settings drift. Producing all shots featuring one character in as few sessions as possible reduces invisible drift between clips.
Anchor locations too. Create a location plate — one wide shot of the space — and reference it whenever you return there. Audiences forgive a lot, but they notice when a room rearranges itself.
Finally, accept that some inconsistency is unavoidable and plan the edit around it. If a character looks slightly different in a wide shot, cut away on motion, shorten the clip, or place it after a reaction shot. Editing is still the most powerful consistency tool you have.
Storyboarding and Agentic Direction Without Losing Control
A growing category of tools offers automatic direction: you describe a scene, and the system proposes shot breakdowns, camera angles, and pacing. Used well, this is a genuine accelerant. Used carelessly, it produces video that feels like a template.
The productive pattern is draft, then decide. Let the tool generate a shot breakdown from your script — beat by beat, with suggested framing and camera movement. Then edit that breakdown like a producer. Delete anything that exists only to look impressive. Merge shots that repeat the same information. Add a reaction shot where the automated version jumps straight to the payoff.
Two rules keep automation honest. First, never let the tool choose your final pacing; the rhythm of a video is a creative argument, and generic tools default to the middle. Second, keep a human-approved storyboard frame for every shot before mass generation begins. Ten approved frames prevent a hundred wasted renders.
For pitch work, storyboard frames generated quickly are enormously useful — you can show a client a visual plan in an afternoon and revise it in an hour. Treat them as communication artifacts rather than finished assets, and be explicit with clients about what is a sketch and what is a final render.
Post-Production: Assembly, Sound, and Delivery
Generated clips become a video in the edit, and this stage deserves more attention than it usually gets.
Assembly. Cut on motion. Generated clips often have a tell — a slight softening or a drifting background around the two-second mark — and hiding the cut inside movement disguises it. Keep clips shorter than you think you need.
Frame rate and speed. Clips generated at one frame rate and delivered at another can look subtly wrong. Conform everything to a single timeline frame rate, and use speed ramps sparingly; slowing generated footage exaggerates artifacts.
Upscaling. Most tools output at a lower resolution than delivery specs. Build an upscale step into the pipeline rather than stretching in the timeline, and apply light sharpening after upscaling, never before.
Sound. Audio does the heaviest lifting in perceived quality. Ambience beds, foley for movement, and a music track that changes at least once will make a modest visual sequence feel professional. If you are generating voice, record a scratch read first so you know the timing you are cutting to.
Delivery formats. Decide aspect ratios at the start. Vertical, square, and widescreen versions of the same project are not crops of one master; each needs slightly different framing, which means generating wider coverage than you think you need.
Managing Cost, Speed, and Renders
Generative video is an iterative medium, and the cost of iteration adds up faster than the cost of final renders. Three habits keep it under control.
Iterate at low fidelity. Draft at the smallest resolution and shortest duration your tool allows, and only spend on high-quality renders once a shot is locked. Rough cuts made from low-resolution drafts are perfectly readable for editorial decisions.
Use a 70/20/10 split. Seventy percent of takes should be cheap exploration, twenty percent refinement of an approved direction, and ten percent final quality renders. Projects that invert this spend everything on polish for shots that get cut.
Queue long jobs deliberately. Batch renders overnight or during meetings. Keep a simple render log with date, shot, model, settings, and rating — when a client asks for "the version from last week," you will be able to find it.
Speed is also a creative constraint worth respecting. If a shot takes twenty minutes to iterate, you will unconsciously stop experimenting. Choose faster tools for exploration and reserve slower, higher-quality ones for locks.
Common Mistakes and Troubleshooting
Cramming two actions into one shot. Split it. Almost always split it.
Moving camera plus moving subject. Choose one. Two simultaneous motions are where most models produce mush.
On-screen text in generated footage. Rarely legible. Add text in post, always.
Uniform lighting across every shot. Real productions vary light by location and time. Sameness reads as artificial.
Using one tool for everything. Different shots genuinely suit different models. Switching is not a failure of loyalty; it is craft.
Forgetting audio planning. Sound designed after the picture is locked will force compromises. Think about it during the shot list.
No continuity pass. Watch the cut once with the sound off, looking only for prop, wardrobe, and color mismatches. Then watch it once with your eyes closed, listening for pacing.
FAQ
How long should an AI-generated clip be?
Target three to five seconds for most shots. Longer clips are possible, but quality and consistency tend to degrade, and the edit rarely needs them.
Do I need several different video tools?
Not necessarily, but most working creators keep two or three: one for realism and people, one for stylized or fast motion, and one for image-to-video with strong reference locking.
How do I stop characters from changing between shots?
Approved reference stills, identical descriptive phrasing in every prompt, consistent camera distance, and batching shots per character in one session.
Can generated video be used for client work?
Often, yes — but check the commercial terms of each tool, avoid recognizable real people and trademarks you do not own, and disclose your process if the client expects live footage.
What is the fastest path to a decent first cut?
Write a shot list, generate stills, animate only the approved frames, assemble at low resolution, then re-render winners at full quality.
Why does my footage look "AI"?
Usually over-smooth motion, uniform lighting, shallow depth of field on every shot, and no sound design. Vary the lighting, cut faster, and add ambience.
Building Your Own Repeatable Pipeline
The value of text-to-video is not any single generation. It is the pipeline around it: a shot list that respects what models can do, a prompt framework you trust, a cast sheet that keeps characters recognizable, an assembly process that hides seams, and a render budget that survives revision.
Start small. Pick one thirty-second scene, build the full pipeline end to end — beats, stills, animation, edit, sound — and keep a written log of what worked. The second project will take half the time, and by the third you will have something more useful than any tool subscription: a method that travels with you, whichever models you happen to be using that month.
