
Why text to video is a workflow problem now
Turning a sentence into a moving clip stopped being impressive a while ago. What still separates a good AI video from a bad one is almost never the model you typed into. It is the order of operations around it: how the script was cut into shots, whether reference images existed before generation started, how many alternates were generated per beat, and whether anyone bothered to fix audio, cadence, and grading afterwards.
The bottleneck moved. It used to be raw capability, so people waited for the next release. Now the ceiling is coordination. A single prompt can produce a beautiful five-second shot, but a sixty-second piece needs six to fifteen shots that look like they belong to the same film. Faces have to stay stable, wardrobe has to stay consistent, camera language has to feel intentional, and the audio has to land on the cut. No single model handles all of that gracefully, which is why the practical skill is orchestration rather than prompt luck.
This guide is a neutral, tool-agnostic workflow you can run with whatever generation tools you already have access to, whether that is a hosted cinematic model, an image-to-video engine, an open-weight model you run locally, or a mix of all three.
The four layers of a modern AI video pipeline
Think in layers rather than in tools. Each layer has a clear input and a clear output, and mixing them up is where most projects stall.
Layer 1: script and beat sheet
The input is an idea; the output is a shot list with durations, intent, and dialogue or narration. Keep every beat between four and eight seconds for generation purposes, even if the final edit holds a shot longer. Short beats give you room to trim, and trimming always looks better than stretching.
Layer 2: visual generation
The input is the shot list; the output is stills and short clips. This is where model selection matters most, and where most people spend all their time. Resist the urge to start here. Without locked stills, you are paying generation time to discover what your film looks like.
Layer 3: motion, continuity, and assembly
The input is approved clips; the output is an animatic with correct timing. This layer is unglamorous and decisive. If the animatic does not work with scratch audio, no amount of polish will save it.
Layer 4: audio and finishing
The input is the locked animatic; the output is a publishable file. Music, sound design, voice, captions, upscaling, frame interpolation, and color all live here. Budget roughly a third of your total time for this layer. Most beginners spend ten percent and wonder why the result feels artificial.
How to choose a model for a single shot
Model selection is a per-shot decision, not a per-project decision. The fastest way to get consistent results is to describe the shot in concrete terms, then match those terms to a model family.
Use these criteria in order:
- Shot type. Photoreal human close-ups, wide establishing landscapes, product macros, stylized animation, and abstract motion all favor different architectures. Photoreal faces need a model with strong temporal identity preservation. Landscapes tolerate more variation. Product shots need controllable lighting and minimal drift.
- Motion complexity. A slow push-in on a static subject is easy. Running, dancing, fighting, or any interacting crowd is hard. If motion is the point of the shot, allocate more alternates and expect a lower hit rate.
- Duration and continuity. Short clips hide identity drift. Long clips expose it. If you need a fifteen-second continuous take, you likely need a model with native long-form coherence rather than a stitched set of five-second clips.
- Control surfaces. First-frame conditioning, last-frame conditioning, camera trajectory control, motion strength sliders, and region-based editing are what let you steer a shot instead of rerolling it. A slightly weaker model with better controls often beats a stronger model without them.
- Audio needs. Lip-synced dialogue, ambient sound, and music generation are separate capabilities. If dialogue is on camera, pick the pipeline around that requirement first, then solve visuals.
- Iteration speed. During exploration, fast low-resolution drafts are worth more than beautiful slow renders. Switch to your highest-quality option only once the shot is locked.
Draft models versus hero models
Run a two-tier system. Tier one is your draft pass: fast, cheap, low resolution, high volume, used to test composition and timing. Tier two is your hero pass: slow, high resolution, run only on approved shots. Teams that skip the draft tier waste their best model on shots that get cut.
When to use image-to-video instead of text-to-video
If a shot must match an established look, generate or source the still first and animate from it. Image-to-video gives you a huge amount of directorial control: you choose framing, wardrobe, lighting, and composition with cheap iteration (in an image model) and only pay the expensive motion step for shots you already like. Text-to-video shines for abstract transitions, mood inserts, and B-roll where identity does not matter.
A repeatable nine-step workflow
- Lock the script and runtime. Decide the final length before generating anything. Runtime determines shot count, and shot count determines your whole budget of time and attention.
- Break into beats. One action per beat. If a beat contains "and then," split it.
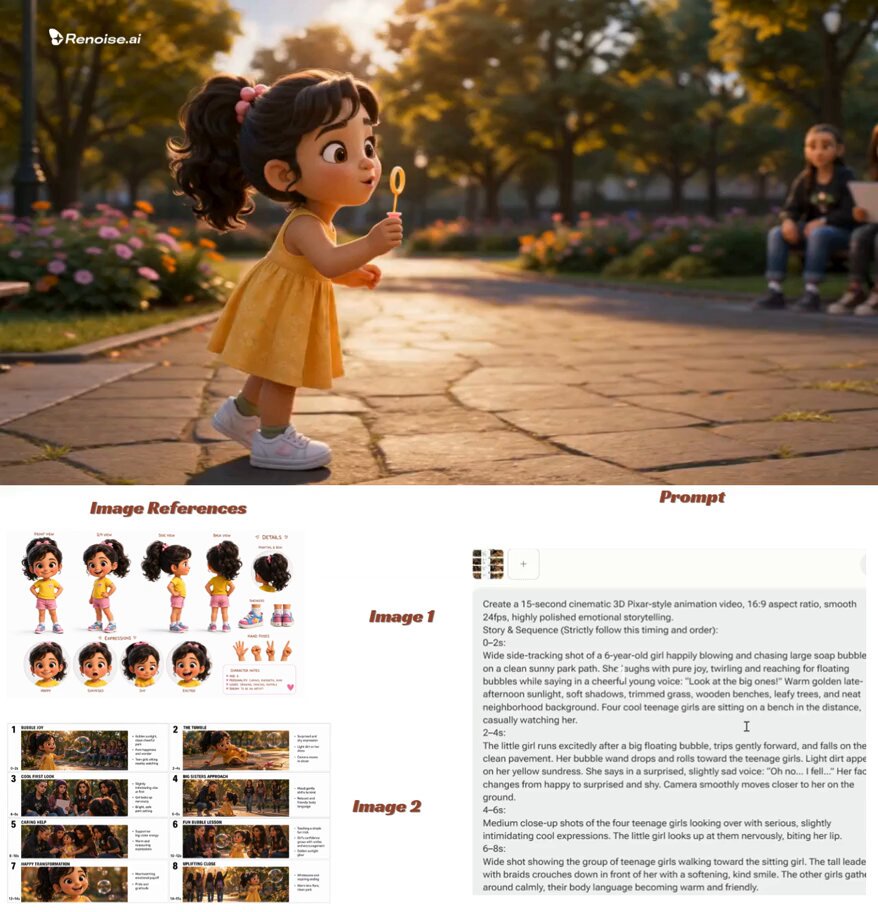
- Build a lookbook. Collect three to five reference images that define palette, lens feel, wardrobe, and lighting. Write a one-paragraph style bible in plain language.
- Generate stills first. Use an image model to nail composition. Approve stills before animating. This single habit eliminates more rework than any prompt trick.
- Animate approved stills. Prefer image-to-video for character shots, text-to-video for inserts and transitions.
- Generate three to five alternates per shot. Variation is cheaper than perfection. Pick the best take, not the first take.
- Assemble a radio edit. Cut to scratch narration or temp music and watch it end to end. Fix pacing here, not in the final render.
- Finish. Upscale, interpolate frames if needed, stabilize, color grade, then layer sound design, music, and voice.
- Quality check and export per platform. Each destination has its own aspect ratio, safe areas, and loudness expectations. Export deliberately, not generically.
Prompting like a director
Prompting is not writing marketing copy. It is writing a shot description for a crew that cannot ask questions. Every ambiguous word becomes a random decision.
The seven-slot prompt formula
Use a consistent structure so you can debug one variable at a time:
- Subject — who or what, with two or three identifying details.
- Action — one clear verb, in present tense.
- Environment — location, time of day, weather, background activity.
- Camera — shot size, angle, and movement.
- Lighting — direction, quality, color temperature, contrast.
- Lens and texture — focal length feel, depth of field, film grain, medium.
- Style anchor — the same short phrase repeated across every prompt in the project.
That last slot is where continuity comes from. If every prompt ends with the same style anchor, your shots will look related even when the content differs.
What negative constraints actually do
Negative prompts help with artifacts, not with storytelling. Use them for things like extra fingers, warped faces, watermark-like text, jitter, and duplicated limbs. Do not use them for emotional direction. "Not sad" does not produce a happy performance; it produces a confused one.
Camera language models understand
Stick to vocabulary that maps to real camera behavior: slow push in, dolly out, static tripod shot, handheld follow, crane up, orbit left, rack focus to background, wide establishing shot, over-the-shoulder. Vague words like cinematic or epic do very little on their own. Pair a specific shot description with your style anchor instead.
Keeping characters and scenes coherent
Identity drift is the number one complaint about AI video, and it is almost always a pipeline problem rather than a model problem.
- Create a character sheet. Generate a still of your character from three angles in neutral light. Reuse that reference in every shot where they appear.
- Reuse seeds or reference conditioning. If your tool supports seed locking or reference images, lock them per character and per location.
- Anchor wardrobe and hair. Describe clothing with specific colors and materials, and keep the wording identical across prompts.
- Keep the grade constant. Do not grade shot by shot during assembly. Apply one color treatment across the sequence so lighting differences blend.
- Match lens feel. Mixing a wide-angle look and a telephoto look in the same scene reads as a mistake even when viewers cannot name it.
- Stage the edit to hide drift. Cut on motion. A cut during a turn of the head hides identity changes far better than a static hold.
Common failure modes and how to fix them
Melting hands and faces. Reduce motion complexity, shorten the shot, or generate from a still where hands are already resolved. Re-roll rather than repair when the artifact is in the first frame.
Flicker and pulsing brightness. Usually a symptom of an aggressive motion setting or an unstable base image. Lower motion strength and regenerate the source still with more even lighting.
Drifting identity across cuts. Not a generation problem; a reference problem. Build the character sheet and standardize your style anchor.
Camera that whips uncontrollably. Remove conflicting motion words from the prompt. One camera instruction per shot. If you want a push-in, do not also ask for a pan and a zoom.
Garbled text in frame. Most video models cannot render readable typography reliably. Generate clean plates and add text in your editor.
Lip sync drift. Generate dialogue shots with shorter sentences, split long lines into separate clips, and align audio in post rather than trusting the model to nail timing.
Overcooked motion. Newer models sometimes over-animate. If a subject should be still, say so explicitly and use a static camera instruction.
Speed, cost, and quality trade-offs
The practical trade-off is not money alone; it is the number of decisions you can afford to make. High-volume exploration early costs little and saves enormous rework later.
- Resolution ladder. Explore at the lowest usable resolution, then upscale the winners. Detail you cannot see at draft scale is detail you should not pay to render.
- Batch by location. Generate all shots for one scene in one session so lighting and palette stay mentally consistent.
- Set an alternate cap. Three to five takes per shot, then move on. Endless rerolling is a pacing decision disguised as a quality decision.
- Self-host when volume is high and requirements are stable. Local generation is worth it when you have repeatable shot types and a machine to run them, and not worth it when you are still experimenting.
- Time-box audio. Sound design transforms AI footage more than any upscale. Give it a real block on the calendar.
Post-production steps people skip
- Upscale with a video-aware model rather than a photo upscaler to avoid shimmer.
- Interpolate frames only when motion looks choppy; over-interpolation creates a soap-opera look.
- Stabilize selectively. Full-clip stabilization can fight intentional camera movement.
- Grade with one look applied across the sequence, then trim exposure per shot.
- Design sound. Room tone, footsteps, cloth movement, and impact sounds sell realism far more than sharpness does.
- Normalize loudness to the target platform range and check on phone speakers, not studio monitors.
- Caption with accurate timing; auto-captions still need a proofread pass.
Quality checklist before you publish
Watch the whole piece once at normal speed without stopping. Then watch again with these checks in mind:
- Faces and hands are stable at every cut.
- No flicker, wobble, or unexplained brightness shifts.
- Motion cadence matches the music or narration rhythm.
- No accidental on-screen text or watermark-like artifacts.
- Audio peaks are controlled and voice is intelligible on small speakers.
- Aspect ratio and safe areas fit the destination platform.
- Captions are timed, spelled correctly, and do not cover faces.
- The first two seconds communicate the subject without context.
Frequently asked questions
Do I need one model or many?
You need one model for most shots and one or two specialists for the hard ones. Most projects use an image model for stills, a reliable image-to-video model for character shots, and a flexible text-to-video model for inserts and transitions.
How long should each generated clip be?
Generate four to eight seconds and edit down. Longer generations are harder to control and more likely to drift.
Can I make a full video without editing software?
You can assemble something, but pacing, sound, and captions are what make AI footage feel professional. Even a basic editor pays for itself immediately.
How do I keep the same character across many shots?
Build a character sheet, lock reference images or seeds, keep wardrobe wording identical, and cut on motion.
Is local generation worth it?
If you have repeatable shot types and frequent renders, yes. If you are still exploring style, hosted tools will get you to a decision faster.
Why does my output look AI-generated even when it is sharp?
Usually because of motion cadence and audio. Add sound design, vary shot lengths, and avoid uniform camera movement across every shot.
Where to start tomorrow
Pick one scene, not one clip. Write a five-shot beat sheet, generate stills for all five, animate only the two strongest, and cut them together with scratch audio. That single exercise teaches more about model selection than a week of isolated prompt testing, because it forces you to confront continuity, pacing, and finishing — the three things that actually determine whether AI video looks like a finished film or a demo reel. From there, expand the pipeline one layer at a time: first your reference library, then your drafting pass, then your audio finishing, and finally your export presets. The tools will keep changing; the workflow compounds.
