
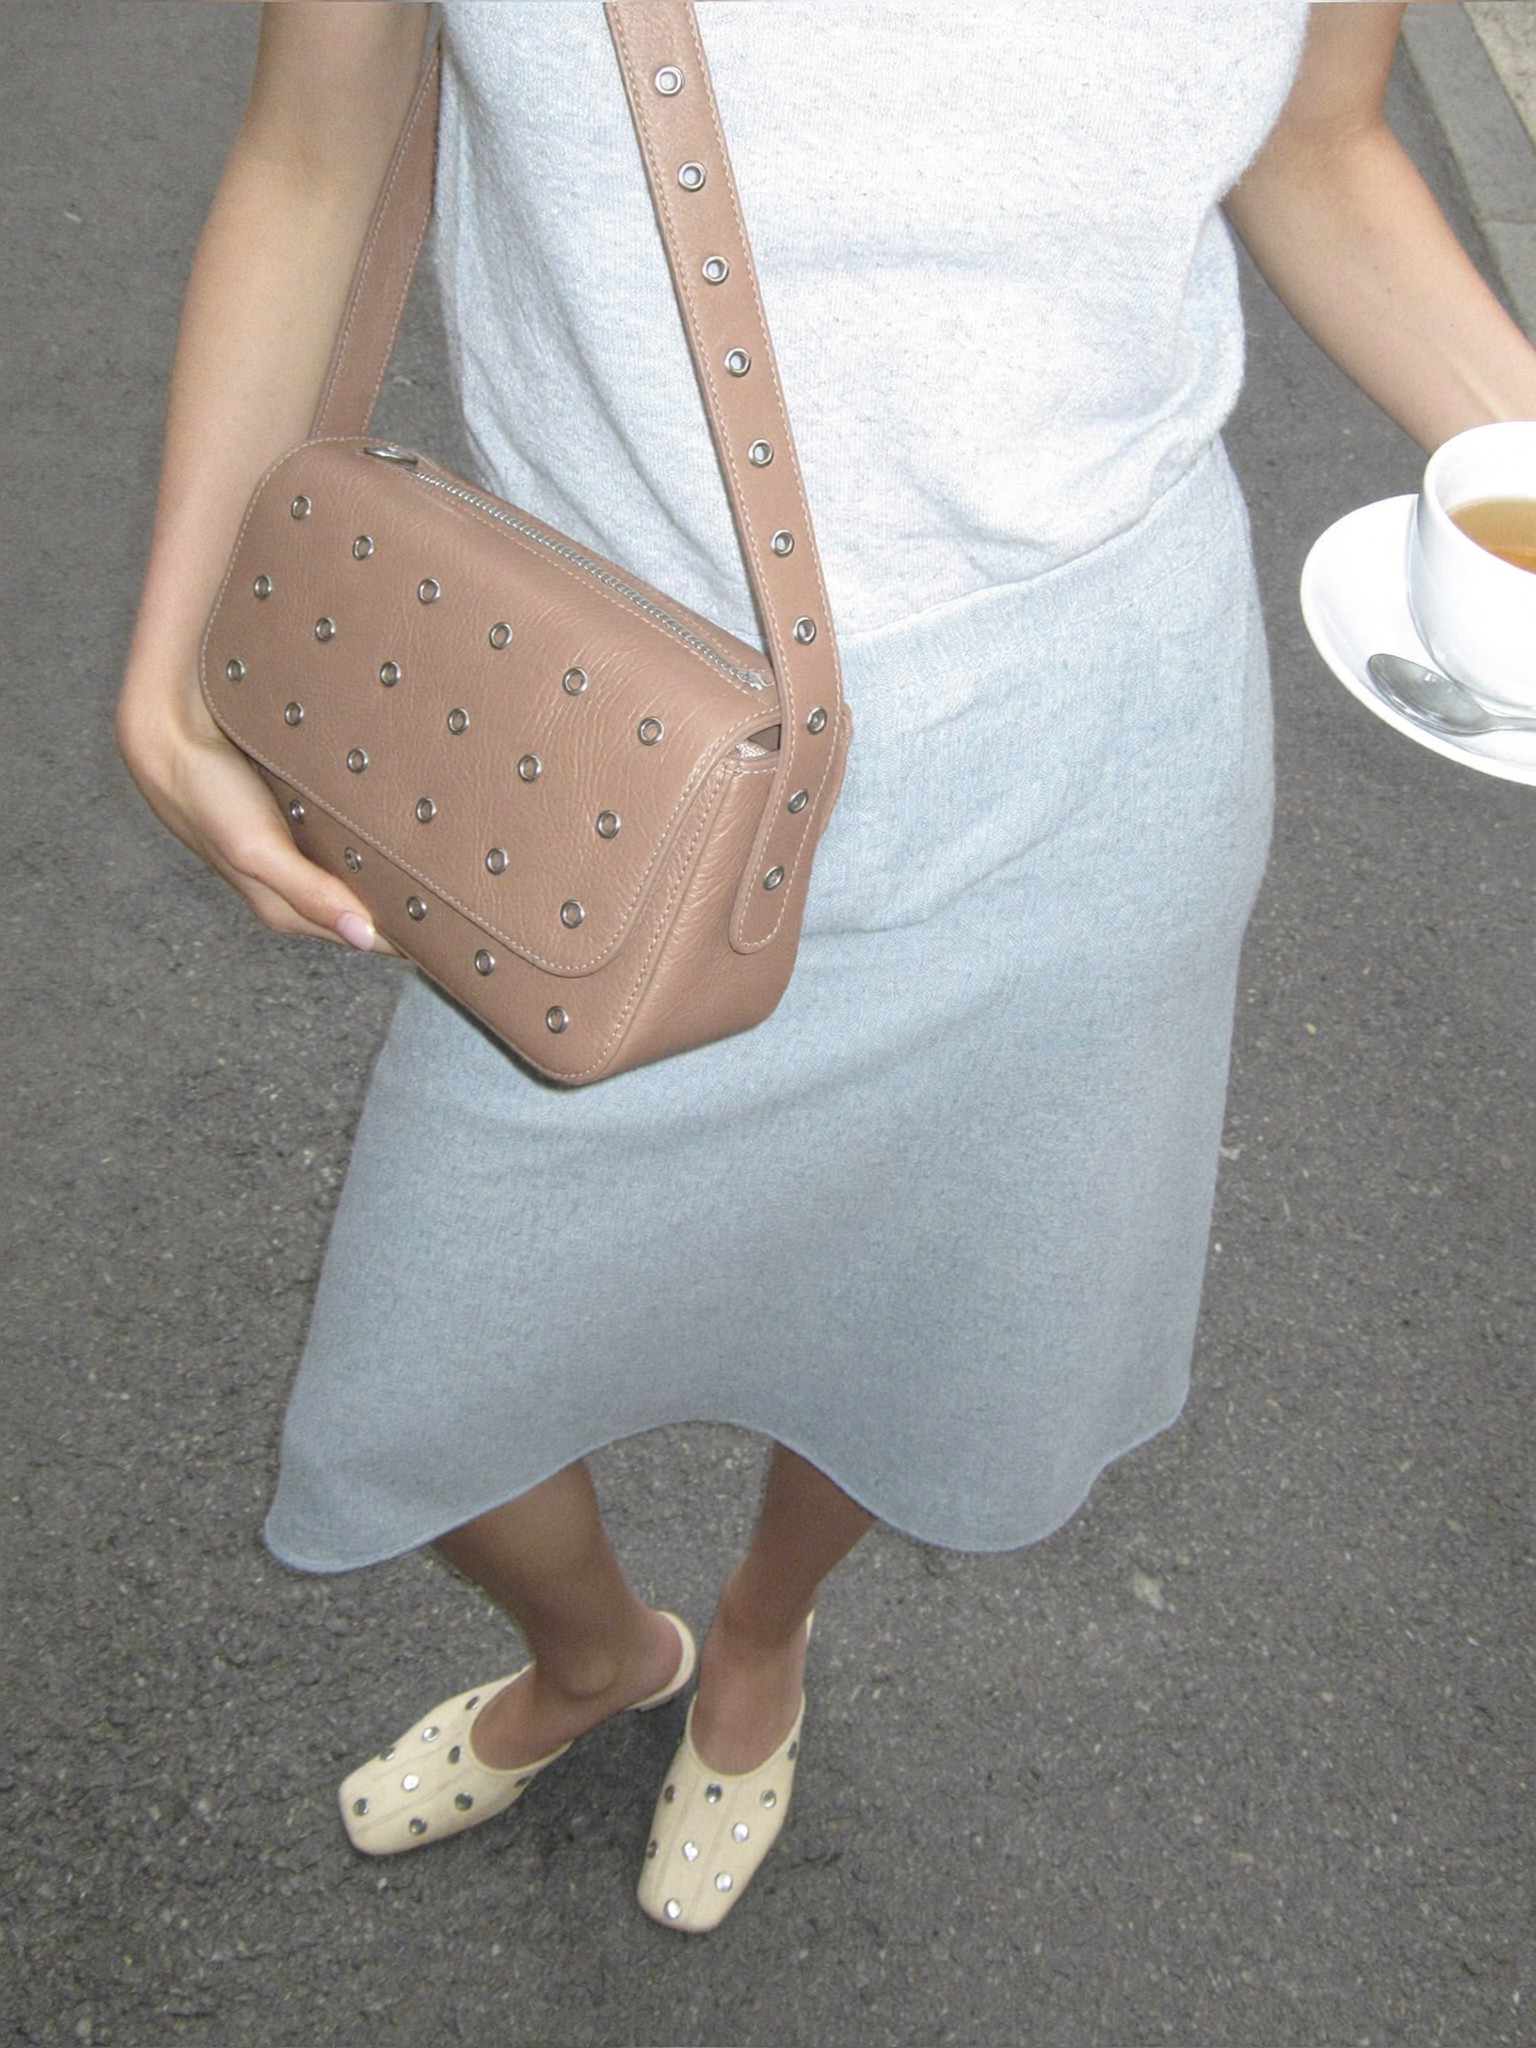
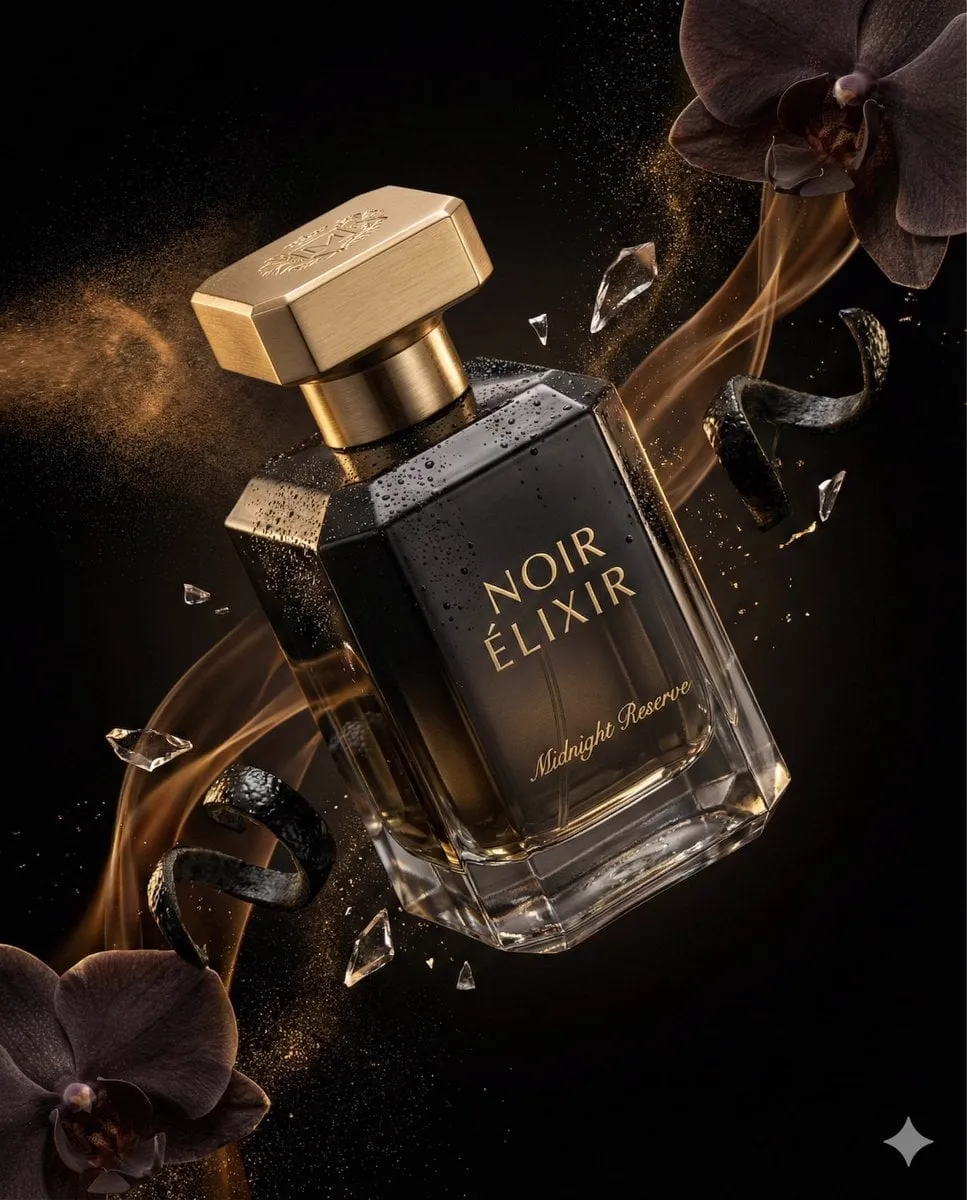
Animating a still photograph used to mean hiring a motion designer, hand-tracking masks frame by frame, and waiting days for a render. Image-to-video models have collapsed that timeline. A single well-chosen frame can now return several seconds of believable movement in minutes, often from nothing more than a short written description of how the scene should move.
The bottleneck has shifted. It is no longer technical skill or access to software; it is editorial judgment. Knowing which photos deserve to move, how to describe motion in language a model can act on, and how to assemble the outputs into something that feels intentional rather than like a feature demo. This guide covers the complete workflow, from sorting a photo library to exporting a finished cut, with the decision criteria, prompt patterns, and quality checks that separate usable results from expensive noise.
Why Still Photos Are the Best Raw Material for AI Video
Photographs are a dense, cheap, and emotionally specific source of visual information. A portrait contains a face, a lighting direction, a wardrobe, a background, and a mood, all captured in one frame. Generative video models do not need to invent any of that — they only need to extrapolate. That is a much smaller ask than generating a scene from scratch, which is why image-to-video output is generally more coherent than pure text-to-video output.
The frame also acts as a consistency anchor. If you animate ten different photos of the same product from the same shoot, each clip inherits the same color palette, the same lens character, and the same subject proportions. Try to produce that same consistency from ten separate text prompts and you will spend hours fighting drift in skin tone, wardrobe, and lighting.
The trade-off is that your source photo sets a ceiling. A blurry, over-compressed, badly cropped image will produce a blurry, over-compressed, badly cropped video, and the model may also hallucinate detail to compensate — extra fingers, melting edges, wobbling architecture. Preparing the frame properly is therefore the highest-leverage step in the entire process, not an optional polish pass.
The Core Workflow: Five Phases From Library to Timeline
The workflow below is deliberately linear. Skipping ahead is the most common reason creators end up generating dozens of clips and using none of them.
Phase 1: Choose images with motion potential
Not every photo wants to move. The best candidates contain an implied action or a natural camera move: a subject mid-stride, hair caught in wind, steam rising from a cup, a car on a road, water in the frame, a crowd in the background. Photos where the implied motion is obvious give the model a clear, low-risk job. Static architectural shots and tightly cropped product stills can work, but they need deliberate camera motion rather than subject motion, which is a different prompt strategy.
Phase 2: Prepare a clean, well-framed source frame
Crop to your target aspect ratio before generating, not after. Fix exposure and white balance, remove distractions that would confuse the model, and consider upscaling small images so the model has enough pixel information to preserve texture. This phase typically takes longer than generation itself and saves far more time than it costs.
Phase 3: Write a motion prompt that describes change, not content
This is the single biggest skill shift. The image already describes what is in the frame. Your prompt should describe what happens next: how the camera moves, how the subject moves, how light and atmosphere evolve, and how long the shot should feel.
Phase 4: Generate several takes and compare
Treat each generation as a sketch, not a final render. Produce three to five variants, watch them once at full speed without pausing, and keep only the takes that read clearly on a first viewing. Human eyes are forgiving of small artifacts in motion and merciless about awkward ones in slow motion.
Phase 5: Assemble, score, and finish
Generated clips are ingredients. Cut them to the beat, add sound, correct color drift between shots, and deliver. A mediocre generation with excellent sound design and pacing will outperform a pristine generation dropped raw into a timeline.
Preparing Images So the Model Has Something to Work With
The model interprets your photo as evidence about the world: where the horizon sits, which surfaces are shiny, how light falls on a face. Anything ambiguous becomes a guess, and guesses become artifacts.
Resolution, aspect ratio, and framing
Aim for at least 1080 pixels on the short edge, ideally more. Match the source aspect ratio to your delivery format before generation — cropping a generated clip usually means losing the part of the frame that moved most convincingly. Vertical social formats benefit from a taller crop with headroom, while widescreen shots need deliberate negative space on the side the camera will travel toward.
Cleanup that pays for itself
Remove watermarks, timestamp overlays, and stray text. Straighten horizons; a tilted horizon that the model tries to stabilize will produce a subtle wobble across the whole clip. Reduce heavy noise selectively rather than globally, since aggressive denoising removes the fine texture that makes skin and fabric look real once motion is added.
Depth cues and subject separation
Models estimate depth from occlusion, perspective, and focus. If your subject blends into the background — similar tone, no rim light, cluttered edges — the parallax will look wrong. A light vignette, a slight subject brightening, or a tighter crop can restore separation and give the model an unambiguous foreground and background to move independently.
Writing Motion Prompts That Actually Move
Most disappointing generations come from prompts that describe the scene instead of the change. "A woman in a red coat on a city street" tells the model nothing it cannot already see. The prompt needs verbs.
Camera language beats adjectives
Use the vocabulary of a camera department: slow push in, dolly left, crane up, handheld drift, static tripod, orbit around the subject, rack focus from foreground to background. Combine at most two moves in one clip. "Slow push in with a slight rise" reads clearly; a paragraph of five simultaneous camera instructions produces mush.
Subject motion and secondary motion
Describe what the subject does — turns their head, steps forward, raises a hand, blinks, breathes — and then describe the small secondary motion that sells realism: fabric shifting, hair lifting, smoke curling, ripples spreading, leaves rustling. Secondary motion is where generated clips stop looking like photographs on rails.
What to leave out of the prompt
Do not re-describe clothing, colors, or facial features in detail. Long lists of attributes compete with the image itself and can cause the model to restyle the subject. Do not request text, logos, or legible signage; these are still the weakest output for nearly every model. Do not ask for cuts, transitions, or multiple shots inside a single short clip.
A reusable prompt skeleton
A structure that works across subjects: camera move, then subject action, then environment motion, then lighting or atmosphere, then pacing. For example: "Slow dolly in, subject turns toward the window, curtain fabric drifts, warm afternoon light shifts across the floor, calm and steady." Keep it to one or two sentences. Save the longer creative rationale for your own notes, not the prompt box.
Choosing Generation Settings Without Guesswork
Settings interact, so change one variable at a time until you have a feel for how your chosen model responds.
Duration and motion strength
Short clips of two to four seconds are far easier to control and usually enough for a cutaway, an establishing beat, or a social post. Longer clips give the model more time to accumulate drift. Motion strength is the dial between a near-static photograph with subtle life and an aggressive, sometimes distorted animation. Start low, increase until the shot reads clearly, then stop — the most common mistake is pushing motion until faces warp.
Resolution, upscaling, and detail retention
Generate at the highest native resolution your model supports comfortably, then upscale with a dedicated video upscaler rather than re-generating. Re-generation reshuffles detail; upscaling preserves it. If your model offers a sharpening or detail slider, keep it moderate, since over-sharpened generated motion produces a shimmering, crawly texture around edges.
Seeds, batching, and reproducibility
Lock the seed once you find a take you like, so you can adjust the prompt or motion strength and compare changes meaningfully. Keep a small log of image, prompt, seed, settings, and a one-line verdict. After twenty clips, that log is the difference between a repeatable style and a lucky accident.
The Audio Layer: Music, Voice, and Sound Design
Sound is the fastest way to raise perceived production value. Audiences forgive minor visual artifacts; they rarely forgive flat, mismatched audio.
Music beds and pacing
Choose a track with a clear rhythmic structure and cut your clips to it. Beat-matched cuts make slow camera pushes feel deliberate instead of sluggish. For dialogue-free montages, a single track with one build is enough; layering two or three tracks under a two-minute video usually muddies the pacing.
Voiceover and narration
Synthesized narration has become genuinely usable, but the writing still determines quality. Short sentences, concrete nouns, and no throat-clearing. Record or generate narration before you finalize the cut, so the visuals can breathe with the voice rather than being trimmed to fit after the fact.
Sound effects and ambience
Add environmental sound to animated stills: room tone, distant traffic, wind, paper, footsteps. Even a quiet ambience bed under a photo-to-video clip makes the motion feel grounded in a real space. Place effect hits on the exact frame where motion starts, since that moment reads as the visual "impact."
Editing and Assembly: Turning Clips Into a Story
Cutting on motion
The strongest cut point is mid-motion. Cut while the camera is still pushing or the subject is still turning, so the next shot continues the energy instead of restarting it. Cutting on a settled, static frame kills momentum.
Handling transitions between generated shots
Generated clips do not share a continuous world, so hard cuts are usually safer than elaborate transitions. Match two adjacent clips on movement direction, on color temperature, or on framing scale to make the cut feel intentional. Avoid cross-dissolves between clips with different lighting unless you are deliberately signaling a time jump.
Color, grain, and visual continuity
Apply one look across the whole sequence. A subtle film grain or a very light halation layer helps blend clips generated from different photos with slightly different color science. Correct skin tones first, then unify highlights, then adjust saturation — reversing that order makes skin look plastic.
Captions, titles, and platform crops
Add captions after color, and make them large enough to survive compression. Deliver one master and derive platform crops from it, checking that the important motion is still inside the safe area. Text rendered into a generated clip will not be legible; overlay titles in the editor instead.
Quality Control: Artifacts, Causes, and Fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Faces warp or shift identity | Too much motion strength, or prompt re-describes the face | Lower motion strength, remove facial descriptors, shorten the clip |
| Edges crawl or shimmer | Over-sharpening, or source image over-denoised | Reduce sharpening, restore source texture, upscale instead of re-generating |
| Background geometry bends | Ambiguous depth, no clear horizon | Straighten the horizon, add subject separation, request a simpler camera move |
| Motion looks rubbery | Secondary motion missing | Add fabric, hair, smoke, or water movement to the prompt |
| Clip drifts in brightness | Long duration, strong lighting cues | Shorten the clip, remove lighting-change instructions |
| Flickering textures | Very fine repeating detail like mesh or text | Crop out the detail, or accept a softer look with light blur on the source |
Run every clip through the same three checks before it enters the timeline: watch once at full speed, watch once muted to judge motion alone, and watch once against the adjacent clips to judge continuity. Rejecting a clip early is cheaper than rebuilding a sequence around it later.
Scaling the Workflow Without Losing Quality
Build a prompt library
Collect the prompt skeletons that worked, grouped by shot type: portrait, landscape, product, interiors, food, motion-heavy action. When a new project starts, adapt an existing skeleton rather than writing from zero. This is how you keep a consistent house style across dozens of clips.
Batch by scene, not by clip
Generate all the shots for one scene before moving on, using the same settings and the same seed family where possible. Batching by scene keeps color and motion consistent, and it makes the editing pass faster because you already know what the material looks like.
Review gates and naming conventions
Use a simple pipeline: incoming, approved, rejected. Name files with project, scene, shot, take, and version. Ten minutes of naming discipline prevents the classic disaster of discovering that your best take is buried in a folder of untitled downloads.
Budgeting time and compute
Plan for a ratio of roughly five generated takes per finished shot, and budget most of your time for preparation and assembly, not generation. If a specific shot refuses to work after several attempts, the problem is usually the source photo, not the settings. Swap the image and try again.
FAQ: Photo-to-Video Questions Creators Ask Most
How long should an animated photo clip be? Two to four seconds covers most needs. Longer clips accumulate drift, and you can always slow a strong four-second clip down in the edit rather than generating an eight-second one.
Can I animate a group photo? Yes, but keep motion minimal: a slow camera push or orbit with subtle breathing and blinking reads best. Asking several people to perform different actions in one clip is where identity swapping begins.
Do I need to describe the subject in the prompt? Rarely. The image supplies the subject. Describe the change — camera move, action, atmosphere — and leave appearance alone.
Why does my output look like a filter instead of real motion? Usually the motion strength is too low and the prompt is only describing mood. Add a concrete camera move and one secondary motion cue, then increase motion strength gradually.
What is the best source image format? A high-quality, low-compression frame at or above your delivery resolution, with a clean horizon and clear subject separation. Avoid heavily filtered images with crushed blacks or blown highlights, since the model cannot recover information that is not there.
Should I animate every photo in a project? No. A sequence that mixes animated and static shots with strong sound design often feels more professional than one where every frame moves. Motion should mark the moments that matter.
How do I keep a series of clips looking like one film? Use one color grade, one grain treatment, consistent clip lengths, and a shared prompt skeleton. Consistency comes from constraints, not from variety.
Where does AI generation stop and editing begin? Treat generation as acquisition. Everything after it — selecting takes, cutting on motion, sound design, color — is where the video is actually made, and it deserves at least as much attention as the prompting.
