
From Still to Scene: What Image-to-Video Actually Does
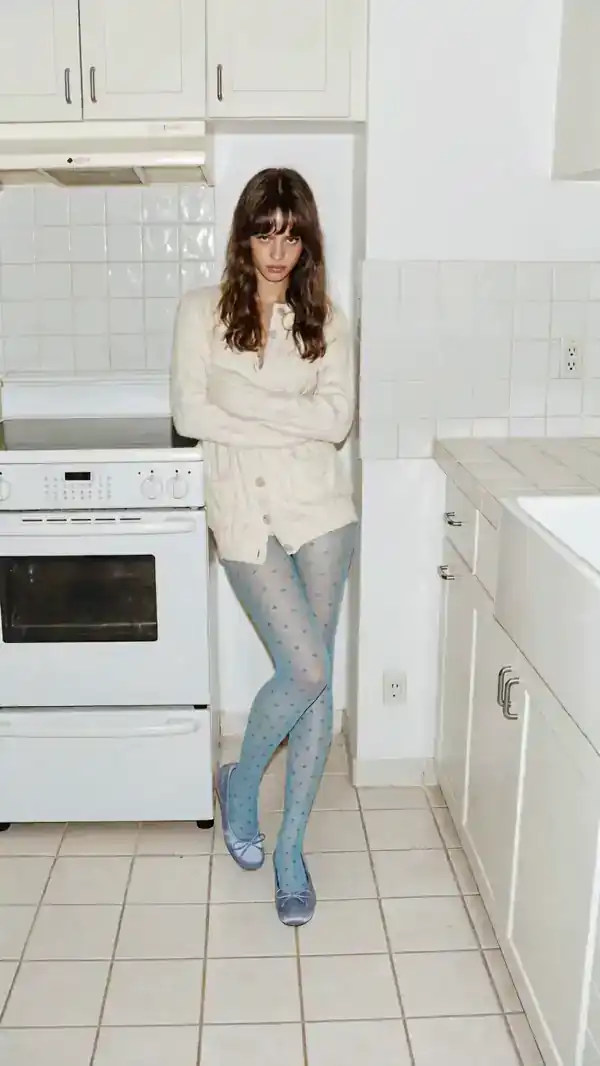
A single photograph carries more information than most people assume. It encodes lighting direction, depth cues, material texture, clothing wrinkles, and one frozen instant of subject movement. Generative video models start from that frozen instant and invent what happens next. They extrapolate a plausible continuation of the frame, then render it as a sequence of frames that must stay internally consistent — the same face, the same jacket, the same window light — across dozens or hundreds of images.
Two different technologies often get bundled under the same label, and confusing them wastes a lot of time. Frame interpolation takes two real images and synthesizes the frames between them. It is how smooth slow-motion and seamless pans are produced from existing footage. Generative image-to-video does something considerably harder: it invents new visual information. A head turns. Fog rolls across a field. The camera drifts left and reveals part of a room that simply was not in the original picture.
That distinction matters because the failure modes are different. Interpolation fails by warping edges or smearing fine detail. Generative animation fails by changing identity, melting hands, drifting backgrounds, or producing motion that contradicts the lighting in the source frame. Knowing which problem you are looking at tells you whether to fix the input image, rewrite the prompt, change the motion strength, or switch models entirely.
A useful mental model is to treat the still as a set design and a lighting plan, and the model as a very fast, very literal cinematographer. The cinematographer will do exactly what you ask, including the things you did not mean to ask for. If your prompt says the camera pushes in while the subject walks toward the lens, you have created a collision, and the model will resolve it in the ugliest way available.
What Makes a Generated Clip Feel Cinematic
Cinematic is a slippery word, so it helps to break it into components you can control. Most clips that feel amateur share the same handful of problems: motion that is too fast, a camera that moves for no reason, flat lighting, and a duration that ends before the moment lands.
The Grammar of Camera Movement
Real camera movement has motivation. A slow push-in increases tension or intimacy. A lateral tracking shot reveals context. A handheld drift suggests documentary immediacy. A crane rise signals scale and release. When you choose a movement, choose the narrative reason with it, and your clips will immediately feel more intentional.
Keep one dominant movement per clip. Combining a dolly, a tilt, and a zoom in a five-second generation usually produces a rubbery, unstable result because the model has to satisfy contradictory geometry. If the shot needs two movements, generate two clips and cut between them.
Speed is the other lever. Most image-to-video models default to motion that reads as roughly twice as fast as a natural human pace. Prompting for slow, deliberate movement — or reducing the motion-strength parameter — is often the single biggest quality improvement available.
Light, Contrast, and Color Continuity
The source image dictates the lighting. If your photograph has a hard key light from the left and deep shadows on the right, any generated subject movement must respect that. Prompts that mention the existing light — warm window light from frame left, cool blue ambient fill — reduce the chance that the model invents contradictory illumination halfway through the clip.
Color continuity across multiple shots is what makes a sequence feel like one film rather than a slideshow. Lock a simple look early: one contrast curve, one color temperature bias, one grain setting. Apply the same treatment to every generated clip during post-production rather than fighting each model's native color rendition.
Pacing and Duration
A three-second clip is usually enough for a cutaway, an insert, or a reaction. A five- to eight-second clip can carry a short beat with movement. Anything longer should either have a genuinely interesting internal event or be assembled from several shorter generations stitched with clean cuts.
Ask what changes during the clip. If nothing changes, the shot is a still with expensive wobble. If three things change, the audience will not register any of them. One change per clip is the practical rule.
Preparing Source Images Before You Animate
The quality ceiling of your output is set by the input frame. Most disappointing generations trace back to a source image that was too small, too cluttered, or too ambiguous about what should move.
Resolution, Aspect Ratio, and Framing Headroom
Feed the model a source at or above the resolution you intend to deliver, and match the aspect ratio of the target format. Cropping a 16:9 still into a 9:16 vertical later means you lose the sides of the frame — and possibly the subject's shoulder, elbow, or the object they were holding.
Leave headroom and look room. Generative models frequently introduce small camera drift even when you ask for a static shot, and if the subject touches the edge of the frame, that drift will slice into them. A little empty space around the subject acts as a shock absorber.
Cleanup Before Animation
Spend two minutes cleaning the still. Remove compression noise with a light denoise pass. Fix obvious blemishes, stray objects, and text artifacts, because the model will faithfully animate every flaw you leave behind. Sharpen conservatively: over-sharpened edges produce shimmering halos in motion because the model treats those bright outlines as real structure and tries to move them.
If the image contains faces, make sure the eyes are sharp and unobstructed. Face identity is the most fragile element in image-to-video, and a soft or partially occluded face gives the model permission to improvise a new person.
Reference Sheets for Recurring Characters
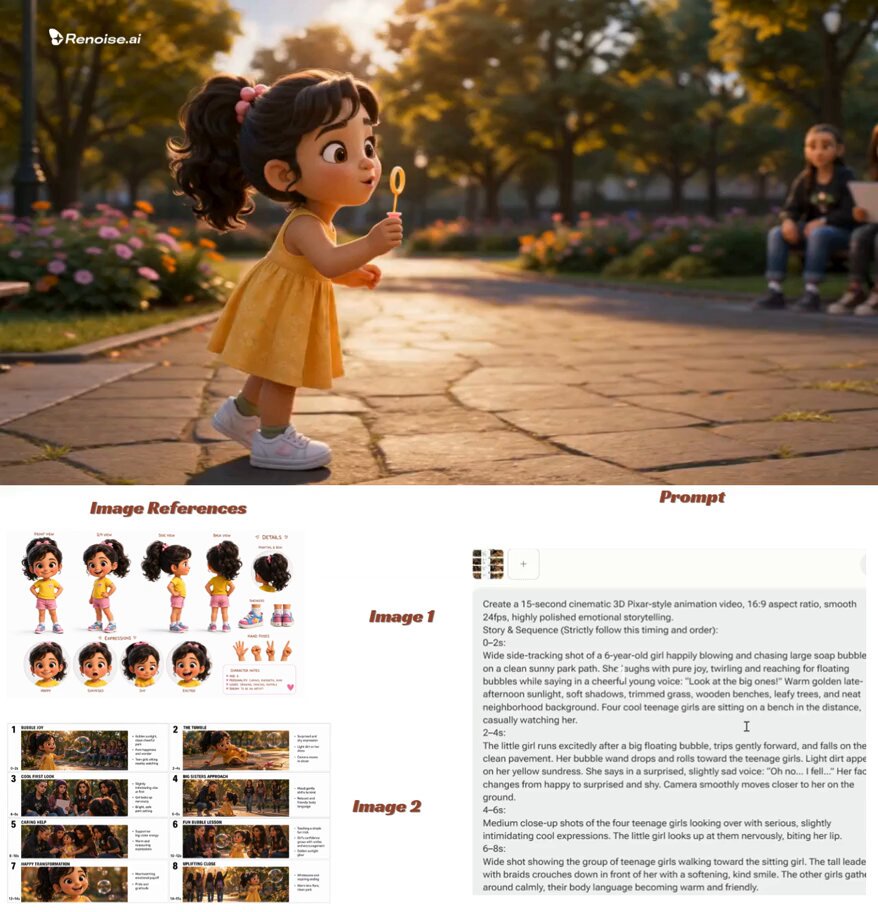
When the same character appears in several shots, assemble a small reference set: one clean front-facing portrait, one three-quarter view, and one full-body shot under consistent lighting. Even when a tool does not formally accept reference images, you can reuse the same character still across multiple generations and mask or crop to the region you need. Consistency improves dramatically when the starting pixels are identical.
Matching the Model to the Shot
The model landscape changes quickly, but the categories are stable, and choosing the right category matters more than chasing the newest name.
Photoreal People and Faces
Some models are tuned for human realism and handle skin texture, hair strands, and subtle facial micro-movement well. These are the right choice for portraits, interviews, and narrative close-ups. They tend to be slower and more sensitive to prompt wording, so keep instructions simple and let the source image carry the detail.
Stylized, Animated, and Surreal Looks
Other models excel at illustration, anime, painterly textures, and physics-defying transitions. If your source is a digital painting, a comic panel, or a product render, use a model that treats stylization as a feature rather than an error to correct. Sending stylized art into a photoreal pipeline produces uncanny half-real results that satisfy no one.
Environments, Products, and Macro Shots
Landscapes, architecture, food, and product photography are the easiest wins in image-to-video, because the motion vocabulary is limited — water, clouds, steam, fabric, light flicker, slow parallax. These shots tolerate lower motion strength and shorter durations, which also makes them faster and cheaper to iterate.
A practical approach is to keep two or three tools available: one for photoreal humans, one for stylized work, and one fast option for quick previews and blocking. Generate the same source frame in two of them before committing to a full sequence; the comparison takes minutes and usually settles the decision immediately.
Writing Prompts That Control Motion
Image-to-video prompting is not the same as text-to-video prompting. You are not describing a scene from scratch. You are describing what changes, and how the camera behaves while it changes.
A Five-Part Prompt Skeleton
A reliable structure has five slots: subject action, camera movement, speed, lighting consistency, and atmosphere. For example: the woman turns her head slowly toward the window; camera pushes in gently; slow, deliberate pace; warm afternoon light stays consistent; faint dust particles drift in the air.
Notice what is absent. There is no attempt to re-describe her clothing, the room, or the era. The source image already handles all of that, and redundant description gives the model conflicting instructions to reconcile.
Describing Motion Without Breaking the Image
Use verbs that a camera or a body can actually perform: turn, lift, step, drift, settle, ripple, billow, flicker. Avoid abstract directions such as the scene becomes tense or the mood intensifies. Models do not render mood; they render pixels.
Anchor motion to a single region of the frame. A prompt that asks for the subject to walk while hair blows while background pedestrians cross while the camera tracks is four simultaneous problems. Prioritize one, generate, and layer the rest in post-production with overlays or a second pass.
Negative Prompts and Stability Controls
If your tool supports negative prompts, use them for a short, boring list of the failures you actually see: extra limbs, warped hands, face morphing, text artifacts, flicker, duplicate subjects. A generic negative list of thirty items rarely helps and can flatten motion entirely.
Stability or motion-strength sliders are your coarse adjustment. Lower values preserve the source image and produce subtle movement; higher values create dramatic movement at the cost of identity. Start low, review, then raise the value in small increments.
A Repeatable Production Workflow
Ad hoc generation produces one good clip and no film. A repeatable pipeline produces a sequence you can finish.
Step 1: Build a Shot List From the Stills
Collect every image you might use. For each, write one sentence describing the single change you want and one sentence describing the camera. Sort them into an order that tells a story: establishing shot, subject introduction, detail insert, movement beat, reaction, resolution. This takes fifteen minutes and prevents the most common creative dead end, which is having beautiful clips that do not connect.
Step 2: Generate and Review in Passes
Generate at the shortest duration your tool allows and review ruthlessly. Reject any clip with identity drift, structural warping, or contradictory lighting; do not hope that post-production will rescue it. Keep a simple naming convention that records the source image, model, prompt version, and motion setting so you can reproduce what worked.
Run the same prompt two or three times. Generative output varies between runs, and the second attempt is frequently better than the first for reasons no one can fully explain.
Step 3: Repair, Extend, and Retime
Trim clips to their strongest moment. Most generated footage has a weak first half-second while the model settles, so cutting the head of the clip often fixes a shaky opening. If a shot needs more time, extend it or generate a continuation and cut at a moment of similar motion, then use a short dissolve or a whip-pan transition to hide the join.
Retiming is underused. Slowing a clip to 80 percent or 90 percent often transforms frantic motion into something controlled, and the artifacts introduced by retiming are usually less objectionable than the original pacing.
Step 4: Assemble, Sound, and Deliver
Cut on motion. Edit music before you edit picture, or at least lay down a temp track, because pacing decisions feel completely different against rhythm. Add ambience — room tone, wind, distant traffic — under every clip. Silence is what makes AI video feel synthetic; sound design is what makes it feel shot.
Finish with a single color pass applied to the whole timeline rather than per-clip corrections, and add grain last. Grain unifies generated footage in a way that no individual clip can achieve on its own.
Common Failure Modes and How to Fix Them
When a clip goes wrong, diagnose before you regenerate. Regenerating blindly burns time and rarely solves the underlying cause.
Face morphing mid-clip. Usually caused by a low-resolution or partially occluded face in the source. Fix the still first: sharpen eyes, remove occlusion, raise resolution. Then reduce motion strength.
Melting or rubbery hands. The model has insufficient detail to model finger articulation. Frame the shot so hands are out of frame, or prompt for subtle movement only. Cropping is a legitimate fix.
Background drift and warping. Common with cluttered or low-contrast backgrounds. Simplify the source image, reduce camera movement to a simple push or pull, or composite the subject over a cleaner plate.
Flicker and strobing. Often a byproduct of over-sharpening or heavy noise in the source. Denoise gently and avoid aggressive sharpening before generation.
Motion that contradicts the lighting. The prompt implied new light sources. Remove lighting instructions that conflict with the source and describe the existing light instead.
Static, lifeless output. Usually too many negative prompts or motion strength set too low. Trim the negative list and raise motion in small steps.
Keeping Multiple Shots Consistent
Consistency across shots is a pipeline problem, not a model problem. Four habits do most of the work. First, keep the same source image family for a character, reusing the same base still for every generation. Second, lock camera vocabulary: if your film uses slow pushes and lateral tracks, do not introduce a whip pan in shot nine. Third, fix a single look in post and apply it to everything. Fourth, keep a shot list document with the exact prompt text for every clip, so a reshoot matches the original.
Another practical technique is to generate a slightly wider version of each shot than you need. Extra frame edges give you room to stabilize, reframe, and match movement between adjacent cuts without losing the subject.
Delivery Settings: Aspect Ratio, Frame Rate, and Compression
Decide the delivery format before generating, not after. Vertical 9:16 for social, 16:9 for landscape presentation, 1:1 or 4:5 for feed placements — each dictates a different source framing, and retrofitting a horizontal shot into vertical usually destroys the composition.
Generate at 24 frames per second if you want a filmic cadence, or 30 if the material will sit alongside screen-recorded or broadcast content. Upscale and interpolate only after the edit is locked; interpolating first doubles the data you have to manage and hides problems you should be fixing.
Export at a high bitrate master, then create delivery versions from that master. Aggressive compression destroys exactly the fine texture that makes generated footage read as photographic, so give the encoder headroom.
FAQ
How many attempts does a good clip usually take? Two to four generations per shot is typical once your source images are clean. If you are past six attempts, the problem is usually the input frame rather than the prompt.
Can I animate a screenshot or a low-resolution photo? Yes, with lowered expectations. Upscale first, reduce motion strength, and prefer shorter clips. Details invented by the upscaler will be animated as though they were real.
Should I animate the subject or the camera? Pick one as the primary change. Subject motion reads as performance; camera motion reads as style. Combining them at full strength produces instability.
Is it better to generate long clips or cut short ones? Short clips cut together almost always look better. Long generations accumulate drift, and editing decisions at the cut give you control the model cannot.
Do I need special hardware? No. The heavy lifting happens on remote infrastructure, so a mid-range laptop handles prompting, review, and editing comfortably. Plan your storage around large master files instead.
How do I stop clips looking artificial? Add sound design, apply one consistent grade, add grain, and cut on motion. Most perceived artificiality comes from presentation rather than generation.
Where to Take This Next
Start with five stills and one clear constraint: every clip must contain exactly one change, described in one sentence, with the camera doing one thing slowly. Finish the sequence, add ambience, apply a single grade, and watch it end to end. That exercise teaches more than any list of tools, because it forces you to confront pacing, continuity, and sound — the three things that separate a folder of impressive clips from a piece of video someone will actually watch to the end.
From there, expand deliberately. Add a second model for stylized shots. Build a reusable prompt skeleton. Keep a shot list document that doubles as a production log. Over a handful of projects you will develop a personal vocabulary of camera moves, motion strengths, and durations that works reliably, and that vocabulary is worth more than any single generation feature.
