
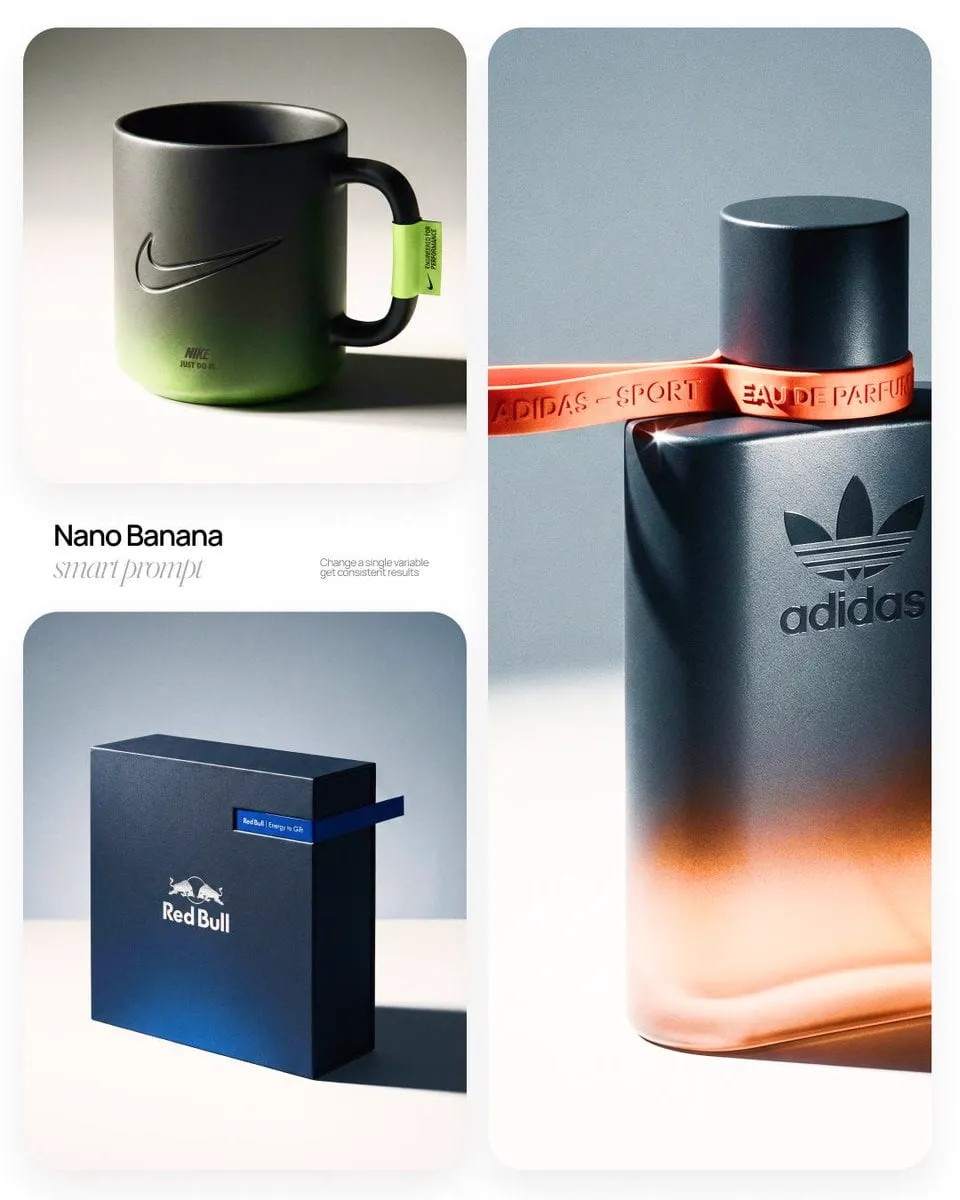
Generating video with AI has stopped being a party trick. The models shipping today can hold a face steady across an eight-second shot, follow a camera instruction without dissolving into abstract mush, and produce enough usable material that a small team can cut together something that feels deliberate. That changes what is realistic for a freelance editor, a two-person brand studio, or a solo creator with a storyboard and a weekend.
But comparing models has become genuinely confusing. Every release promises better realism, longer clips, and tighter prompt adherence, and the marketing language is nearly identical across the board. This guide takes a different route. Instead of ranking tools, it treats AI video as a pipeline problem: which model handles which job, how to move shots between tools, where quality collapses when you scale past a single test clip, and what to do about it.
What actually changed in AI video generation
Three shifts matter more than any benchmark chart. First, duration. Usable clip length moved from the four-second novelty range into the eight-to-fifteen-second range for many models, with some extending further through interpolation or continuation tricks. Longer single shots mean fewer hard cuts hiding continuity errors, and fewer cuts means a piece can breathe.
Second, controllability. Early text-to-video was a slot machine. Modern models accept reference images, start frames, end frames, motion brushes, camera trajectories, and in some cases separate prompts for subject and environment. Control is what separates a workflow from a lottery ticket, because it lets you retry one variable instead of rerolling the whole shot.
Third, the cost of a usable second dropped dramatically. Where a single decent clip once required an unreasonable number of attempts, most teams now report keeping roughly one in three to one in five generations. That ratio sounds bad until you compare it to booking a crew, a location, and a day of shooting for a five-second insert.
The four axes that decide whether a model works for you
Feature lists are noise. Four qualities predict whether a model will actually fit into your production:
Prompt adherence and semantic control
Can you describe a shot and get the shot? This includes whether the model understands compound instructions, negative constraints, and spatial relationships. A model that renders beautiful faces but ignores the instruction to keep the camera behind the subject is not useful for coverage.
Motion coherence and physical plausibility
Watch hands, feet, liquids, fabric, and fast rotation. Weak models smear limbs, melt objects into surfaces, and turn walking into gliding. Strong models keep weight and momentum believable, which is what makes an audience stop noticing the effect.
Temporal consistency and style drift
The enemy of long sequences is drift: skin tone shifts, wardrobe changes, lighting temperature wanders, and a stylized look gradually reverts toward generic realism. Consistency across shots matters more than any single frame looking beautiful.
Control surfaces: keyframes, references, and camera language
List the inputs you can feed the model. Start-frame conditioning, end-frame conditioning, character references, depth or pose guides, motion strength, and explicit camera terms. Every extra input is a retry lever you can pull without starting over.
Where the leading model families differ
Each family has a personality. Understanding that personality saves more time than any prompt template.
Runway Gen-4 and the editing-first approach
Runway built its reputation on the timeline, not the prompt box. Gen-4 leans hard into reference consistency: give it a character or location reference and it will carry that identity across separate generations. For a series of shots featuring the same person or product, that matters enormously. Its tooling around inpainting, motion control, and post-generation cleanup fits editors who think in sequences rather than single clips.
Sora-class models and narrative coherence
Sora-style models excel at interpreting a described scene, not just a described image. They handle multi-subject framing, environmental storytelling, and longer continuous action better than most. The tradeoff is often less granular control: you describe more and steer less, which is wonderful for exploratory work and frustrating when you need an exact composition to match a brand template.
Kling, PixVerse, and fine-grained creative control
Kling has earned a following for motion realism, particularly human movement and start-to-end frame transitions that let you bridge two images with a believable in-between. PixVerse goes after stylization, quick effects, and fast iteration cycles, which makes it a strong fit for social-first content where volume beats polish. Both reward users who iterate quickly rather than composing the perfect prompt.
Luma Ray 2 and Hailuo for realism per second
Luma's models are known for natural camera motion and a documentary-like physicality: reasonable parallax, believable depth, minimal uncanny warping. Hailuo tends to deliver dramatic motion and crisp detail, which suits action beats and hero shots. Neither is a universal answer, but both produce fewer embarrassing frames than the average model when the scene involves movement through space.
Image models as the first link in the chain
Flux-class image generators have quietly become the most important part of many video pipelines. Generating a high-quality keyframe first, then animating it, gives you composition control that text-to-video cannot match. You choose the framing, the lighting, the wardrobe, and the expression before a single frame moves.
Designing a multi-model workflow end to end
The professional move is not loyalty to one tool. It is assigning each stage of the pipeline to whichever model is strongest at that stage.
Stage 1: script, shot list, and visual references
Write the piece as a sequence of shots with a stated duration, camera behavior, subject action, and lighting intent. A shot list that says 'close-up, locked camera, product rotates slowly, soft key light from the left' will produce better results than any poetic prompt, because it removes ambiguity the model would otherwise invent.
Stage 2: keyframe generation
Generate first frames as stills for every shot. Iterate on composition here, where a retry costs seconds instead of minutes. Lock aspect ratio, color palette, and lens character at this stage so the whole piece feels like one film.
Stage 3: image-to-video and text-to-video
Animate approved keyframes with an image-to-video model. Keep motion strength conservative for product shots and interview-style framing, and push it higher for action beats. Generate three to five variations per shot, labeled by seed and settings, then review them at full size rather than in a grid of thumbnails.
Stage 4: assembly, sound, and finishing
Cut in an editor rather than in the generator. Trim to the strongest half-second, add speed ramps where motion stalls, and let sound design do heavy lifting. Room tone, footsteps, and a subtle score make AI footage feel shot rather than synthesized. Finish with a light grade to unify any color drift between models.
How to choose a model for a specific shot
Shot type drives tool choice more than personal preference does. A rough mapping:
| Shot type | Best-fit approach | Why it works |
|---|---|---|
| Product close-up, locked camera | Image-to-video from a rendered still | Minimal motion means minimal opportunity for artifacts |
| Talking head or presenter | Image-to-video with reference-locked identity | Preserves facial consistency across the sequence |
| Wide establishing shot | Text-to-video, then upscale and stabilize | Models invent plausible environments well |
| Action or movement beat | Models tuned for physical plausibility | Better weight, momentum, and limb behavior |
| Stylized or graphic insert | Style-first model plus a strong reference still | Holds a non-real look longer than generic models |
| Transition between two beats | Start-frame and end-frame conditioning | Bridges two locked images with a controllable in-between |
Two practical rules sit above the table. First, pick the model that gives you the most retry levers for the shot you are struggling with. Second, never judge quality on a compressed preview; export and review at final resolution.
Mistakes that make AI video look cheap
Most bad AI footage fails for the same handful of reasons.
Overloading the prompt is the most common. Five sentences of competing instructions produce mush. One subject, one action, one camera behavior, one lighting condition.
Ignoring seeds and settings is the second. When a variation works, note the seed, the model version, the motion strength, and the prompt. Reproducibility is the difference between a hobby and a workflow.
Mixing aspect ratios and lens language mid-project creates visual whiplash. Decide on 16:9 or 9:16, pick a lens character, and stay there.
Cutting too fast hides nothing. New viewers accept an AI shot more readily when it holds long enough to establish spatial logic. Ironically, fast cutting reads as an attempt to hide errors.
Treating audio as an afterthought is a quiet killer. Silent AI footage feels synthetic. Layered ambience and foley do more for perceived realism than another render pass.
Skipping the keyframe stage is the most expensive mistake of all. Teams that animate directly from text spend hours rerolling composition they could have fixed in a still image.
Planning time, compute, and iteration cycles
Run the arithmetic before you start. A thirty-second piece with an average shot length of two and a half seconds needs about twelve shots. At four attempts per shot, that is roughly forty-eight generations, plus keyframe iterations and upscales. If each successful generation takes two to four minutes of processing and review, a realistic solo timeline lands between six and twelve hours for a polished result.
Allocate your budget accordingly. Reserve the strongest, slowest model for hero shots and the fastest, cheapest option for coverage and cutaways. Build in one full revision pass after assembly, because continuity problems only become visible when shots sit next to each other. And keep a rejected-shots folder; sequences that fail in context often work as inserts later.
A worked example: a thirty-second product film
Suppose you are making a thirty-second spot for a lightweight travel mug.
The shot list: a misty establishing shot of a trailhead, a close-up of hands gripping the mug, a steam shot in cold air, a walking sequence with the mug in a side pocket, a tabletop rotation on a neutral background, and a closing logo beat.
You generate the trailhead with a text-to-video model, accepting ten variations and keeping two. The hands, steam, and tabletop shots become keyframes in an image generator first, so the mug's proportions and logo position stay identical, then animate with conservative motion. The walking sequence goes to whichever model handles human movement most convincingly, with the side pocket as the focal point to distract from foot placement.
The logo beat is built in an editor, not generated. Assembly uses the steam shot as the emotional pivot, sound design adds wind, a metallic click, and a low pad, and a single grade unifies everything toward cool morning light. Total output: roughly fifty generations, twelve kept, six in the final cut.
FAQ
How many attempts should I expect per usable shot?
Three to five is normal for straightforward shots, and closer to ten for complex human motion or intricate hand interaction. If you are consistently above ten, your prompt or keyframe is probably ambiguous rather than the model being weak.
Is text-to-video or image-to-video better?
Image-to-video wins whenever composition and identity matter, which is most commercial work. Text-to-video is better for exploration, environments, and anything you have not fully visualized yet.
How do I keep a character consistent across shots?
Generate a strong reference still, then use a model with reference conditioning. Keep wardrobe and lighting described identically in every prompt, and avoid extreme angle changes between consecutive shots.
Do I need more than one model?
Usually yes. A single-model pipeline is simpler but forces compromises on motion, consistency, or stylization. Two or three models covering keyframes, motion, and cleanup is a practical sweet spot.
Why does my footage look uncanny even when the frames look good?
Uncanny quality almost always comes from motion, not stills. Reduce motion strength, narrow the action in the prompt, and check frame rate consistency before blaming the model.
How long should individual AI shots be in a final edit?
Two to four seconds is comfortable for most cuts. AI clips often fall apart in their final second, so trim the tail before you trim the head.
What to watch next
Model churn will continue, and version numbers will keep moving. The durable skills are not model-specific: writing precise shot lists, locking composition with keyframes, keeping identity references stable, and treating sound as a first-class part of the pipeline. Teams that build those habits can swap in whatever model leads next quarter without rebuilding their process from scratch.
Start small. Pick one fifteen-second sequence, run it through the full pipeline, and measure where your time actually goes. The bottleneck is rarely the model. It is almost always the shot list, the keyframe stage, or the edit.
