
Why Text-to-Video Moved Into the Production Pipeline
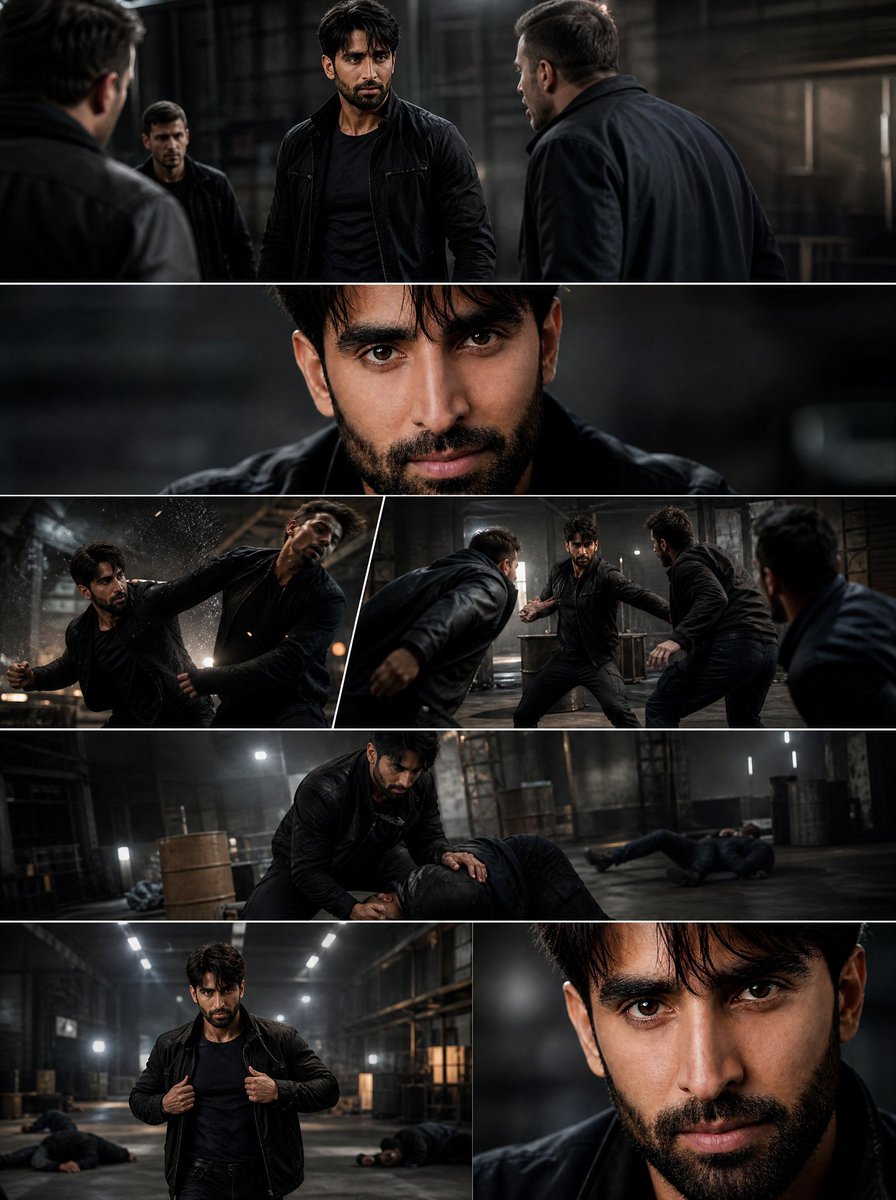
For a long time, generating motion from a written sentence was a demo you showed to impress people, not a tool you scheduled work around. That has changed. Temporal consistency, prompt adherence, and frame-level control have all improved enough that AI video is now used for storyboards, social cutdowns, product explainers, pitch visuals, and full segments inside larger productions.
The important shift is not resolution. It is control. Early tools behaved like a slot machine: you typed a sentence, waited, and either liked the result or tried again. Modern generation let you separate the decisions that used to be bundled together. What does the shot look like? How does the camera move? How long does it last? How does light behave? How does the subject change from first frame to last?
Once those decisions are separable, generation becomes a workflow instead of a gamble. You can lock an opening frame, guide motion with a short instruction, extend a shot without the subject morphing, and iterate on the one part that is wrong instead of regenerating the whole clip.
This guide is about that workflow. It covers how to break a script into shots, how to choose between text-only, image-conditioned, and keyframe-driven generation, how to write motion prompts that actually change the output, how to fix the failure modes you will inevitably hit, and how to finish a project so it looks deliberate rather than assembled.
Whether you are a solo creator publishing weekly or part of a small team delivering client work, the principles are the same: plan like an editor, prompt like a cinematographer, and review like a quality assurance engineer.
Start With a Shot List, Not a Prompt
The most common reason AI video projects stall is that people start typing before they know what they are making. They generate twelve beautiful but unrelated clips and then struggle to assemble them into something coherent.
A shot list fixes this before it happens. It does not need to be formal. A spreadsheet with five columns is enough:
- Shot number and duration — three to six seconds per generated clip is a reliable default for most models.
- What the audience must understand — the single piece of information this shot carries.
- Subject and setting — who or what is on screen, and where.
- Camera behavior — static, slow push, handheld drift, orbit, aerial reveal.
- Motion intensity — how much the frame changes from start to finish.
That last column matters more than beginners expect. Low-motion shots generate far more reliably than high-motion shots. A conversation at a table is easy. A character sprinting through a collapsing market while the camera orbits is hard, and no prompt phrasing will fully rescue it.
Write durations before you generate, not after. If your shot list says a beat needs four seconds, generate four seconds. Trimming a five-second clip to four is trivial; stretching a two-second clip never looks right.
Finally, group shots by generation method. Shots that need a specific opening composition belong in the image-conditioned group. Shots that are pure atmosphere belong in the text-only group. Shots that need a precise transition from frame A to frame B belong in the keyframe group. Assigning methods up front prevents a lot of wasted attempts.
The Three Generation Modes and When to Use Each
Text-to-Video
You describe the shot and the model invents everything: composition, subject, lighting, motion. This is the fastest mode and the best for establishing shots, abstract transitions, backgrounds, textures, and any place where a specific layout is not critical.
The trade-off is predictability. Two runs of the same prompt will produce two different compositions. Treat text-to-video as a tool for generating options and for shots where variety is welcome.
Image-to-Video
You supply a still frame and the model animates from it. This is where most production work actually happens. Because composition is locked, you can match a storyboard, keep a character consistent across shots, and place a product in the exact position the edit requires.
Use image-to-video whenever continuity matters: recurring characters, branded objects, diagram overlays, and any shot that must cut cleanly against its neighbors. The still can come from an image generator, a photograph, a 3D render, or a frame you liked from an earlier clip.
Keyframe and Reference-Driven Generation
Here you define both the start and end of a shot, and the model fills the motion between them. This is the highest-control mode, and it is the right choice for reveals, transformations, before-and-after comparisons, and any shot whose final frame must land on a specific composition.
References add another layer: a style image, a character sheet, or a lighting reference that tells the model what kind of image you want rather than what content you want. Combining a content reference with a style reference is usually more effective than trying to describe both in words.
A practical rule: start every scene in image-to-video mode, drop into text-to-video only for connective or atmospheric shots, and reserve keyframe mode for the one or two shots per scene that carry the story.
Writing Prompts That Control Motion
Most prompt guides focus on content. In video, motion matters more. A prompt that describes a person perfectly but says nothing about movement produces a near-static shot — or worse, unpredictable drift.
Separate Subject Motion From Camera Motion
Write them as distinct phrases. "A cyclist pedals uphill" is subject motion. "The camera tracks alongside, slightly ahead" is camera motion. When both are packed into one clause, models frequently blend them and move the world instead of the camera.
Camera vocabulary that models respond to reliably:
- Static locked-off shot — no movement, best for dialogue and product detail.
- Slow push in — increases tension and focus.
- Slow pull out — reveals context.
- Lateral tracking — good for movement across a scene.
- Orbit — strong but demanding; keep the arc small.
- Handheld drift — adds documentary realism with minimal structural change.
Describe Intensity, Not Just Direction
"Slow" and "subtle" are your friends. A slow push is a real camera instruction; "dynamic camera movement" is a wish. If a shot looks frozen, increase motion with specific verbs: turns, lifts, steps, unfolds, drifts, ripples. If it looks chaotic, remove verbs rather than adding negative phrasing.
Anchor Lighting and Atmosphere Early
Lighting instructions belong at the start of the prompt, because they affect every other decision the model makes. "Overcast morning light, soft shadows, cool tones" sets a consistent palette for the whole clip. Repeating the exact same lighting phrase across every shot in a scene is one of the simplest ways to make generated footage feel like it belongs together.
Keep Prompts Under Control
Long, poetic prompts feel productive but often dilute each instruction. A workable structure is: lighting and atmosphere, subject and setting, subject action, camera behavior, and one optional style note. That is roughly forty to eighty words. If a shot needs more than that, split it into two shots.
A Practical End-to-End Workflow
Step 1: Decompose the Script
Read the script and mark every visual beat. A thirty-second explainer usually contains six to nine shots. Write one line per shot describing what the audience must see, not what you hope the model will produce.
Step 2: Collect or Generate Opening Frames
For each shot, produce a still frame. This can be fast — a rough composition is enough. The goal is not a finished image; it is a fixed starting point that keeps every shot consistent with the edit.
Step 3: Generate in Batches by Shot Type
Group similar shots together and generate them in one session. Keeping lighting, style, and aspect ratio constant across a batch reduces the visual drift that appears when you jump between wildly different prompts.
Generate at least two or three variations per shot. Even with good prompts, the first output is rarely the best one, and comparing options is faster than trying to perfect a single take.
Step 4: Review Against the Shot List
Score each attempt on three axes: does it match the shot list, does the motion read correctly, and are there structural artifacts? Keep a short note for each rejected clip so you do not repeat the same mistake in the next batch.
Step 5: Extend and Assemble
For shots that need more length, extend from the last frame rather than generating a longer clip from scratch. Extension preserves motion continuity far better than stretching or slowing footage.
Assemble a rough cut immediately, even with placeholder audio. Seeing shots in sequence reveals continuity problems that are invisible when you review clips one at a time.
Choosing the Right Approach for the Shot
The table below is a decision shortcut, not a rulebook. Use it when you are unsure how much control a shot needs.
| Shot type | Recommended mode | Motion level | Notes |
|---|---|---|---|
| Establishing landscape | Text-to-video | Low | Generate several, pick the cleanest |
| Character close-up | Image-to-video | Low | Lock the face with a still |
| Product rotation | Keyframe | Medium | Define start and end angles |
| Transformation | Keyframe | High | Expect multiple attempts |
| Abstract transition | Text-to-video | Medium | Cheap and forgiving |
| Dialogue beat | Image-to-video | Very low | Minimal motion reads as intentional |
| Reveal | Keyframe | Medium | End frame must match the next cut |
The pattern is consistent: the more a shot must match something else, the more conditioning it needs. Pure atmosphere tolerates text-only generation. Anything that must cut against a neighboring shot benefits from a locked frame.
One more consideration is aspect ratio and frame rate. Decide them at the start of the project. Vertical social clips and widescreen sequences have different framing logic, and regenerating an entire scene in a new aspect ratio is expensive in time even when it is cheap in cost.
Editing, Continuity, and the Assembly Cut
Generated footage is raw material. The edit is where it becomes a video.
Cut on Motion, Not on Duration
The strongest cuts happen when movement carries across the edit. Match the direction of motion: if a subject exits frame right, the next shot should continue that rightward energy. This single habit makes AI footage feel far more intentional than it is.
Hide Unstable Frames
Every generated clip has a weakest moment — usually the first few frames or the last. Trim into the clip rather than using it whole. Starting mid-motion often improves a shot, because it removes the ramp-up period where the model is still settling.
Use Speed Changes Sparingly
Slight speed adjustments can fix pacing, but heavy slow motion exposes interpolation artifacts and makes inconsistent motion obvious. If a clip needs to be dramatically slower, generate a slower shot instead.
Bridge With Simple Elements
Whip transitions, light leaks, occlusions, and fast overlays hide imperfect joins between shots. A dark frame or a brief motion blur between two mismatched clips is often more convincing than trying to make them match.
Keep a Continuity Note
Track which frames you used as starting points and which style phrases you used per scene. When a client asks for one more shot in the same style, that note saves twenty minutes of guesswork.
Audio, Subtitles, and Finishing
Silent generated footage rarely lands. Audio does most of the emotional work in short-form video, and it also masks minor visual problems.
The Three-Layer Audio Approach
Build sound in layers: a music bed, a set of spot effects, and voice. Music sets pacing, effects sell physical actions, and voice delivers meaning. Even a simple whoosh on a transition or a low rumble under a reveal changes how viewers read the shot.
Voice and Narration
If you use synthetic narration, generate it per sentence rather than per paragraph. You get more control over pauses and emphasis, and you can regenerate one awkward line without redoing the whole read. Keep a consistent voice across the entire project — switching voices mid-video is more noticeable than any visual imperfection.
Subtitles and Safe Areas
Burned-in subtitles remain the standard for social delivery, and they help reach viewers watching without sound. Place them inside the platform safe area and keep them clear of faces and key product details. If your generated shots have a lot of movement, add a subtle background bar behind text to keep it readable.
Color and Final Polish
A light grade — small contrast and saturation adjustments, plus a consistent look applied across all clips — unifies footage generated in different sessions. Add a gentle film grain or noise layer if the shots feel too clean and synthetic. Finish with a consistent loudness level so the video does not jump in volume between segments.
Troubleshooting Common Generation Failures
The subject morphs over time. Reduce motion, shorten the clip, and lock the subject with an image reference. Morphing is usually a symptom of asking for too much change inside too few frames.
The camera moves when it should not. Remove subject-motion verbs from the prompt and add an explicit static camera phrase. Models often interpret any action verb as a reason to move the frame.
Hands, faces, and text look wrong. Simplify the shot. Reduce detail, avoid close-ups of complex hands, and never rely on generated on-screen text — add typography in the edit instead.
The clip flickers or the lighting pulses. This typically comes from an inconsistent lighting phrase or conflicting style references. Remove style references one at a time to find the culprit, and repeat the lighting phrase exactly across the scene.
The motion is too fast and chaotic. Fewer verbs, lower motion intensity, and shorter duration. Chaos is almost always a duration problem: two seconds of activity compresses into something unreadable.
The output does not match the prompt at all. Check prompt order. Models weight early tokens more heavily, so move the most important subject description to the front.
Everything looks slightly different from shot to shot. Normalize aspect ratio, lighting phrase, and style reference across the scene, then grade the assembled cut.
Quality Checklist Before You Deliver
Run this list on the finished edit, not on individual clips:
- Every shot advances the story or the argument; nothing is there because it looked nice.
- Cuts land on motion and maintain directional continuity.
- No clip plays its first or last frames if they are unstable.
- Audio levels are consistent and narration is intelligible on a phone speaker.
- Subtitles sit inside safe areas and stay clear of faces.
- Colors and grain are consistent across scenes.
- Aspect ratio and frame rate match the delivery platform.
- The video communicates its main point within the first three seconds.
- No generated on-screen text carries essential information.
- A viewer who watches without sound still understands the piece.
If a project fails two or more of these checks, fix them before exporting. Most of them take minutes, and they separate work that looks generated from work that looks directed.
FAQ
How long should a single AI-generated clip be?
Three to six seconds is the sweet spot for most projects. Shorter clips stay stable, and you can extend from the final frame when a shot needs more room. Longer single generations tend to drift or slow down unnaturally.
Do I need a still image for every shot?
No, but you should for every shot that must match a storyboard, a character, or a neighboring cut. Atmospheric and transitional shots generate fine from text alone.
What is the biggest beginner mistake?
Starting with the prompt instead of the shot list. Planning shots first means every generation attempt has a clear pass or fail condition, which makes iteration dramatically faster.
Why does my generation look better at low resolution?
Lower resolutions hide fine detail where artifacts live. Always evaluate at delivery resolution before committing, because problems invisible in a preview become obvious on a large screen.
How do I keep a character consistent across many shots?
Use the same reference image, the same lighting phrase, and the same style notes for every shot in the scene. Consistency comes from repetition of the conditioning inputs, not from a clever prompt.
Can I mix AI footage with real footage?
Yes, and it is one of the most reliable approaches. Place generated shots between real shots, match the grade closely, and use transitions to bridge any remaining mismatch. Real footage anchors the piece; generated footage fills the gaps that would otherwise be expensive or impossible.
How many attempts should I plan for per shot?
Budget three attempts for simple shots and six or more for complex ones. Planning for iteration instead of expecting a first-try success is the difference between a smooth project and a frustrating one.
What should I do when a shot simply will not work?
Redesign the shot instead of fighting the model. Split it into two simpler shots, change the camera angle, or replace it with an insert. Most impossible shots are really two shots compressed into one.
